Download dbmole-mcp-<version>.mcpb from the
latest release and open it, or add
the JSON below to claude_desktop_config.json. Claude Desktop does not start servers inside a
project, so keep connections in the global store (the default scope).
The container runs as node with cwd /work: mount a project there to use its
.dbmole.json, and the named volume keeps the global store. Mount known_hosts for SSH
connections (or pin ssh.hostKey), and any private key you reference by privateKeyPath, at
the path the connection names; for ssh.agent: true, forward the agent socket
(-v "$SSH_AUTH_SOCK:/ssh-agent" -e SSH_AUTH_SOCK=/ssh-agent). To reach hosts that only your machine can reach, add
--add-host=host.docker.internal:host-gateway (Linux) and use host.docker.internal. The
image has no git, so the "not ignored by git" check always warns.
A 0.1 setup that still sets DBMOLE_CONNECTIONS, DBMOLE_CONFIG or --config starts fine:
the server prints one line on stderr saying they are ignored. See the
changelog.
Quick start
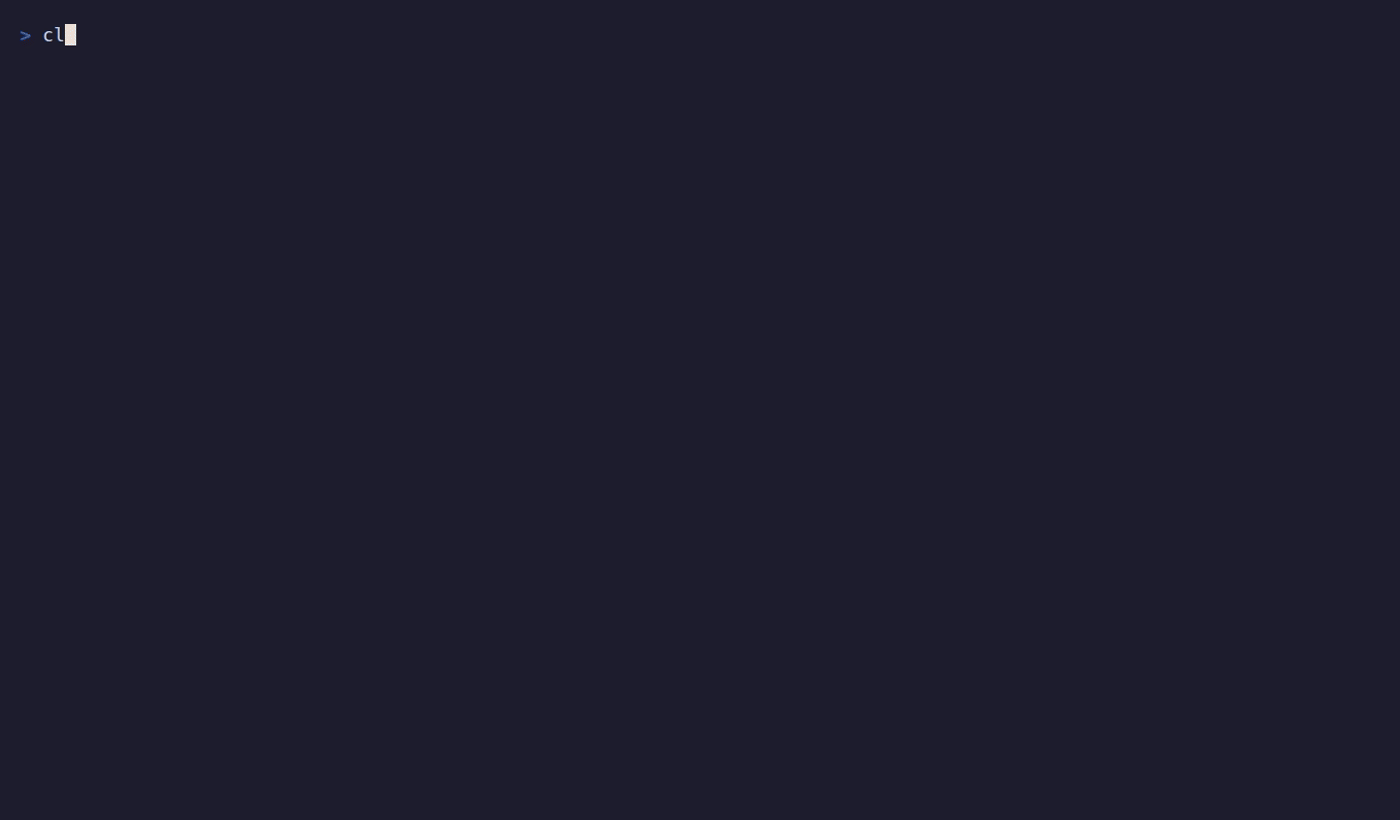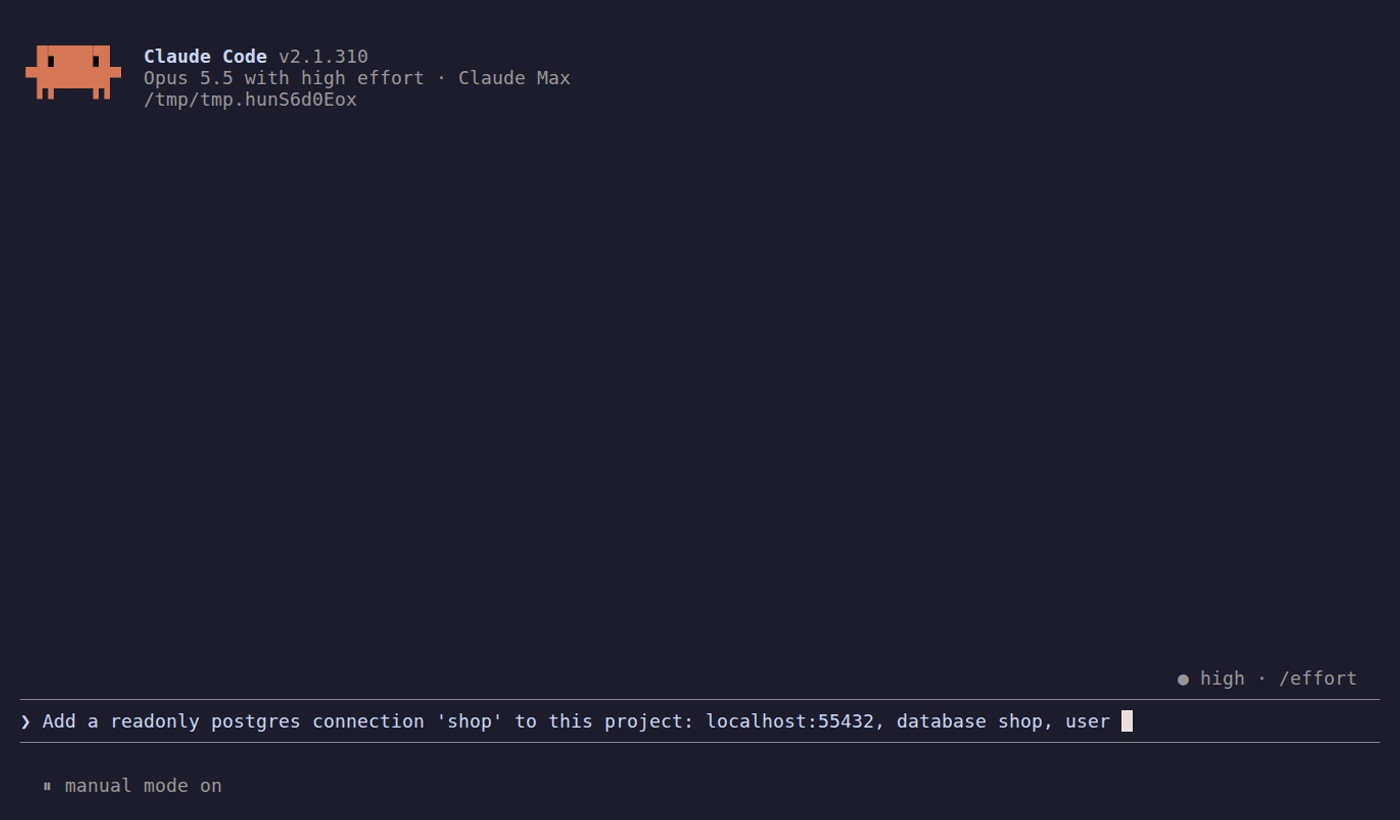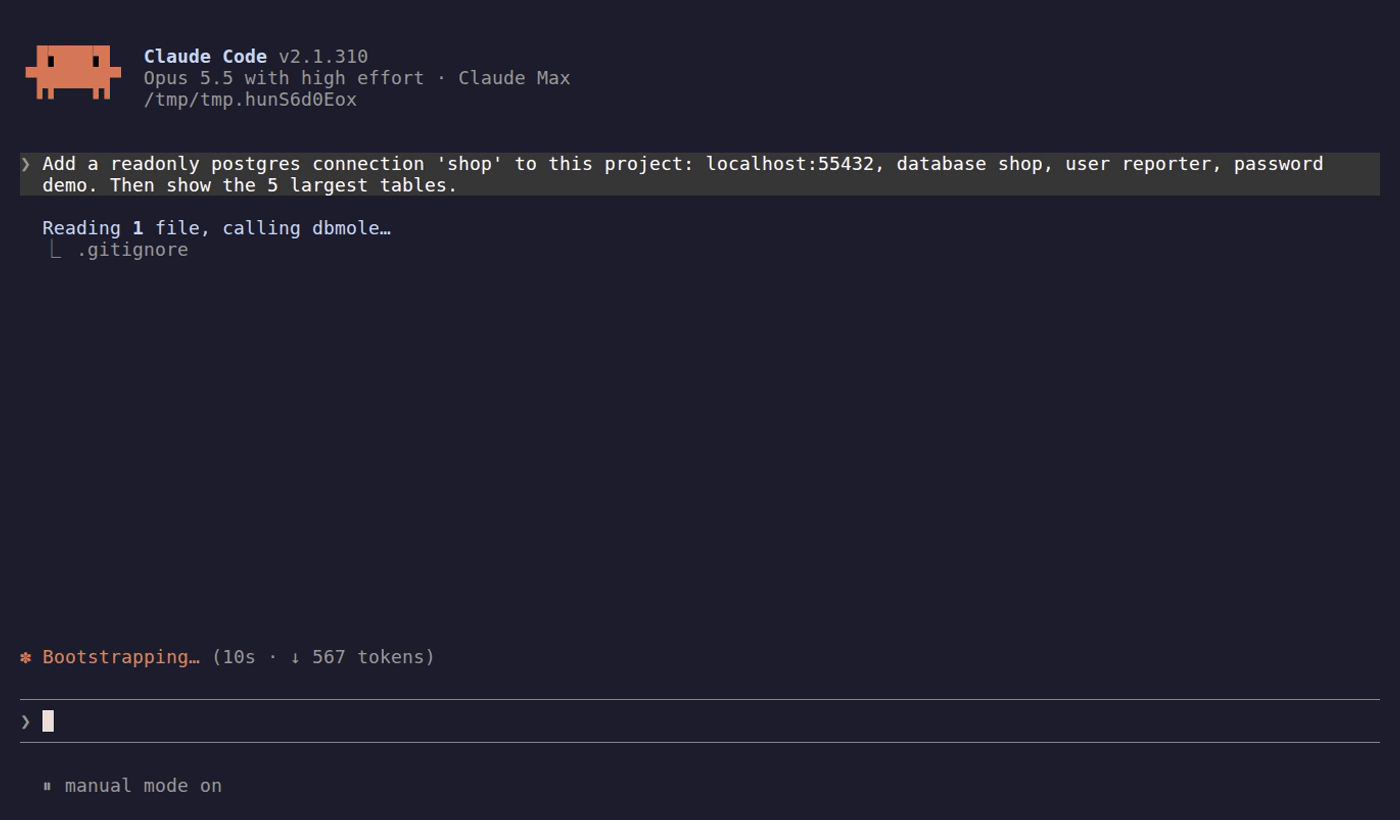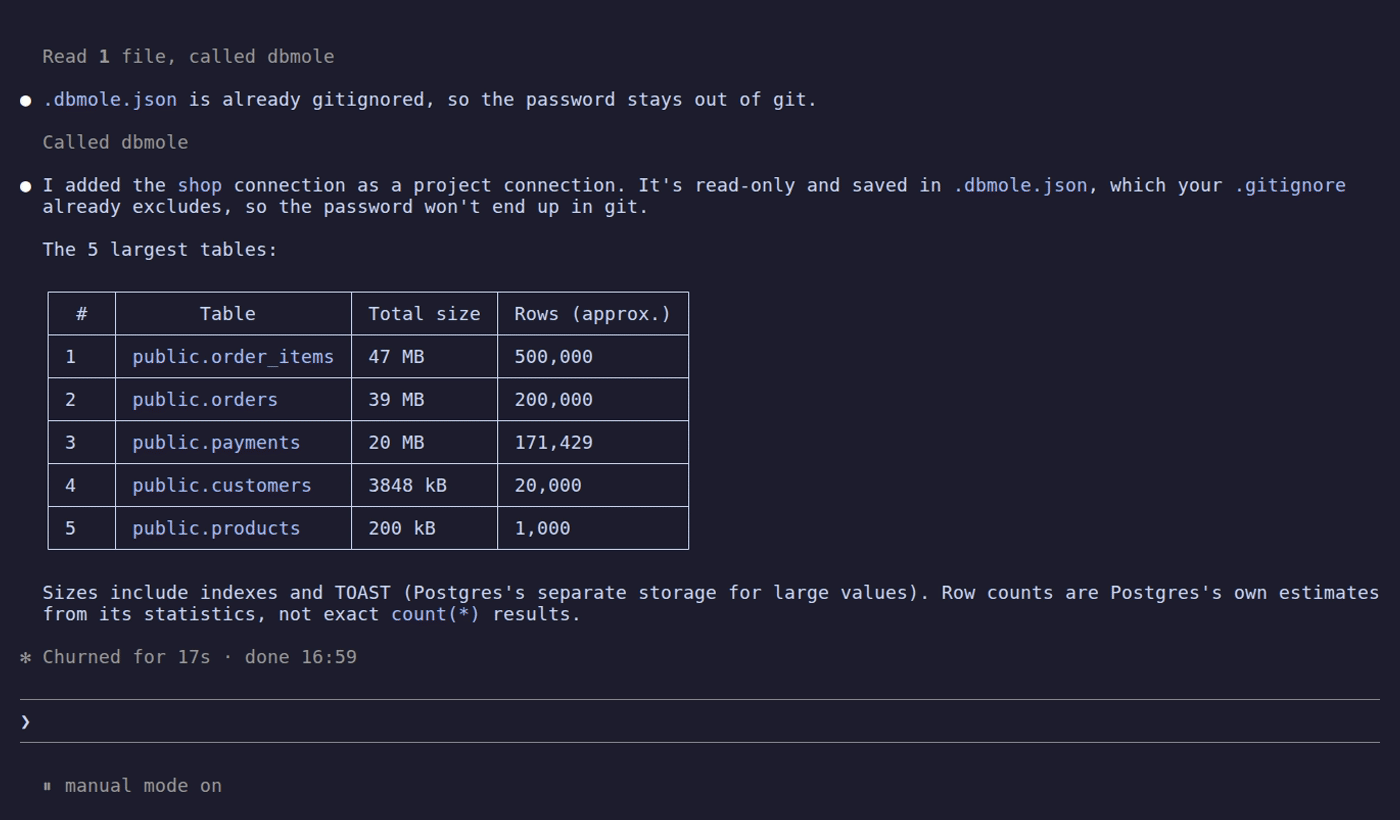
Ask the agent, for example:
Add a readonly postgres connection shop to this project: host 10.0.0.12, database shop,
user reporter, through ssh as [email protected] with my ssh agent. Then show the
five largest tables.
then test_connection, list_tables and execute_sql. Credentials you type in chat pass
through the model's context; for production secrets, write the entry into the file yourself.
Connections
Two layers
Layer
File
Shape
project
.dbmole.json, found from the server's working directory
{ "connections": [ ... ] }
global
~/.config/dbmole/connections.json, or the path in DBMOLE_STORE
[ ... ]
Same name in both: the project entry wins.list_connections reports each connection's
source (project or global) and, when it hides an entry of the same name in the other
layer, shadows.
Hot reload. Both files are re-read on every tool call. Edit a file mid-session and the next
call uses the new settings; a changed connection gets a fresh pool, the old one is closed.
Project file discovery. Starting from the server's working directory (Claude Code and
Codex start it in the project directory), dbmole walks up to the filesystem root and uses
the first .dbmole.json it finds. In a linked git worktree with no file of its own, it falls
back to the main checkout's .dbmole.json, so every worktree of a repo shares one file.
Both files are plain JSON with mode 0600, written atomically. Writes keep entries they
cannot parse verbatim, and refuse to overwrite a file that is not valid JSON.
Managing connections with tools
add_connection takes the connection fields plus scope: "global" (default) or
"project". With project and no file yet, the file is created at the main checkout root
(or the git root, or the working directory outside git). If git does not ignore it, the
response warns you; add .dbmole.json to .gitignore so credentials are not committed.
add_connection fails when the name already exists in the target layer. The same name in
the other layer is allowed; the response says which entry now shadows which.
update_connection patches the connection where it lives (the winning layer). A null
value removes an optional field. An ssh object is merged into the stored one field by
field, so { "ssh": { "hostKey": "SHA256:..." } } keeps the stored SSH secrets; ssl is
replaced as a whole.
remove_connection deletes it from that layer and tells you if that uncovers a same-name
entry in the other layer.
Credentials are never echoed back: list_connections shows host, port, database,
readonly, source and whether SSH is used.
Broken and invalid entries
An entry that fails validation does not silently disappear: its name resolves to an error
(connection 'x' in <file> is invalid: ...) instead of falling through to a same-name entry
in the global store, and list_connections lists it as invalid. A name defined twice in one
file is an error too. remove_connection can delete an invalid entry.
A file that exists but is unreadable, not JSON, or the wrong shape is reported in
list_connections (brokenLayers). A broken project file blocks every connection; a broken
global store blocks only names the project file does not define. A missing file is just
empty.
Connection fields
Unknown fields are rejected.
Field
Type
Notes
name
string
[a-zA-Z0-9_-]+
type
postgres | mysql
host
string
as seen from the SSH bastion when ssh is set
port
number
default 5432 / 3306
user
string
password
string
optional
database
string
default database for queries and schema tools; PostgreSQL falls back to postgres for list_databases and test_connection
Host keys are verified. With hostKey set, the bastion's key must match it (trailing =
padding is accepted) and known_hosts is not consulted. Otherwise the key must match an entry
for the host in ~/.ssh/known_hosts (host on port 22, [host]:port otherwise):
Plain and hashed host names match. Wildcard patterns never match, and a line with a negated
wildcard (!*.example.com) is ignored.
A key listed under @revoked is rejected for every host, whatever the line's host pattern.
@cert-authority lines and unknown markers are skipped.
There is no trust-on-first-use: an unknown key fails the connection with an error that shows
the presented fingerprint. Check it against a trusted source, then either add the host to
known_hosts or pin it:
and ask the agent to update_connection with ssh.hostKey set to that SHA256:... value.
Tunnels send keepalives every 15 s and are rebuilt after 3 missed replies. Not supported:
ProxyJump and ~/.ssh/config, SSH certificates.
TLS
ssl value
Meaning
absent
no TLS
true
TLS, certificate chain and hostname verified
{ "ca": "..." }
verify against this CA: a PEM string or a file path (~ expanded)
{ "rejectUnauthorized": false }
TLS without verification
The hostname checked is always the connection's host, also when the connection goes through
an SSH tunnel. MySQL cannot verify the identity of an IP address, so a MySQL connection with an
IP host and verifying TLS is rejected at validation: use a hostname, or set
ssl.rejectUnauthorized: false.
update_connection replaces ssl as a whole (unlike ssh, it is not merged).
list_connections does not show TLS settings.
Readonly
readonly: true protects against accidental writes. The database session enforces it, not a
SQL parser:
PostgreSQL: each execute_sql call runs as BEGIN READ ONLY → statement → ROLLBACK.
MySQL: each call runs on a session set to SET SESSION TRANSACTION READ ONLY.
Every call gets a clean session: after it, the connection is reset (open transaction,
autocommit, session variables, current database, temporary tables), so nothing one call
sets, including an attempt to switch readonly off with SET, carries into the next call.
PostgreSQL runs ROLLBACK and DISCARD ALL; MySQL sends COM_RESET_CONNECTION, one extra
round trip per call. A connection whose reset fails (or, on MySQL, takes over 5 s) is closed,
never reused. This applies to writable connections too.
One statement per call; multi-statement strings are refused by the protocol.
What it is not:
Not a security boundary. The agent can switch it off with update_connection, by
design.
Known gaps include (the list is not exhaustive):
server-side file and program writes: PostgreSQL COPY ... TO PROGRAM,
COPY ... TO '<file>' and lo_export, MySQL SELECT ... INTO OUTFILE / INTO DUMPFILE;
writes through dblink;
DML on temporary tables;
privileged administrative statements and functions, such as pg_terminate_backend,
SET GLOBAL and KILL.
For a hard guarantee, connect as a least-privilege database role with no write grants, no file,
program or administrative privileges, and no write-capable routines.
Tools
Tool
What it does
list_connections
connections with their source, shadowed names, invalid entries and broken files
add_connection
add a connection to the project file or the global store
update_connection
patch a connection where it lives; null removes a field
remove_connection
remove a connection; reports a same-name entry it uncovers
test_connection
connect end to end (including the tunnel) and report server version and latency
execute_sql
run one statement with positional params ($1… for PostgreSQL, ? for MySQL); rowLimit default 100, max 1000; optional database
list_databases
databases on the server with their size; hides PostgreSQL templates and MySQL system schemas
list_tables
tables, views and materialized views (type: table or view) with approximate row counts
describe_table
columns, primary key, indexes and foreign keys of a table or view; accepts schema.table (PostgreSQL) and db.table (MySQL), with "quoted" or `quoted` parts that may contain dots
Tool arguments are checked strictly: a wrong key is rejected with a hint, e.g.
unknown key 'query' — did you mean 'sql'?.
PostgreSQL COPY ... FROM STDIN and COPY ... TO STDOUT are refused: use INSERT and
SELECT. A COPY ... TO STDOUT still runs to the end on the server (its output is discarded,
queryTimeoutMs bounds it) before the call fails.
MySQL errors come with hints where they help: the real columns of the tables in the query on
an unknown column, similar table names on an unknown table, and a reminder to backtick-quote a
reserved word on a parse error.
The nine tool definitions cost about 1.8k tokens of context (tools/list is about 7,100
characters; measured with npm run smoke, at roughly 4 characters per token).
Limits and timeouts
Every result is at most 40 KB of JSON. Strings longer than 2 KB are cut and marked
…[+N bytes]; if rows still do not fit, whole rows are dropped from the end and rowCount
is the number of rows kept. The result says so in truncated
({ "reason": "budget", "dropped": N, "kept": M }), and stays valid JSON.
execute_sql stops reading at rowLimit rows
(truncated: { "reason": "rowLimit", "limit": N }); the
database streams rows (PostgreSQL cursor, MySQL stream), so a huge table never lands in
memory. The limits count rows: one enormous cell is still read in full before it is cut.
queryTimeoutMs (default 60 s) bounds each statement: PostgreSQL cancels it on the server
(statement_timeout), which only helps while the server is reachable; if the network drops
silently, TCP keepalive detects the dead peer and fails the call; on MySQL the client stops waiting, sends KILL QUERY over a separate
short-lived connection (the server would otherwise keep running a statement that produces no
output), then discards the connection.
Behind a load balancer or a DNS-rotated endpoint (an Aurora reader endpoint, HAProxy), that
separate connection can reach a different MySQL server: the KILL QUERY then misses the
statement, or, in theory, hits another session with the same thread id. Point MySQL
connections at a direct server endpoint if you rely on timeouts.
A dropped connection resets the pool. list_databases, list_tables, describe_table and
test_connection retry once; execute_sql never replays a statement and tells you it may or
may not have run.
✓ documented, ✗ not offered, — not mentioned in the project's docs. Checked October 2026;
corrections welcome.
Security
Connection files hold plaintext credentials (mode 0600, like ~/.pgpass). Keep
.dbmole.json out of git. Database errors are passed to the client verbatim.
Whoever can change a connection, through update_connection or by editing a connection file,
can redirect its credentials. Changing host keeps the stored password, and changing
ssh.host keeps the stored SSH password or key, so the next call sends them to the new host.
Treat write access to the connection tools and files like access to the credentials.
A project's .dbmole.json is trusted as is: in a cloned or untrusted repository it can add
connections or shadow a global one of the same name and send your queries to another host.
Discovery walks up to /, so a file in a parent directory (such as ~) applies to every
project below it. Check list_connections before working in an unfamiliar repository.
Each open SSH tunnel listens on 127.0.0.1 at a random port without authentication: while it
is open, any local process, including other users on a shared host, can connect through it
to the target host. The database still asks for its own credentials.
See SECURITY.md for the
threat model and how to report a vulnerability.
Development
npm ci
npm run lint        # Biome
npm run typecheck   # tsc across packages
npm run test:unit   # unit tests, mocked IO
npm run test:int    # integration tests against real databases (needs Docker)
npm run smoke       # build, npm pack, install the tarballs in a temp dir, boot, tools/list
packages/
  core/         @dbmole/core: registry, project files, SSH tunnels, pools, MCP connection tools
  dbmole-mcp/   the PostgreSQL and MySQL server (this README)
@dbmole/core is published to npm because
esmole-mcp builds on it; dbmole-mcp bundles it,
so installing dbmole-mcp pulls no @dbmole/core.
अभी टूल सूची नहीं है। रिमोट सर्वर को पहले हेल्थ चेक के बाद सूची मिलती है।
FAQ
सवाल
Dbmole कैसे इंस्टॉल करें?
इस पेज पर Cursor, Claude Desktop, Claude Code या VS Code के लिए stdio कॉन्फ़िग कॉपी करें। यह पब्लिशर का इंस्टॉल इस्तेमाल करता है, PlugMCP प्रॉक्सी नहीं।
क्या Dbmole के लिए API key चाहिए?
इस रिकॉर्ड में कोई ज़रूरी एनवायरनमेंट वेरिएबल दर्ज नहीं है।
Dbmole कौन सा ट्रांसपोर्ट इस्तेमाल करता है?
Dbmole stdio पर लोकल चलता है।
Dbmole की पिछली जाँच कब हुई थी?
पिछली जाँच 2026-11-09 को हुई। PostgreSQL and MySQL with connections managed at runtime by the agent, SSH tunnels, readonly.