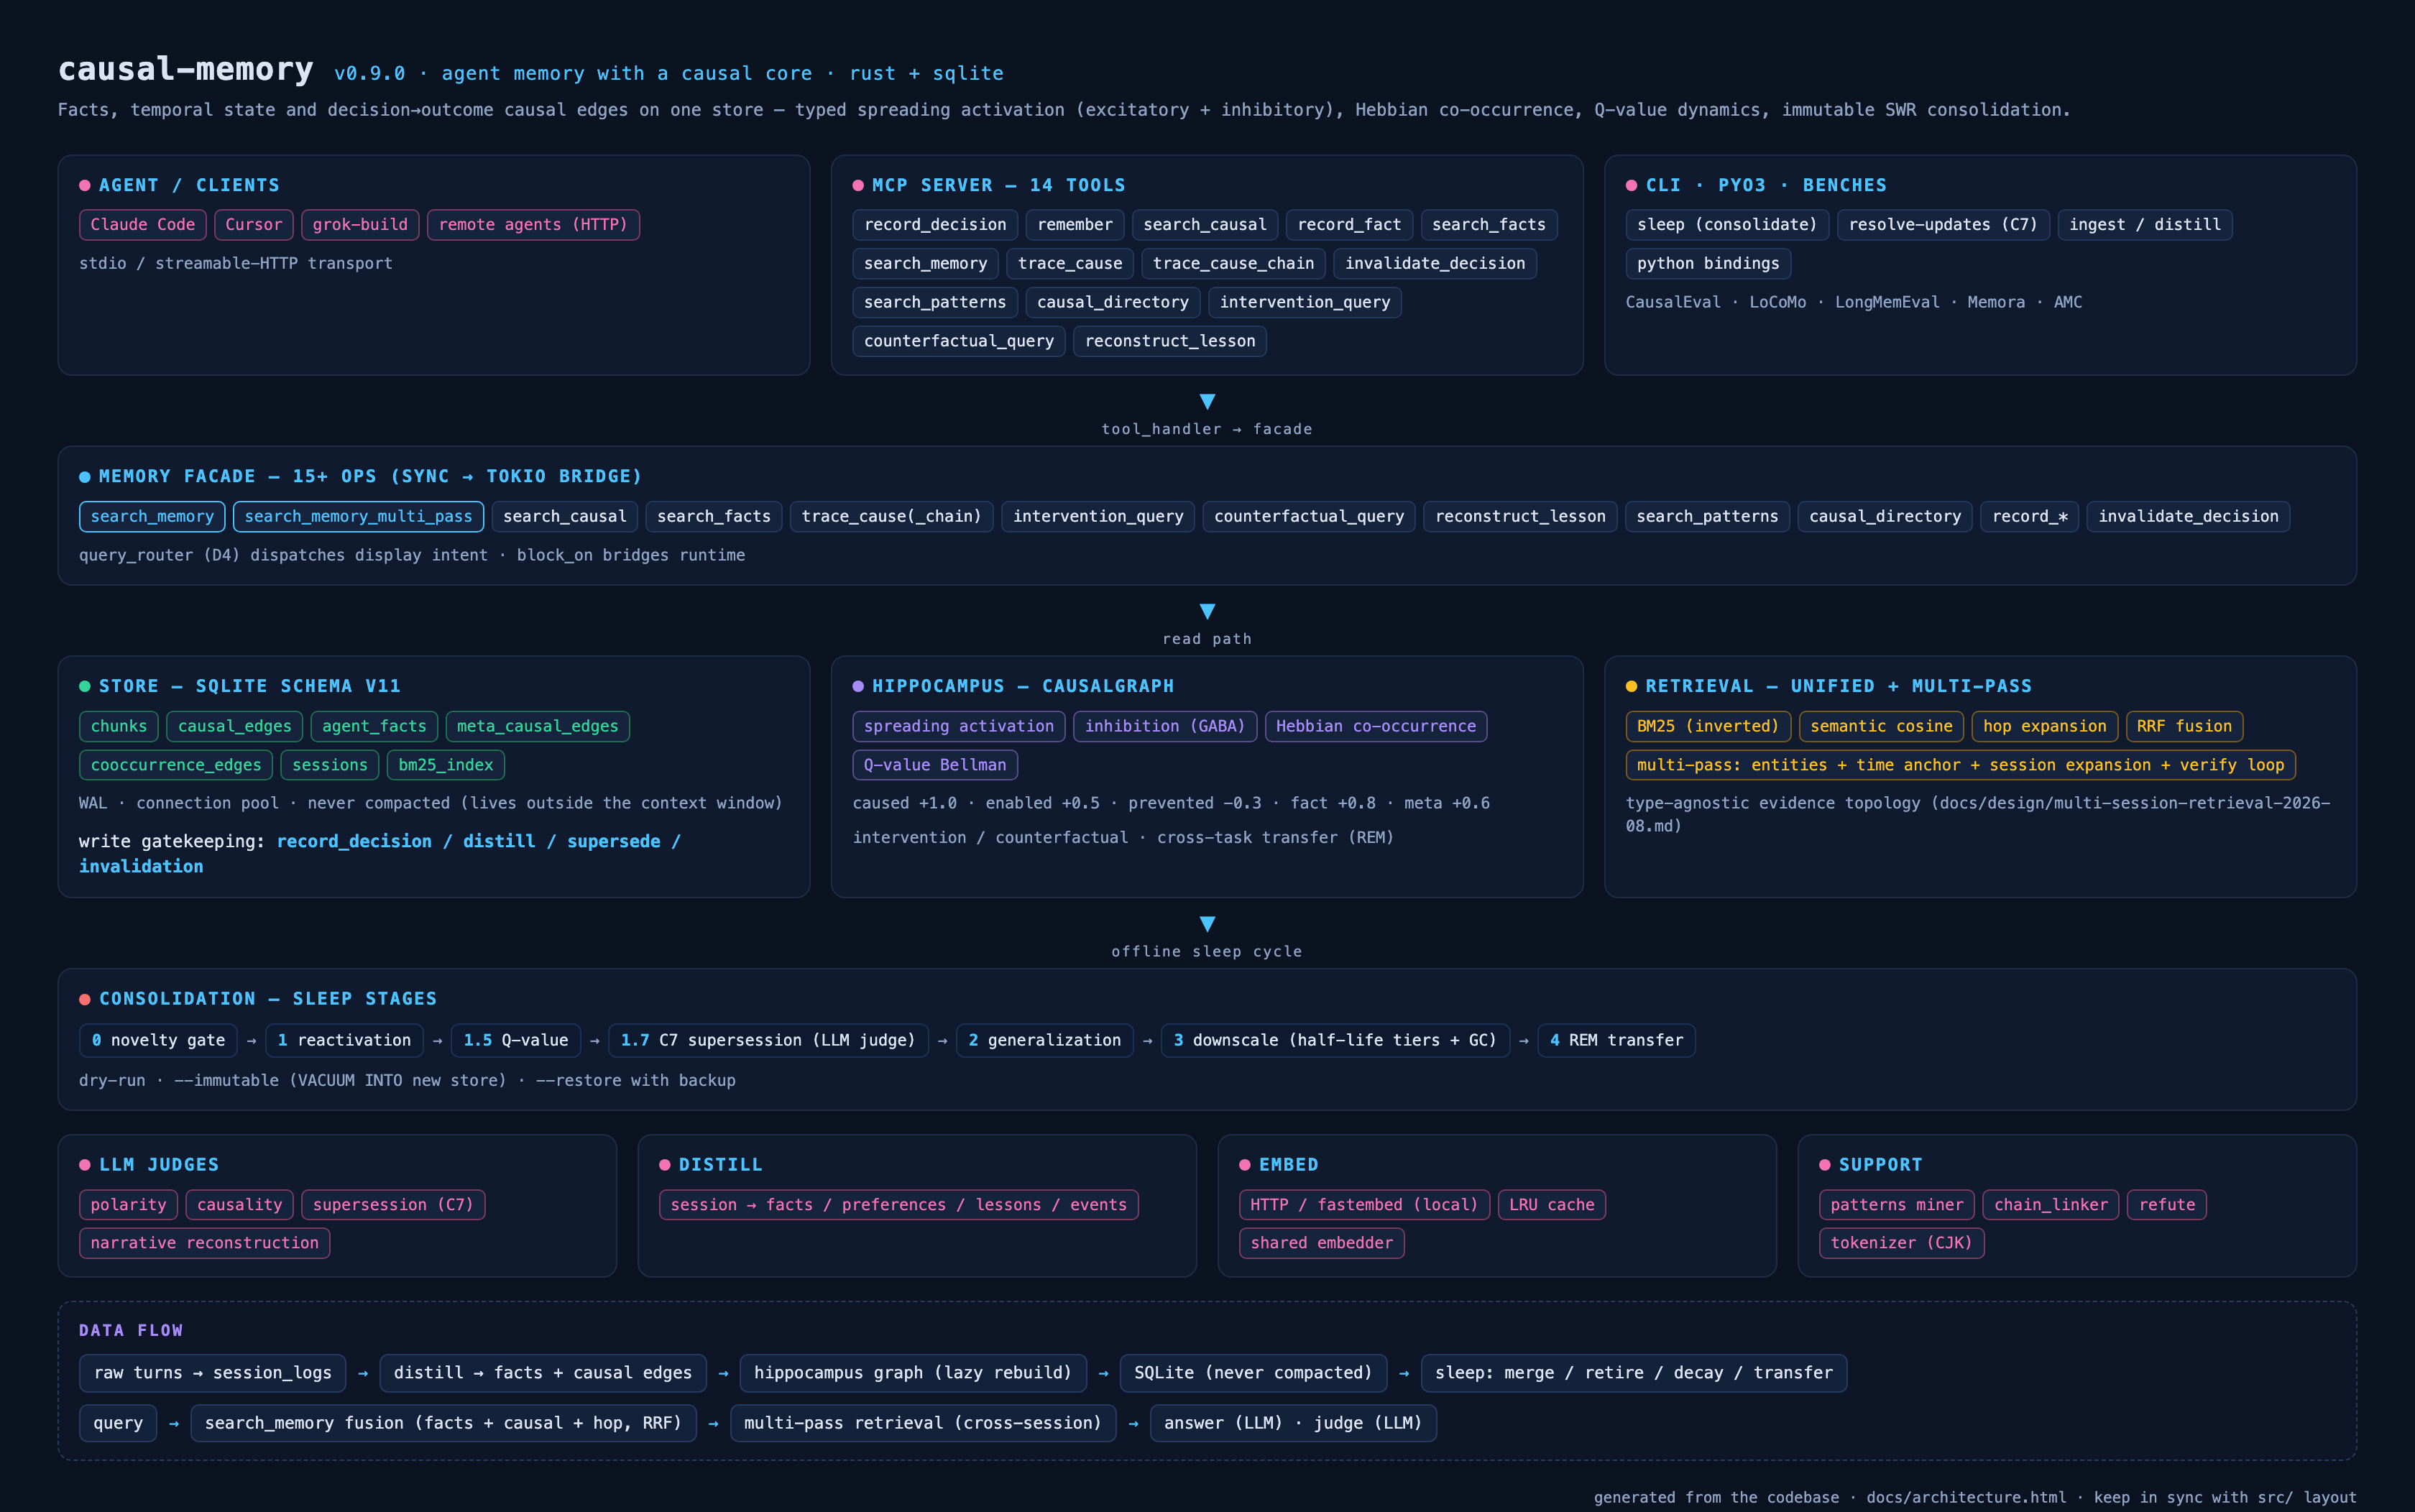
An agent memory system with a causal core — and the only one that models inhibition.
Facts, temporal state, and decision → outcome causal edges on one SQLite store,
powered by a hippocampus-style engine: typed spreading activation (excitatory
and inhibitory), Hebbian co-occurrence reinforcement, Q-value dynamics, and
immutable SWR consolidation. Agents recall happened, it was true,
it worked — and they acted differently.
Causal memory layer for AI agents — MCP server that records decision→outcome relationships. Survives compaction.
Every agent forgets why it made past decisions after a few context compactions.
It re-fixes the same bug the same wrong way, re-debates the same architecture
choice, relearns the same lesson.
This happens because causal information is the most fragile type under text
compaction. Real-LLM benchmark (grok-build's production compaction prompt):
Compactions (k)
Textual recall
Causal-table recall
1
100%
100%
2
85%
100%
3
55%
100%
5
45%
100%
The causal table survives because it lives outside the agent's context window —
compaction cannot touch it.
Demo
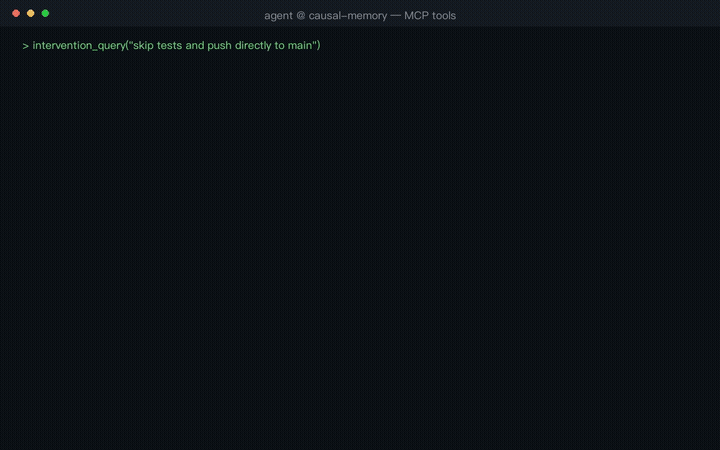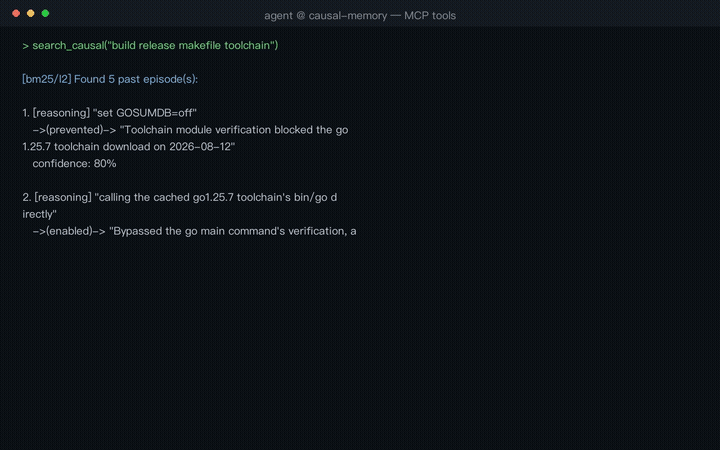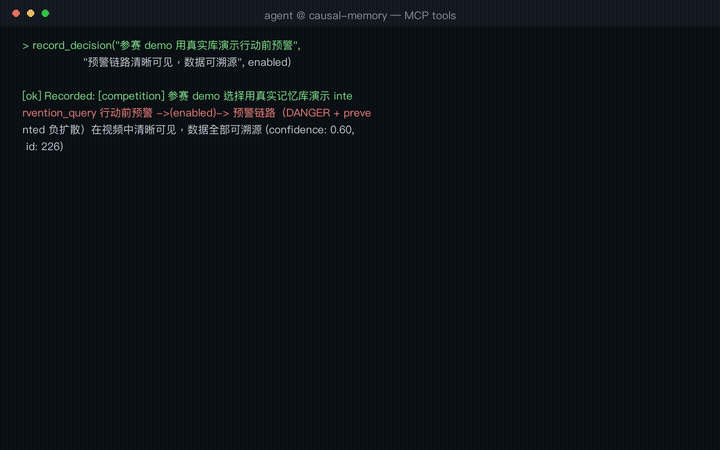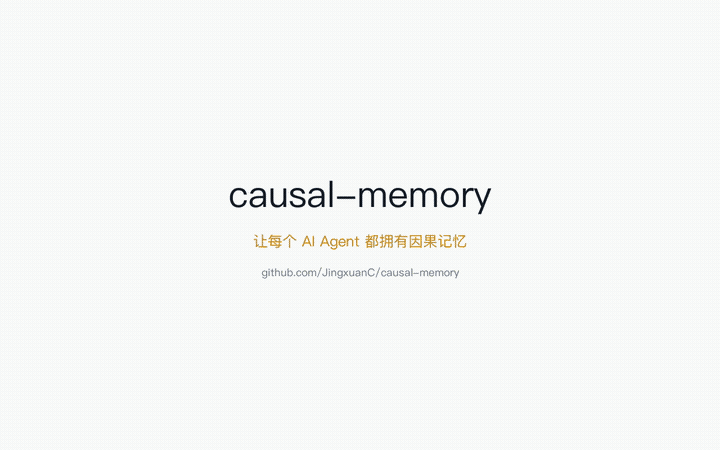
30-second single scene — the agent is about to git push --no-verify;
intervention_query fires a DANGER chain citing the lesson it recorded last
time ("production login failed for 40 minutes; emergency rollback"):
CausalEval — the causal memory benchmark (primary)
Most agent-memory benchmarks (LoCoMo, LongMemEval, Memora) test fact recall
("what is the user's preference"). causal-memory's differentiators — typed
causal edges, inhibition, intervention prediction, cross-task transfer — are
invisible on those suites. CausalEval measures them.
Design: the causal graph is the answer key. Typed DAGs are generated
deterministically; conversations are narrated from the graph; gold answers are
derived from graph structure — zero hand annotation, zero ambiguity.
CausalEval v13 (soft supersession) — 140 questions, 20 graphs (same LLM,
same judge; v12 baseline was 70q/10 graphs; mem0 comparison ran on the 70q
protocol):
Capability
causal-memory
v12 (70q)
mem0 (70q)
What it tests
C7 Update
100%
50%
80%
Supersede old belief after falsification (soft superseded_by annotation)
C3 Counterfactual
95%
90%
80%
Choosing between alternatives with known outcomes
C2 Intervention
75%
70%
40%
Forward prediction: "if X again, what happens?"
C4 Inhibition
80%
90%
50%
Distinguishing root-cause fix vs blast-radius limiter (prevented edges)
C1 Attribution
85%
90%
90%
Backward causal chain → root cause
C5 Temporal-causal
90%
100%
90%
Ordering on a causal chain
C6 Lesson transfer
20%
20%
30%
Cross-task analogy via meta edges (open limitation)
Overall
78%
81%
65%
Key result: C7 update 50% → 100% (+50pp, 20/20 questions) and it holds at
doubled sample size. Soft supersession annotates superseded edges
(superseded_by) instead of hiding them — the falsification signal reaches
the answer model while the old lesson stays retrievable for counterfactuals
(C3 unharmed at 95%). The C6 gap (20% vs mem0 30%) is the remaining open
limitation; C1/C4/C5 dips vs v12 are within re-distillation variance and
new-graph difficulty (v12 and v13 do not share a distilled corpus).
Fact-recall benchmarks (not our strong suit)
On traditional fact-recall suites, causal-memory performs competitively but
does not beat mem0 — this is expected, because fact recall is mem0's
specialty and not where causal-memory adds value.
Core innovation: the excitatory/inhibitory duality. HeLa-Mem (ACL 2026) builds
the excitatory side (Hebbian co-activation, positive spread). causal-memory adds
the inhibitory side (prevented edges spread negative activation — a GABA
analogue). A complete memory needs both: "what caused this" and "what prevents
this from happening again."
First-class installers: Claude Code (integrations/claude-code/) and
Codex CLI (integrations/codex/) — MCP registration + activation
prompt/skill in one idempotent script each.
No Rust toolchain? pip install causal-memory puts the same causal-memory
console script on your PATH (the full CLI — bare invocation is the stdio MCP
server), so "command": "causal-memory" works as the MCP entry too.
To teach the agent when to use the memory tools (agents don't call them
proactively without instruction), install the bundled agent skill
skills/causal-memory/SKILL.md:
Guided installer (recommended) — one command installs the skill, the
causal-memory server, and the MCP registration across every detected client
(Claude Code / Cursor / Opencode / Claude Desktop / Kimi Code):
./install.sh                     # interactive, walks you through each step
./install.sh --yes               # non-interactive, accept all defaults
./install.sh --uninstall         # remove the skill (+ optional MCP)
Or via the Skills CLI, or by hand:
# Skills CLI (skills.sh ecosystem) — works with Claude Code, Cursor,
# Kimi Code CLI, Codex, Copilot and more:
npx skills add JingxuanC/causal-memory@causal-memory
…or copy skills/causal-memory/ into your agent's skills directory
(e.g. ~/.agents/skills/causal-memory/), or paste CLAUDE.md
into your system prompt / AGENTS.md.
HTTP transport (remote agents, multi-agent shared memory)
GET /metrics                    Prometheus text (RED + recall metrics)
GET /healthz / /readyz          liveness / readiness (readiness probes the store)
GET /debug/recall?query=...     run a recall now, return the full JSON trace
                                (seeds, hop summary, per-result provenance)
GET /debug/recalls              newest-first recall audit rows (persisted,
                                schema v13 recall_audit table; survives restarts)
/metrics and /debug/* expose the recall corpus, so they accept opt-in
bearer auth: set CAUSAL_MEMORY_HTTP_AUTH_TOKEN (env or
causal-memory setconfig) and they require
Authorization: Bearer <token> (unset = open, the previous behavior).
/healthz / /readyz stay open on purpose — kubelet probes cannot send
bearer headers and leak nothing. /mcp client auth is a separate
mechanism: per-tenant bearer tokens (see Multi-tenant HTTP below).
Without the token, do not expose
the port to the public internet.
Structured JSON logs on stderr: CAUSAL_MEMORY_LOG_FORMAT=json.
Multi-tenant HTTP (per-tenant databases)
Point CAUSAL_MEMORY_TOKENS_FILE (env or causal-memory setconfig) at a
JSON file mapping bearer tokens to tenant names:
With the file configured and non-empty, /mcp requires
Authorization: Bearer <token>, and each tenant reads and writes its own
SQLite store at <db-dir>/tenants/<tenant>.<fnv1a-hash>.db — one database
per tenant, opened lazily on first request, so one tenant can never see
another's facts or causal edges (covered by an end-to-end isolation test).
Missing or unknown tokens get 401 and never create a database file. The
file is reloaded when its mtime changes, so tenants can be added or revoked
without a restart; if the file turns unreadable at runtime the last-good
map stays in force (fail closed).
Unset (or an empty/unreadable file) keeps the previous behavior: no /mcp
auth, one shared store — local and stdio usage are unaffected. The startup
log states the mode: auth=multi-tenant (N tokens) vs auth=open.
Memory residency: every active tenant holds its own CausalStore and
in-memory graph, so RSS grows with the tenant count — see
docs/design/enterprise-scaling.md
before packing many tenants into one process. The observability endpoints
(/metrics, /debug/*) keep reporting on the default store and are still
gated by CAUSAL_MEMORY_HTTP_AUTH_TOKEN, independently of tenant auth.
With local embeddings (no API key needed)
cargo build --release --features local-embed
# Uses BAAI/bge-small-en-v1.5 (384 dims, ~130MB, downloads once then offline)
All 14 memory operations are also available as a Python package, built on the
same causal_memory::memory::Memory facade the MCP server uses:
cd crates/causal-memory-py
pip install maturin
maturin develop          # builds and installs into the active venv
from causal_memory import CausalMemory

mem = CausalMemory("~/.local/share/causal-memory/causal.db")  # or CausalMemory.in_memory()
mem.record_decision("used Redis mutex for cache stampede protection",
                    "deadlock under load", "caused", "concurrency",
                    context="go 1.22, single redis, 5k rps")
print(mem.search_causal(query="cache stampede protection"))
print(mem.intervention_query("skip the test suite before shipping"))
Methods mirror the 17 MCP tools one-to-one and return the same text. Embedding
and LLM features use the same CAUSAL_MEMORY_EMBED_* / CAUSAL_MEMORY_LLM_*
environment variables; without them the bindings degrade gracefully to
BM25-only retrieval. Smoke tests: maturin develop && pytest tests/.
macOS note: always build the bindings through maturin. Plain
cargo build -p causal-memory-py --release fails to link — the Xcode CLT
Python ships no libpython3.9 dylib (this is why the py crate sits outside
the workspace default-members).
Integrations
Hermes memory provider
hermes-plugin/ turns causal-memory into a drop-in Hermes
MemoryProvider — flat facts + decision→outcome causal lessons on one local
SQLite store, per-profile by construction
(<hermes_home>/causal-memory/causal.db). Wired hooks: system-prompt causal
directory, budgeted prefetch recall, non-blocking sync_turn write-behind,
and a hermes causal-memory stats CLI. Because the store lives outside the
context window, Hermes compaction can't touch it. Install and configuration:
hermes-plugin/README.md.
DeepSeek Harness (DSH) native plugin
dsh-plugin/ mounts all 16 causal-memory tools onto DSH's
ctx.tools with clean names (no mcp__ prefix) and injects a system-prompt
block telling the model when to consult the causal store. Zero runtime
dependencies — JSON-RPC over stdio straight to the causal-memory binary.
One-line install: dsh plugin --profile web add "$PWD/dsh-plugin" (needs the
causal-memory binary — pip install causal-memory, or a repo
cargo build --release).
Details: dsh-plugin/README.md.
Seventeen MCP tools
Tool
When to call
What it does
record_decision
After acting on a decision
Logs decision → outcome as a causal edge with relation type; optional context records the world state — same task_tag + context becomes a comparable branch (fork)
Contrastive: compares recorded outcomes of two alternatives; renders same-context branches (natural experiments) when they exist; every verdict logs a falsifiable prediction
prediction_report
Periodic calibration check
Prediction-ledger accuracy overall / per method / per task_tag + pending list
causal-memory sleep --dry-run   # preview what would change
causal-memory sleep             # run consolidation cycle
Immutable SWR 2.0: produces a delta + clone (original graph untouched), with full
audit log. Triple-criterion GC (weak AND dormant AND zero-access). Triggers
automatically when novelty entropy exceeds threshold.
Causal distill pipeline
The distiller extracts structured memories from raw conversations:
Raw turns go to session_logs (audit/replay only) — they never enter the
retrieval pool. This write-time gatekeeping keeps BM25 precision high.
System layer coverage
All 16 designed layers have end-to-end validation (322 workspace tests):
Layer
Benchmark
Tests
Fact layer
Memora / LoCoMo
—
Causal edges (caused/enabled/prevented)
Capability
12
Hippocampus spreading activation
Capability
—
SWR consolidation (LTP/LTD/GC)
Longitudinal
5
Q-value dynamics
Longitudinal
3
Novelty entropy trigger
Longitudinal
3
Sleep-wake cycle
Longitudinal
1
Meta-edge pattern mining
Advanced
3
Co-occurrence Hebbian
Advanced
3
Intervention query (forward sim)
Advanced
4
Trace cause chain
Capability
2
Inhibitory ablation
Inhibition
2
Distill / retrieval / facts
Memora / LoCoMo / LME
—
Compaction survival
Compact
—
Agent trap-world
Agent
—
Pipeline e2e
Migration / Pipeline
2
Build & test
cargo build --release                    # Build binary
cargo test --workspace --no-fail-fast  # Run 322 tests
cargo test --features local-embed     # Run with ONNX embedding tests
cargo clippy --workspace -- -D warnings # Lint
Agent Memory Challenge (AMC/01)
causal-memory enters the Agent Memory Leaderboard
first evaluation cycle via an Add/Search integration server — a thin HTTP
frontend over the same Memory facade the MCP server runs (BM25 + semantic +
entity retrieval, RRF-fused; one store per user_id):
cargo build --release --bin causal-memory-amc
./target/release/causal-memory-amc --db-dir amc_data --port 8787 --write-mode raw
# --write-mode raw (no LLM, platform default) | distill (write-time LLM extraction)
# POST /add (store memory, user_id-isolated) · POST /search (ordered evidence) · GET /health
Docker route: docker build -t causal-memory-amc . && docker run -p 8787:8787 -v amc-data:/data causal-memory-amc.
Submission details, method description, and the participation checklist live in
docs/benchmarks/amc-2026.md.
Test suite breakdown:
186 library unit tests (types, store, distill, patterns, hippocampus)
Full documentation map: docs/README.md — design docs,
benchmark protocols, evaluation reports, paper drafts, and the literature
survey.
This project is the engineering output of 17 research notes on agent memory
architecture (insights/01-17),
a teardown of 7 production agent frameworks, and deep analysis of 10+ memory
research papers. Key references:
HeLa-Mem (ACL 2026) — Hebbian spreading activation (our closest competitor; we add the inhibitory side)
Anthropic Dreams API — immutable consolidation pattern (aligned in SWR 2.0)
अभी टूल सूची नहीं है। रिमोट सर्वर को पहले हेल्थ चेक के बाद सूची मिलती है।
FAQ
सवाल
Causal Memory कैसे इंस्टॉल करें?
इस पेज पर Cursor, Claude Desktop, Claude Code या VS Code के लिए stdio कॉन्फ़िग कॉपी करें। यह पब्लिशर का इंस्टॉल इस्तेमाल करता है, PlugMCP प्रॉक्सी नहीं।
क्या Causal Memory के लिए API key चाहिए?
इस रिकॉर्ड में कोई ज़रूरी एनवायरनमेंट वेरिएबल दर्ज नहीं है।
Causal Memory कौन सा ट्रांसपोर्ट इस्तेमाल करता है?
Causal Memory stdio पर लोकल चलता है।
Causal Memory की पिछली जाँच कब हुई थी?
पिछली जाँच 2026-10-27 को हुई। Causal memory layer for AI agents — MCP server that records decision→outcome relationships. Survives compaction.