Install · Use · Workbench · AI agents · Reading a score · ⭐ Star
Power your agent
पब्लिशर का इंस्टॉल। PlugMCP एंडपॉइंट नहीं।
Host a copy with our keys and logs.
रजिस्ट्री में अभी कोई पैकेज्ड रिलीज़ नहीं है। रिपॉज़िटरी का README देखें.
रिमोट URL या आपकी मशीन पर कमांड? दोनों इंस्टॉल में क्या अंतर है
PlugMCP पर चलाएँ
A new server you create. It is not this listing's official endpoint. Use the publisher install when you want their URL and their credentials.
लॉन्चDoes your AI-generated sound match what you asked for?
Sonicproof is a local QA tool for generative audio — sound effects, music and ambience from Stable Audio and friends. It listens with one multilingual model, Google's EmbeddingGemma 2, which puts text, sound, images and video in one shared space:
Everything runs on your machine — no uploads, no API keys — and you can use it from a local workbench in your browser, from your AI agent (MCP server + agent skill), or from the command line and Python.
$ sp check dog_bark.wav "a dog barking"
╭─ dog_bark.wav ───────────────────────────────────────────────────────╮
│                                                                      │
│   STRONG   +3.79σ  ━━━━━━━━━━━━━━━━━━━━━━━━━━━━                      │
│  clearly sounds like the prompt                                      │
│                                                                      │
│    prompt  “a dog barking”                                           │
│   ranking  #1 of 438 descriptions for this clip                      │
│  evidence  cos 0.765 · clip-side +4.22σ · prompt-side +3.36σ         │
│                                                                      │
│  Heard as                                                            │
│  +3.79σ  a dog barking  ✓  animals                                   │
│  +3.37σ  a small dog yapping  animals                                │
│  +3.10σ  a dog whining  ✓  animals                                   │
│  +3.03σ  a dog growling  ✓  animals                                  │
│  +2.26σ  a duck quacking  animals                                    │
│                                                                      │
╰──────────────────────────────────────────────────────────────────────╯
uv tool install "sonicproof[model]"        # or: pip install "sonicproof[model]"
sonicproof doctor --load                   # downloads the model once and checks the setup
Python 3.11 or newer (tested on 3.11–3.13). Apple Silicon (MPS), CUDA and CPU all work. sp is a short alias for sonicproof.
The model — EmbeddingGemma 2, about 1.5 GB — is downloaded from Hugging Face into its usual cache on first use. No Hugging Face account or token is needed.
ffmpeg is only needed for M4A / AAC / MP4 and other formats libsndfile can't read, and for video in
fit / search. WAV, FLAC, OGG and MP3 work without it.
Windows + NVIDIA GPU: the PyPI build of PyTorch for Windows is CPU-only (uv tool install and uvx
get that build too). Everything works on the CPU, only slower. To use the GPU, make an environment with the
CUDA build of both torch and torchvision first — installing only torch lets sonicproof[model] pull a
newer torchvision that silently swaps it back to the CPU build. In PowerShell:
uv venv $HOME\sonicproof-env --python 3.12
# cu128 or whichever CUDA version pytorch.org lists for your GPU
uv pip install --python $HOME\sonicproof-env torch torchvision --index-url https://download.pytorch.org/whl/cu128
uv pip install --python $HOME\sonicproof-env "sonicproof[model]"
& $HOME\sonicproof-env\Scripts\sonicproof.exe doctor --load   # the PyTorch row should say "device cuda"
With plain pip in a venv it is the same two installs, in the same order. Use
$HOME\sonicproof-env\Scripts\sonicproof.exe (or add that folder to PATH) wherever this README says
sonicproof, including the MCP server command below.
Technical checks only? qc needs no model: pip install sonicproof (without [model]) is enough.
Latest main: git clone https://github.com/kanaworksai-hue/sonicproof, run uv sync --extra model
inside it, and run commands with uv run sp … (or uv run --project /path/to/sonicproof sp … from any other
folder).
# Prompt adherence. Omit the prompt to read it from a Stable Audio .json sidecar.
sp check explosion.wav "a huge explosion with debris"
sp check thunder.wav

# Pick the best take
sp rank "a wooden door creaking open" door_v1.wav door_v2.wav door_v3.wav door_v4.wav

# Technical checks (no model needed). Exit code 1 if anything fails — handy in scripts.
sp qc *.wav
sp qc ambience_loop.wav --loop --target-lufs -16

# Everything in one scorecard: SHIP / REVIEW / REDO. --strict exits 1 unless it is SHIP.
sp report footsteps.wav "footsteps on gravel"
sp report footsteps.wav "footsteps on gravel" --strict

# Does the sound suit the picture? Words about the scene are optional.
sp fit sizzle.wav --image kitchen.png
sp fit rumble.wav --video storm.mp4 "a stormy night with thunder"
sp fit trailer.mp4                          # a video's own soundtrack against its own picture
sp index ~/SFX                              # once; re-runs only read new or changed files
sp search "rain on a tin roof" --in ~/SFX
sp search --like take_03.wav --in ~/SFX     # sounds like this one
sp search --image frame.png --in ~/SFX      # sounds that suit this picture
sp dedupe ~/SFX                             # duplicates and near-duplicates (nothing is deleted)
The library folder is always given explicitly: index DIR, search … --in DIR, dedupe DIR (your home
folder, a drive root and system folders are refused — point at the folder that holds your sounds).
The index lives in ~/SFX/.sonicproof/; --in-cache keeps it in Sonicproof's cache instead, so nothing is
written into the folder (read-only folders use the cache automatically). search and dedupe bring the index
up to date on the fly, so sp index is optional.
--json and exit codesThe analysis commands — check, rank, qc, report, fit, index, search, dedupe — take --json
(doctor, serve, mcp and skill don't). qc --json always prints an array, one record per file, even for
a single file. In qc and rank, a file that can't be read is marked "error" and the rest are still
processed; the exit code is then 2.
With --json, errors are JSON too — {"error": {"code": "not_found", "message": "…", "file": "…"}} on stdout
— so a script doesn't have to parse a traceback. Command-line usage mistakes (a missing argument, an option
value out of range) are the exception: they print the usual usage message and exit 2. Set
SONICPROOF_DEBUG=1 to see the full traceback.
sonicproof serve                            # opens http://localhost:7788
sonicproof serve --port 8800 --no-open      # another port, no browser tab
The address is printed in the terminal (http://localhost:<port>, 7788 unless you pass --port); open it
yourself if you used --no-open or no tab appeared. Ctrl+C stops the server.
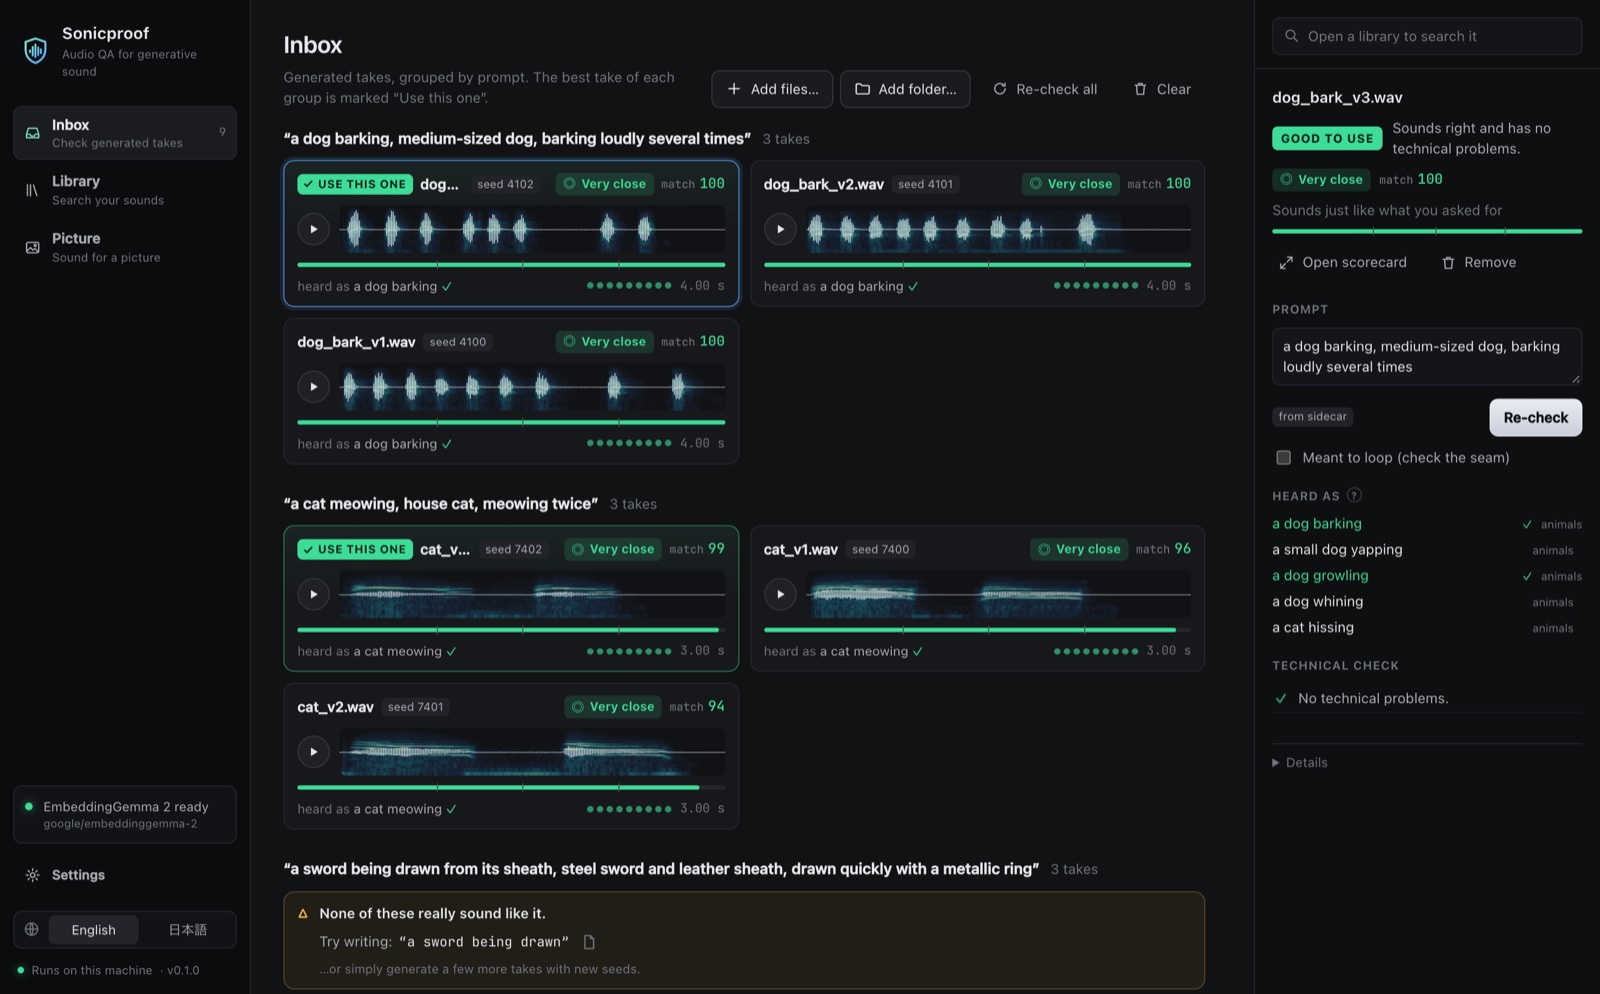
.json sidecars (or type
your own). Takes of the same prompt are grouped, ranked, and the best one is marked Use this one. When
nothing in a group sounds right, it says so and suggests a wording to try next.
Each card shows the waveform over a spectrogram, a plain verdict (◎ Very close · ○ Close · △ Somewhat ·
✕ Not a match), a 0–100 match bar and a dot per technical check; technical findings are spelled out in
plain words with the fix.The raw numbers behind each verdict are one click away under Details, or shown everywhere with Settings → Pro mode. Settings also shows how much the cache uses and clears it; removing files from the Inbox deletes the copies made when they were dropped (your originals are never touched).
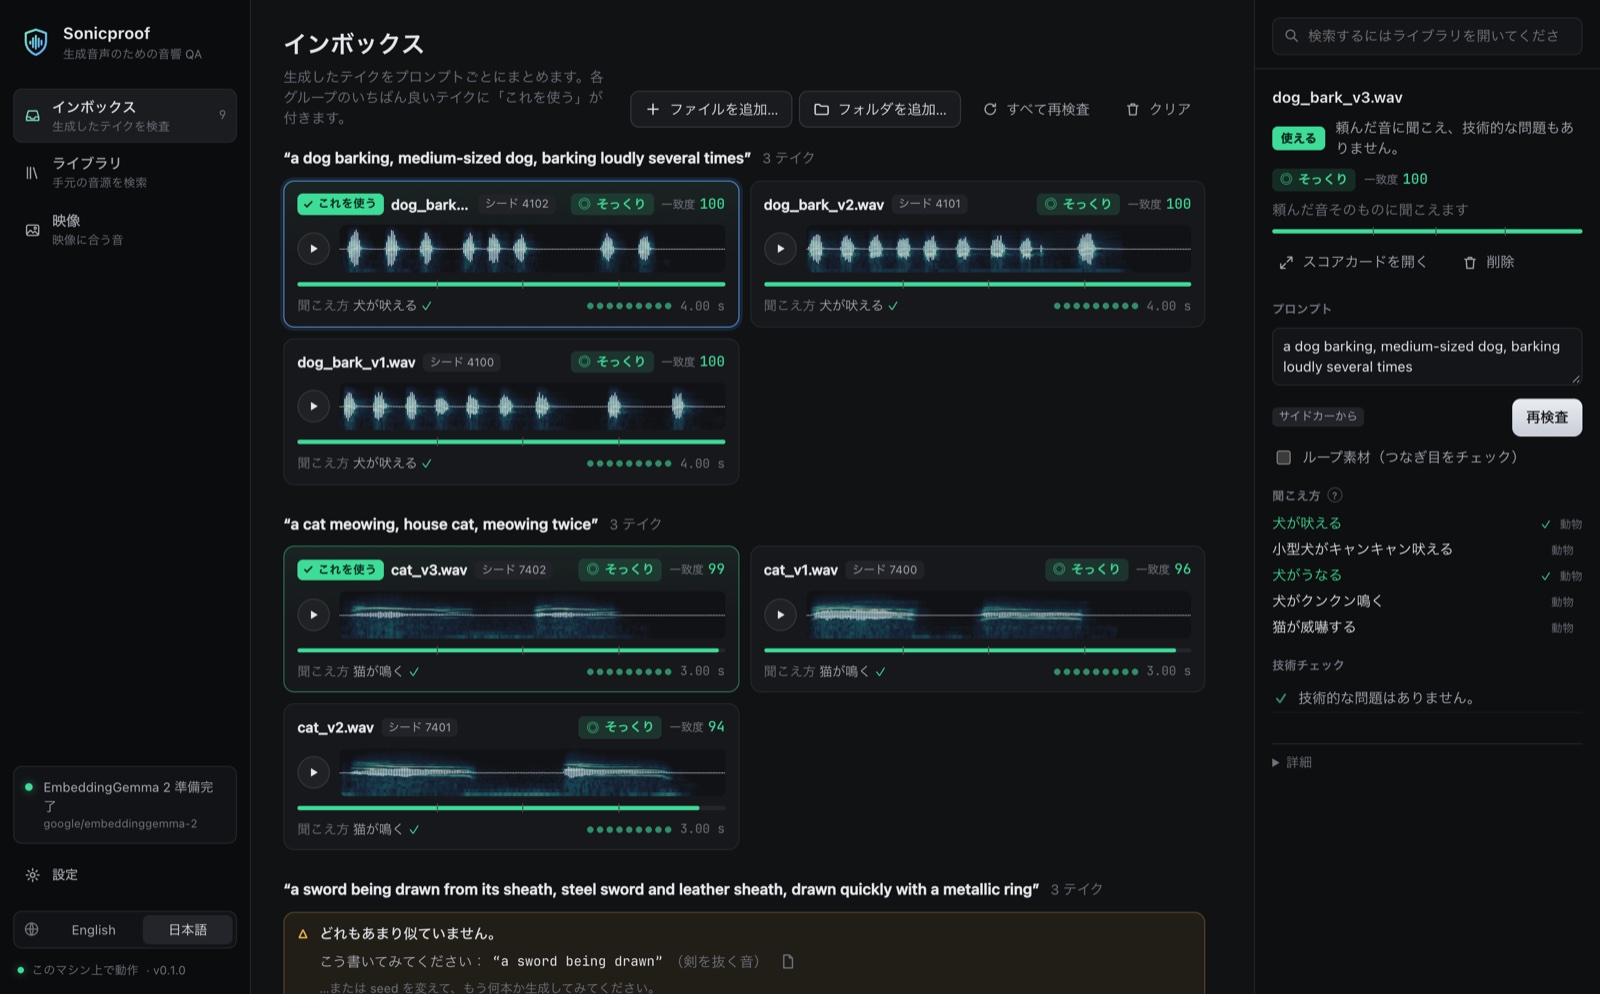
The interface is in English and Japanese; it follows your browser and can be switched. Sound only plays when
you press play. The server listens on localhost only and refuses requests from other sites.
The quickest way: give your agent the link to this repository and ask it to check the sounds it generates. Everything it needs is in this section.
1. Install and download the model once, in a terminal (Install). The MCP server never starts
the 1.5 GB download inside a tool call — it would look like a hang — so make sure sonicproof doctor --load
has run once. Or, without a permanent install:
uvx --from "sonicproof[model]" sonicproof doctor --load
2. Add the MCP server — tools check, rank, qc, report, fit, search, dedupe, index. Each returns
the same records the matching CLI command prints with --json. The model loads once and stays loaded.
# Claude Code
claude mcp add sonicproof -e HF_HOME="${HF_HOME:-$HOME/.cache/huggingface}" -- uvx --from "sonicproof[model]" sonicproof mcp
# Codex
codex mcp add sonicproof --env HF_HOME="${HF_HOME:-$HOME/.cache/huggingface}" -- uvx --from "sonicproof[model]" sonicproof mcp
# any client: streamable HTTP at http://127.0.0.1:7789/mcp
sonicproof mcp --http --port 7789
On Windows the server finds the default cache (%USERPROFILE%\.cache\huggingface) by itself:
claude mcp add sonicproof -- uvx --from "sonicproof[model]" sonicproof mcp
codex mcp add sonicproof -- uvx --from "sonicproof[model]" sonicproof mcp
If you moved the cache with HF_HOME, HF_HUB_CACHE or the older HUGGINGFACE_HUB_CACHE, pass it on — some
clients (Codex, for one) start the server without it, and the server then reports the model as not downloaded.
In PowerShell:
codex mcp add sonicproof --env "HF_HOME=$env:HF_HOME" -- uvx --from "sonicproof[model]" sonicproof mcp
# HF_HUB_CACHE or HUGGINGFACE_HUB_CACHE: pass the folder as HF_HUB_CACHE
codex mcp add sonicproof --env "HF_HUB_CACHE=$env:HUGGINGFACE_HUB_CACHE" -- uvx --from "sonicproof[model]" sonicproof mcp
# Claude Code: the same with -e instead of --env
Other clients take the same command in their JSON config (write out the absolute path of your cache):
{ "mcpServers": { "sonicproof": {
    "command": "uvx", "args": ["--from", "sonicproof[model]", "sonicproof", "mcp"],
    "env": { "HF_HOME": "/Users/you/.cache/huggingface" } } } }
HF_HOME: MCP clients start servers with a reduced environment. Passing it makes the server use
the same Hugging Face cache as your terminal, so the model is not downloaded a second time. If you set
HF_HUB_CACHE (or the older HUGGINGFACE_HUB_CACHE) instead, pass that folder as HF_HUB_CACHE.127.0.0.1 only and refuses requests from web pages not served from localhost, but it has no
authentication: any process on your machine can call it. Use stdio when that matters.main: use uv run --project /absolute/path/to/sonicproof --extra model sonicproof mcp
as the server command (--project keeps the caller's working directory; --directory would change it).3. Add the agent skill — it teaches an agent the loop that makes generated audio trustworthy: generate several takes → rank them → check the best one → rephrase or reseed when nothing matches → deliver the pick with its scorecard. It ships with the package:
sp skill install              # → ~/.claude/skills/sonicproof/SKILL.md
sp skill install --project    # → ./.claude/skills/sonicproof/SKILL.md (this project only)
sp skill show                 # print it, for agents that read skills from elsewhere
In a clone it lives at src/sonicproof/skill/SKILL.md.
examples/stable_audio_loop.py
runs the same loop as a script, with one MCP client for a Stable Audio server and one for Sonicproof.
If you are an agent reading this repository: do steps 1–3, then follow the skill (sp skill show prints
it). Without MCP, every analysis command works from the shell with --json, e.g.
sp rank "prompt" /abs/a.wav /abs/b.wav --json. Pass absolute local file paths; never play audio to "listen"
— Sonicproof is your ears.
Every clip gets one of four verdicts. The workbench shows them in plain words with a 0–100 match bar; the CLI
and --json give the verdict name and the raw score behind it.
Where the raw score comes from: plain similarity between a prompt and a clip is not very informative — almost any caption scores about the same against any clip — so Sonicproof asks two relative questions and averages them:
Both are measured in standard deviations above those baselines, which is why the CLI prints scores like
+3.79σ. The workbench's match bar maps −1 … +3 onto 0 … 100.
Heard as lists what the clip sounds most like; ✓ marks descriptions that agree with your prompt. When a
verdict surprises you, that list usually explains why. Silent clips (nothing above −60 dBFS) are never scored
as a match: they get "verdict": "miss" with "note": "silent" and rank last. Short one-shots such as UI
clicks are judged normally.
Sonicproof is a second opinion, not a judge: short, concrete prompts ("glass shattering") work better than long ones full of mixing notes, and very short transient sounds are the hardest to tell apart. Always listen before you ship.
fit weighs two pieces of evidence, both calibrated the same way and read on the same verdict scale:
Pictured as marks with ✓ what the clip also sounds like; Heard as marks what the picture also shows. When the fit is weak or a miss, Sonicproof suggests a prompt drawn from the picture — useful for regenerating. Videos are sampled at one frame per second (up to 32 frames, spread evenly over longer clips).
Two sounds can be close in meaning without being the same file — four seeds of the same prompt, say.
dedupe therefore uses the embeddings only to find candidates, then compares the signals themselves
(time-aligned spectral fingerprints), so it groups copies that differ in format, codec, level, sample rate,
channel count or trimmed ends, and leaves different takes alone. In each group it picks the copy to keep —
lossless over lossy, not clipped, more of the spectrum (a higher sample rate only counts when it really
holds more — an upsampled copy does not), more channels, longest, not turned down — and says why.
from sonicproof.judge import Judge

judge = Judge(vision=True)    # one model for everything; Judge() alone is lighter but can't see pictures
result = judge.check("door.wav", "a creaky wooden door")
print(result.verdict, result.score, [a.text for a in result.heard_as])

fit = judge.fit("sizzle.wav", "kitchen.png", "image")
print(fit.verdict, [a.text for a in fit.pictured_as])

from sonicproof.library import Library, find_duplicates, search_text

lib = Library("~/SFX")
lib.update(lambda wave: judge.embedder.embed_audio([wave])[0])
for hit in search_text(lib, judge, "rain on a tin roof"):
    print(hit.path, hit.score, hit.verdict)
for group in find_duplicates(lib):
    print(group.keep, group.reason)
uv sync --extra model --group dev && uv run pytest
cd web && npm ci && npm run dev             # UI with hot reload on :5173; proxies /api to `sp serve` on :7788
npm run build                               # (in web/) writes the bundled UI into src/sonicproof/web
UI strings live in web/src/i18n/ (en.ts, ja.ts); the type checker makes sure both have the same keys.
See CONTRIBUTING.md for tests, linting and pull requests.
Sonicproof is licensed under the MIT License (see also NOTICE). It downloads EmbeddingGemma 2 from Hugging Face on first run — the model is not bundled. The model is released by Google under Apache 2.0, and its model card asks that deployments follow the Gemma Prohibited Use Policy.
The KanaWorks_AI name, logo and the Kana character are © KanaWorks_AI and are not covered by the MIT license. See docs/brand.
Does your AI-generated sound match the prompt? Local QA for generative audio — check, rank, QC, picture-fit and library search with EmbeddingGemma 2. CLI, web workbench, MCP server.
टूल
अभी टूल सूची नहीं है। रिमोट सर्वर को पहले हेल्थ चेक के बाद सूची मिलती है।
FAQ
इस पेज पर Cursor, Claude Desktop, Claude Code या VS Code के लिए stdio कॉन्फ़िग कॉपी करें। यह पब्लिशर का इंस्टॉल इस्तेमाल करता है, PlugMCP प्रॉक्सी नहीं।
इस रिकॉर्ड में कोई ज़रूरी एनवायरनमेंट वेरिएबल दर्ज नहीं है।
Sonicproof stdio पर लोकल चलता है।
पिछली जाँच 2026-10-28 को हुई। Does your AI-generated sound match the prompt? Local QA for generative audio — check, rank, QC, picture-fit and library search with EmbeddingGemma 2. CLI, web workbench, MCP server.
