webmcp-gen
Point it at any website. Get back tools an AI agent can actually call.
Power your agent
पब्लिशर का इंस्टॉल। PlugMCP एंडपॉइंट नहीं।
Host a copy with our keys and logs.
रजिस्ट्री में अभी कोई पैकेज्ड रिलीज़ नहीं है। रिपॉज़िटरी का README देखें.
रिमोट URL या आपकी मशीन पर कमांड? दोनों इंस्टॉल में क्या अंतर है
PlugMCP पर चलाएँ
A new server you create. It is not this listing's official endpoint. Use the publisher install when you want their URL and their credentials.
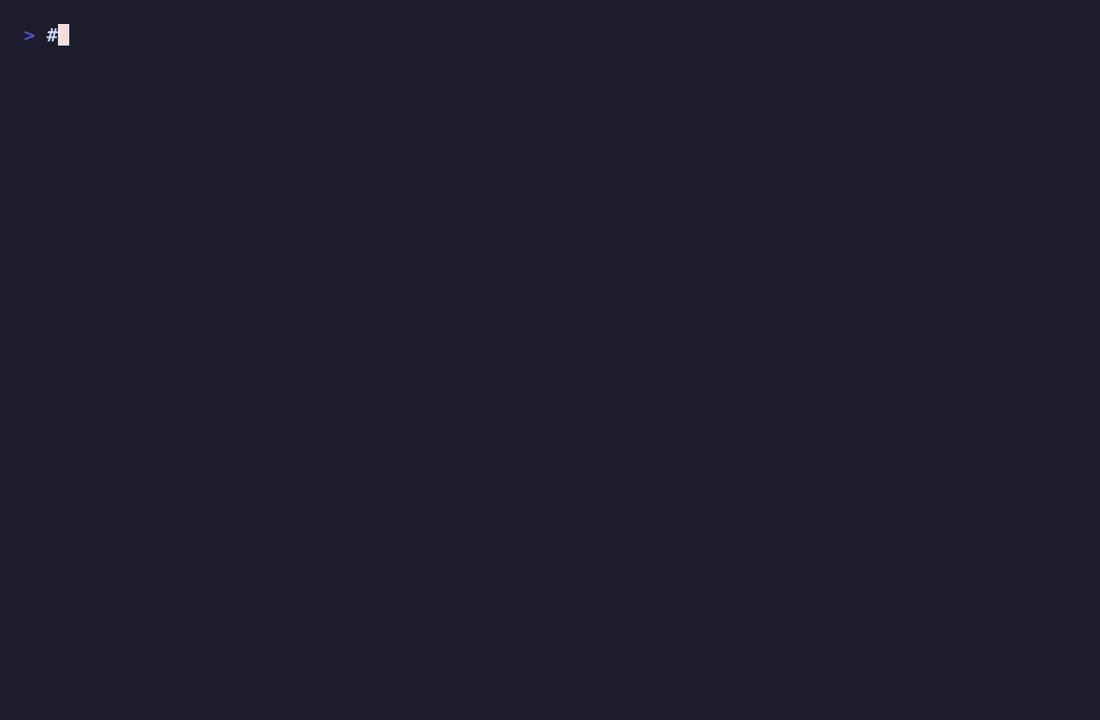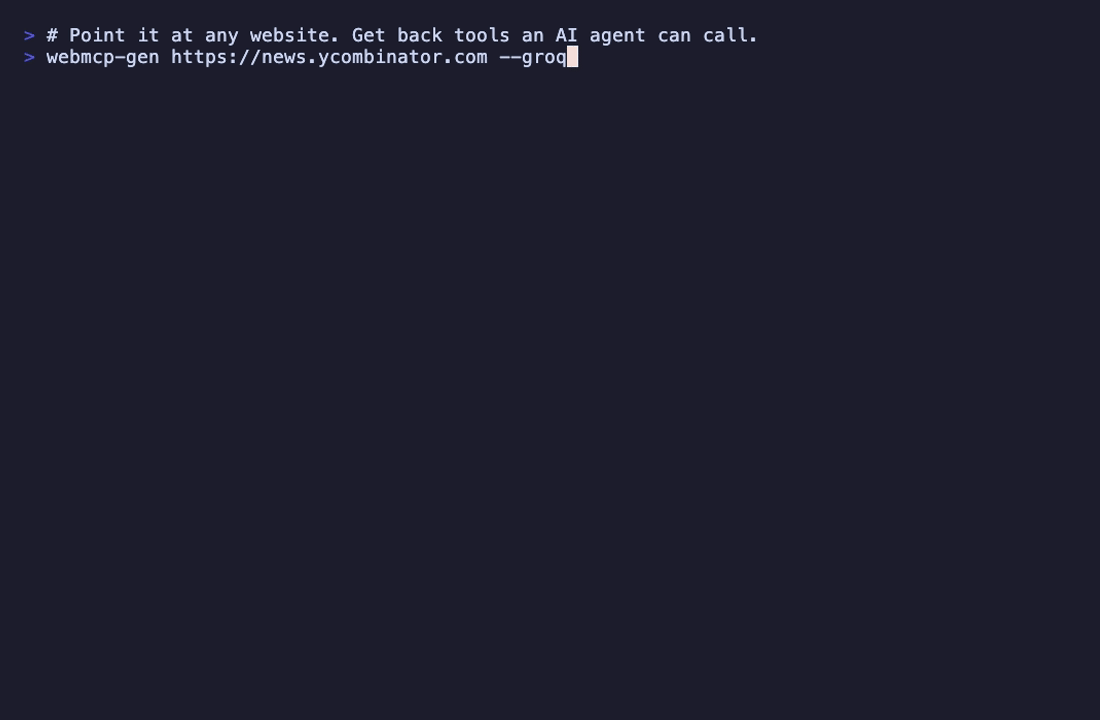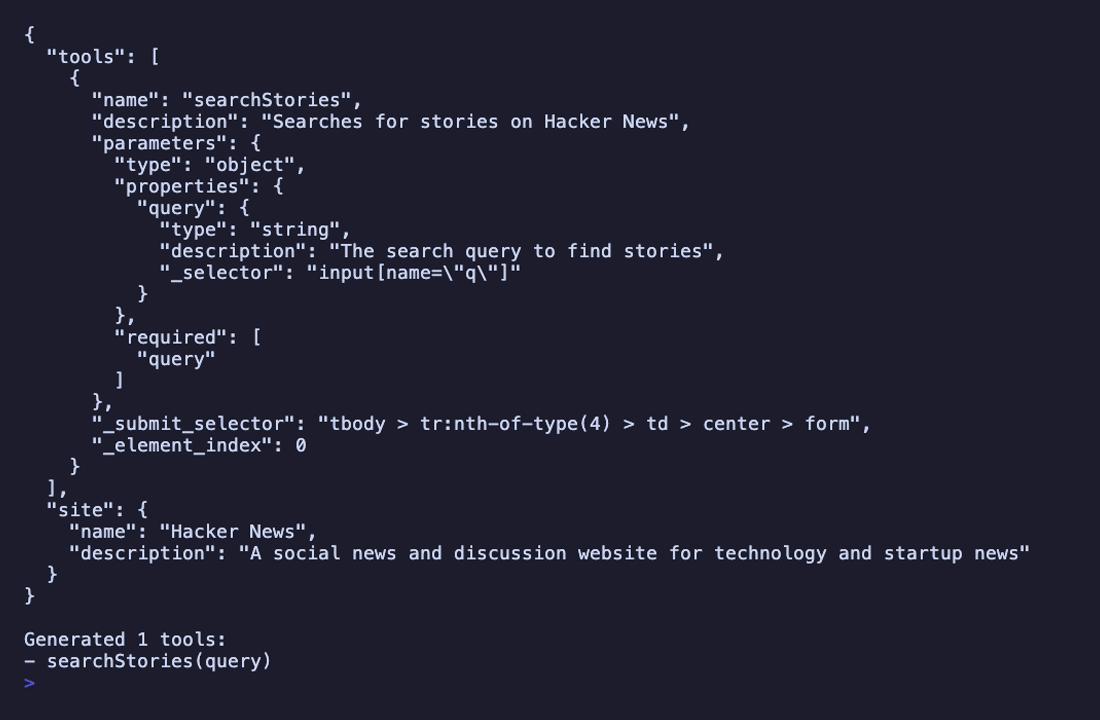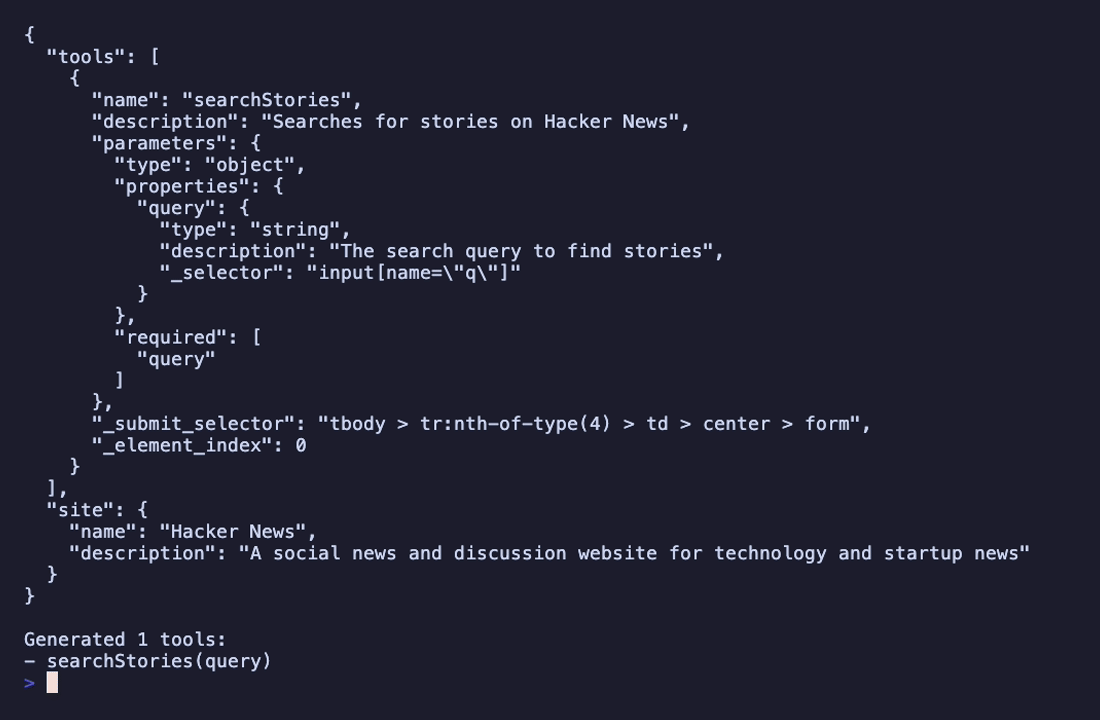
लॉन्चwebmcp-gen https://news.ycombinator.com --groq
{
  "tools": [{
    "name": "searchStories",
    "description": "Search Hacker News stories",
    "parameters": {
      "type": "object",
      "properties": { "query": { "type": "string", "description": "e.g. 'rust async'" } },
      "required": ["query"]
    }
  }]
}
No site cooperation. No API keys from the site. No OpenAPI spec. You give it a URL, it drives a real browser, reads the page the way a person would, and writes the tool definitions an agent needs to use it — and then it can actually run them.
There's a clean story everyone tells about AI agents and the web: agents will call structured tools, websites will expose those tools, everything will be typed and reliable. Google shipped WebMCP in Chrome behind a flag to make exactly this happen. It's a genuinely good idea.
Here's the part that's awkward: adoption is basically zero. No major site has implemented it. Standards take years. In the meantime your agent is still doing the old thing — screenshotting, scraping, clicking at pixel coordinates and praying the layout didn't change.
So there are two ways to wait for the agentic web:
webmcp-gen is option 2. It treats the website's own UI — its forms, its buttons,
its nav — as the spec, because it already is one. A search box with a labeled input
and a submit button is a search(query) tool. Somebody just has to read it and
write it down. That's the whole trick.
flowchart TD
    URL["URL (any website)"] --> Browser

    subgraph EXTRACT ["EXTRACT"]
        Browser["Chromium + Stealth\npatches webdriver, chrome,\nplugins, WebGL"] --> Navigate["Navigate + wait"]
        Navigate --> Hydration["MutationObserver\nwaits for DOM stable"]
        Hydration --> DOM["Walk DOM tree"]
        DOM --> Shadow["Shadow DOM\n(open roots)"]
        DOM --> Iframes["Same-origin\niframes"]
        Shadow --> Collect
        Iframes --> Collect
        DOM --> Collect["Collect interactive\nelements"]
        Collect --> Forms["Forms + fields"]
        Collect --> Buttons["Buttons"]
        Collect --> Links["Nav links"]
        Forms --> Selectors["Stable CSS selectors\n#id > [name] > path"]
        Buttons --> Selectors
        Links --> Selectors
    end

    Selectors --> Analysis

    subgraph ANALYZE ["ANALYZE"]
        Analysis{"LLM available?"}
        Analysis -- yes --> LLM["LLM\nGroq / OpenAI / Ollama\nhttpx + retries"]
        Analysis -- no --> Heuristic["Heuristic engine\ncamelCase naming\nnoise filtering\ndeduplication"]
        LLM --> ToolDefs
        Heuristic --> ToolDefs["WebMCP Tool Definitions\nname + description +\ninputSchema + _selectors"]
    end

    ToolDefs --> Validate["Spec Validator\nWebMCP ToolDescriptor"]
    ToolDefs --> Cache["Disk Cache\nTTL by url+mode+model"]
    ToolDefs --> Output["tools.json"]
    ToolDefs --> Server

    subgraph SERVE ["SERVE · MCP Server"]
        Server["Official MCP SDK"]
        Server --> STDIO["stdio"]
        Server --> SSE["SSE"]
        Server --> SHTTP["streamable-HTTP"]
    end

    Server --> Executor

    subgraph EXECUTE ["EXECUTE"]
        Executor["WebExecutor\npersistent browser"] --> Fill["Fill fields by\nbound CSS selector"]
        Fill --> Submit["Submit form\nor click button"]
        Submit --> Wait["Wait for\nnetwork idle"]
        Wait --> Detect{"Bot wall?"}
        Detect -- yes --> Blocked["blocked:true\nnever fake success"]
        Detect -- no --> Extract["Extract structured\nitems: title/url/snippet"]
        Extract --> Result["ToolResult"]
        Blocked --> Result
    end

    Result --> Agent["AI Agent\nClaude / Kiro / Cline"]

    subgraph MULTI ["MULTI-STEP CAPABILITIES"]
        Workflow["Workflow engine\n{{ refs }} between steps"]
        Workflow --> ReExtract["Re-extract page\nafter each step"]
        ReExtract --> NewTools["Discover new tools\non new pages"]
        Crawl["Multi-page crawler\nBFS within origin"]
        Session["Session persistence\ncookies + localStorage"]
    end

    Agent --> Server
    Executor -.-> ReExtract
The key design choice is in ANALYZE: every parameter carries the CSS selector of
the element it fills. So when the agent later calls search(query="rust"), the
executor doesn't guess which box is the search box — it was told. That one decision
is the difference between a demo that works on Google's homepage and something that
holds up on a messy real page.
A few engineering decisions are what make this hold together, not just demo:
sleep. It walks open
Shadow DOM and same-origin iframes, so component-framework sites aren't invisible.mcp SDK, so the stdio /
SSE / streamable-HTTP handshakes are real — verified by connecting an actual MCP
client in the test suite, not by hand-rolling JSON-RPC.items (title / url / snippet),
so an agent gets data, not an innerText dump it has to re-parse.blocked, never as a hollow success.getAttribute, not properties like
form.method, so a field literally named method can't crash extraction — the
kind of bug that only shows up once you run against dozens of real sites.sequenceDiagram
participant Agent as AI Agent
participant Server as webmcp-gen
participant Site as Live Website
Agent->>Server: initialize
Server-->>Agent: capabilities (tools)
Agent->>Server: tools/list
Server-->>Agent: searchStories(query), navigate(page), ...
Agent->>Server: tools/call searchStories query="rust"
Server->>Site: fill #search-input with "rust"
Server->>Site: click submit button
Site-->>Server: results page loads
alt Success
Server-->>Agent: {success:true, items:[{title, url, snippet}...]}
else Bot wall detected
Server-->>Agent: {success:false, blocked:true, error:"..."}
end
Note over Agent,Site: Agent can chain: search -> open result -> act on detail page
pip install webmcp-gen
playwright install chromium

# No API key — heuristic analysis. Crude names, but it runs.
webmcp-gen https://en.wikipedia.org

# With an LLM — real names, real descriptions. This is the good one.
export LLM_API_KEY=gsk_...          # Groq has a free tier
webmcp-gen https://en.wikipedia.org --groq
Heuristic vs LLM on the same page is the clearest way to see why the LLM matters:
The heuristic sees a form and names it after its submit button. The LLM understands it's a Wikipedia search and says so. Run the comparison yourself across a handful of sites:
python -m webmcp_gen.compare --groq
LLM mode speaks any OpenAI-compatible API: Groq (LLM_API_KEY), OpenAI
(OPENAI_API_KEY), or a local model (--base-url http://localhost:11434/v1 for
Ollama, no key needed).
webmcp-gen runs as a real MCP server using the official SDK, so Claude Desktop, Kiro, Cline, etc. connect with no glue code:
{
  "mcpServers": {
    "hn": {
      "command": "webmcp-serve",
      "args": ["https://news.ycombinator.com", "--groq"]
    }
  }
}
The agent connects, calls tools/list, and gets clean WebMCP tool definitions. When
it calls one, webmcp-gen fills the form on the live site and hands back structured
results, not a wall of scraped text:
{
  "success": true,
  "blocked": false,
  "url": "https://hn.algolia.com/?q=rust",
  "items": [
    { "title": "Rust in the Linux kernel", "url": "https://...", "snippet": "..." },
    { "title": "Why Discord switched to Rust", "url": "https://...", "snippet": "..." }
  ]
}
stdio is the default; --sse and --transport streamable-http are there for
network clients.
Real tasks are chains: search, open a result, act on it. Each step needs the
previous step's output. Write that as a workflow and reference earlier results with
{{ }}:
{
  "url": "https://example.com",
  "variables": { "query": "rust" },
  "steps": [
    { "tool": "search",   "args": { "q": "{{ vars.query }}" },            "save_as": "search" },
    { "tool": "navigate", "args": { "page": "{{ steps.search.items.0.title }}" } }
  ]
}
webmcp-workflow flow.json --groq
Between steps the page is re-read, so a tool that only exists on the next page — the "reserve" button you only see after picking a hotel — becomes callable when you get there.
Two more capabilities worth knowing:
--crawl walks the
origin (bounded BFS), pulls tools from each page, and merges them.
webmcp-gen https://example.com --crawl --max-pages 5
0600.
webmcp-login https://github.com/login --session gh
webmcp-serve https://github.com --session gh
The benchmark ships in the box. It runs the full pipeline against real sites grouped by difficulty and reports per-tier rates, because "X% success" is meaningless without saying which sites.
webmcp-benchmark --suite full
Latest full run (heuristic mode, stealth on):
81% success across non-walled sites — and that figure includes successful live
runs against Google, Amazon, Bing, GitHub, GitLab, Wikipedia, and Startpage, not
just toy pages. Re-run it any time; the suite is webmcp_gen/suite.py and nothing is
hidden.
Driving a headless browser means some sites will try to stop you. Here's exactly where webmcp-gen stands, with no spin.
What it handles. Headless Chromium leaks tells — navigator.webdriver is
true, window.chrome is missing, the plugin list is empty, WebGL reports a
software renderer. webmcp-gen patches these by default (turn off with
--no-stealth). It's the well-understood, dependency-free subset of what
playwright-stealth does, with tests that probe the live signals to prove it — plus a
control test confirming the signals leak without it.
What it doesn't. Behavioral detection — request timing, TLS fingerprints, IP reputation, CAPTCHAs — needs residential proxies, TLS spoofing, and CAPTCHA-solving services. That's a paid, adversarial arms race, and webmcp-gen deliberately doesn't ship it.
What it does instead: tells you the truth. When a site blocks the action, the result is honest — it never pretends a CAPTCHA page was a successful search:
{ "success": false, "blocked": true,
  "error": "Blocked by anti-bot protection (redirected to '418.html')." }
An agent can act on that. A fake success: true with garbage results is far worse
than a clear "I was blocked." If you need a guarded site: try --session (a lot of
"blocks" are really "you're not logged in"), --headful, or a friendlier endpoint.
The gap it fills: high-level tools, generated automatically, from sites that never opted in.
Everything the CLI does is importable:
from webmcp_gen import extract_page, analyze_with_llm, WebExecutor

extraction = await extract_page("https://news.ycombinator.com")
analysis   = await analyze_with_llm(extraction, model="llama-3.3-70b-versatile",
                                    base_url="https://api.groq.com/openai/v1")

async with WebExecutor("https://news.ycombinator.com",
                       tools=analysis["tools"], extraction=extraction) as ex:
    result = await ex.call("searchStories", {"query": "rust"})
    print(result.to_dict())
CLIs: webmcp-gen (generate), webmcp-serve (MCP server), webmcp-workflow
(chains), webmcp-login (sessions), webmcp-benchmark (reliability),
webmcp-compare (heuristic vs LLM).
playwright install chromiumLLM_API_KEY, free tier), OpenAI (OPENAI_API_KEY), or local
Ollama (--base-url, no key)pip install -e ".[dev]"
playwright install chromium
pytest # unit tests are fast; -k Live hits the network
MIT
Turn any website into an MCP server. Auto-generates WebMCP tools from live pages - no site cooperation needed.
टूल
अभी टूल सूची नहीं है। रिमोट सर्वर को पहले हेल्थ चेक के बाद सूची मिलती है।
FAQ
इस पेज पर Cursor, Claude Desktop, Claude Code या VS Code के लिए stdio कॉन्फ़िग कॉपी करें। यह पब्लिशर का इंस्टॉल इस्तेमाल करता है, PlugMCP प्रॉक्सी नहीं।
इस रिकॉर्ड में कोई ज़रूरी एनवायरनमेंट वेरिएबल दर्ज नहीं है।
Webmcp Gen stdio पर लोकल चलता है।
पिछली जाँच 2026-10-27 को हुई। Turn any website into an MCP server. Auto-generates WebMCP tools from live pages - no site cooperation needed.
