HKEx Filing Scraper
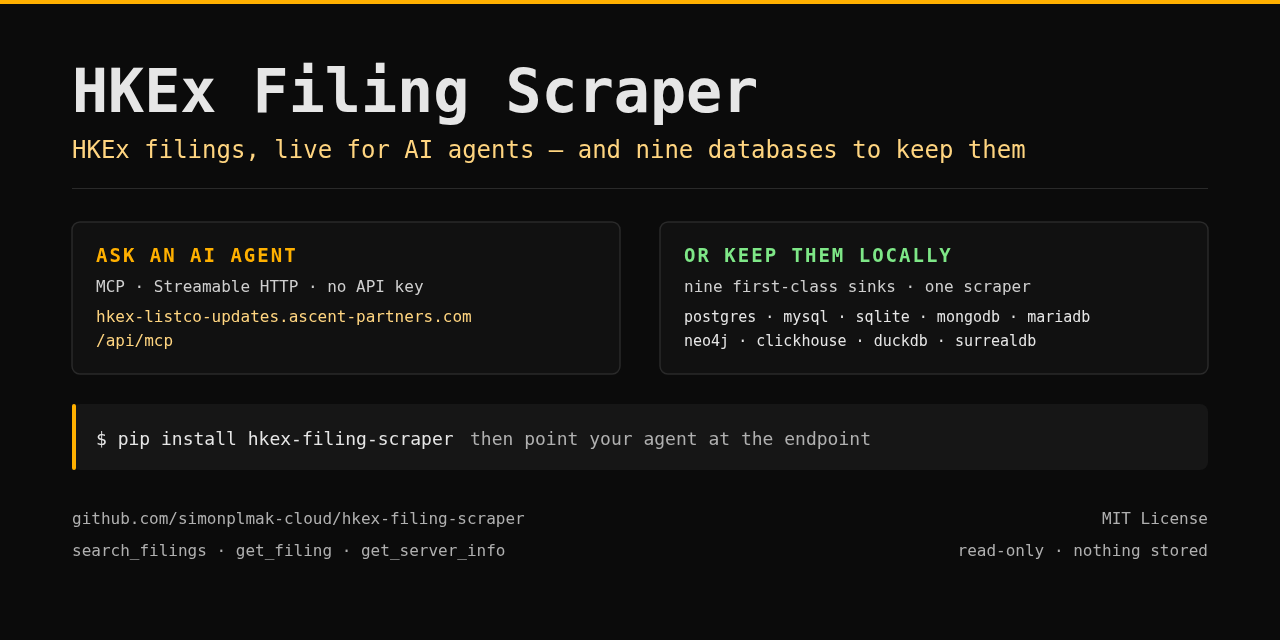
An open-source scraper for 25+ years of HKEx regulatory filings — into any of nine databases, with full-text extraction, graph linking, and a read-only MCP server for AI agents.
에이전트 강화
게시자의 자체 URL입니다. PlugMCP 엔드포인트가 아닙니다.
Host a copy with our keys and logs.
https://hkex-listco-updates.ascent-partners.com/api/mcp위의 Claude 버튼을 누르면 이름과 URL이 채워진 상태로 Claude가 열립니다. 확인은 Claude에서 직접 해야 합니다.
claude mcp add --transport http simonmak-ascent-hkex-filing-scraper https://hkex-listco-updates.ascent-partners.com/api/mcpRun in a terminal.
{ "mcpServers": { "simonmak-ascent-hkex-filing-scraper": { "command": "npx", "args": [ "-y", "mcp-remote", "https://hkex-listco-updates.ascent-partners.com/api/mcp" ] } }}claude_desktop_config.json
원격 URL인가요, 내 컴퓨터에서 실행하는 명령인가요? 두 설치 방식의 차이
PlugMCP에서 실행
A new server you create. It is not this listing's official endpoint. Use the publisher install when you want their URL and their credentials.
실행게시자 제공
An open-source scraper for 25+ years of HKEx regulatory filings — into any of nine databases, with full-text extraction, graph linking, and a read-only MCP server for AI agents.
HKEx regulatory filings scraper — 25+ years of filings into nine databases, with full-text extraction, graph linking, and a hosted MCP server for AI agents
The US has EDGAR full-text search. Japan has EDINET. Hong Kong has a search form that returns one page at a time. There is no bulk, machine-readable, full-text corpus of HKEx filings. This builds one.
An open-source Python tool that scrapes 25+ years of Hong Kong Stock Exchange (HKEx) regulatory filings and ingests them into any combination of nine databases — with full-text and table extraction, chunk-level coverage, optional graph linking, and a read-only MCP server so AI agents can query the corpus or the live site.
It speaks the undocumented HKEx JSON API directly, which is faster and more resilient than driving a browser.
Databases — nine first-class destinations, in documented popularity order (see the support matrix):
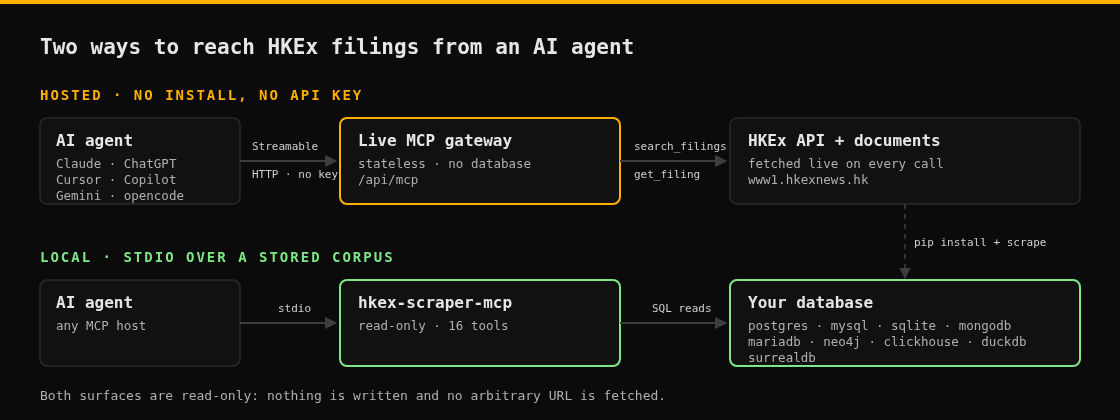
AI clients — any MCP-capable agent; ready-made configuration for Claude, ChatGPT, Cursor, VS Code/Copilot, Gemini CLI, opencode, Manus, and Perplexity.
Available on — PyPI · Glama · MCP Registry · hosted gateway.
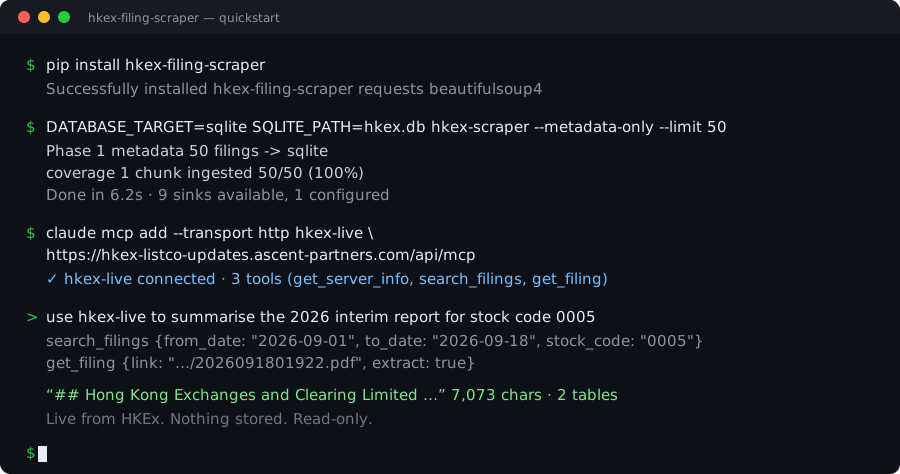
POST, Streamable HTTP, no API key:
https://hkex-listco-updates.ascent-partners.com/api/mcp
Four read-only tools: get_server_info, search_filings (a window of at most 31 days, with
optional stock-code, title, document-type, category, and stock-name filters),
list_filing_facets (browse what a window contains), and get_filing (downloads one
document and extracts its text and tables).
Point a client at it — for example opencode:
{
  "$schema": "https://opencode.ai/config.json",
  "mcp": {
    "hkex-live": {
      "type": "remote",
      "url": "https://hkex-listco-updates.ascent-partners.com/api/mcp"
    }
  }
}
Then ask:
Use hkex-live to list the filings published between 2026-09-01 and 2026-09-18,
then summarise the interim report.
Ready-made configuration for Claude, ChatGPT, Cursor, VS Code/Copilot, Gemini CLI, opencode,
Manus, and Perplexity is in AI agent support — and for a stored corpus,
the stdio MCP server exposes a wider tool catalog and is published on
Glama. The gateway is listed
in the official MCP Registry as
com.ascent-partners/hkex-filings.
Featured on Glama — the read-only stdio MCP server is also published on Glama, where Glama scans the built server and scores tool-definition quality (currently 4.7/5).
Fastest path: no install — use the hosted gateway at
https://hkex-listco-updates.ascent-partners.com/api/mcp (Streamable HTTP), or install and run
locally:
pip install hkex-filing-scraper        # core; SQLite needs no server
pip install "hkex-filing-scraper[all]" # Excel + dotenv + every driver + the MCP server
cp .env.example .env                   # then set DATABASE_TARGET (below)
hkex-scraper --metadata-only --limit 100
Optional extras: excel, postgres, mysql, duckdb, mongodb, clickhouse, neo4j,
mcp, pdf, all, dev.
DATABASE_TARGET is an ordered, comma-separated list of sink ids; the order decides which
sink serves reads. To start with no server:
DATABASE_TARGET=sqlite
SQLITE_PATH=hkex.db
hkex-scraper runs the full pipeline (metadata + documents + graph); hkex-scraper --full-history covers everything since April 1999. The schema is created automatically.
Full install options and per-sink settings are in Getting started.
Every sink is a first-class destination; rows are in documented popularity order. The full matrix — licenses, capability differences, per-engine notes — is in Database sinks.
¹ Source-available, not OSI-approved — labeled exceptions per ADR 0003.
Valid sink ids, in documented order: postgres, mysql, sqlite, mongodb, mariadb, neo4j, clickhouse, duckdb, surrealdb. Set one variable and the same run feeds every sink:
# Order sets read precedence.
DATABASE_TARGET=postgres,sqlite
POSTGRES_DSN=postgresql://user:password@localhost:5432/hkex
SQLITE_PATH=hkex.db
Four ways to get HKEx filings, and what each one costs you.
If you need licensed, redistributable, SLA-backed data, buy the feed. If you need a complete local corpus for research, compliance, or RAG, this replaces the pipeline you would otherwise write yourself.
flowchart LR
    A[HKEx JSON API] --> B[Phase 1: metadata]
    B --> C[Canonical record]
    C --> D{DATABASE_TARGET}
    D --> E[(PostgreSQL)]
    D --> F[(MySQL / MariaDB)]
    D --> G[(SQLite)]
    D --> H[(MongoDB)]
    D --> I[(Neo4j)]
    D --> J[(ClickHouse)]
    D --> K[(DuckDB)]
    D --> L[(SurrealDB)]
    B --> M[Graph linking]
    M --> D
    B --> N[Phase 2: download and extract]
    N --> C
filingId.has_filing and references_filing edges when
COMPANY_TABLE is set.Deeper detail: Architecture · ADR 0002.
sequenceDiagram
    autonumber
    participant C as hkex-scraper
    participant J as HKEx site (JSF)
    participant A as HKEx JSON servlet
    C->>J: GET /search/titlesearch.xhtml
    J-->>C: HTML + javax.faces.ViewState
    C->>J: POST form (from/to dates + ViewState)
    C->>A: GET /search/titleSearchServlet.do (rowRange paging)
    A-->>C: JSON page of filings
    Note over C: generate_monthly_chunks() splits ranges > 1 month
    C->>C: dedupe on 16-char MD5 filingId
erDiagram
    COMPANY ||--o{ EXCHANGE_FILING : has_filing
    EXCHANGE_FILING ||--o{ DOCUMENT : has_document
    EXCHANGE_FILING ||--o{ EXCHANGE_FILING : references_filing
    EXCHANGE_FILING ||--o{ SCRAPE_COVERAGE : chunk_of
    EXCHANGE_FILING {
        string filingId "16-char MD5"
        string stockCode
        string title
        datetime dateTime
    }
    DOCUMENT {
        text documentText
        array documentTables
    }
    SCRAPE_COVERAGE {
        int apiCount
        int ingestedCount
        int uniqueCount
        string runId
    }
exchange_filing and scrape_coverage are SCHEMAFULL; has_filing /
references_filing are the graph edges written by graph.py.
flowchart LR
    CANON["canonical record<br/>per filing / document / coverage / edge"] --> DISPATCH["dispatch to every configured sink"]
    DISPATCH --> S1["sink A"]
    DISPATCH --> S2["sink B"]
    DISPATCH --> SN["sink N"]
    S1 -.->|error| LOG["logged + counted<br/>never blocks the others"]
    READ["reads: pending filings · tickers · titles · coverage"] --> FIRST["first configured sink<br/>whose capabilities include reads"]
    DISPATCH --> EXIT["sink_exit_code()<br/>non-zero if any sink failed"]
--coverage-report / --parity-report / --verify.requests + beautifulsoup4; drivers and document
extraction are extras with graceful fallbacks.examples/)pip install -e ".[dev,all]"
ruff check # lint (py310, line-length 100)
ruff format --check # formatting
pytest # unit tests (no DB or network required)
Tests are pure unit tests; SQLite and DuckDB contract tests run in-process, and integration tests that need a server are skipped unless that sink is configured. See Testing.
CI and deployment run through the APG workbench pipeline.
The deploy smoke check probes the public hostname through the balancer, not a local port.
See CONTRIBUTING.md; report security issues per SECURITY.md. Ideas and questions are welcome in Discussions.
Built by Ascent Partners.
If this saves you time, a ⭐ on GitHub helps others find it.
Up-to-date HKEx Filing Scraper documentation is indexed on Context7, so coding agents can pull it into context on demand. With the Context7 MCP server or ctx7 CLI installed, name the library in your prompt:
use library /simonmak-ascent/hkex-filing-scraper for API and docs
MIT — see LICENSE. That covers this project's code only; optional dependencies
carry their own licenses, notably the pdf extra (PyMuPDF / pymupdf4llm), which is
AGPL-3.0 and deliberately excluded from .[all]. See
docs/legal.md.
Data & Terms of Use: this is a research tool for the undocumented HKEx JSON API, and it is not affiliated with or endorsed by HKEx. Commercial redistribution of HKEx data may require a licensed HKEx feed; see docs/legal.md.
HKEx regulatory filings scraper — 25+ years of filings into nine databases, with full-text extraction, graph linking, and a hosted MCP server for AI agents
{ "mcpServers": { "simonmak-ascent-hkex-filing-scraper": { "url": "https://hkex-listco-updates.ascent-partners.com/api/mcp", "headers": {} } }}도구
아직 도구 목록이 없습니다. 원격 서버는 첫 상태 확인 후에 도구 목록이 생깁니다.
FAQ
이 페이지에서 Cursor, Claude Desktop, Claude Code 또는 VS Code용 http 설정을 복사합니다. PlugMCP 프록시가 아니라 게시자의 설치 방식을 사용합니다.
이 레코드에는 필수 환경 변수가 등록되어 있지 않습니다.
Hkex Filing Scraper에는 HTTP로 연결합니다.
마지막 확인: 2026-10-28. HKEx regulatory filings scraper — 25+ years of filings into nine databases, with full-text extraction, graph linking, and a hosted MCP server for AI agents