Power your agent
การติดตั้งจากผู้เผยแพร่ ไม่ใช่เอนด์พอยต์ของ PlugMCP
URL แบบรีโมตหรือคำสั่งบนเครื่องของคุณ? การติดตั้งสองแบบต่างกันอย่างไร
รันบน PlugMCP
A new server you create. It is not this listing's official endpoint. Use the publisher install when you want their URL and their credentials.
เปิด⭐ If you find this project useful, please star the repo! It helps others discover the tool and motivates continued development.
Transform compressed data dumps into browsable HTML archives with flexible deployment options. Redd-Archiver supports offline browsing via sorted index pages, full-text search with Docker deployment, or fully dynamic serving straight from PostgreSQL. Archives stay current with monthly incremental updates from Arctic Shift dumps. Features mobile-first design, multi-platform support, operator-selectable themes, and PostgreSQL full-text indexing.
Supported Platforms:
Tracked content: 2.38B+ posts across 68,883 communities (full Reddit dataset plus monthly Arctic Shift dumps via incremental updates; Voat/Ruqqus complete archives)
Version 1.1 “Living Archive” adds three serving modes, monthly incremental updates, 11 theme palettes, community metadata/wiki enrichment, and a major performance pass on top of 1.0's multi-platform archiving, REST API, and MCP server. See CHANGELOG.md.
One archive, three ways to serve it — the database is the canonical store, switch modes anytime:
# Static: export once, host anywhere
reddarc.py /data --subreddit privacy ... --output /var/www/html/

# Hybrid (current default): static pages + search server
docker compose up -d

# Dynamic: no export step, Flask renders pages from PostgreSQL
reddarc.py --import-only /data --subreddit privacy ...
REDDARCHIVER_SERVE_MODE=dynamic python search_server.py
Apply monthly Arctic Shift dumps to an existing archive — only tracked subreddits are imported, re-runs are skipped by checksum, and scores refresh without altering preserved content:
# One month
reddarc.py --update RS_2026-01.zst --comments-file RC_2026-01.zst

# Or point at a downloaded monthly torrent (comments/ + submissions/ layout
# is auto-discovered) and apply every unprocessed month in order:
reddarc.py --update-all /data/monthly/reddit/
reddarc.py --update-status   # audit what has been applied
Archive internet history before it disappears - Deploy in 2 minutes, no domain required.
Try the live demo: Browse Example Archive →
→ QUICKSTART.md - Step-by-step deployment:
Why now? Communities get banned, platforms shut down, discussions vanish. Start preserving today.
→ First time here? QUICKSTART.md - Deploy in 2-15 minutes
→ Quick answers? FAQ - Common questions answered in 30 seconds
→ Need help? Troubleshooting - Fix common issues
→ Using the API? API Reference - 30+ REST endpoints
→ How it works? Architecture - Technical deep-dive
→ Deployment guides:
→ Operations:
→ Advanced:
Archive content from multiple link aggregator platforms in a single unified archive:
29 MCP tools auto-generated from OpenAPI for AI assistants:
{
  "mcpServers": {
    "reddarchiver": {
      "command": "uv",
      "args": ["--directory", "/path/to/mcp_server", "run", "python", "server.py"],
      "env": { "REDDARCHIVER_API_URL": "http://localhost:5000" }
    }
  }
}
See MCP Server Documentation for complete setup guide.
--theme / REDDARCHIVER_THEME, plus --accent-color and --custom-css; CSS-only dark/light mode follows system preference with a manual toggle--precompress + gzip_static for high-traffic static serving
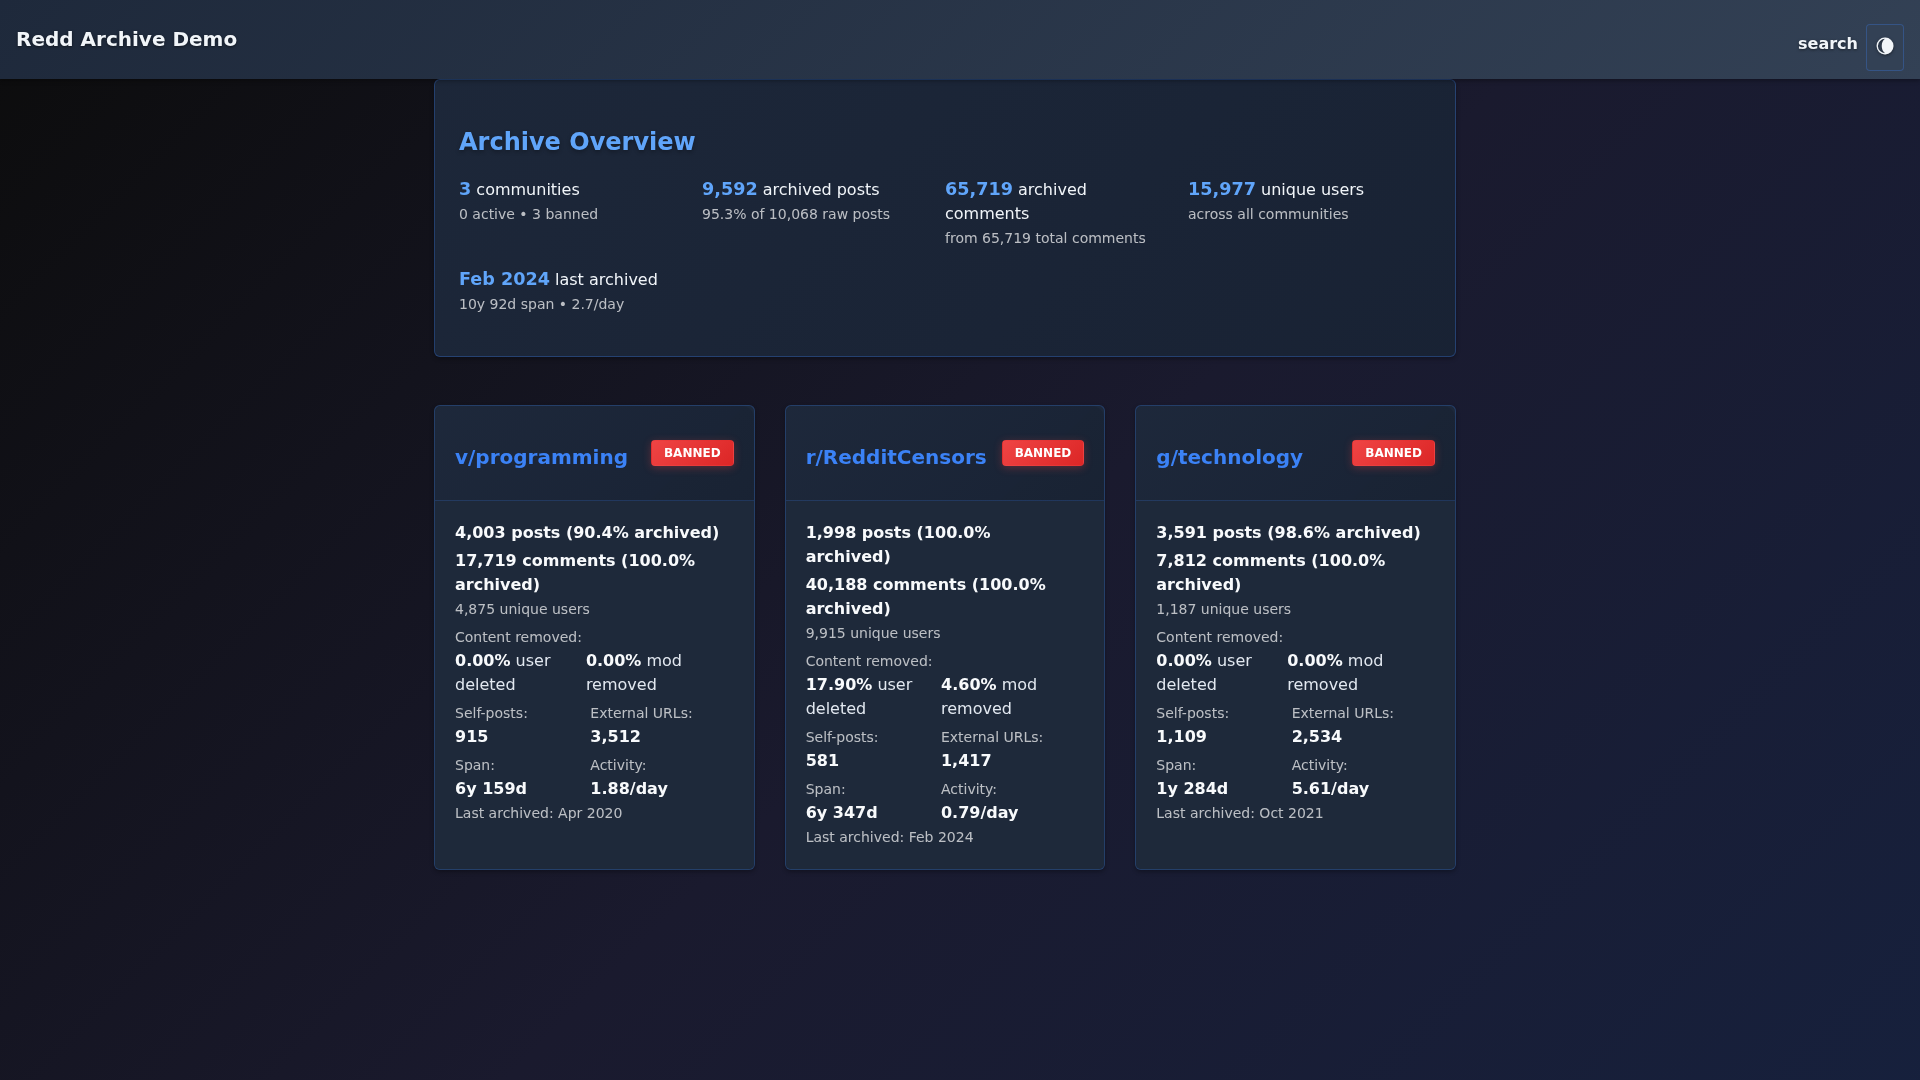
Main landing page showing archive overview with statistics for 9,592 posts across Reddit, Voat, and Ruqqus. Features customizable branding (site name, project URL), responsive cards, activity metrics, and content statistics. (Works offline)
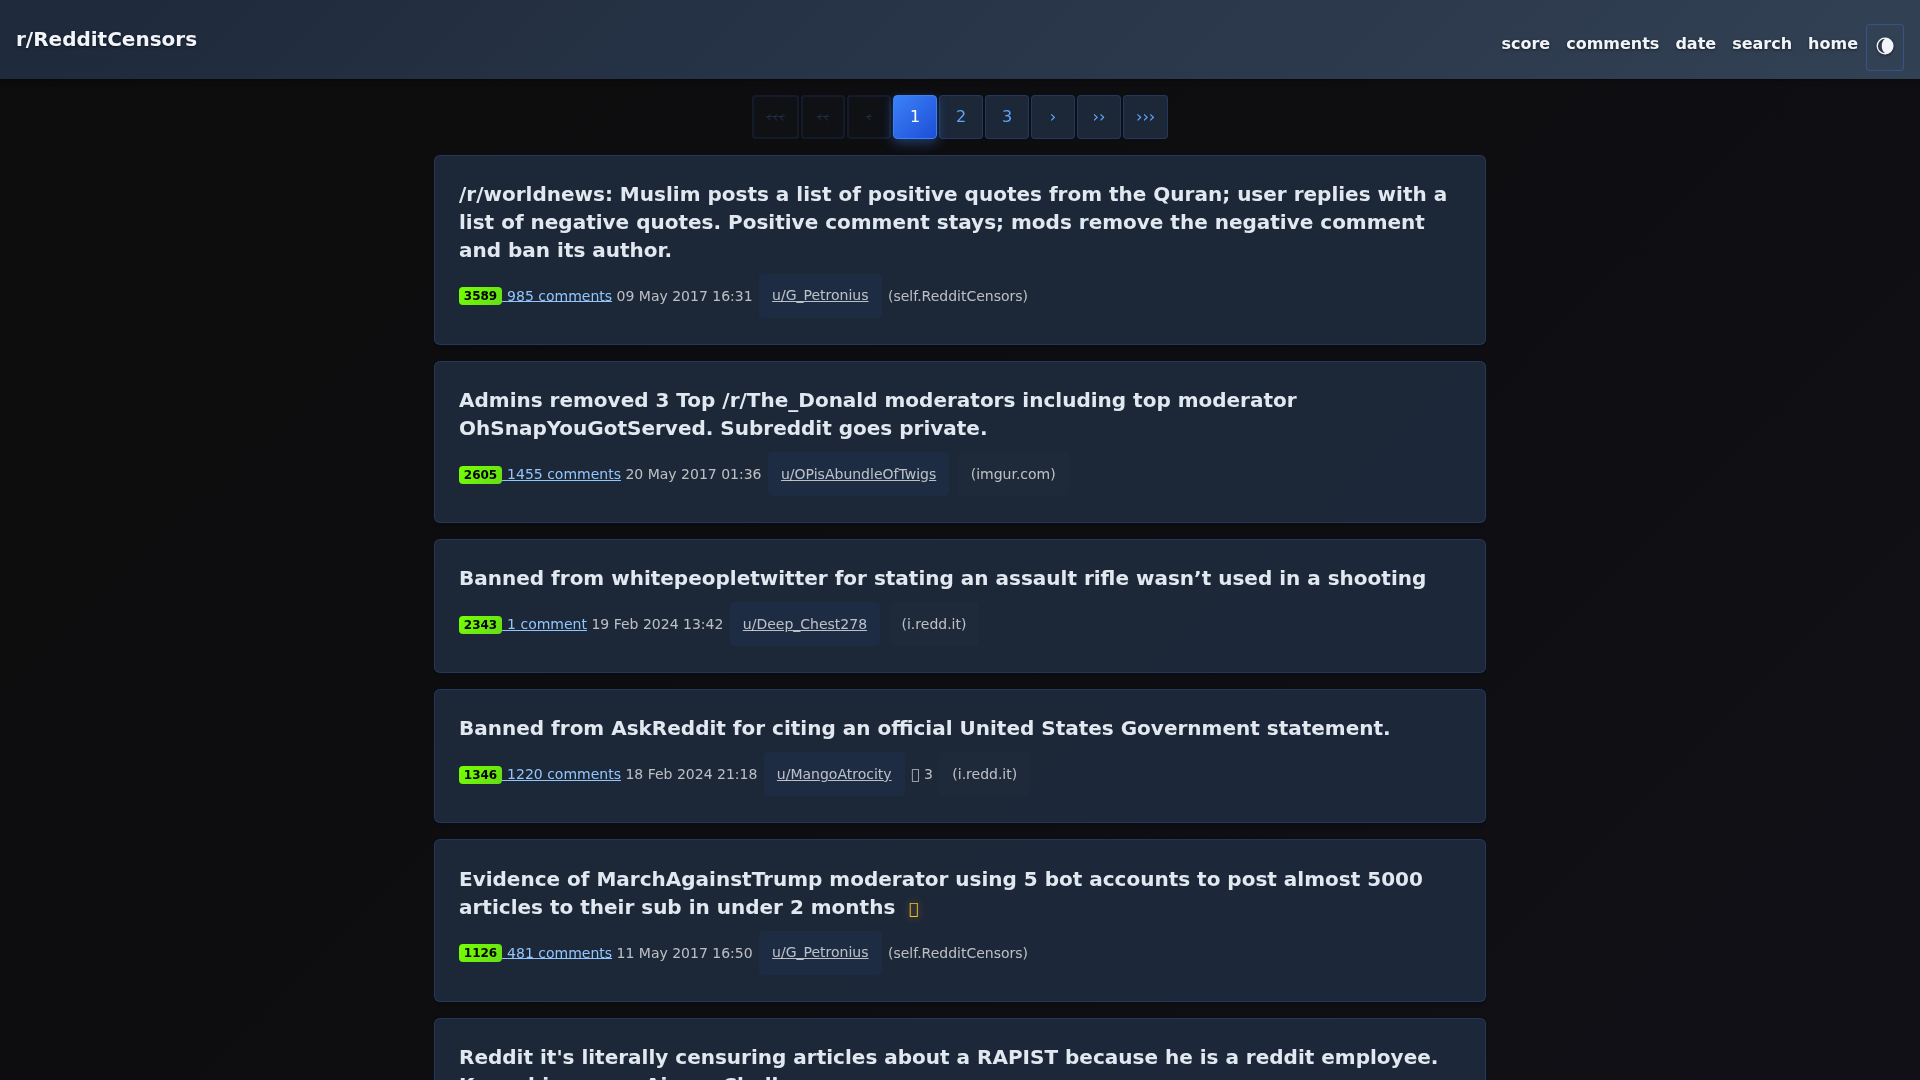
Post listing with sorting options (score, comments, date), pagination, and badge coloring. Includes navigation and theme toggle. (Works offline - sorted by score/comments/date)
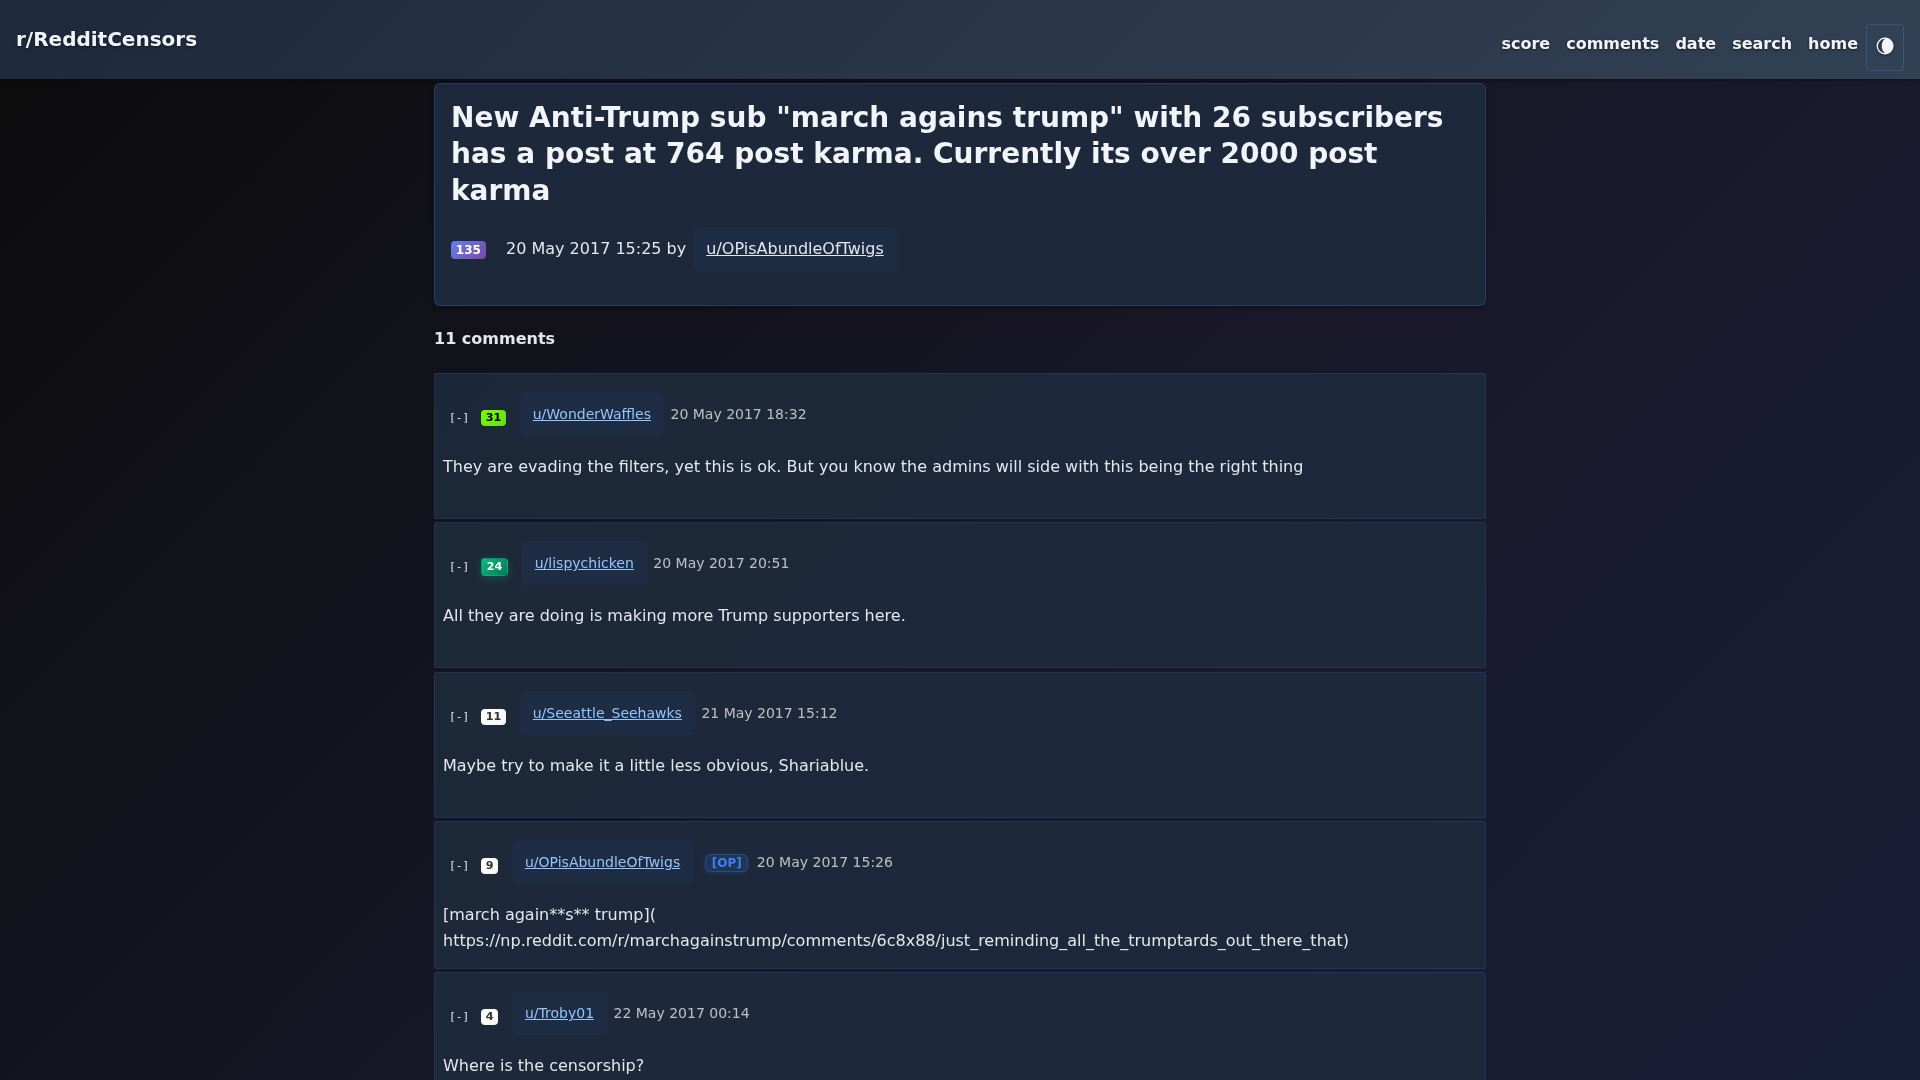
Individual post displaying nested comment threads with collapsible UI, user flair, and timestamps. Comments include anchor links for direct navigation from user pages. (Works offline)
Fully optimized for mobile devices with touch-friendly navigation and responsive layout.
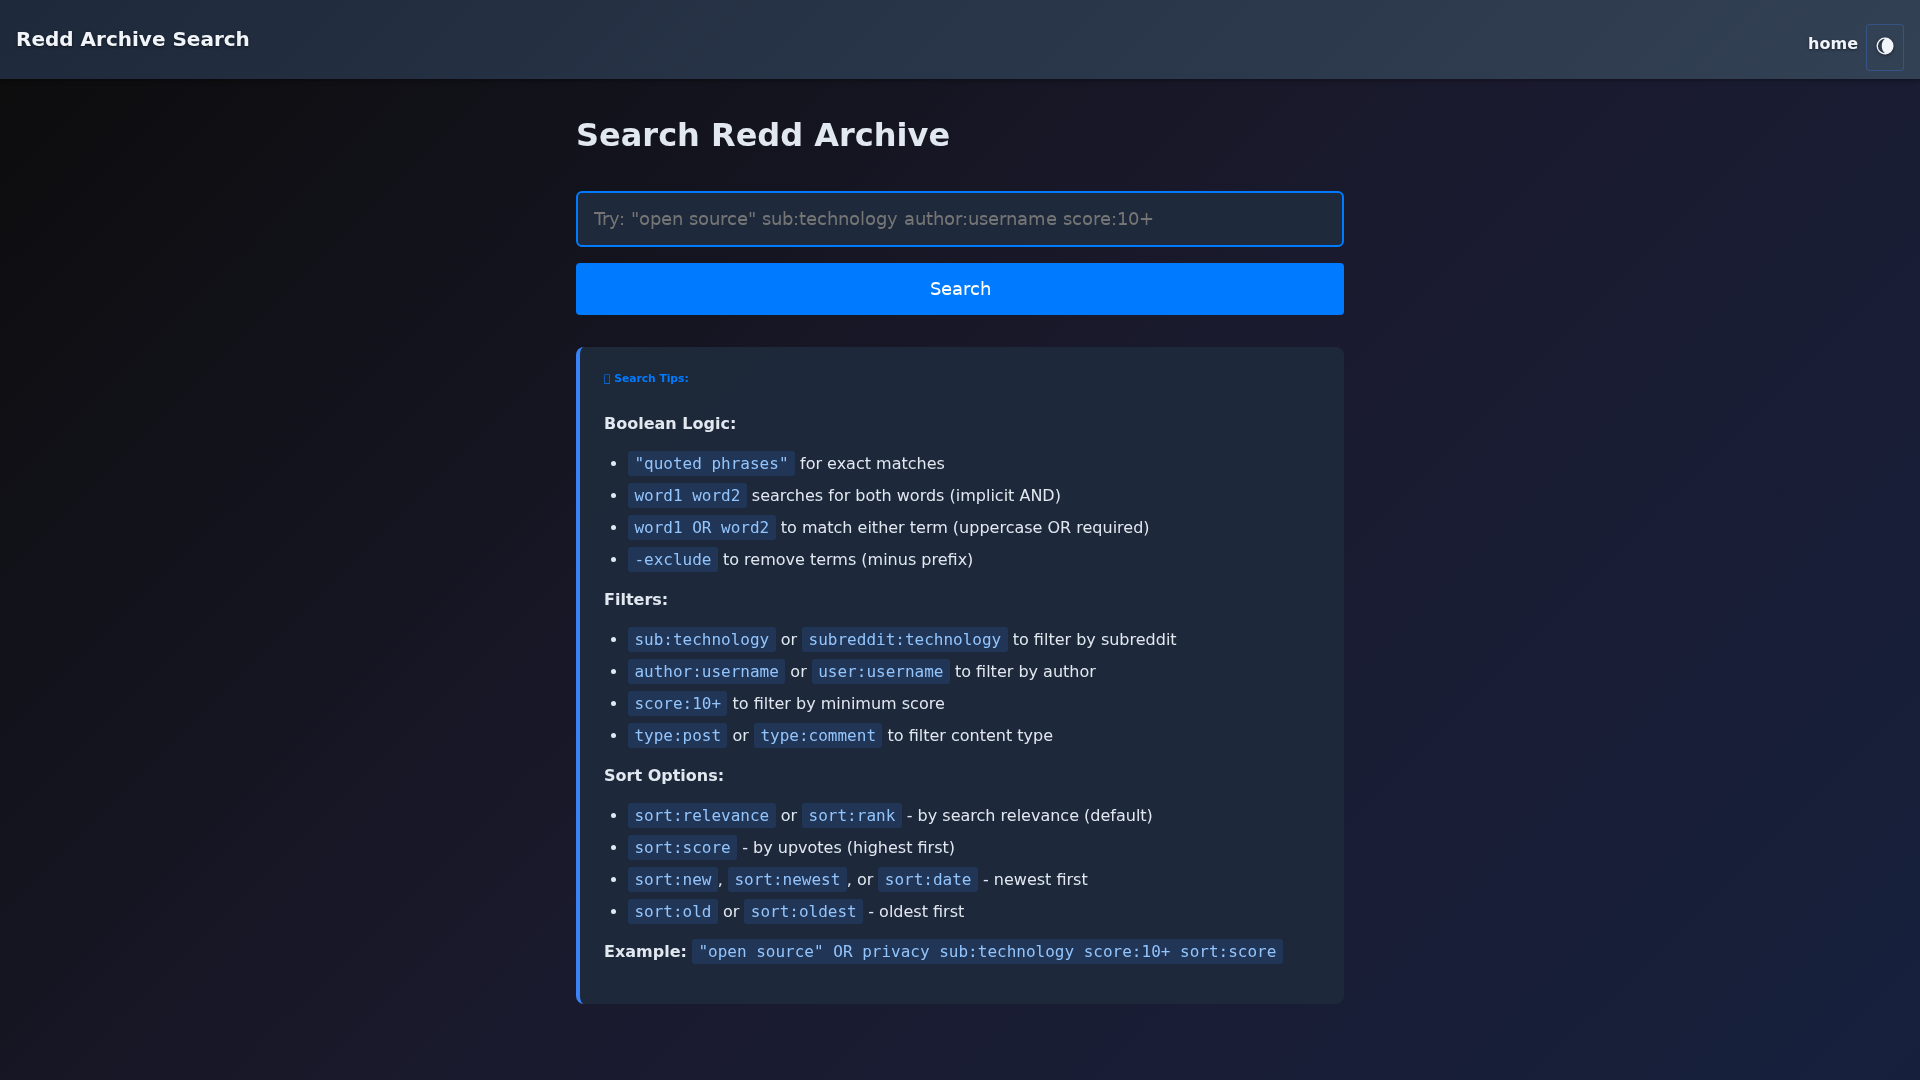
PostgreSQL full-text search with Google-style operators. Supports filtering by subreddit, author, date range, and score. (Requires Docker deployment)
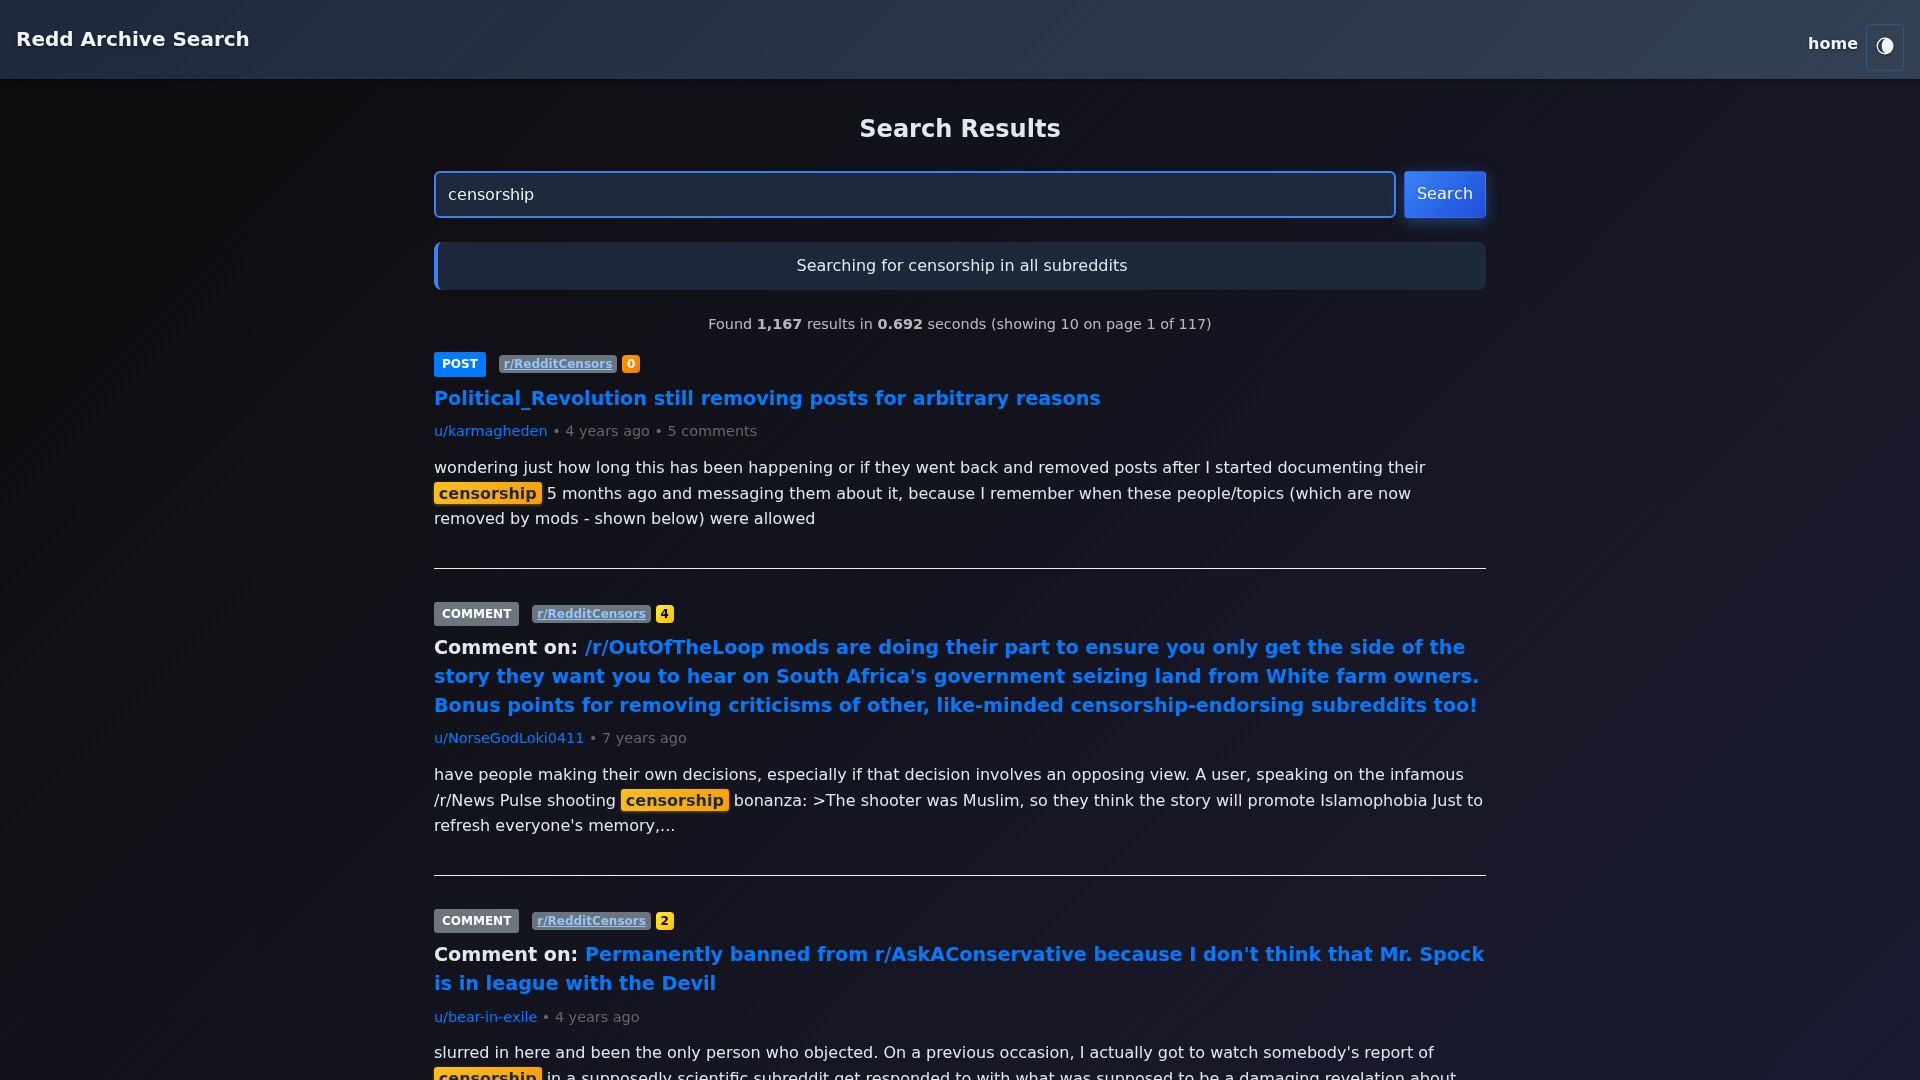
Search results with highlighted excerpts using PostgreSQL ts_headline(). Sub-second response times with GIN indexing. (Server-based, Tor-compatible)
All 11 palettes on the same post page (each ships dark and light variants; --accent-color re-tints any of them):
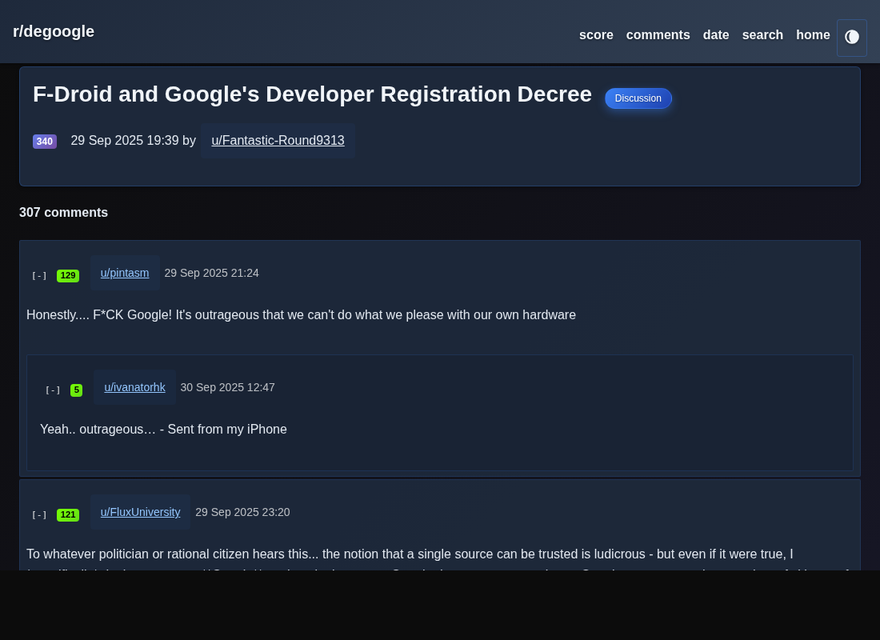 default | 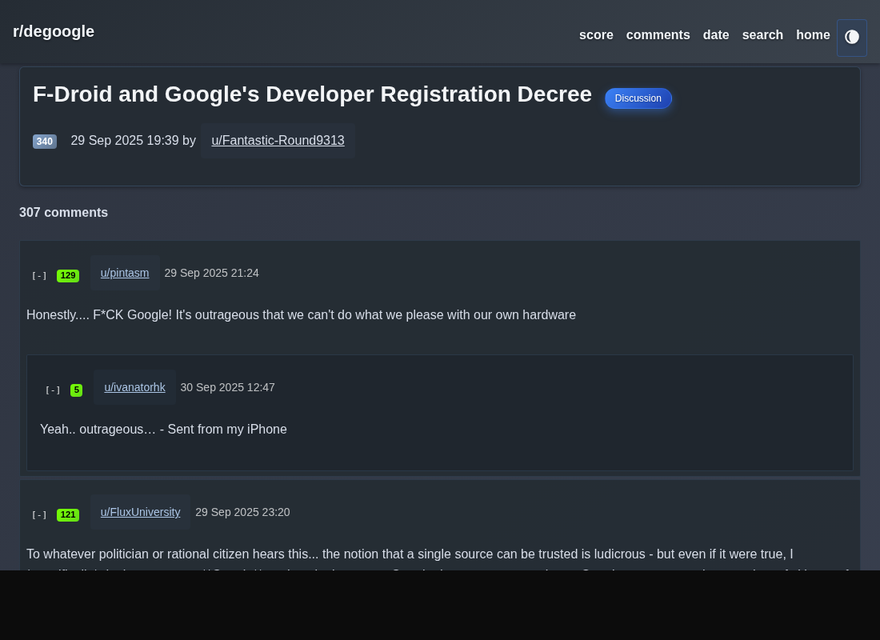 nord |
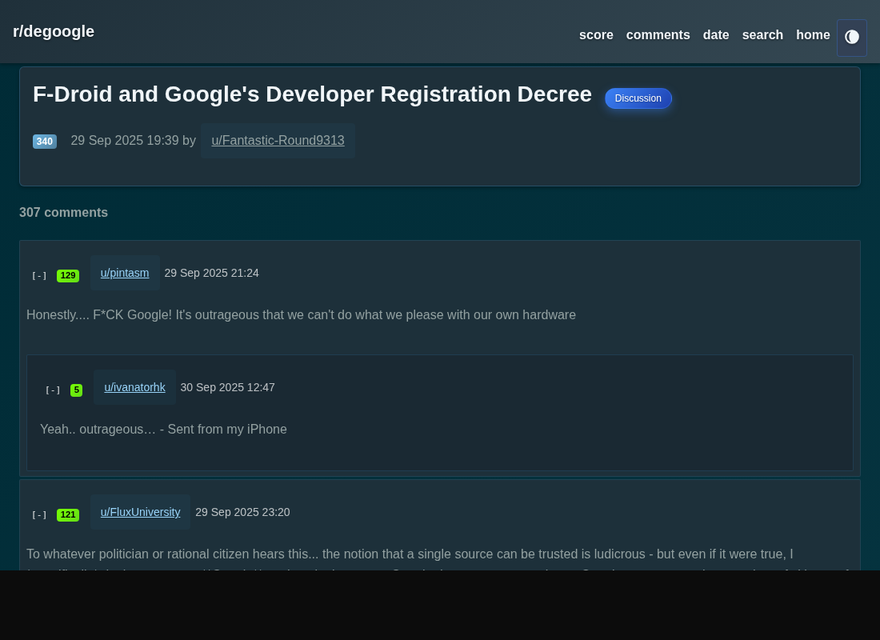 solarized | 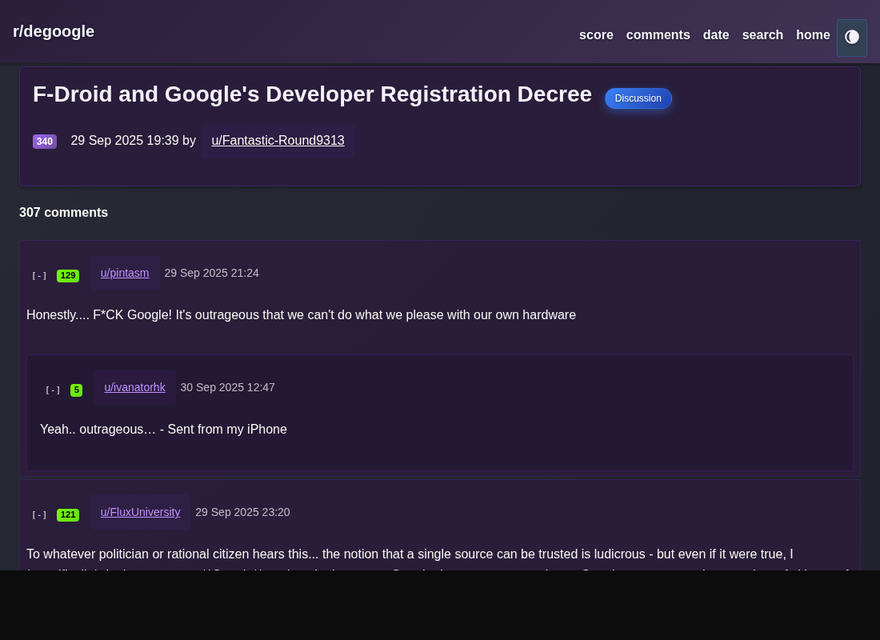 dracula |
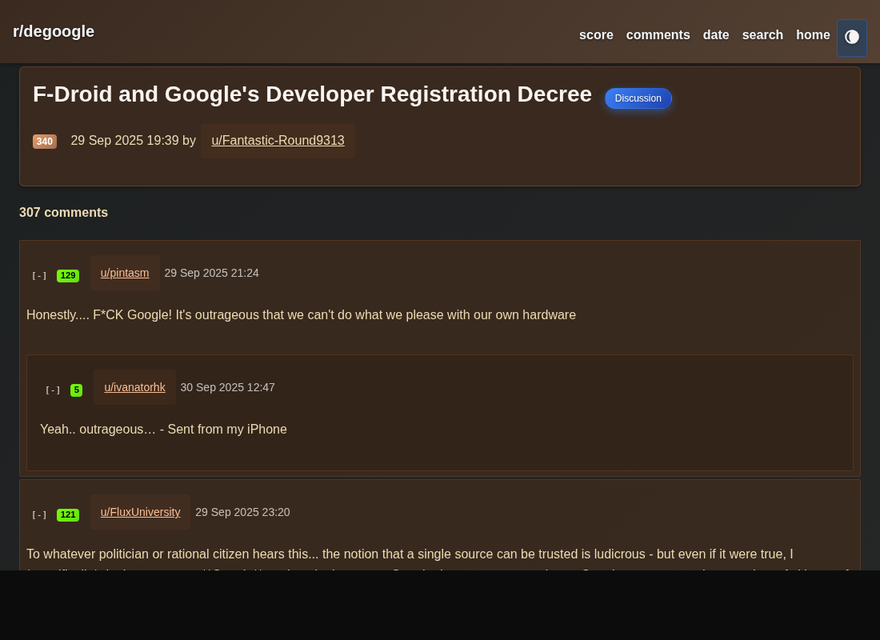 gruvbox | 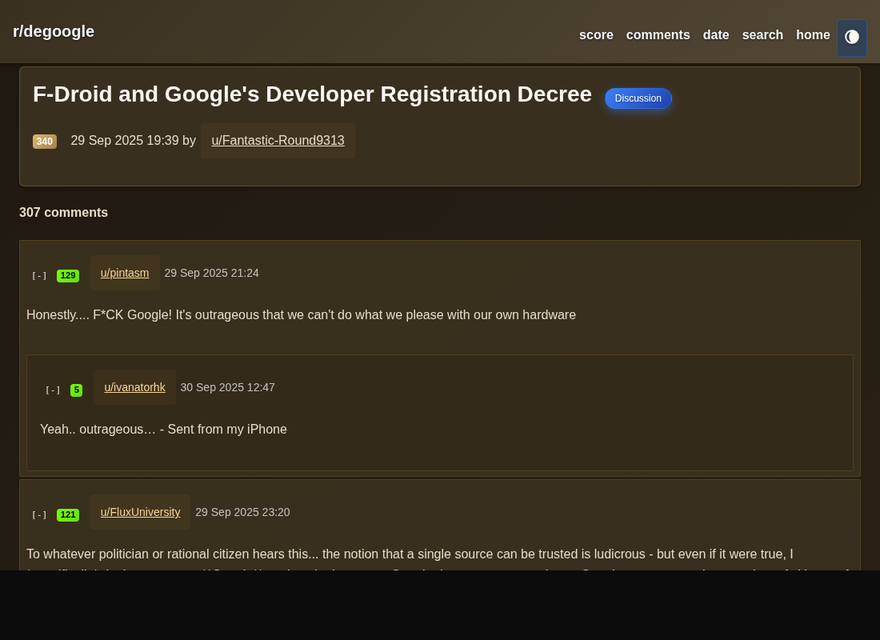 sepia |
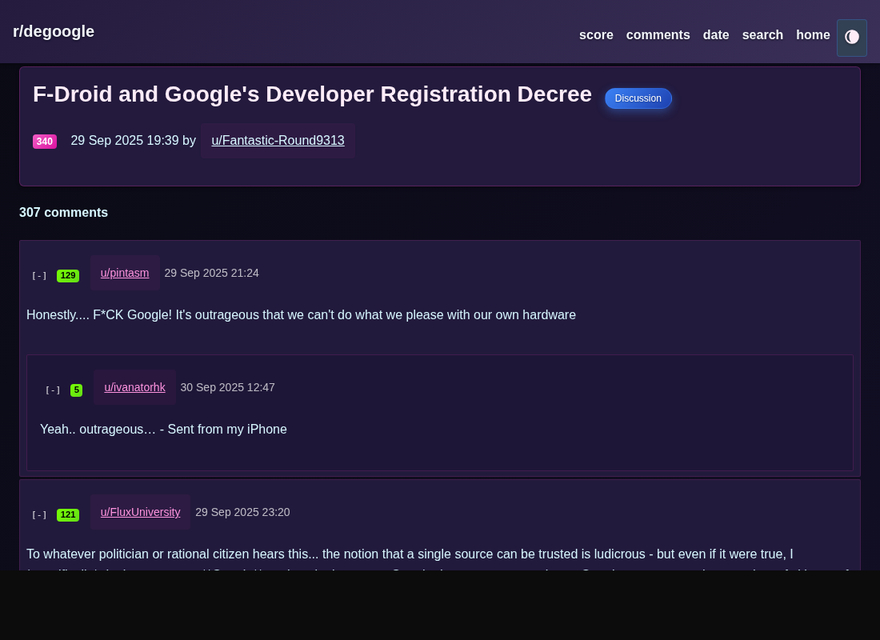 cyberpunk | 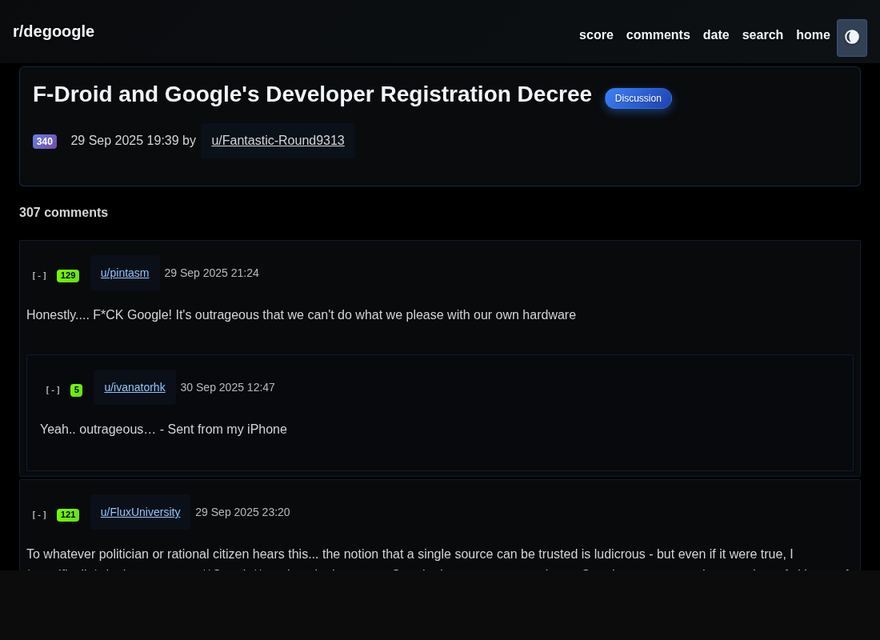 midnight (OLED) |
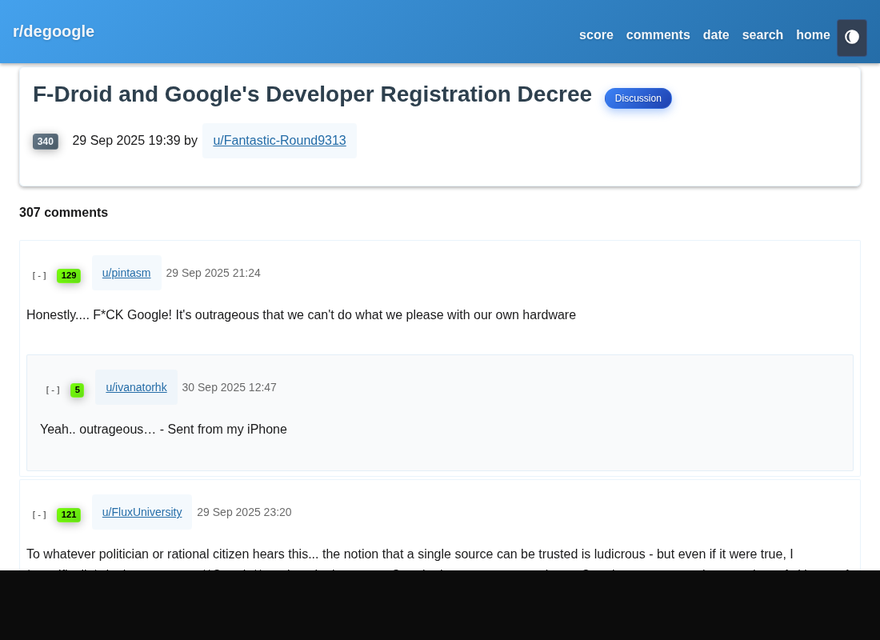 old-reddit | 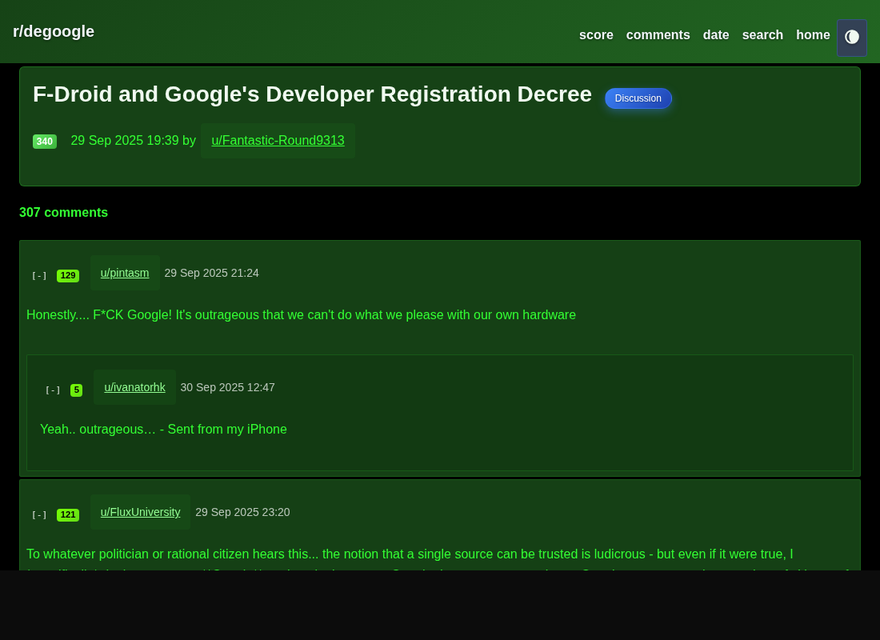 phosphor |
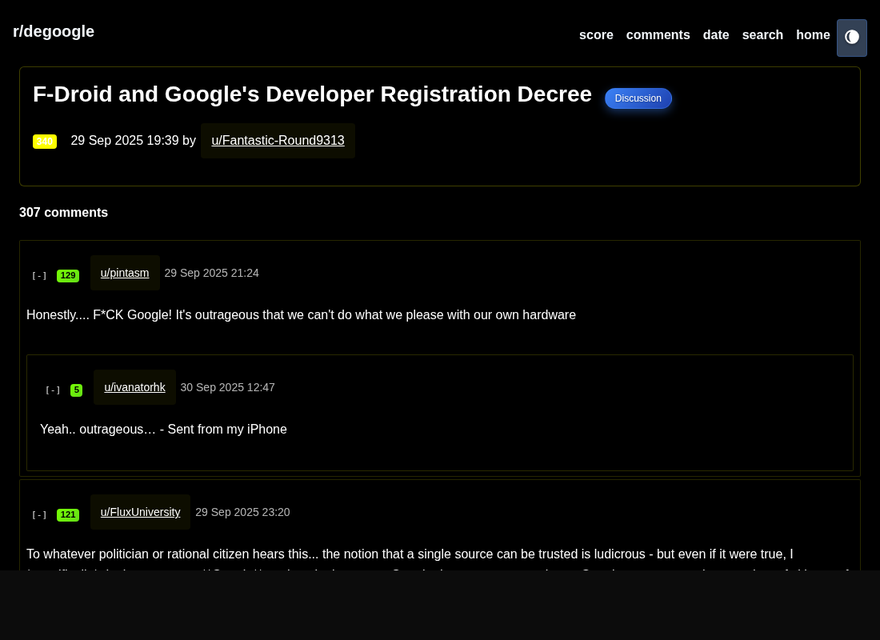 high-contrast |
reddarc.py ... --theme nord                    # static export
REDDARCHIVER_THEME=nord search_server.py       # dynamic mode
Sample Archive: Multi-platform archive featuring programming and technology communities from Reddit, Voat, and Ruqqus · See all screenshots →
Prerequisites: Python 3.10+, PostgreSQL 14+, 4GB+ RAM
Quick Install (Docker):
git clone https://github.com/19-84/redd-archiver.git
cd redd-archiver

# Create required directories
mkdir -p data output/.postgres-data logs tor-public

# Configure environment (IMPORTANT: change passwords!)
cp .env.example .env
nano .env  # Edit POSTGRES_PASSWORD and DATABASE_URL

# Start services
docker compose up -d

# Generate archive (after downloading .zst files to data/)
docker compose exec reddarchiver-builder python reddarc.py /data \
  --subreddit privacy \
  --comments-file /data/privacy_comments.zst \
  --submissions-file /data/privacy_submissions.zst \
  --output /output/
Detailed installation procedures (Docker, Ubuntu/Debian, macOS, Windows WSL2):
Quick workflow: Download data → Run archive generator → Deploy
# Docker (canonical): generate archive inside the builder container
docker compose up -d
docker compose exec reddarchiver-builder python reddarc.py /data \
  --subreddit privacy \
  --comments-file /data/privacy_comments.zst \
  --submissions-file /data/privacy_submissions.zst \
  --output /output/
# Access at http://localhost

# Local development (uv): same flags, host paths
export DATABASE_URL="postgresql://user:pass@localhost:5432/reddarchiver"
uv run python reddarc.py data/ --subreddit privacy \
  --comments-file data/privacy_comments.zst \
  --submissions-file data/privacy_submissions.zst --output output/
.zst files from Pushshift (3.28TB, 2.38B posts).7z files from Archive.org (752MB, 500K posts)CLI options and advanced workflows: See QUICKSTART.md for complete reference.
Environment Variables:
# Required
DATABASE_URL=postgresql://user:pass@host:5432/reddarchiver

# Serving (search server)
REDDARCHIVER_SERVE_MODE=dynamic         # hybrid (default) | dynamic
REDDARCHIVER_THEME=nord                 # 11 palettes: default|sepia|high-contrast|nord|solarized|dracula|gruvbox|cyberpunk|midnight|old-reddit|phosphor
REDDARCHIVER_ACCENT_COLOR="#8b6914"     # Accent override (hex), both modes
REDDARCHIVER_HTTP_CACHE_MAX_AGE=300     # Cache-Control/ETag for GET responses (0 disables)
REDDARCHIVER_LISTING_CACHE_TTL=300      # Listing count/stats cache (dynamic mode)
GUNICORN_WORKERS=8                      # Override CPU-scaled worker count (Docker)

# Optional Performance Tuning (auto-detected if not set)
REDDARCHIVER_MAX_DB_CONNECTIONS=8       # Connection pool size
REDDARCHIVER_MAX_PARALLEL_WORKERS=4     # Parallel processing workers
REDDARCHIVER_USER_BATCH_SIZE=2000       # User page batch size
REDDARCHIVER_QUEUE_MAX_BATCHES=10       # Queue backpressure control
REDDARCHIVER_CHECKPOINT_INTERVAL=10     # Progress save frequency
REDDARCHIVER_USER_PAGE_WORKERS=4        # User page generation workers
Modular PostgreSQL-backed design with specialized HTML modules and multi-platform import support:
Core Components:
reddarc.py - Main CLI entry point with platform auto-detectioncore/ - PostgreSQL backend, streaming importers (Reddit/Voat/Ruqqus), incremental updates, HTML generationapi/ - REST API v1 with 30+ endpointsmcp_server/ - MCP server for AI integration (29 tools)dynamic_pages.py - Flask page routes for dynamic serving modehtml_modules/ - 24 specialized modules (Jinja2 rendering, SEO, themes, statistics, CSS minification)templates_jinja2/ - 27 Jinja2 templates with inheritance systemprocessing/ - Parallel user processing, batch optimization, statisticsmonitoring/ - Performance tracking, auto-tuning, system optimizationKey Features:
Learn more: ARCHITECTURE.md - Complete technical deep-dive
30+ REST API Endpoints for programmatic access with MCP/AI optimization:
AI-Optimized Features: Field selection, truncation controls, export formats (CSV/NDJSON), batch endpoints, context endpoints. Rate limited to 100 req/min.
PostgreSQL Full-Text Search: Lightning-fast GIN-indexed search with relevance ranking, highlighted excerpts, and advanced filters (subreddit, author, date, score). Sub-second results for large datasets.
Instance Registry: Distributed leaderboard system for tracking archive instances. Configure metadata, automate scoring, group teams for coordinated archiving.
Learn more: API Documentation · Search Setup · Registry Guide
Internet content disappears every day. Communities get banned, platforms shut down, and valuable discussions vanish. You can help prevent this.
Don't wait for content to disappear. Download these datasets today:
† Voat Performance Tip: Use pre-split files for 1000x faster imports (2-5 min vs 30+ min per subverse)
‡ Ruqqus: Docker image includes p7zip for automatic .7z decompression
Every mirror matters. Store locally, seed torrents, share with researchers. Be part of the preservation network.
Already running an archive? Register it on our public leaderboard:
Benefits:
Found a new platform dataset? Help expand the archive network:
Why submit?
We welcome contributions! Please see CONTRIBUTING.md for development guidelines, code structure, and testing procedures.
Key areas for contribution:
See our modular architecture (24 specialized HTML modules plus importer, API, and processing packages) for easy entry points to contribute.
This is free and unencumbered software released into the public domain. See the LICENSE file (Unlicense) for details.
Anyone is free to copy, modify, publish, use, compile, sell, or distribute this software for any purpose, commercial or non-commercial, and by any means.
This project leverages public datasets from the following sources:
This project builds upon the work of several excellent archival projects:
Redd-Archiver was built by one person over 6 months as a labor of love to preserve internet history before it disappears forever.
This isn't backed by a company or institution—just an individual committed to keeping valuable discussions accessible. Your support helps:
Every donation, no matter the size, helps keep this preservation effort alive.
bc1q8wpdldnfqt3n9jh2n9qqmhg9awx20hxtz6qdl7
42zJZJCqxyW8xhhWngXHjhYftaTXhPdXd9iJ2cMp9kiGGhKPmtHV746EknriN4TNqYR2e8hoaDwrMLfv7h1wXzizMzhkeQi
Thank you for supporting internet archival efforts! Every contribution helps maintain and improve this project.
This software is provided "as is" under the Unlicense. See LICENSE for details. Users are responsible for compliance with applicable laws and terms of service when processing data.
A PostgreSQL-backed archive generator that creates browsable HTML archives from link aggregator platforms including Reddit, Voat, and Ruqqus.
เครื่องมือ
ยังไม่มีรายการเครื่องมือ เซิร์ฟเวอร์แบบรีโมตจะได้รายการหลังการตรวจสอบสถานะครั้งแรก
FAQ
คัดลอกคอนฟิก stdio สำหรับ Cursor, Claude Desktop, Claude Code หรือ VS Code ได้ในหน้านี้ คอนฟิกนี้ใช้การติดตั้งของผู้เผยแพร่ ไม่ใช่พร็อกซีของ PlugMCP
ระเบียนนี้ไม่ได้ระบุตัวแปรสภาพแวดล้อมที่จำเป็น
Redd Archiver ทำงานแบบโลคัลผ่าน stdio
ตรวจสอบล่าสุดเมื่อ 2026-10-26 A PostgreSQL-backed archive generator that creates browsable HTML archives from link aggregator platforms including Reddit, Voat, and Ruqqus.