MemClaw Fleet: 5-Agent Pipeline with Shared Memory
A runnable reference implementation of multi-agent constraint propagation using MemClaw. Each agent recalls what the previous one decided before acting. Clone it, run it, adapt it to any domain.
Power your agent
การติดตั้งจากผู้เผยแพร่ ไม่ใช่เอนด์พอยต์ของ PlugMCP
URL แบบรีโมตหรือคำสั่งบนเครื่องของคุณ? การติดตั้งสองแบบต่างกันอย่างไร
รันบน PlugMCP
A new server you create. It is not this listing's official endpoint. Use the publisher install when you want their URL and their credentials.
เปิดจากผู้เผยแพร่
A runnable reference implementation of multi-agent constraint propagation using MemClaw. Each agent recalls what the previous one decided before acting. Clone it, run it, adapt it to any domain.
A runnable reference implementation of multi-agent constraint propagation using Caura. 5 specialists share memory via MCP so decisions made upstream automatically govern downstream agents.
MemClaw is a governed shared memory platform built for AI agent fleets. It's not a vector database bolted onto your pipeline; it's a memory layer designed from the ground up for multi-agent coordination.
New to MCP? MCP (Model Context Protocol) is an open standard that lets LLMs call external tools via a consistent interface. MemClaw exposes its memory operations as MCP tools, so any MCP-compatible agent or IDE (Claude Code, Cursor, OpenClaw) can read and write fleet memory without custom integration code. Learn more →
This repo connects to the MemClaw MCP server over Streamable HTTP. pipeline/mcp_client.py initializes an MCP session, calls tools/list to get live schemas, and executes model-selected tools with tools/call. A REST compatibility mode is available for tests and debugging by setting MEMCLAW_TRANSPORT=rest.
Get your free API key at memclaw.net. Prism dashboard is at memclaw.net/prism.
Single agents hit a wall when complexity grows. They lose context, contradict their earlier decisions, and have no way to enforce rules across a long task.
Multi-agent pipelines solve this by dividing work across specialists. But they introduce a new problem: agents that can't see each other's decisions make contradictory choices. Agent A bans external JavaScript. Agent B loads a schema library from a CDN. Nobody catches it.
MemClaw fixes this with shared fleet memory. Every agent writes its decisions before finishing. Every downstream agent recalls those decisions before acting. Constraints propagate automatically not because the code hard-wires them, but because agents read each other's memory.
This repo demonstrates that pattern end-to-end:
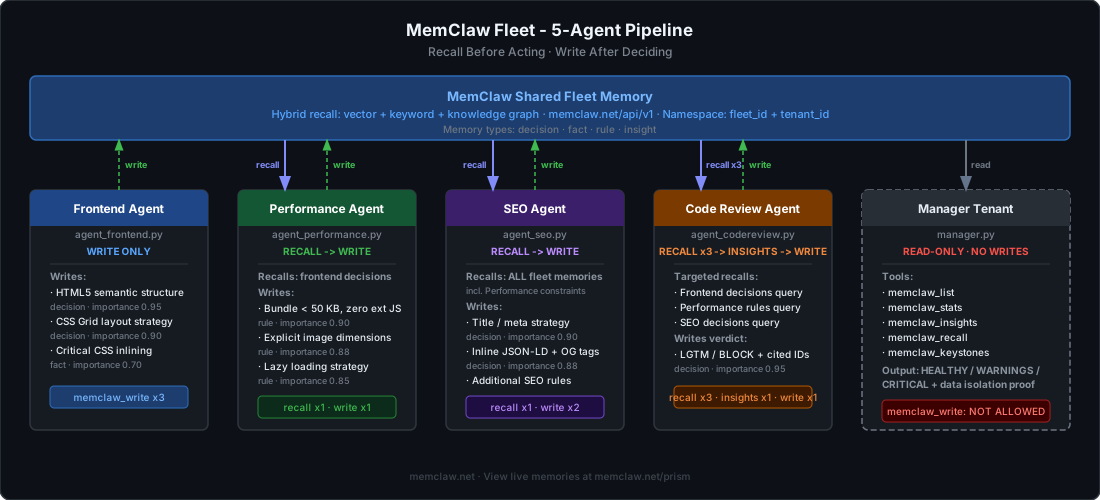
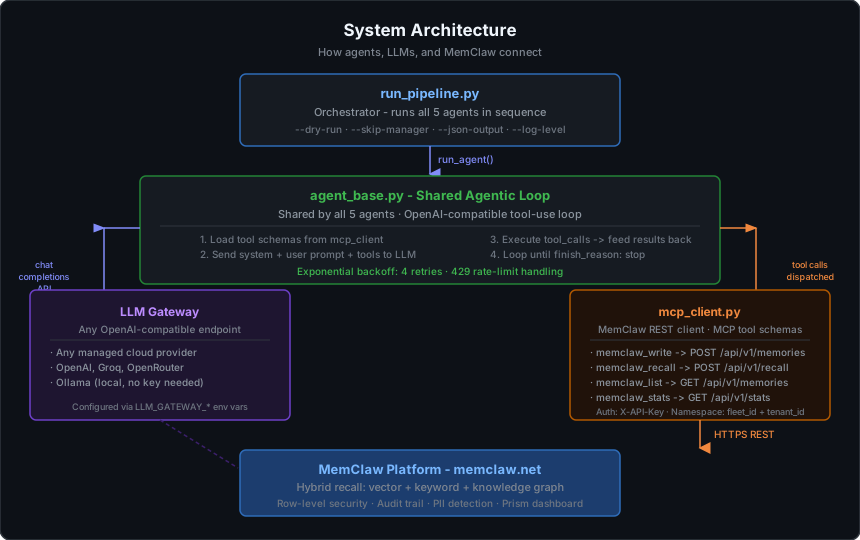
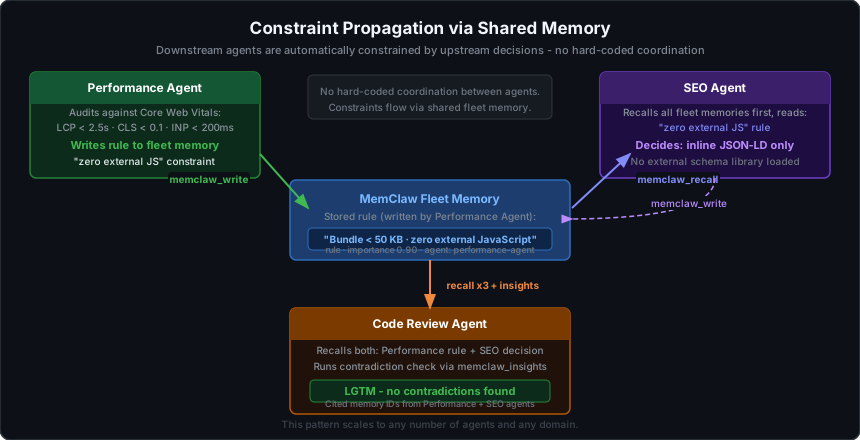
Each agent receives an explicit allowlist of MCP tools. Agents cannot call tools outside their allowlist; this enforces least-privilege and makes the data flow auditable.
Why restrict tools? Giving every agent every tool is a common mistake. The Manager agent's inability to call
memclaw_writeis enforced at the tool-schema level; it simply never receives that tool definition. At the end of every run it reports zero write operations, which is the read-only isolation proof.
What the Manager actually audits: Before the Manager's
run()is called, the orchestrator writes two lightweight bootstrap seed memories under the Manager's agent ID to register its identity in MemClaw (required for trust elevation). Those 2 writes happen in the orchestrator pre-flight; the Manager's own audit phase makes zero writes. When you seememclaw_statsreturntotal: 2, that reflects those seeds scoped to the Manager agent, not the full fleet. The full fleet memory list comes frommemclaw_list, which enumerates all memories across all agents in the fleet.
memclaw_insightsandmemclaw_statsscope note: At default trust level, bothmemclaw_insightsandmemclaw_statsoperate on the calling agent's own memories only. This meansmemclaw_statswill return a count scoped to the Manager agent (the 2 bootstrap seeds), not the full fleet; don't be surprised if you seetotal: 2rather than the ~20+ memories the other agents wrote. The complete fleet memory list comes frommemclaw_list, which does enumerate all agents. Cross-agent contradiction detection works because Code Review first recalls all fleet memories and the model reasons over them directly;insightsadds automated pattern/staleness analysis on top. For full cross-agentinsightsandstats, elevated trust is required; available on managed MemClaw accounts.
MemClaw provides three levels of isolation that can be combined. This pipeline uses fleet-level namespacing as the default.
Recommended defaults:
fleet_id per pipeline run or projectscope_agent only for sensitive per-agent secrets (API keys, PII) that should not be shared downstreammemclaw-build-fleet/
├── pipeline/
│ ├── run_pipeline.py # ← START HERE: orchestrator and entry point
│ ├── agent_base.py # Shared agentic loop used by all 5 agents
│ ├── mcp_client.py # MemClaw MCP Streamable HTTP client
│ ├── config.py # Shared constants (agent IDs, retry limits)
│ ├── agent_frontend.py # Agent 1: write only
│ ├── agent_performance.py # Agent 2: recall + write
│ ├── agent_seo.py # Agent 3: recall + write ← copy this to add a new agent
│ ├── agent_codereview.py # Agent 4: recall + insights + write
│ └── manager.py # Agent 5: read-only audit (no write access)
├── docs/
│ └── images/ # SVG architecture diagrams
├── .env.example # Copy to .env and fill in your keys
└── README.md
Reading order for new contributors: run_pipeline.py → agent_base.py → any single agent file → mcp_client.py
MEMCLAW_API_KEY and MEMCLAW_TENANT_ID from the Prism dashboard. The tenant ID is shown on your dashboard home page immediately after sign-up.Any provider that exposes an OpenAI-compatible /v1/chat/completions endpoint with function calling support will work.
Model requirement: The model must support
tool_choice/ function calling. If you see zero tool calls in the output, the model does not support it; switch models.
git clone https://github.com/caura-ai/memclaw-build-fleet.git
cd memclaw-build-fleet

python -m venv .venv

# Windows
.venv\Scripts\Activate.ps1

# macOS / Linux
source .venv/bin/activate

pip install -r pipeline/requirements.txt
.envcp .env.example .env # macOS / Linux
copy .env.example .env # Windows
Edit .env:
LLM_GATEWAY_API_KEY=your_provider_api_key
LLM_GATEWAY_API_URL=https://your-provider-base-url/v1
LLM_GATEWAY_MODEL=your-model-name

MEMCLAW_API_URL=https://memclaw.net
MEMCLAW_MCP_URL=https://memclaw.net/mcp
MEMCLAW_TRANSPORT=mcp
MEMCLAW_API_KEY=mc_your_key_here
MEMCLAW_TENANT_ID=your-tenant-id
MEMCLAW_FLEET_ID=memclaw-build-fleet
The Manager and Code Review agents need trust_level=2 to call memclaw_stats, memclaw_list, and memclaw_insights. Run these two commands once per tenant; they persist and never need repeating:
curl -X PATCH "https://memclaw.net/api/agents/manager-tenant/trust?tenant_id=YOUR_TENANT_ID" \
  -H "X-API-Key: $MEMCLAW_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"trust_level": 2}'

curl -X PATCH "https://memclaw.net/api/agents/code-review-agent/trust?tenant_id=YOUR_TENANT_ID" \
  -H "X-API-Key: $MEMCLAW_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"trust_level": 2}'
If you skip this step the Manager and Code Review agents will receive 403 errors and the pipeline will report
Data Isolation: ⚠️ UNCONFIRMED. See the Troubleshooting table for details.
Tenant ID format note: MemClaw silently normalizes underscores to hyphens in agent IDs and tenant IDs (e.g.
ran_test→ran-test). Paste your tenant ID exactly as shown in the Prism dashboard. If it contains underscores, the PATCH will return 403. Use the hyphenated form if you encounter a 403 on an otherwise correct key.
python pipeline/run_pipeline.py --dry-run
python pipeline/run_pipeline.py
Runs entirely on your machine. No cloud provider, no API key.
Download from ollama.com and install for your OS.
ollama pull llama3.1
Other supported models: mistral-nemo, qwen2.5, nous-hermes2. Verify function calling support on the model's Ollama page before using.
git clone https://github.com/caura-ai/memclaw-build-fleet.git
cd memclaw-build-fleet

python -m venv .venv

# Windows
.venv\Scripts\Activate.ps1

# macOS / Linux
source .venv/bin/activate

pip install -r pipeline/requirements.txt
.env for OllamaLLM_GATEWAY_API_KEY=ollama
LLM_GATEWAY_API_URL=http://localhost:11434/v1
LLM_GATEWAY_MODEL=llama3.1
MEMCLAW_API_URL=https://memclaw.net
MEMCLAW_MCP_URL=https://memclaw.net/mcp
MEMCLAW_TRANSPORT=mcp
MEMCLAW_API_KEY=mc_your_key_here
MEMCLAW_TENANT_ID=your-tenant-id
MEMCLAW_FLEET_ID=memclaw-build-fleet
Ollama's OpenAI-compatible server accepts any non-empty string as the API key. ollama is the conventional placeholder.
Same as Option A; run the two curl -X PATCH commands from Step 3 above before running the pipeline.
# Confirm Ollama is running
ollama list

python pipeline/run_pipeline.py --dry-run
python pipeline/run_pipeline.py
# Full pipeline (all 5 agents)
python pipeline/run_pipeline.py

# Skip the Manager audit (faster iteration during development)
python pipeline/run_pipeline.py --skip-manager

# Loop mode: resets memories between runs, pauses for Enter between iterations
python pipeline/run_pipeline.py --loop

# Reset all fleet memories after the run completes
python pipeline/run_pipeline.py --reset

# Save full results to JSON
python pipeline/run_pipeline.py --json-output results.json

# Loop mode keeps each JSON result separately: results-1.json, results-2.json, ...
python pipeline/run_pipeline.py --loop --json-output results.json

# Verbose debug logging (shows every tool call input and output)
python pipeline/run_pipeline.py --log-level DEBUG

# Run a single agent in isolation
python pipeline/agent_frontend.py
python pipeline/agent_performance.py
python pipeline/agent_seo.py
python pipeline/agent_codereview.py
python pipeline/manager.py
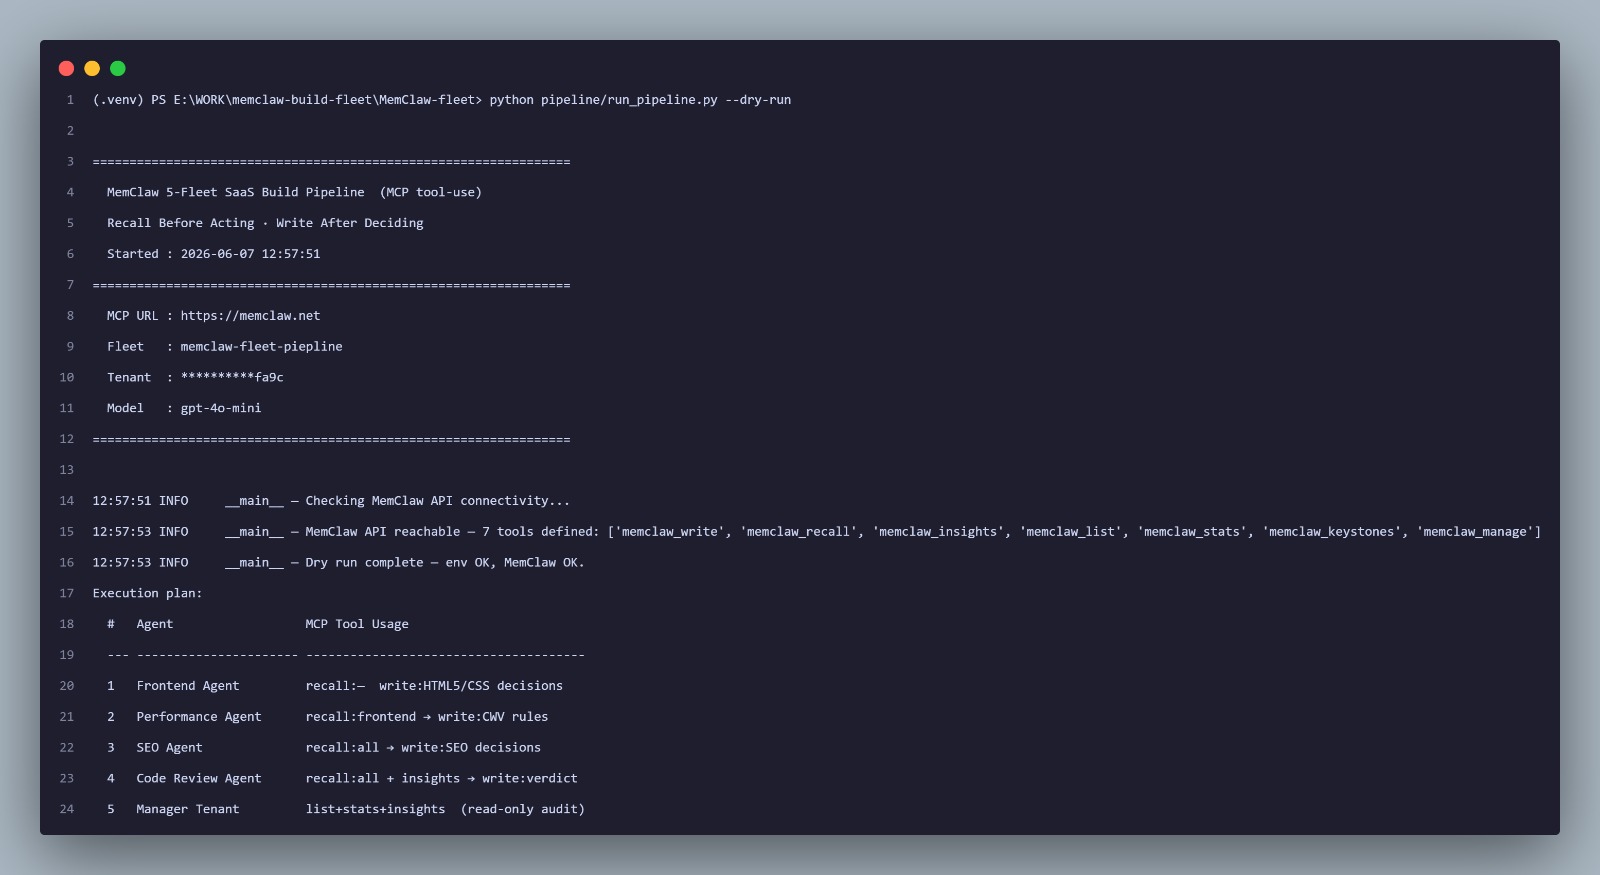
--dry-runUse --dry-run to verify your environment and MemClaw connectivity before running the full pipeline. It checks that all required env vars are set, opens an MCP session, calls tools/list, and exits; no LLM calls, no memories written.
python pipeline/run_pipeline.py --dry-run
If any required env var is missing, the run exits immediately with a clear error before touching the network:
ERROR __main__  Missing required env vars: LLM_GATEWAY_API_KEY, LLM_GATEWAY_API_URL, LLM_GATEWAY_MODEL, MEMCLAW_API_KEY, MEMCLAW_TENANT_ID, MEMCLAW_FLEET_ID
Copy .env.example → .env and fill in your keys.
MemClaw Fleet  ·  5-Agent MCP Pipeline
Recall Before Acting  ·  Write After Deciding

  Started  : 2026-06-06 10:58:10
  Fleet    : memclaw-build-fleet
  Tenant   : **********fa9c
  Model    : your-model-name
  MCP      : https://memclaw.net/mcp
Execution plan
Agent Results
Verdicts
▸ View memories : https://memclaw.net/prism
Note on verdict reproducibility:
Code Review VerdictandPipeline Healthare emitted by the LLM and are model-dependent. Different models (or the same model on different runs) may produceLGTMorBLOCKdepending on how they interpret recalled memories and any detected contradictions. ABLOCKverdict is not a pipeline failure; it means the model found a real or apparent inconsistency (e.g. SEO inline JSON-LD read as conflicting with the Performance "no external JS" rule). Review the agent'sfinal_textfor its cited reasoning.
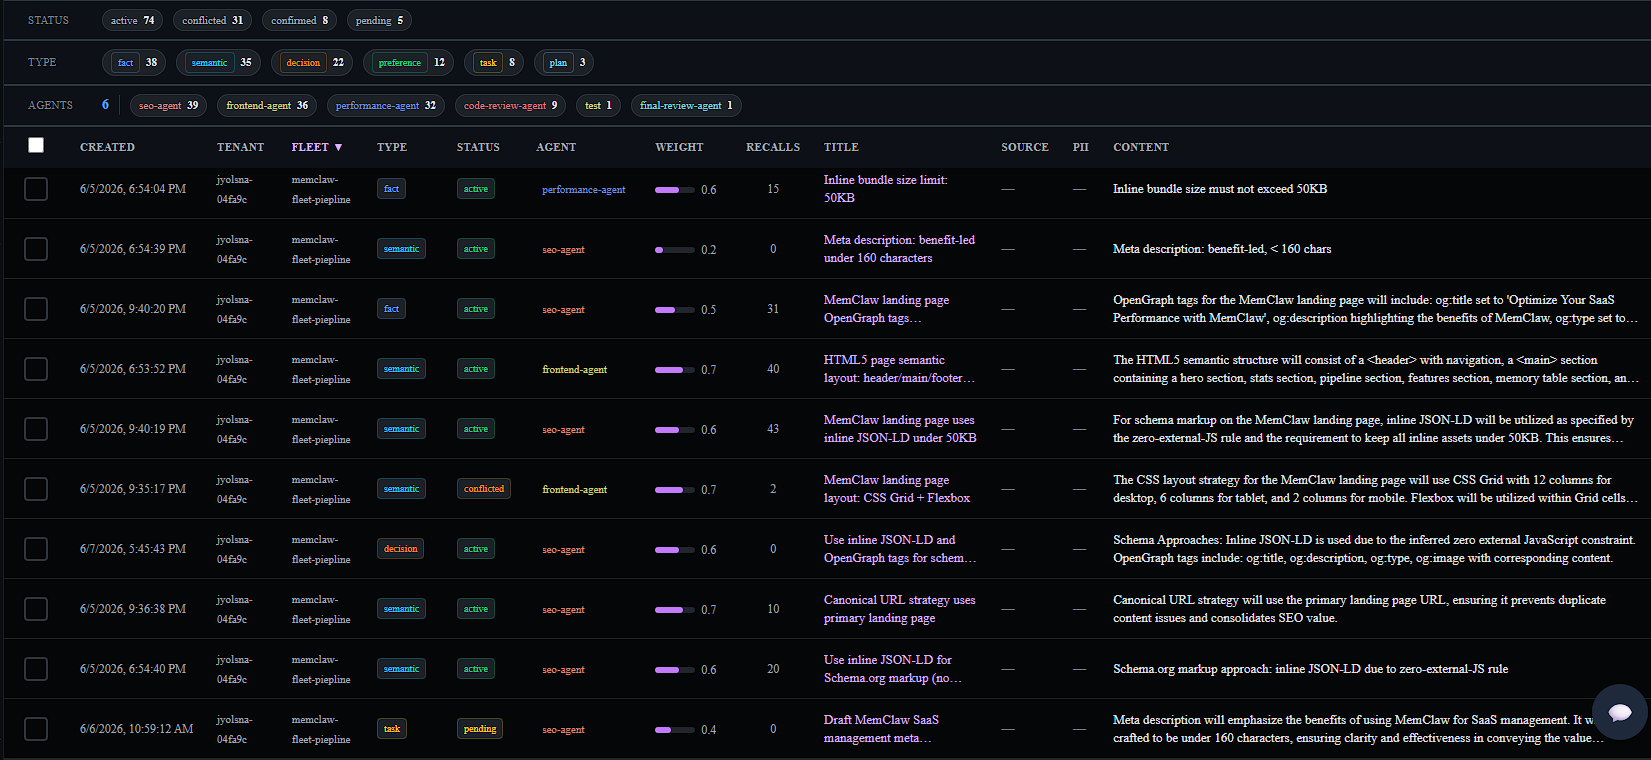
After any full pipeline run, every memory written by the fleet is visible in the Prism dashboard. The summary line at the end of the run prints the direct URL:
View memories at: https://memclaw.net/prism
In Prism you can:
decision, rule, fact, insight)A "fleet" is a named namespace (fleet_id) that scopes all memories written by a group of agents. You don't need to register it anywhere; set the name in .env and memories are automatically isolated to that namespace.
MEMCLAW_FLEET_ID=my-api-review-fleet
Any string works. Use something descriptive: payments-audit-fleet, onboarding-pipeline-v2, security-review-fleet.
Copy pipeline/agent_seo.py to pipeline/agent_<name>.py and change:
AGENT_ID      = "my-new-agent"
SYSTEM        = "You are a ..."
PROMPT        = "Review the ..."
ALLOWED_TOOLS = ["memclaw_recall", "memclaw_write"]
In pipeline/config.py, add a constant for your agent ID. In pipeline/run_pipeline.py, add it to PIPELINE_STEPS:
PIPELINE_STEPS = [
    ("Frontend Agent",   agent_frontend,  "recall: none  →  write: HTML5/CSS decisions"),
    ("My New Agent",     agent_myagent,   "recall: all  →  write: my decisions"),   # ← add here
    ...
]
Change MEMCLAW_FLEET_ID to a new value to start fresh. Old memories remain under the old namespace and won't affect the new fleet.
MEMCLAW_FLEET_ID=my-api-review-fleet-v2
After the pipeline runs, query the written memories three ways.
Register the MemClaw MCP server with Claude Code:
claude mcp add \
  --transport http \
  --header "X-API-Key: mc_your_key_here" \
  --scope user \
  memclaw https://memclaw.net/mcp
Open a new Claude Code session and ask it to recall memories from your fleet. Claude will call memclaw_recall directly against your tenant.
The official MCP debugging tool; browser UI, no code required.
npx @modelcontextprotocol/inspector
Opens at http://localhost:5173. Set transport to HTTP, URL to https://memclaw.net/mcp, add header X-API-Key: mc_your_key_here. Call any tool interactively.
This repo is a plain-Python reference implementation; no framework dependency required. The MemClaw MCP server works with any framework that can call an OpenAI-compatible tool or an MCP endpoint.
Wrap each memclaw_* tool as a CrewAI @tool and pass it to your Agent definition. The recall_before_acting and write_after_deciding prompts in each agent's SYSTEM string map directly onto CrewAI task descriptions.
from crewai_tools import tool
import mcp_client as mcp

@tool("recall fleet memories")
def recall(query: str) -> str:
    """Retrieve relevant memories from the shared fleet before acting."""
    return str(mcp.call_tool("memclaw_recall", {"query": query}, agent_id="my-crew-agent"))

@tool("write fleet memory")
def write(content: str, importance: float = 0.85) -> str:
    """Persist a decision to shared fleet memory after acting."""
    return str(mcp.call_tool("memclaw_write", {"content": content, "importance": importance}, agent_id="my-crew-agent"))
Assign tools=[recall, write] to agents that need fleet memory. The Manager audit agent gets tools=[recall] only; matching the read-only isolation this repo enforces.
Register MemClaw tools as StructuredTool objects and bind them to your graph nodes. Each node in the LangGraph state machine corresponds to one agent in this pipeline.
from langchain_core.tools import StructuredTool
import mcp_client as mcp

recall_tool = StructuredTool.from_function(
    func=lambda query: mcp.call_tool("memclaw_recall", {"query": query}, agent_id="langgraph-agent"),
    name="memclaw_recall",
    description="Recall relevant fleet memories before acting.",
)
Bind the tool to your ChatOpenAI model with llm.bind_tools([recall_tool, write_tool]); the rest of the agentic loop (tool-call → execute → feed back) works identically to agent_base.py.
Add MemClaw tools to an AssistantAgent's function map. AutoGen's register_for_llm + register_for_execution pattern maps cleanly onto the write-after-deciding pattern:
import autogen, mcp_client as mcp

assistant = autogen.AssistantAgent("seo_agent", llm_config={...})

@assistant.register_for_llm(description="Recall fleet memories.")
@assistant.register_for_execution()
def memclaw_recall(query: str) -> str:
    return str(mcp.call_tool("memclaw_recall", {"query": query}, agent_id="seo-agent"))
Any orchestrator that can make HTTP POST requests can call MemClaw directly without this Python client. Set MEMCLAW_TRANSPORT=rest in .env to use the REST fallback path in mcp_client.py, or POST to https://memclaw.net/api/v1/recall and /memories directly with X-API-Key authentication.
The MCP server (https://memclaw.net/mcp) also works with any MCP-compatible runtime; register it as an MCP tool server and each tool schema is discovered automatically at session start.
Contributions welcome. Useful directions:
mcp_client.py MCP session handling and REST compatibility modegit clone https://github.com/caura-ai/memclaw-build-fleet.git
cd memclaw-build-fleet
python -m venv .venv && source .venv/bin/activate # or .venv\Scripts\Activate.ps1 on Windows
pip install -r pipeline/requirements-dev.txt
Run the test suite locally with:
cd pipeline
pytest tests/ -v
Always run --dry-run first after making changes:
python pipeline/run_pipeline.py --dry-run
pipeline/agent_seo.py to pipeline/agent_<name>.pyAGENT_ID, SYSTEM, PROMPT, ALLOWED_TOOLS, and a run() -> dict functionconfig.pyPIPELINE_STEPS in run_pipeline.pyagent_base.run_agent() handles the full tool-use loop, retry logic, and tool execution. You only write prompts and declare which tools the agent can call.
MemClaw platform is separately licensed. See memclaw.net for terms.
A runnable reference implementation of multi-agent constraint propagation using Caura. 5 specialists share memory via MCP so decisions made upstream automatically govern downstream agents.
เครื่องมือ
ยังไม่มีรายการเครื่องมือ เซิร์ฟเวอร์แบบรีโมตจะได้รายการหลังการตรวจสอบสถานะครั้งแรก
FAQ
คัดลอกคอนฟิก stdio สำหรับ Cursor, Claude Desktop, Claude Code หรือ VS Code ได้ในหน้านี้ คอนฟิกนี้ใช้การติดตั้งของผู้เผยแพร่ ไม่ใช่พร็อกซีของ PlugMCP
ระเบียนนี้ไม่ได้ระบุตัวแปรสภาพแวดล้อมที่จำเป็น
Caura Build Fleet ทำงานแบบโลคัลผ่าน stdio
ตรวจสอบล่าสุดเมื่อ 2026-10-28 A runnable reference implementation of multi-agent constraint propagation using Caura. 5 specialists share memory via MCP so decisions made upstream automatically govern downstream agents.