Power your agent
คำสั่งของผู้เผยแพร่เอง ไม่ใช่เอนด์พอยต์ของ PlugMCP
Host a copy with our keys and logs.
npx -y @codewithjuber/[email protected]Claude Code ไม่มีลิงก์ติดตั้งสำหรับคำสั่งแบบโลคัล ให้คัดลอกคำสั่งด้านล่างแล้วรันในเทอร์มินัล
claude mcp add codewithjuber-forgekit -- npx -y @codewithjuber/forgekit@1.14.1รันในเทอร์มินัล
{ "mcpServers": { "codewithjuber-forgekit": { "command": "npx", "args": [ "-y", "@codewithjuber/[email protected]" ] } }}claude_desktop_config.json
URL แบบรีโมตหรือคำสั่งบนเครื่องของคุณ? การติดตั้งสองแบบต่างกันอย่างไร
รันบน PlugMCP
A new server you create. It is not this listing's official endpoint. Use the publisher install when you want their URL and their credentials.
เปิดForgekit is a Node.js CLI and MCP server (zero runtime dependencies) that gives your AI coding tools a reliability layer: agent memory that survives sessions and teammates, pre-push verification gates, and guardrails that run before and after every tool call. You author project rules once, and it emits native configuration for 12 agent tools. Claude Code is the most deeply exercised integration.
Why it wins, measured:
hooks/budget.json: 12 KB SessionStart, 4–6 KB the rest), enforced by the
launcher. No silent context bloat.forge verify runs the repo's real
test suites and reports PASS / FAIL / INCOMPLETE / NOT_CONFIGURED against a
tree fingerprint of the code it ran on — a red run blocks the push, not just the chat.forge impact lists the files a change probably
touches from a cached code graph: 1.68 ms warm (the cache is built by forge init).It does three jobs:
forge verify runs the repository's detected test suites and
reports PASS, FAIL, INCOMPLETE or NOT_CONFIGURED for the code state it ran on. A run that
covers only part of the repository is partial verification, and says so.Status: beta — read before you rely on it.
- Releases follow Semantic Versioning (CHANGELOG, release notes): since 1.0.0 a breaking change ships as a new major version. "Beta" describes maturity, not interface churn — the analyses are heuristic, the checks are advisory unless you enable enforcement, and most integrations have less real-world exercise than Claude Code. The core (
init,sync,substrate,impact,ledger, guards) is tested and in daily use.- Claude Code is the deepest-tested integration (full plugin, ambient
UserPromptSubmitguards). The other eleven tools receive native config (most also an MCP server entry; Aider, Windsurf/Devin and Kimi Code do not) but no automatic hooks, and have had less real-world exercise. On OpenClaw specifically, rules arrive viaAGENTS.mdproject context; the config-only path uses a one-command MCP registration, while installing the package as a compatible Codex bundle loads its skills and bundle-scoped MCP server. Neither path provides ambient hooks (see OpenClaw in ARCHITECTURE).- Impact/blast-radius analysis is heuristic — a regex-approximate code graph, not a sound call graph. It is not conservative: it can miss affected files as well as flag unaffected ones, so treat its output as advisory and an empty result as "unknown", not "safe".
- "Proof-carrying memory" is a name, not a formal proof. Claims are content-addressed and carry evidence references; confidence moves only when independent oracles (tests, CI, a human) raise it. There is no theorem-prover in the loop.
- Some integrations shell out —
forge harden,forge scan, and the git-native ledger assume Bash and Git are available (jqis not required — the guards read hook JSON with node). Claude hooks on Windows do not requirebashonPATH: their Node launcher finds Git Bash and preserves guard exits.protect-pathsneeds no bash at all and fails closed: when it cannot reach a verdict, the tool call is blocked rather than let through.- Guardrails reduce risk; they are not a security sandbox. What each integration actually does — config emission, MCP registration, automatic hooks, blocking — is in docs/INTEGRATIONS.md.
npm install -g @codewithjuber/forgekit   # or: npm install -g github:CodeWithJuber/forgekit
forge init                               # emit native config for the tools this repo uses
forge doctor                             # verify providers, hooks, and MCP wiring
forge demo                               # watch the gate catch a real defect (green → broken → green)
Then run a pre-action check inside a repository:
forge substrate "Change verifyToken in src/auth.js to require length > 20; update tests"
The result includes an assumption verdict, a model-tier recommendation, predicted impact,
a context-coverage check (what was delivered, not a proof that it suffices), scope clusters, and
a verification checklist. On Claude Code, the
pre-action check can run automatically through a UserPromptSubmit hook. On other supported
tools, Forgekit emits instructions and MCP configuration that the tool can invoke.
The three jobs, one command each:
forge ledger query "token validation"   # 1. what does the team already know about this area?
forge impact verifyToken                 # 2. which files will this edit probably touch?
forge verify                             # 3. did the change pass the suites that actually ran?
Real terminal recordings of the actual CLI — nothing mocked:
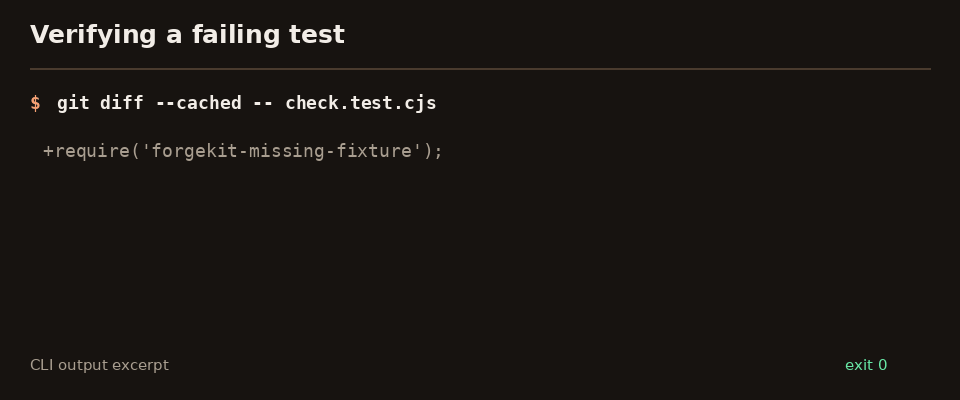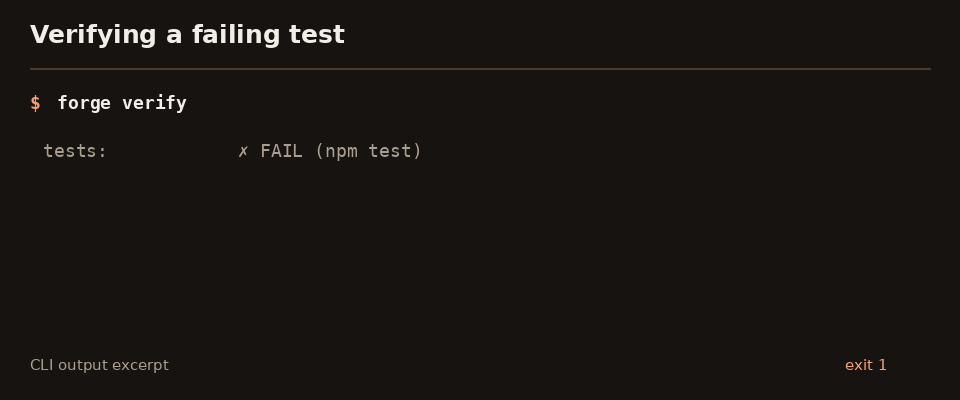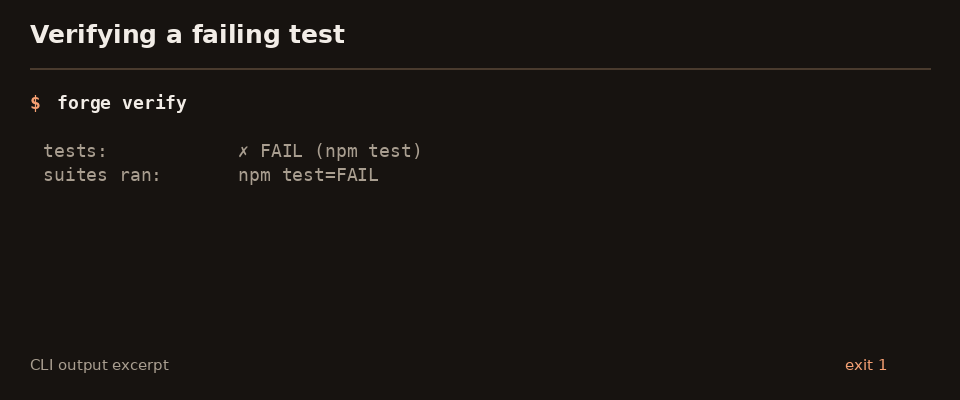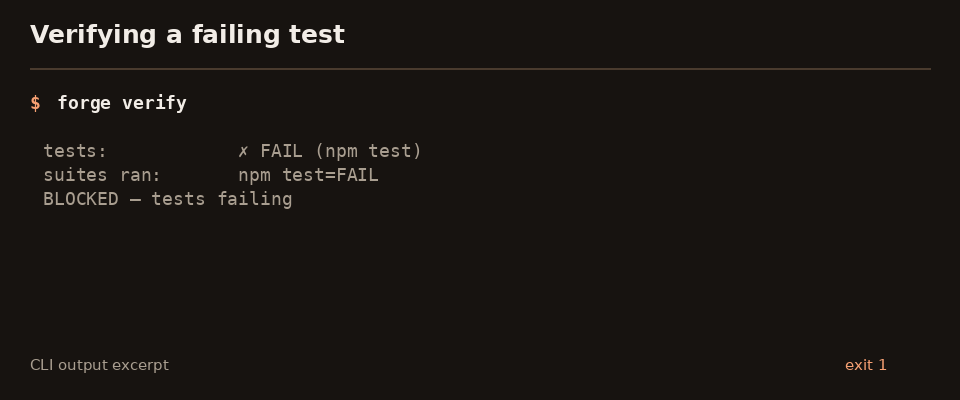
forge verify on a change that imports a package that doesn't exist: it flags the hallucinated dependency (frobnicator — not in the codebase) and blocks the push.
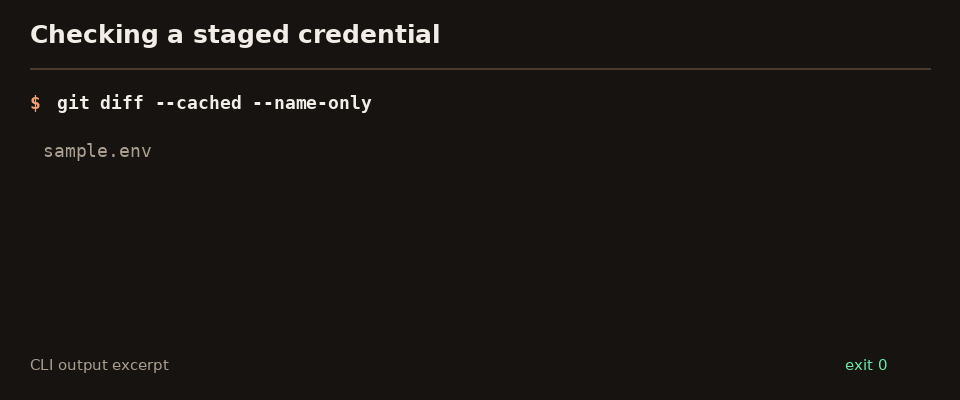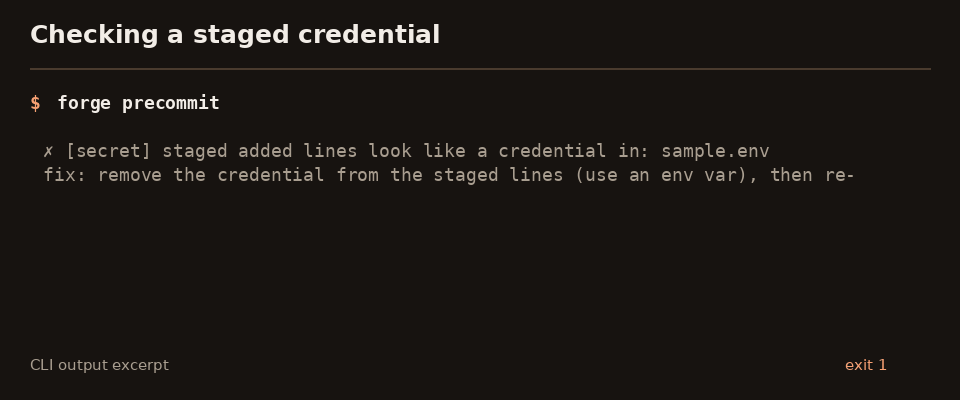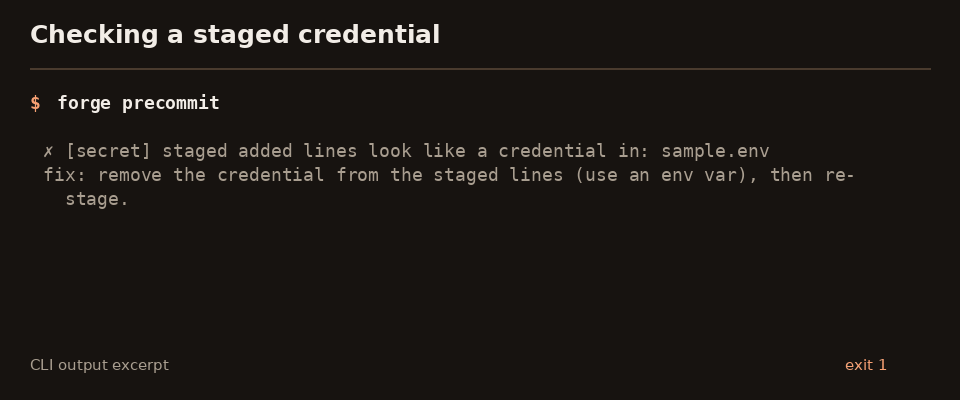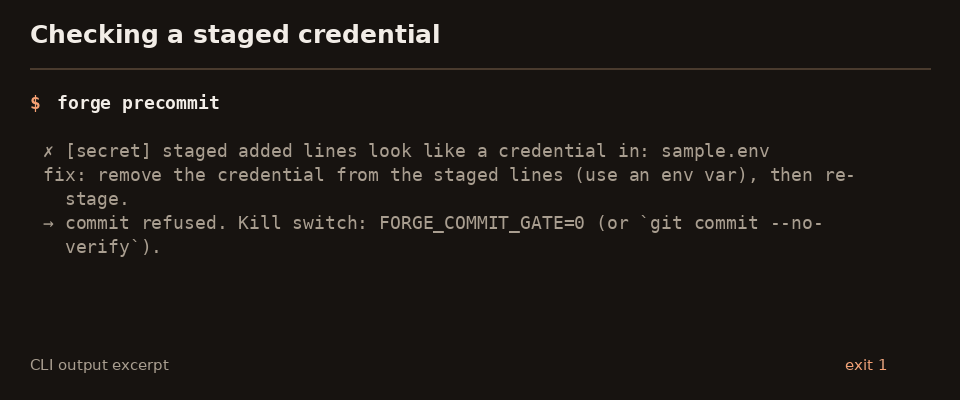
A fake secret staged with git add: forge precommit spots the credential-like line and refuses the commit before it ever happens.
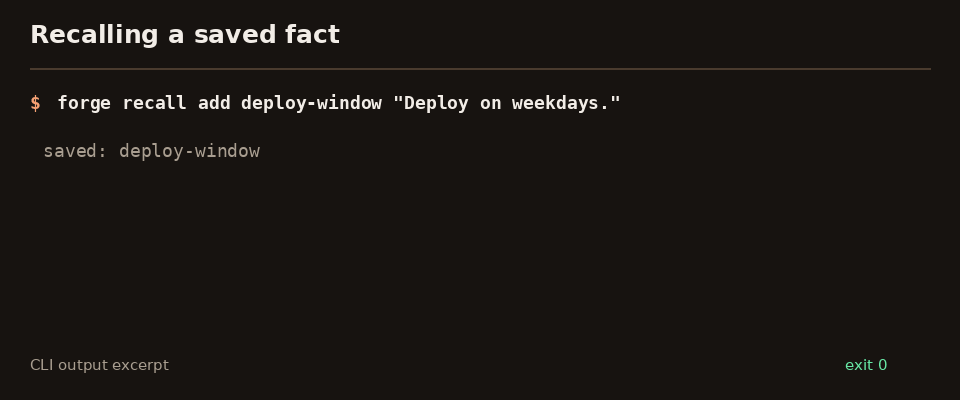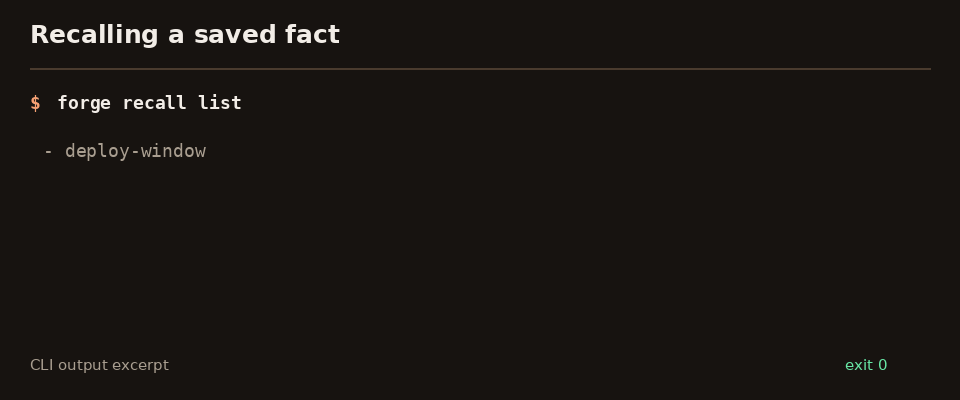
Cross-session memory: forge recall add saves a durable fact (deploy-window), forge recall list reads it back — memory that survives across agent sessions.
The pain it kills — and the mechanism that kills it:
forge ledger query "token validation" finds what the team already knows —
teammates get it by pulling. (Memory persists outside the model; it doesn't guarantee the
agent reads it — retrieval is budget-bounded, and missing context becomes a question, not
invented context.)forge impact <symbol> shows
the predicted blast radius before you edit, including coupled files you never named. It is
heuristic — a regex-derived graph, not a sound call graph — so treat the output as advisory
and an empty result as "unknown", not "safe".forge docs sync sweeps the diff for stale prose, forge handoff writes the bounded
session snapshot, forge decide records choices so no session re-decides them). On Claude
Code this runs automatically.CLAUDE.md does not. (Ambient hooks are the Claude Code
integration; other tools get config and instructions. The substrate is advisory by default;
set FORGE_ENFORCE=1 to block only its strongest signals.)Forgekit runs a deterministic substrate before work, lets the external coding agent act, and records evidence from tests, CI, or explicit human correction afterwards.

Open the interactive diagram: pan, zoom, search, and trace any node.
Only independent oracles (tests, CI, a human accept/revert) move a memory's confidence —
so a wrong lesson decays out instead of ossifying. Full design:
ARCHITECTURE.md.
The day-to-day value first — what the substrate keeps outside the model, so it survives between sessions and tools:
verifyToken
break?" and get the blast radius — the set of files an edit is predicted to impact, read
from a regex-approximate code graph (not sound, and it can miss affected files), including
coupled files you never named.CLAUDE.md prose does not. They reduce risk as
defence in depth; they are not a sandbox, and a sufficiently creative shell command can
still bypass a regex guard.forge docs sync sweeps the diff for stale prose, forge handoff writes the bounded
session snapshot the next session resumes from, forge decide records choices so no
session re-decides them).Every number is a median from npm run bench on this repo, recorded with its environment
block in reports/benchmarks.md — the project rule is a number is
an assumption until measured.
impact walks reverse dependencies transitively by default, so it
returns everything downstream while the labels name only the direct referencers (restricted
to one hop the same cases return their labeled sets). The precision 0.90 this line used to
quote does not reproduce. On nine real Python repositories the research prototype's impact
oracle reached recall 0.022 (refutation).forge cost --stages reports only your
measured stages.FORGE_ENFORCE=1 to block only its strongest
signals: a vacuous task, required context that cannot be assembled, or a large impact set
from a fresh repository graph.escalateTo recommendation, which names the tier only once an external check has actually
failed (the doom-loop diagnosis at its thrash threshold). Forgekit advises which tier to
request; it does not itself proxy or fail over model traffic. The opt-in cross-provider router
(route universal) minimises expected routing cost for a success target; its budgets are
expectations, not spend caps, and its benchmark headline is repository-reported. Its shipped
prior refits exactly from pinned public data in this repository, and a new in-repo held-out
replay finds it no better than a fixed cascade chosen on the same dev tasks
(docs/UNIVERSAL_ROUTING.md). For agents nobody watches,
--mode unattended adds a confidence-gated vote raise, a writes-code floor, a risk floor and
a gate on the top tier (Agent orchestration).forge verify runs the repository's detected test
suites, reports PASS, FAIL, INCOMPLETE, or NOT_CONFIGURED, checks unknown symbols,
and binds provenance to the code state it ran on. A verdict covers only the suites that ran:
partial coverage is INCOMPLETE, not PASS. --deep adds structural, security, spec-drift,
impact, and optional model-review lenses.A lead agent running several sub-agents mostly pays for context re-reads, not new work. In one measured session, 7 parallel agents on one shared e2e environment used ~857M tokens in ~4.5 h, ~98% of them cache re-reads: agents polled logs every ~10 minutes against a 250–300k-token context, more agents ran than the environment could serve, and the top model tier was hand-picked for routine work (~140M tokens).
forge sync now emits an orchestration rule pack into every tool's config: no polling,
a parallel-agent cap (default 2), heavy suites in CI, fresh small sub-agents with short reports,
model choice via forge route, tests plus lead review for money/auth/secrets/migrations/security
changes, isolated e2e environments, and a lean lead. Each rule has a stable id
(orch.no-polling, …) and can be switched per repo or globally:
forge orchestration                        # rules, routing settings, and where each value came from
forge orchestration off orch.parallel-cap  # this repo; add --global for every repo
forge orchestration set route.mode unattended
forge route "add a refund endpoint" --mode unattended --json   # tier key + policy steps
In unattended mode, forge route raises the tier on a confident proposer vote, starts
code-writing tasks at mid, keeps risky tasks on the premium tier, and allows the top tier only
with --allow-top and a top deterministic score. The default conservative mode is unchanged.
Details, defaults and the evidence: docs/ORCHESTRATION.md.
Claude Code's advisor tool lets the main model consult a
second, typically stronger model at decision points: before committing to an approach, when an
error keeps recurring, and before declaring a task done. The advisor reads the whole conversation
and is billed at its own rate per call, and Claude Code accepts it only when it ranks at or above
the session's main model. forge advisor configures it once, per repo or globally, emits it into
Claude Code's settings, and checks the pairing before Claude Code has to refuse it:
forge advisor set opus                     # this repo: .forge/forge.config.json → .claude/settings.json + an Advisor section in AGENTS.md
forge advisor set fable --global           # every repo: the user-level config → ~/.claude/settings.json (what /advisor saves to)
forge advisor check sonnet opus            # ok — exit 1 when the pairing would be refused (for scripts and CI)
forge advisor pairings claude-opus-4-8     # which advisors this main model accepts, and the suggested one
forge advisor off                          # remove advisorModel again
The Advisor section tells every agent that reads AGENTS.md when to consult it (approach,
recurring error, done check, risky code), when not to (short, well-specified tasks), and that the
evidence wins over its guidance; each rule has a stable id (advisor.before-approach, …) and can
be switched with forge advisor rule off <id>. The prompt-time advisory adds one line at a
decision point, the doom-loop advisory names the advisor when a failure recurs, and forge doctor
reports the pairing and the environment variables that keep the advisor off
(CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY,
CLAUDE_CODE_DISABLE_NONESSENTIAL_TRAFFIC). The pairing table ships as data
(source/advisor.json, with the date it was verified against the docs); a model newer than it is
accepted with a note, since Claude Code validates the pairing at launch.
Install using one path:
The plugin runs its guards and its forge-cortex MCP server from the plugin directory, so
it needs only node on PATH. It does not put the forge command on your shell's PATH;
to run the forge commands below yourself, also install the npm package.
Initialize inside a project:
forge init
forge doctor
forge doctor --fix
forge init can merge Forgekit hooks and permissions into
~/.claude/settings.json. That file is global and affects all repositories. Use
forge init --no-settings to skip the merge or forge init --remove-settings to reverse
Forgekit-managed entries. The implementation preserves unrelated entries and creates a
timestamped backup before changing the file. When the Forgekit Claude Code plugin is enabled
(in user, project or local settings), its hooks/hooks.json already runs every guard, so
forge init and forge doctor --fix merge permissions only and never register the guards a
second time.
forge init emits configuration only for the agent tools the repository already uses:
Claude Code plus any tool with a sign on disk (.cursor/, .codex/,
.github/copilot-instructions.md, and so on). Choose explicitly with
forge init --tools claude,cursor or --tools all; the choice is recorded in
.forge/forge.config.json, so later forge sync runs emit the same set. In AGENTS.md,
Forgekit owns only the block between and. A
hand-written AGENTS.md keeps every line and gets the block appended; forge sync and the
Stop-hook auto-sync rewrite that block and nothing else.
For an explicit model provider, inspect or update configuration with forge config. API keys
remain environment variables; Forgekit's provider file stores the environment-variable name,
not the secret value.
Commands are advisory unless their documented enforcement flag is enabled. Full worked examples
and output live in docs/GUIDE.md.
Terminal output is plain when piped. On an interactive terminal it can use color and confidence
meters; NO_COLOR disables color and FORCE_COLOR=1 enables it explicitly.
Lessons, durable facts, and verified reuse artifacts land as content-addressed claims under
.forge/ledger/:
forge init

# Work normally; hooks and explicit memory commands add claims and evidence.
git pull
forge ledger merge <path-to-another-ledger>
forge ledger sync
Identical claim content converges to one identifier while provenance records preserve authors.
forge ledger blame <id> shows the mint history, oracle outcomes, and derived trust. The default
storage is files in git, not a hosted database or synchronization service.
With no flags, forge ledger sync serializes ledger state under refs/forge/ledger on the
repository's git remote. A non-fast-forward race triggers a re-merge and bounded retry. A shared
directory can be selected with --dir <path> or FORGE_SYNC_DIR; --personal includes the
per-user ledger.
src/llm.js supports two wire formats:
Credentials are read from environment variables and are not put in command-line arguments. The implementation performs a bounded single-prompt request. It does not implement streaming, conversation persistence, or a model-driven tool-call execution loop.
Forgekit retrieves from its code graph and evidence ledger, then assembles a context bundle for an external coding agent. This is retrieval and augmentation for source-code work, not a general enterprise RAG pipeline. There is no document connector layer, chunking service, citation generator, managed index, or vector database in this repository.
MinHash remains the zero-dependency default. To opt into semantic similarity, configure an external provider with one of the formats the current implementation accepts:
# OpenAI-compatible embedding endpoint
export FORGE_EMBED="https://api.example.com/v1/embeddings"
export FORGE_EMBED_MODEL="your-embedding-model"
export FORGE_EMBED_KEY="your-provider-key"

# Or a local/external command that implements Forgekit's stdin/stdout vector protocol
export FORGE_EMBED="cmd:./my-embedding-provider"
Vectors are cached in .forge/embed-cache.jsonl. Provider failure, timeout, malformed output,
or missing vectors falls back to MinHash. The repository test uses a deterministic fake
provider; it verifies adapter and fallback behavior, not live performance of a hosted model.
The performance snapshot in reports/benchmarks.md was generated at
commit eb68ea9 and does not measure the optional embedding path. Current
embedding behavior is defined by src/embed.js and
test/embed.test.js.
Forgekit registers five Claude Code role definitions:
scout — read-only repository investigation;verifier — fresh-context correctness review;independent-reviewer — diff/spec/test-only merge gate;frontend-verifier — visual and accessibility review;doc-sync — documentation consistency after code changes.These are concrete role prompts supplied to the host tool. Forgekit does not contain a runtime that spawns these roles, exchanges inter-agent messages, or executes a LangGraph-style state machine.
The built-in MCP server exposes 21 tools, including:
substrate_check, preflight_check, assumption_gate, route_task;predict_impact, scope_files, rank_code, collide_check;cortex_lessons, forge_remember, forge_ledger_query,
forge_ledger_ratify, forge_ledger_retract;forge_doctor, forge_provider_status, forge_cost, dashboard data.The MCP server is the tool-provider side of function calling. The compatible host remains responsible for deciding when to call a tool and feeding the result back to its model.
The project is best read as agent reliability and developer tooling. It is not presented as an enterprise multi-agent application, a general-purpose RAG platform, or an Azure AI deployment. Per-claim status (implemented, measured, refuted, hypothesis, partial, reported) is kept in docs/status/.
For reviewers evaluating hands-on Agentic AI or GenAI work, each claim below links to the
implementation and its closest test or build proof. The evidence snapshot used for this
table is default-branch commit
3d9be37.
Personal maintainer use is intentionally not used as proof of organizational adoption. No customer count, enterprise deployment, production traffic, or service-level claim is made without corresponding public evidence.
Numbers below are reported only with their test boundary. See
reports/benchmarks.md and the linked evaluation artifacts for full
methodology.
Parser-stable snapshot labels used by the generated project pages are:
The boundaries in the table below are part of each result.
Recent audited CI runs cover Node 20, Node 22, and Windows Git Bash, plus the reusable
quality gate (CI workflow).
The quality gate runs the Node unit suite,
Biome checks, TypeScript type checking, critical-level npm audit, ShellCheck, zero-runtime-dependency
assertion, version and documentation checks, and npm pack --dry-run. The Python prototype
pytest suites were not part of CI at that commit; since aedddf5 a separate CI job runs both
prototype suites, the Theorem D sanity checks (research/recompute_corrections.py --theorem-checks) and the recomputation of every corrected number from the replication package.
This table describes architecture, not a claim of superiority or equivalent product scope.
The Python packages under research/python-prototypes/ are the
original research baselines preserved for auditability and result reproduction. They are useful
evidence of Python implementation work, but they are not the shipped Forgekit runtime.
router_gate implements:
Its checked-in evaluation used live model calls for a 30-task hand-labelled demonstration. The set was used to tune the rubric, so perfect separation is evidence that the mechanism works on that set, not a general accuracy estimate. Despite legacy package metadata using the phrase “production-ready,” the repository-level maturity classification is research prototype.
impact_oracle parses Python ASTs, stores a NetworkX
dependency graph as JSON, and predicts change impact through reverse-dependency traversal plus the
repaired sibling and forward relations (the in-tree package is the repaired v2, 49 tests). The
bundled evaluation mutates five symbols and uses pytest failures as independent ground truth. On
nine real repositories the as-shipped traversal reached recall 0.022; the repaired version's
held-out point estimate is above grep's, but that it beats grep is not established
(refutation). The Node forge impact graph is a different,
regex-derived implementation and inherits none of these numbers.
The production Forgekit equivalents are the Node implementations behind forge preflight,
forge route, forge atlas, forge impact, and the MCP substrate tools.
The cognitive-substrate white paper explains the motivation,
formal model, evidence map, adjacent work, and the relationship between the Python research
prototypes and the current Node implementation. Treat the paper's measurements according to
their stated methodology; do not blend results from different codebases or evaluation sets. The
"faculty" and theorem language lives there and in research/, with dated
corrections: the papers now state what a frozen model does not guarantee (durable state across
calls, context beyond the window, weight updates from outcomes, reliable self-verification) rather
than claiming it cannot adapt at all, and they name the prior art (CoALA, Reflexion) the
architecture builds on. Their PDFs are historical, pre-correction editions; read the HTML.
Forgekit includes a hand-authored landing page at landing/index.html and
generates a status page at public/index.html. The generator reads
repository data from package.json, README.md, CHANGELOG.md, and the benchmark report.
npm run pages:build
BUILD_PAGES_LIVE=1 npm run pages:build
The default build is offline and deterministic. Optional live mode reads public GitHub repository
metadata with bounded retries and caching. GitHub Pages deployment is defined in
.github/workflows/static.yml; this static documentation site is
not an AI application deployment.
Current implementation truth for optional embeddings is src/embed.js: use an http:// or
https:// endpoint, or cmd:<command>. A bare FORGE_EMBED=1 is not a valid provider
configuration. Benchmark comparison prose that describes MinHash-only behavior is historical and
does not supersede the current source and tests.
Sixty seconds, three commands, and your agent tooling gets a memory:
npm install -g @codewithjuber/forgekit
forge init      # emit native config for the tools this repo uses
forge doctor    # verify providers, hooks, and MCP wiring
Then try it on your own repo:
forge impact <symbol>     # what will this edit probably touch?
forge ledger query "..."  # what does the team already know about this area?
forge verify              # did the change pass the suites that actually ran?
MIT licensed. Built by CodeWithJuber.
Shared memory, impact analysis, and guardrail hooks for AI coding agents — authored once, emitted as native config for Claude Code, Codex, Cursor, Gemini, Aider, and more.
{ "mcpServers": { "codewithjuber-forgekit": { "command": "npx", "args": [ "-y", "@codewithjuber/[email protected]" ] } }}เครื่องมือ
ยังไม่มีรายการเครื่องมือ เซิร์ฟเวอร์แบบรีโมตจะได้รายการหลังการตรวจสอบสถานะครั้งแรก
FAQ
คัดลอกคอนฟิก stdio สำหรับ Cursor, Claude Desktop, Claude Code หรือ VS Code ได้ในหน้านี้ คอนฟิกนี้ใช้การติดตั้งของผู้เผยแพร่ ไม่ใช่พร็อกซีของ PlugMCP
ระเบียนนี้ไม่ได้ระบุตัวแปรสภาพแวดล้อมที่จำเป็น
@codewithjuber/forgekit ทำงานแบบโลคัลผ่าน stdio
ตรวจสอบล่าสุดเมื่อ 2026-11-13 Shared memory, impact analysis, and guardrail hooks for AI coding agents — authored once, emitted as native config for Claude Code, Codex, Cursor, Gemini, Aider, and more.
