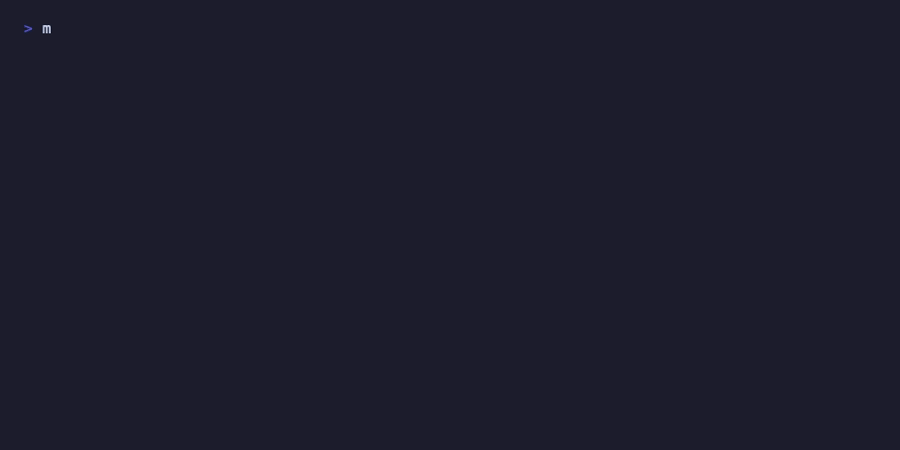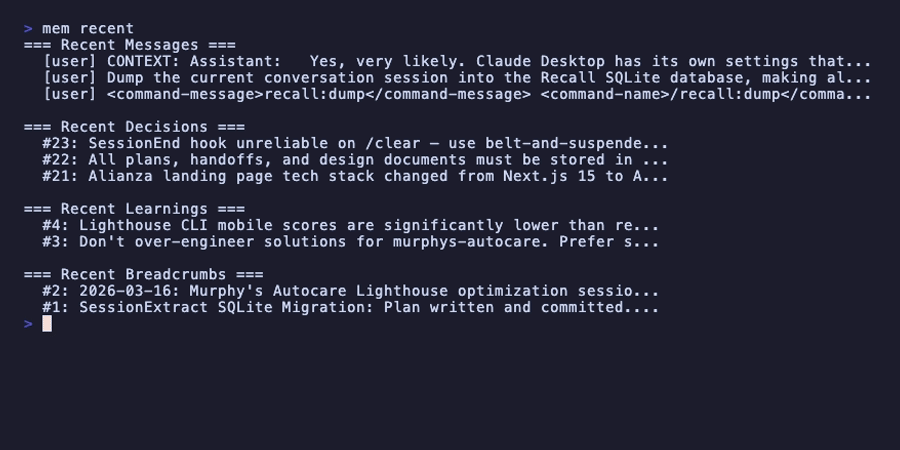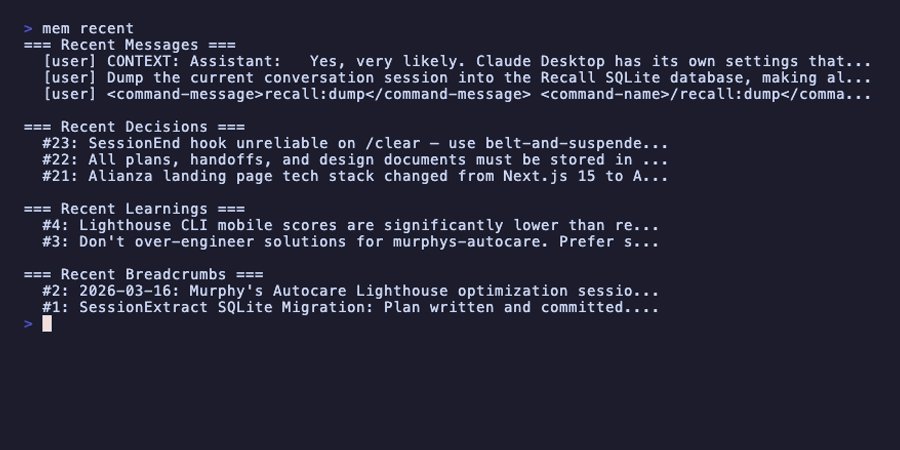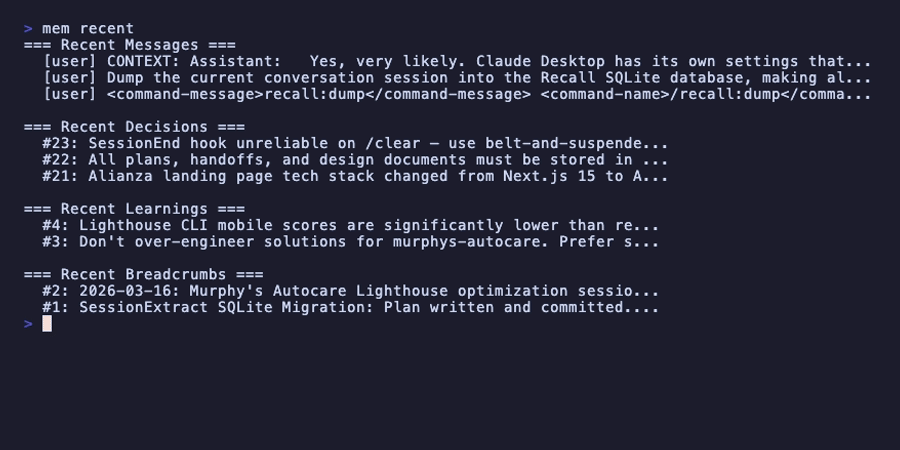
Local memory for AI coding agents. Recall remembers your past sessions so your agent doesn't start from scratch every time.
ดาว
4
เครื่องมือ
—
อัปไทม์
—
Recall is a retrieval-first memory layer: everything lands in one searchable database, the best of it is ranked and injected where a host supports session-start context, and decisions carry confidence, importance, and a lifecycle across any coding agent/harness.
A SQLite-backed persistent memory layer for coding agents. Host lifecycle adapters capture sessions automatically, MCP tools expose them mid-session, hybrid search (FTS5 + embeddings) retrieves them, and a tiered L0/L1 recall block injects identity + top-ranked records on supported hosts. MCP and skills connect supported hosts to one local database where each host supports them; lifecycle automation is host-specific.
Got questions about the project? I'd suggest using DeepWiki from Devin/Cognition to ask questions about the project.
All coding agents forget when a session ends. Recall doesn't — it extracts, indexes, and recalls what matters across every session, across every agent you use.
Built on the Model Context Protocol. One SQLite file. Retrieval does not phone home. Optional Jev is off unless JEV_RECALL_KEY is set in the process environment or in ~/.env. A non-blank environment value wins. When the key is present, Jev sends scrubbed extracted candidates to TypeSafe. No vendor lock-in. Optional ~/.agents/Recall/config.json can point query, extraction, or cluster at a harness. Recall starts Claude, Pi, and Codex. OpenCode, Grok, JCode, omp, and Cursor fail that step until a stdin contract is proven. Anything else is a command you write. A missing file keeps today's local search and extractors. Install never writes the file.
Stable on Claude Code. Beta on Pi and OpenCode. Codex CLI has native MCP, skills, automatic capture, and session-start injection. Grok Build CLI has automatic capture but no automatic injection. omp has native main-session capture with skills and MCP kept separate. JCode remains MCP and skills only after a bounded live probe. See Roadmap.
AI agents have no memory between sessions. Context is lost. You repeat yourself. Decisions made last week are forgotten today. Every new session re-learns the basics.
How Recall Fixes It
Install once, then forget about it. Recall runs silently in the background:
┌──────────┐    ┌────────────────┐    ┌──────────────┐    ┌───────────────┐    ┌──────────────┐
│ You Work │───▶│ Stop hook fires│───▶│ Auto-Extract │───▶│ SQLite + FTS5 │───▶│ Next Session │
└─────▲────┘    │ (end of turn)  │    └──────────────┘    └───────────────┘    └──────┬───────┘
      │         └────────────────┘                                                    │
      └───────────────────────────── Memory Available ───────────────────────────────┘
Automatic capture — supported lifecycle adapters preserve session progress without manual dumps; each host's exact capture and extraction behavior follows its verified lifecycle surface
Full-text + semantic search — find anything from any past session
Tiered session-start context — L0 identity (who you are) + L1 importance-ranked top records load automatically on supported hosts
Zero friction — no workflow changes, no manual steps
MCP integration — your agent searches memory automatically through standard MCP tools
Why Recall
Four things that set Recall apart from cloud-hosted memory layers and from agent-specific scratch files:
Local-first, zero infrastructure. One SQLite file at ~/.agents/Recall/recall.db (override via RECALL_DB_PATH). WAL mode, 0600 perms. No vector database, no graph database, no agent server. Keyword and hybrid retrieval need no API key and do not phone home. Optional Ollama for embeddings stays local. Optional Jev is the exception: with JEV_RECALL_KEY in the environment or ~/.env, scrubbed extracted candidates go to TypeSafe. A non-blank environment value wins. Missing from both, Jev is off and those rows are written unchanged.
Multi-agent native. One memory layer across the agents you actually use. Claude Code, Pi, OpenCode, Codex, Grok, JCode, and omp share the same database through their supported MCP, skill, and lifecycle surfaces. Automatic capture and injection depend on each host's supported lifecycle surfaces; see the capability matrix below.
Structured taxonomy, not a flat blob. Decisions (with supersede/revert lifecycle and confidence scoring), learnings, breadcrumbs, and Library of Alexandria entries (Automatic-capture LoA and Curated LoA) — each has a purpose and a query path. Importance scoring (1–10) surfaces what matters first.
Hybrid search that works offline. FTS5 keyword search ships with SQLite — no embedding infrastructure required to find anything. Optional Ollama embeddings layer on top for semantic queries. Both are merged via Reciprocal Rank Fusion. Lose Ollama, lose nothing — the keyword path keeps working.
Quick Start
First-run walkthrough (install, first commands, where the database lives, how a session starts, how MCP/hooks get wired): Getting Started.
Recall requires Bun (it uses bun:sqlite and Bun-native hooks).
Do not install recall-memory from npm; that name belongs to an unrelated project (#312). Follow the canonical Installation guide for the current source-checkout or local-tarball bootstrap, then use the matching host guide below.
Merge the repository's templates/cursor/ snippets; there is no marketplace plugin.
recall stats        # Database overview
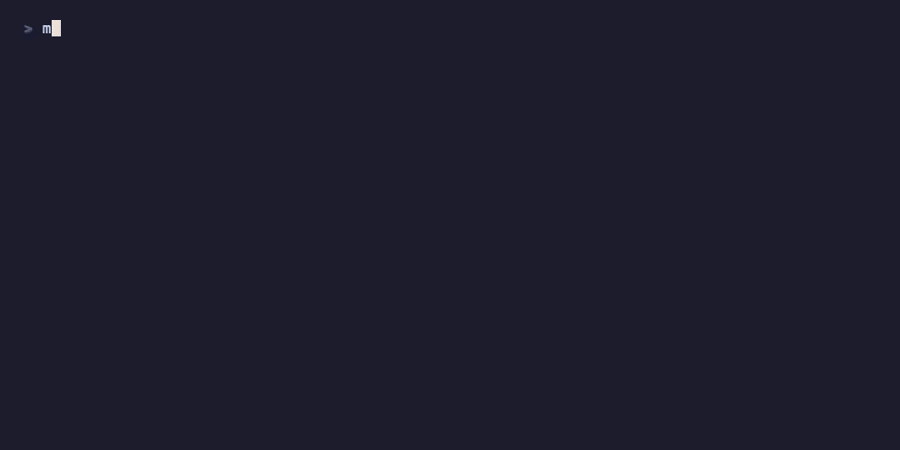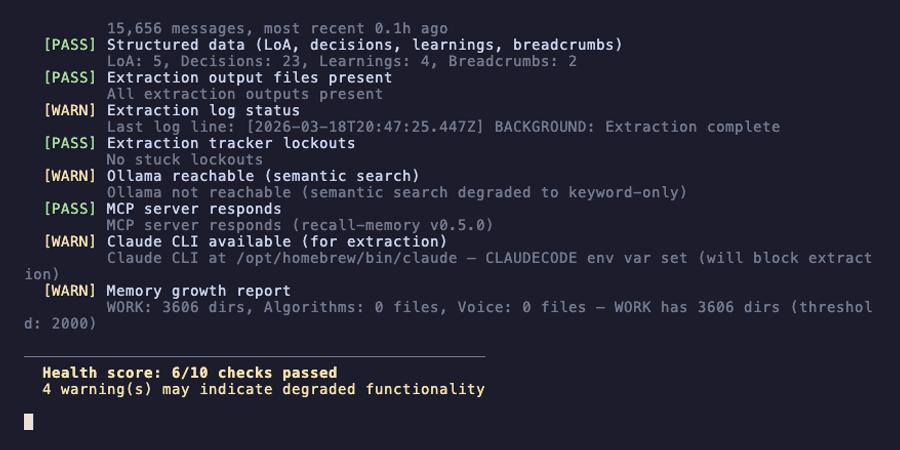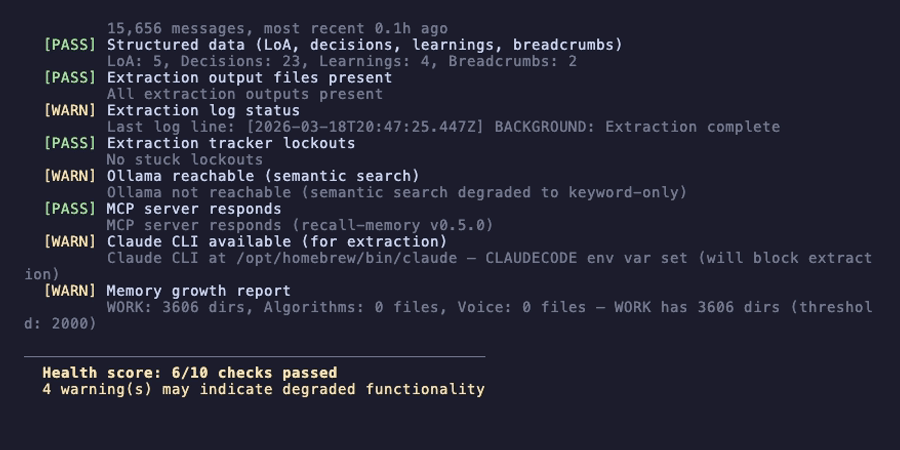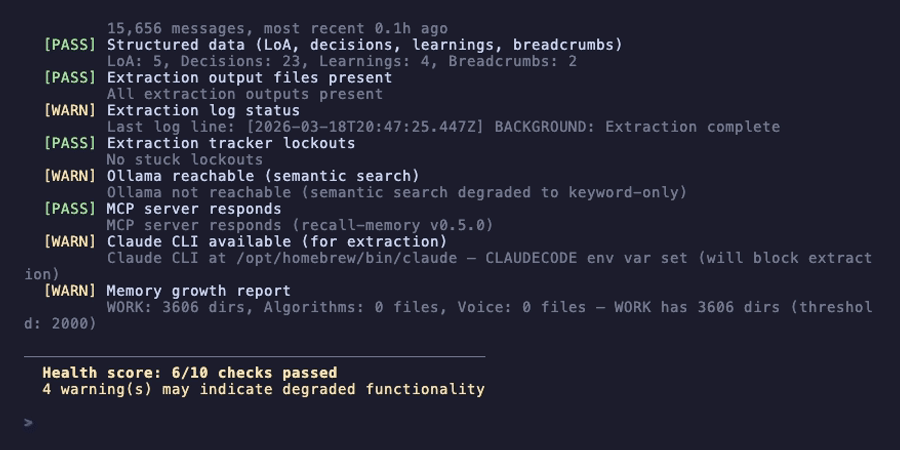
recall doctor       # Health check
Restart each attached agent so it loads the plugin, extension, or snippets.
The Installation guide owns the bootstrap sequence. Managing Recall explains when to use recall install versus ./packaging/install.sh for installer-owned surfaces.
First run: set your identity
Recall's supported session-start integrations inject a small identity file at
the top of a session (the L0 tier — your role, projects, tools, and working
preferences). Without it, L0 is empty and every new session has to
re-learn the basics.
recall onboard
A 7-question interview that writes the resolved global identity file. On a new
install this is ~/.agents/Recall/MEMORY/identity.md; an existing user-owned
Claude identity remains authoritative. See the installation guide
for the shared resolver's precedence. Run it once.
Re-run whenever your role, active projects, or working preferences change.
Use | (not ,) to separate values so a phrase like no force-push, ever
survives as a single entry.
Updating
From inside Claude Code, /do-recall-update prints the current vs. latest
release and the exact command to run. From a shell:
./packaging/update.sh --check   # version check only
./packaging/update.sh           # full update: pull, build, migrate, re-register hooks
Recall sits between your agent and a single SQLite database. A WRITE path captures sessions where a host exposes a supported lifecycle surface; a READ path injects memory where a host supports session-start context. The diagram below shows the shared flows side-by-side, with the line styles in the legend distinguishing capture (solid), recall (dashed purple), and the write-only markdown mirror (dashed gray).
Jev scores structured extraction: one POST, one Choice per candidate. recall capture does not call it. If neither a non-blank process value nor $HOME/.env provides a key, or if a Jev request fails, Recall still writes the parsed rows.
flowchart TD
  subgraph scored [Structured extraction]
    claude["Claude Stop hook"] --> extract["RecallExtract"]
    batch["OpenCode and Pi markdown drops"] --> batchExtract["RecallBatchExtract --reextract-md"]
    batchExtract --> extract
    import["conversation import"] --> structured["writeStructuredExtraction"]
    extract --> parse["parse decisions, learnings, breadcrumbs"]
    structured --> parse
    parse --> key{"Jev key resolves?"}
    key -->|no| write["write every parsed row"]
    key -->|yes| jev["one POST, one Choice per candidate"]
    jev -->|scored| gate{"keep / demote / drop"}
    jev -->|timeout or bad response| write
    gate -->|keep| write
    gate -->|demote| low["write at importance 3"]
    gate -->|drop| omit["omit that row"]
  end
  subgraph bypass [Native raw capture]
    omp["omp session_stop"] --> door["recall capture"]
    codex["Codex Stop"] --> door
    grok["Grok lifecycle hook"] --> door
    door --> raw["write raw text, skip Jev"]
  end
Set JEV_RECALL_KEY in the environment or in ~/.env. A non-blank environment value wins. Walk through that once in Score one memory item with Jev.
Claude Code Session Lifecycle
Session starts — A SessionStart hook injects two tiers of context: L0 identity (your global or project-local identity.md, always on) and L1 top records (top 12 by importance score, with 4 slots reserved for curated Library of Alexandria entries). L2/L3 stay on disk and are pulled on demand via MCP search.
During the session — your agent searches memory via MCP tools (memory_search, memory_hybrid_search, memory_recall, context_for_agent) before falling back to git history. Decisions, learnings, and breadcrumbs are recorded in real-time with memory_add.
End of every turn — A Stop hook fires RecallExtract.ts, which self-spawns a background process (non-blocking). It checks .extraction_tracker.json and only re-extracts if the conversation has grown meaningfully since last time — so capture is incremental, not just an "on exit" event.
Extraction pipeline — The conversation JSONL is filtered, deduplicated, and run through the Automatic-capture Extractor (default claude-cli, then ollama; chunking for sessions >120K chars). A quality gate rejects low-quality extractions before they're stored. Optional per-path config: architecture.
PreCompact flush — When Claude Code is about to compact its context, a PreCompact hook (RecallPreCompact.ts) flushes the in-flight messages first, so the squashed window is never lost.
Dual-write storage — Results are written to SQLite (the only query surface — every CLI/MCP read hits this) and to markdown artifacts (DISTILLED.md, HOT_RECALL.md, etc., write-only, human-readable).
Batch catchup (optional) — A cron job (RecallBatchExtract.ts) sweeps any sessions the Stop hook missed during crashes or interruptions, and ingests sessions dropped by the OpenCode plugin and Pi extension into ~/.agents/Recall/MEMORY/{opencode,pi}-sessions/. For scheduling, see optional batch extraction and managed quarterly aging.
TELOS auto-sync (PAI users) — If you use Personal AI Infrastructure (PAI), Recall ships a RecallTelosSync.ts SessionStart hook that watches ~/.claude/skills/PAI/USER/TELOS/ for changes and silently runs recall telos import --update when any file is newer than the last import. This is automatic — no action required once Recall is installed and PAI's TELOS directory exists. You can also import manually at any time with recall telos import --yes. If you don't use PAI, the hook checks for the directory, finds nothing, and exits in under 1ms.
Search Strategies
Strategy
Command
How it works
Keyword
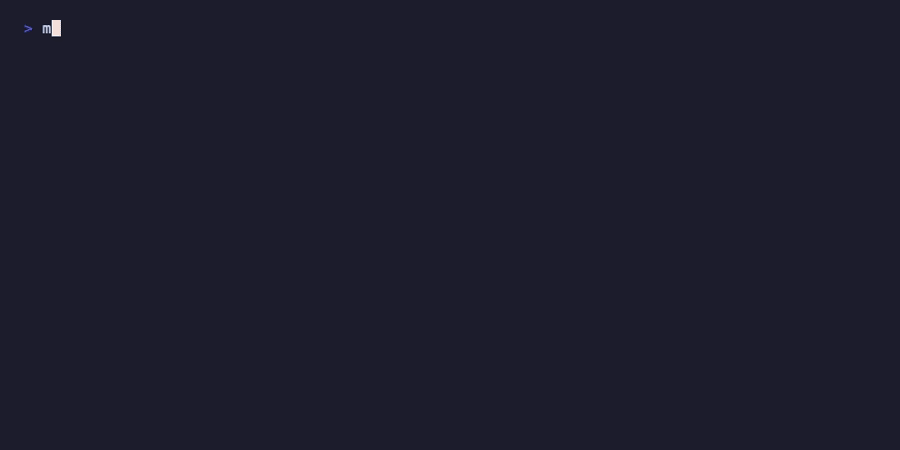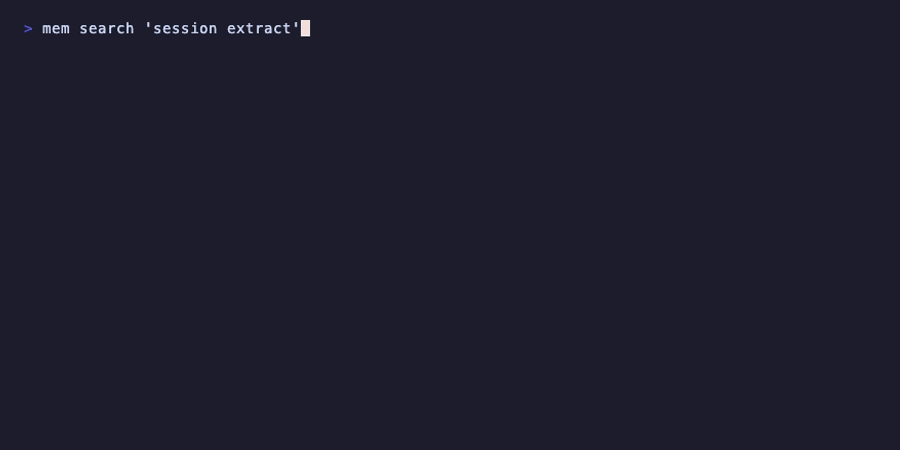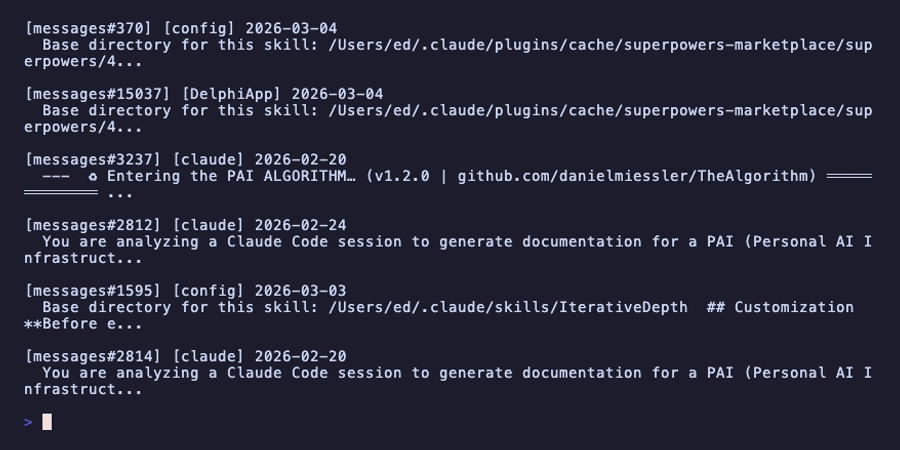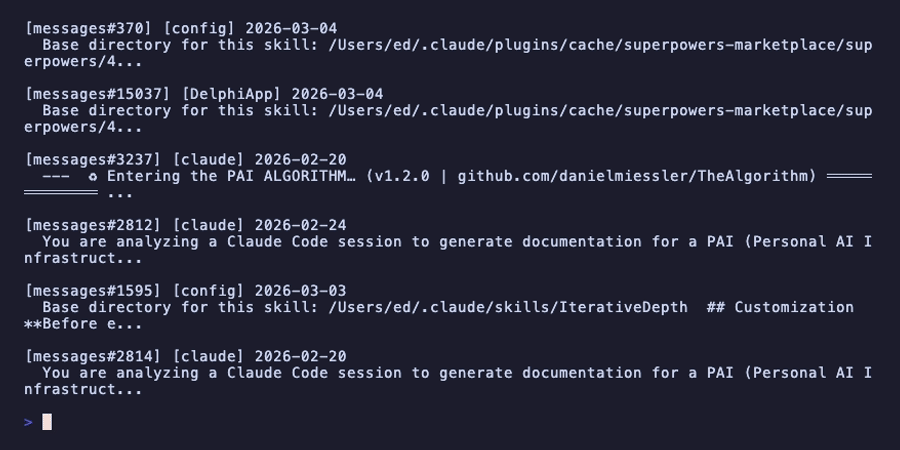
recall search "query"
FTS5 full-text search across all tables. Use -t decisions to hard-filter, or --bias-type decisions to prefer decisions while keeping other matches.
Semantic
recall semantic "query" / recall "query" -v
Ollama embeddings → cosine similarity (requires Ollama). There is no recall embed semantic verb.
Hybrid (default)
recall "query"
Both keyword + semantic, merged with Reciprocal Rank Fusion (k=60). Falls back to keyword-only if Ollama is unavailable
Narrowing by record type — table vs bias_type. Both let you steer results toward decisions, learnings, breadcrumbs, LoA entries, or raw messages, but they differ in strength:
-t / table is a hard filter — only the named record type comes back.
--bias-type / bias_type is a soft boost — matching records of that type rank higher, but every other type can still appear when it's relevant.
Where it's available:table and bias_type act on FTS5 ranking, so they exist only on the keyword path — recall search, recall "query" -k, and the MCP memory_search tool. They are silently ignored elsewhere: plain recall "query" (default hybrid), recall "query" -v (semantic), and memory_hybrid_search rank by embedding distance and have no bias_type. Valid types: messages, decisions, learnings, breadcrumbs, loa.
Auto-captured session memory — Claude Stop shells recall capture and still extracts; Codex, Grok, omp, and Pi shutdown call the same door; OpenCode stays on its markdown drop; JCode calls it only when text is supplied
MCP server (recall-mcp) — memory_search, memory_hybrid_search, memory_recall, memory_add, memory_dump, context_for_agent exposed to your agent mid-session. memory_search supports table hard filters and bias_type soft boosts.
Hybrid search — FTS5 keyword search + optional Ollama embeddings, fused via Reciprocal Rank Fusion. Lose Ollama, lose nothing — keyword path keeps working. Type targeting (table / bias_type) is a keyword-path feature — see Search Strategies.
Tiered RecallStart (v0.7.0+) — resolved L0 identity + L1 top 12 records ranked by importance, with 4 reserved slots for curated Library of Alexandria entries. L2/L3 fetched on demand
Importance scoring (1–10) — every record carries an importance score that drives what surfaces in L1. Manage with recall pin / recall unpin / recall importance backfill
PreCompact flush — RecallPreCompact.ts writes in-flight messages to SQLite before Claude compacts its context window, so the squashed chunk is never lost
Decision lifecycle — recall decision supersede/revert tracks when a decision was replaced or rolled back; confidence scoring (high/medium/low) on every decision and learning
Cross-host ingestion — Claude, Codex, Grok, omp, Pi, and supplied-text JCode write ambient text through recall capture. OpenCode keeps its drop-and-batch path. One database remains searchable from every connected host
Library of Alexandria — Automatic-capture LoA from session extract (importance 6, excluded from reserved L1 LoA slots). Curated LoA from recall loa / dump via the fabric Extractor (extract_wisdom); default importance 8, reserved L1 slots. Optional per-path Extractor config: architecture
TELOS integration (PAI users) — RecallTelosSync.ts auto-imports your TELOS framework files (goals, mission, projects, strategies) from PAI's USER/TELOS/ directory on every session start. Changes are detected by mtime; unchanged files are skipped. Manual import: recall telos import --yes
Breadcrumbs, decisions, learnings — three structured record types for non-session memory, addable from CLI (recall add), MCP (memory_add), or the do-recall-add agent skill
Codebase scouting — /do-recall-scout [focus] produces a memory-first scout report (repo map, key paths, tests, risks, next steps) for orienting in an unfamiliar repo, with a strict no-secrets boundary and chat-only-by-default output
Benchmark harness — recall benchmark run B measures wake-up context efficiency against locked baselines so regressions are visible
Onboarding — recall onboard runs a 7-question interview that writes your L0 identity file
v2 is 51% smaller than v1 on this corpus. CLAUDE.md is hand-written static context; Recall is auto-extracted dynamic memory — the two are complementary, not competitors. Numbers scale with your own DB and L0 identity; reproduce with recall benchmark run B. Methodology and caveats live in docs/benchmarks/README.md.
CLI at a Glance
recall "kubernetes auth"          # Search your memory
recall onboard                    # Seed your L0 identity tier (one-time)
recall dump "Session Title"       # Save this session
recall add decision "Use X" ...   # Record a decision
recall decision list              # List decisions with status and confidence
recall pin decisions 42           # Pin a record to high importance
recall benchmark run B            # Measure wake-up context efficiency
recall prune                      # Preview stale records for removal
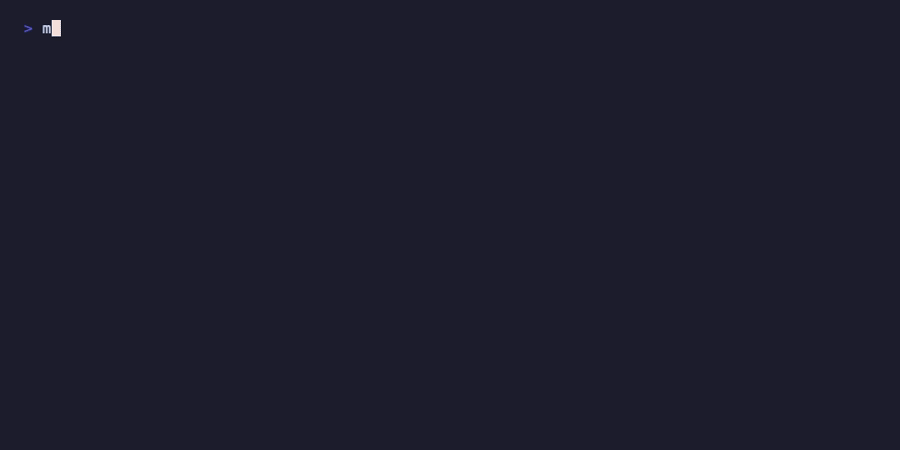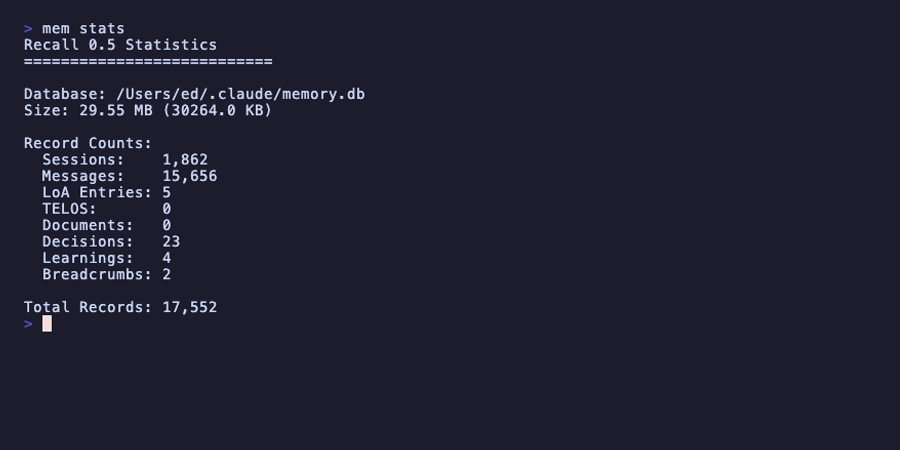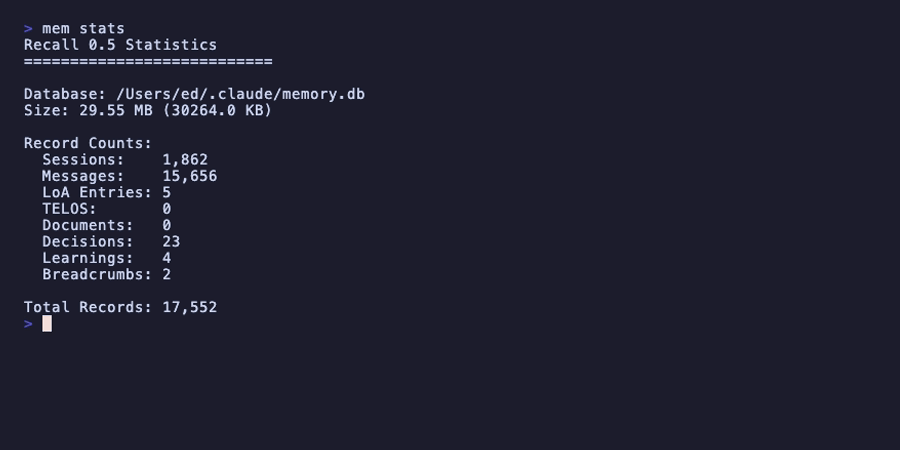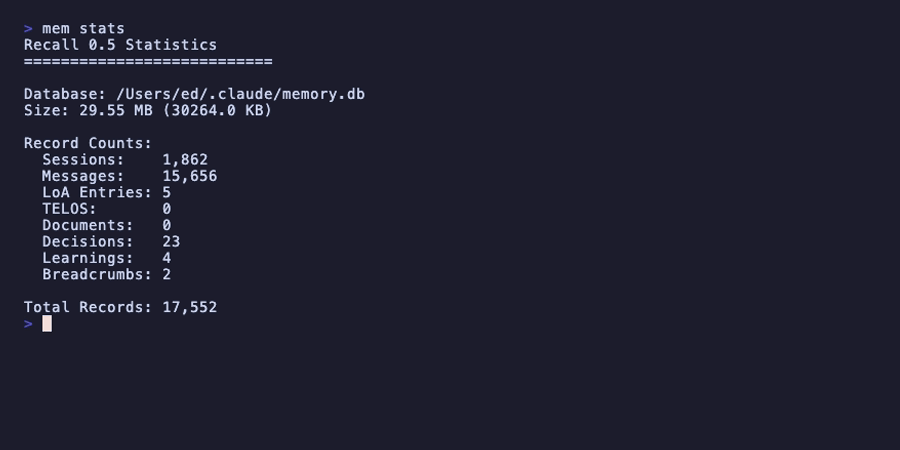
recall stats                      # See what's stored
recall doctor                     # Health check
Cursor sessionStart uses unqualified recall start --format cursor (templates/cursor/). Cursor.app GUI PATH typically lacks ~/.bun/bin, so the hook is a no-op until recall is on that app PATH. CLI Cursor or a shell where recall resolves is fine. Durable GUI PATH / recall start --format cursor accuracy is pending FM-321/327; do not invent a wrapper in the meantime.
Unattended lifecycle writes pass the scrub gate from #50. Agent Skill bodies remain canonical under #228. Installer-owned files follow surgical ownership from #236.
Have an agent you'd like to see supported? Open an issue — Recall is designed to be agent-agnostic, and any host that speaks MCP is a candidate.
Interactive visual map at .agents/atlas/artifacts/2026-06-10-recall-codebase-map.html — generated from the codegraph index, not committed (.agents/ is gitignored)
คัดลอกคอนฟิก stdio สำหรับ Cursor, Claude Desktop, Claude Code หรือ VS Code ได้ในหน้านี้ คอนฟิกนี้ใช้การติดตั้งของผู้เผยแพร่ ไม่ใช่พร็อกซีของ PlugMCP
Recall ต้องใช้ API key ไหม?
ระเบียนนี้ไม่ได้ระบุตัวแปรสภาพแวดล้อมที่จำเป็น
Recall ใช้ทรานสปอร์ตแบบใด?
Recall ทำงานแบบโลคัลผ่าน stdio
Recall ถูกตรวจสอบล่าสุดเมื่อใด?
ตรวจสอบล่าสุดเมื่อ 2026-10-28 Local memory for AI coding agents. Recall remembers your past sessions so your agent doesn't start from scratch every time.