| Graph view | Search highlights | Path finder | Detail panel |
|---|---|---|---|
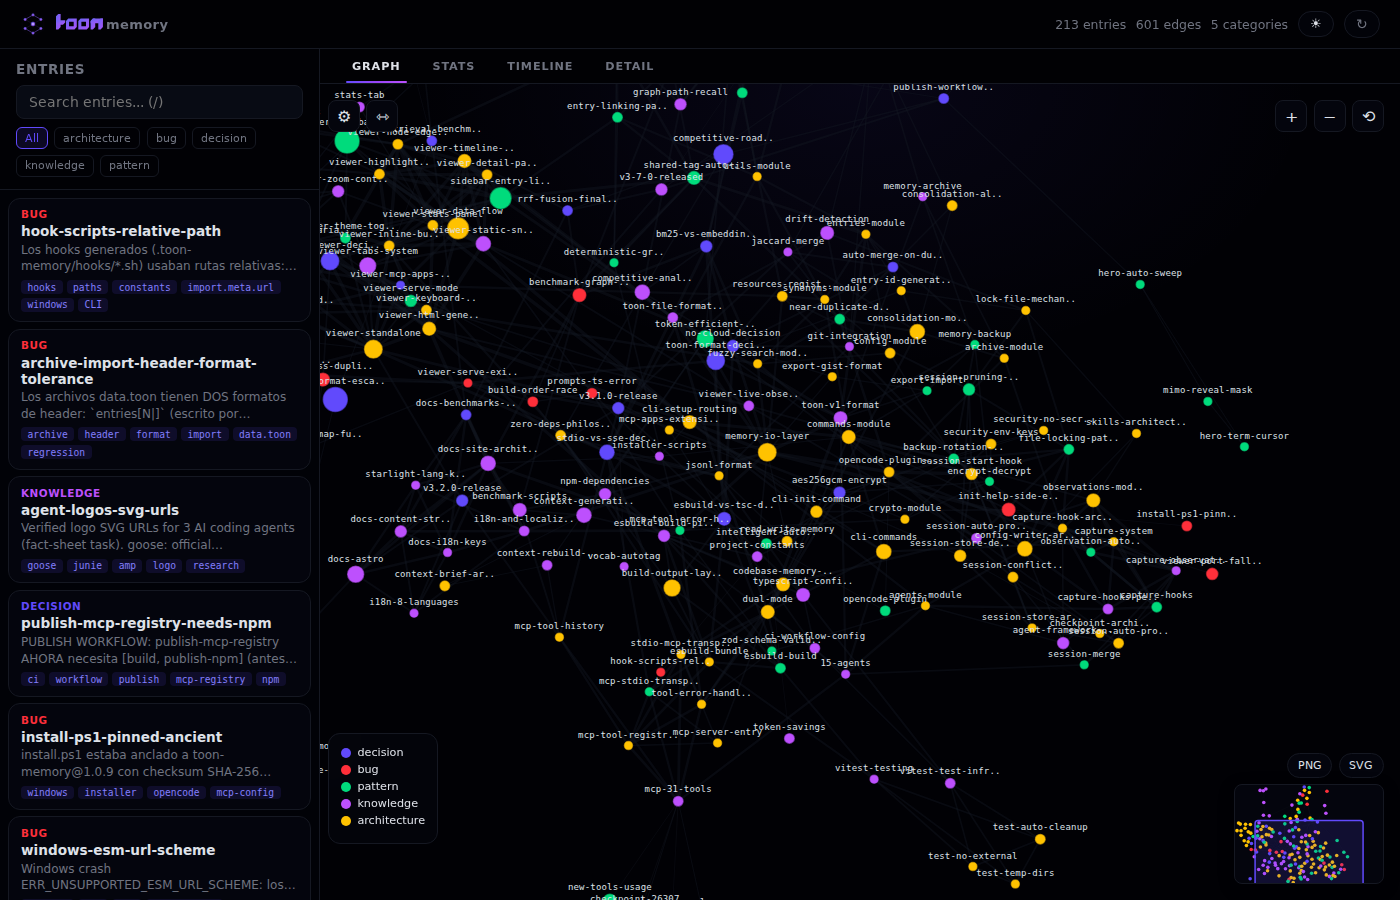 | 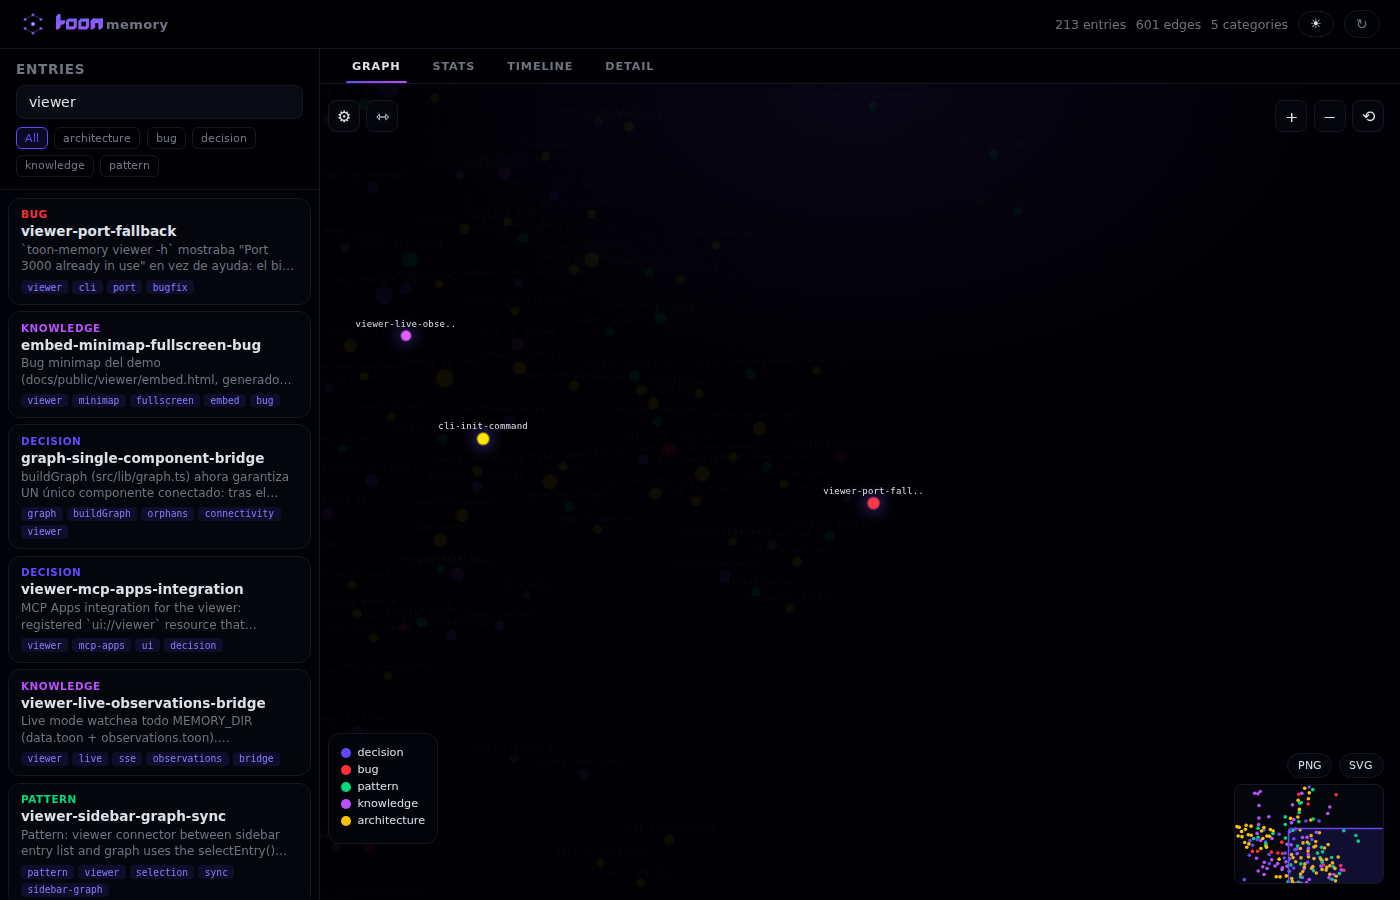 | 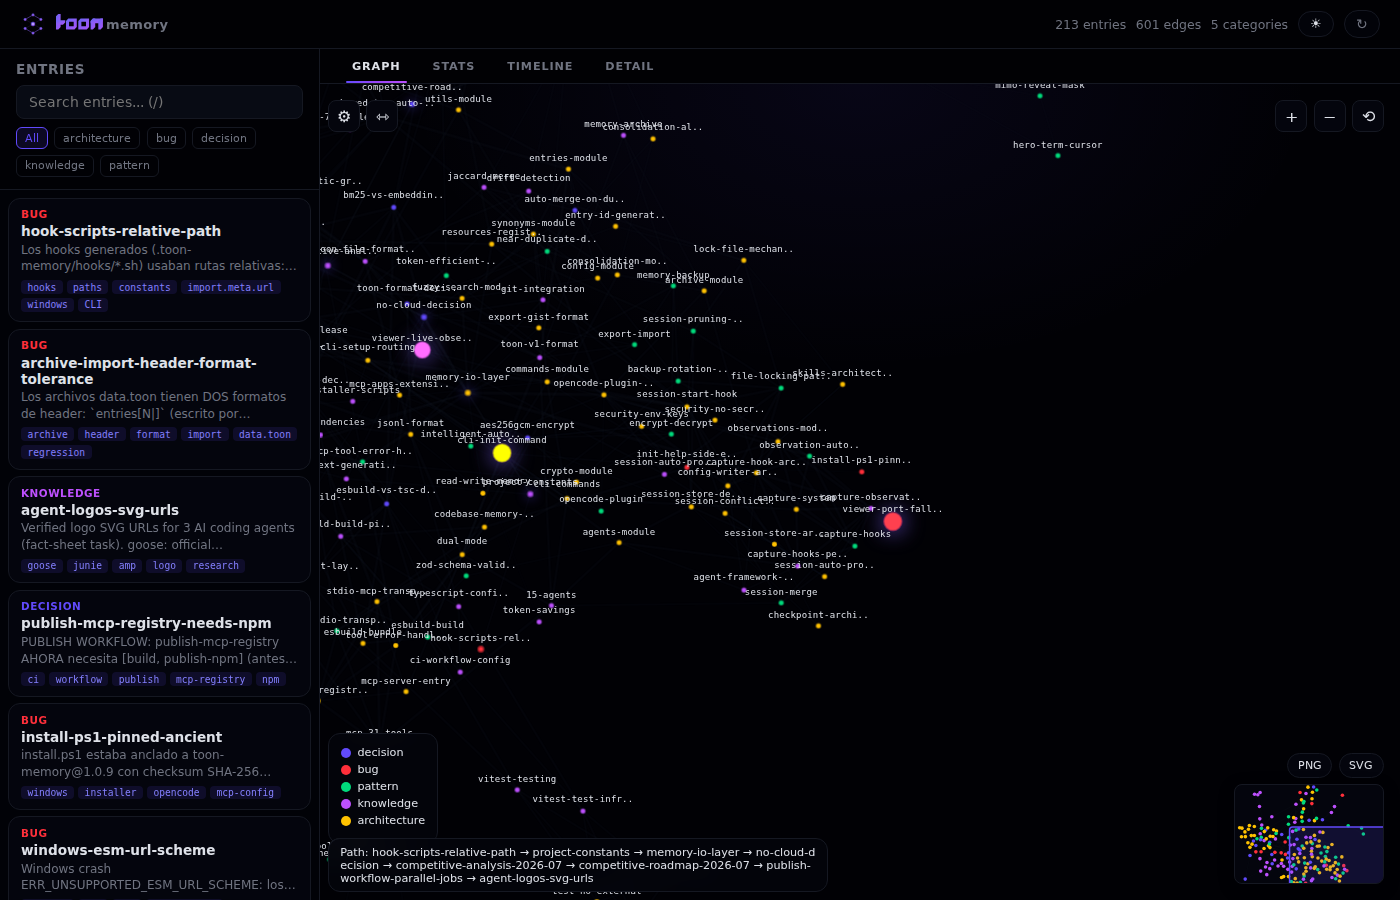 | 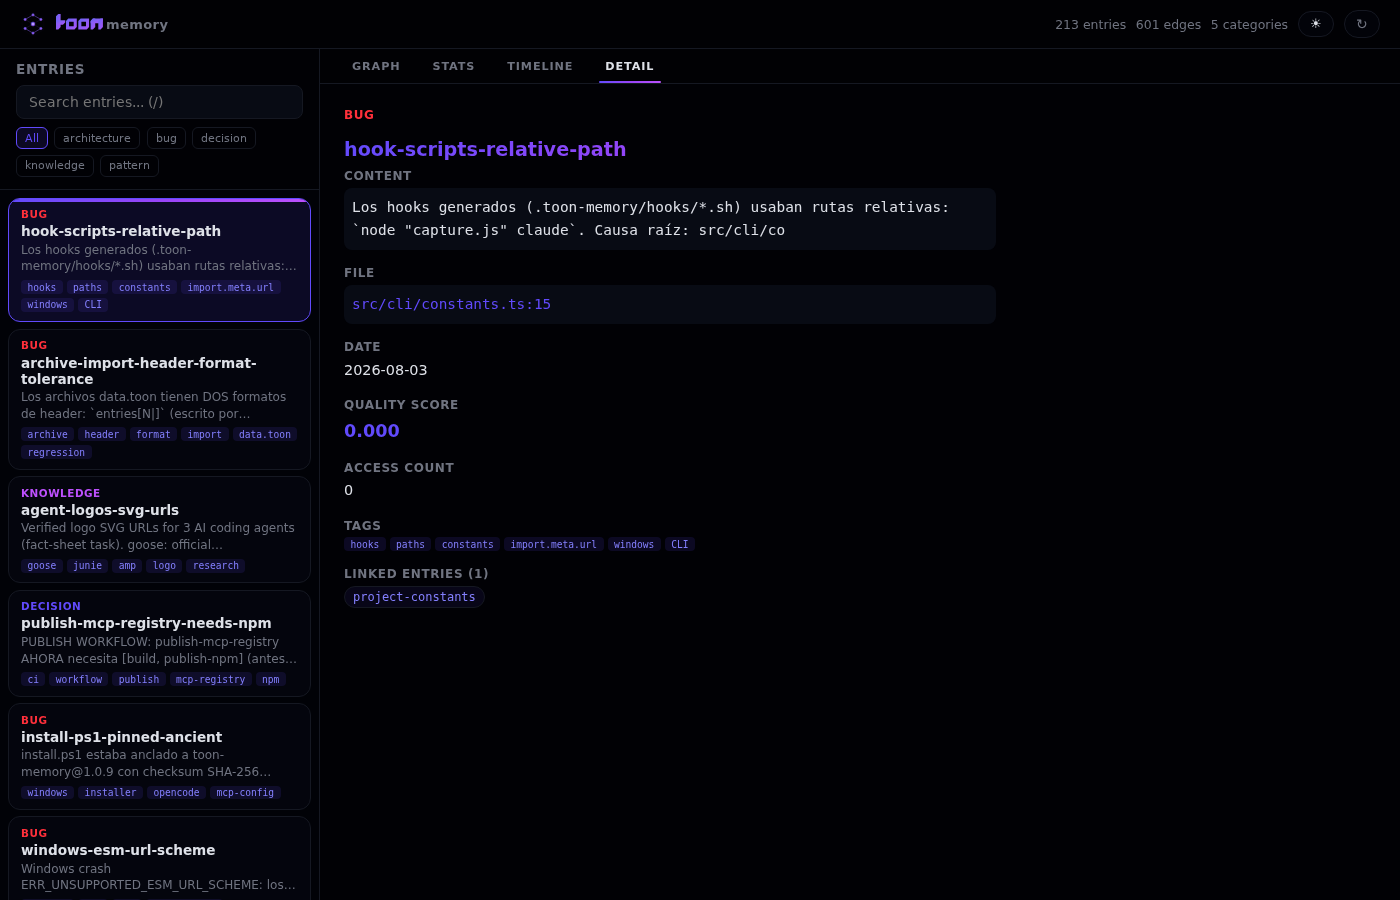 |
Power your agent
คำสั่งของผู้เผยแพร่เอง ไม่ใช่เอนด์พอยต์ของ PlugMCP
Host a copy with our keys and logs.
npx -y [email protected]Claude Code ไม่มีลิงก์ติดตั้งสำหรับคำสั่งแบบโลคัล ให้คัดลอกคำสั่งด้านล่างแล้วรันในเทอร์มินัล
TOON_MEMORY_KEY=<secret> TOON_MEMORY_CAPTURE=<value> TOON_MEMORY_SESSION_ID=<value> TOON_MEMORY_BRANCH=<value> TOON_MEMORY_NO_SESSION=<value> GITHUB_TOKEN=<secret> claude mcp add io.github.luiggival08-toon-memory -- npx -y toon-memory@4.3.5รันในเทอร์มินัล
{ "mcpServers": { "io.github.luiggival08-toon-memory": { "command": "npx", "args": [ "-y", "[email protected]" ], "env": { "TOON_MEMORY_KEY": "<secret>", "TOON_MEMORY_CAPTURE": "<value>", "TOON_MEMORY_SESSION_ID": "<value>", "TOON_MEMORY_BRANCH": "<value>", "TOON_MEMORY_NO_SESSION": "<value>", "GITHUB_TOKEN": "<secret>" } } }}claude_desktop_config.json
URL แบบรีโมตหรือคำสั่งบนเครื่องของคุณ? การติดตั้งสองแบบต่างกันอย่างไร
รันบน PlugMCP
A new server you create. It is not this listing's official endpoint. Use the publisher install when you want their URL and their credentials.
เปิดThe Continuity Layer for AI Agents — AI agents shouldn't have to relearn your project every session.
Ever had that feeling where your AI agent forgets everything from yesterday's session? You explain the same architecture decision for the third time, and it still suggests the approach you already rejected?
toon-memory fixes this. It's the Continuity Layer for AI Agents — a lightweight system that preserves your project's knowledge, decisions, and conventions across sessions, so every session starts where the last one ended. Fully local and private, over MCP — no cloud, no server.
Read How toon-memory Makes Your AI Agent Smarter to see a real-world demo of persistent memory in action.
memory_smart_recall (unified recall with session bias), memory_sessions for multi-session coordination, context_* tools for one-call context generation (briefing, diff, focus, health audit, export), memory_compress (LLM-powered compression), memory_consolidate (deterministic dedup/merge/cleanup), memory_primer (auto-injected context), memory_merge_sessions (cross-session merge), memory_pin/memory_unpin (pin important entries with priority 1-5), memory_checkpoint (session snapshot with 7d TTL), memory_search (unified search with tag filters + session bias), memory_tag (batch tag operations), memory_export_gist/memory_import_gist (GitHub Gist sync), memory_secret (encrypted secrets vault), memory_export_global/memory_import_global (cross-project conventions), memory_forget (soft/hard delete, restore, supersede), memory_reflect (staleness/quality reflection), and memory_promote (auto-promote low-confidence drafts).toon-memory/memory/ to .gitignorelinks/[[key]] refs; memory_recall can expand a relationship-aware subgraph for more precise, lower-token recall (no embeddings, no LLM)memory_recall({ compact: true }) returns numeric-indexed entries, drops id/date/file, renders graph edges as ->2, and truncates graph neighbors to snippetstoon-memory init scans package.json/Cargo.toml/requirements.txt/go.mod and writes a project vocabulary so entries mentioning a dependency get auto-tagged with itmemory_smart_recall combines BM25 + graph + decay + quality in one call; the LLM calls this at the start of every taskkey merges attributes (union of tags, max confidence, latest date, combined links) instead of overwritingmemory_compress uses AI to summarize long entries; memory_consolidate(mode: "low-quality") does batch cleanup deterministicallymemory_merge_sessions merges observations across parallel sessions for a filememory_export_gist and memory_import_gist sync memory entries via GitHub Gist (zero dependencies)config.verbatim preserves original entries instead of overwriting on savecontext_generate (full briefing), context_diff (incremental), context_focus (targeted), context_health (audit), context_export (markdown) — each replaces 5-6 manual tool calls. Zero LLM, pure deterministic aggregationsystemPrimer(), showing top 5 memories for instant contextpath_scope); recall filters by scope automaticallybudget: "tiny" (key+1 line, ~50 tokens), "normal" (compact with tags/edges), "deep" (all fields with origin/scope/status). Backward compatible with compact: truehuman, agent, inferred); human assertions get a quality boostmemory_forget soft-deletes by default (sets status=obsolete). Restore with memory_forget(key, action: "restore"), hide with action: "soft", permanent removal via action: "hard"context_health now detects missing-evidence (path_scope without file) and stale-claims (overlapping content in same category)superseded_by, supersedes, relates), written as type:key in the graph. Explicit links become relates:key, so you can tell how entries are related, not just that they arek = clamp(3..60, round(sqrt(n))). Benchmark (8 gold queries): nDCG 0.776, MRR 0.917 — exact parity with the previous linear scoring. Pass rrf: false to fall backmemory_reflect ranks entries by staleness, quality, and over-connection to surface what needs attention or cleanup. Deterministic, zero LLMmemory_forget(key, action: "supersede", new_key) marks an entry as replaced by a newer one (superseded_by link + supersededOn date). memory_recall({ as_of }) re-includes old entries for point-in-time queries before their supersessionmemory_promote promotes low-confidence drafts to active entries deterministically (threshold 0.65, Jaccard dedup), with dryRun by defaultmemory_recall/memory_smart_recall accept explain: true and append a deterministic reason line to every returned entry (↳ 100% relevance · used 14× · used today · importance HIGH) — why it was retrieved, no LLMbudget_tokens caps the recall output by estimated token count; entries accumulate greedily and the tail that would exceed the budget is dropped (0 = no limit)memory_consolidate(mode: "versions") detects entries describing the same subject at different library versions (e.g. "Use React 18" vs "Use React 19") and retires the older ones in favor of the newestwarning category for "do NOT do this" facts; warning entries get a recall boost so the agent sees the landmines before repeating thempath_scope matches the current filememory_remember({ importance }) sets critical, high, medium, or low. Critical decisions surface first (+0.3), low notes stay out of the way (−0.1); empty = auto (recency + frequency). Re-saving keeps the higher levelmemory_remember save is annotated with an evidence level: verified when its referenced file exists on disk, unverified when it doesn't, conflict when it overlaps a warning or critical/high decision. Conflicts get a +0.15 recall boost (verified +0.03, unverified −0.02) and a ⚠️ CONTRADICTION warning on save — but never block the writememory_secret stores credentials in an encrypted sidecar (secrets.toon, AES-256-GCM) so data.toon stays a readable open format while sensitive values never hit plaintextmemory_export_global writes project memory to ~/.toon-memory/memory/global.toon; memory_import_global pulls cross-project conventions back with a one-shot, deterministic, offline merge (never a live dual source)@inquirer/checkbox/select/confirm); the MCP SDK, zod, and the TOON parser are bundled into the shipped binary — a single npm i -g downloads ~1 MB (was ~14 MB) and lands ~4.4 MB on disk (was ~33 MB)# macOS / Linux
curl -fsSL https://raw.githubusercontent.com/LuiggiVal08/toon-memory/main/install.sh | sh
# Windows (PowerShell)
irm https://raw.githubusercontent.com/LuiggiVal08/toon-memory/main/install.ps1 | iex
# Or with npm (any platform)
npm i -g toon-memory
Tip: The npm install is the most reliable method. The curl/irm scripts are convenience wrappers.
Size: A bare
npm i -g toon-memorydownloads ~1 MB and installs ~4.4 MB — three tiny prompt packages; everything else (MCP SDK, zod, TOON parser) ships bundled.
# Interactive installer — detects agents and configures MCP
npx toon-memory
The installer will:
That's it! In your next agent session, try:
memory_stats      # See what's in memory
memory_recall     # Search memory before reading files
memory_remember   # Save important decisions
Tip: Always run
memory_recallat the start of a session. Your agent will have context from previous sessions instantly.
Add to .cursor/mcp.json:
{
  "mcpServers": {
    "toon-memory": {
      "command": "npx",
      "args": ["-y", "toon-memory", "mcp"]
    }
  }
}
Add to claude_desktop_config.json:
{
  "mcpServers": {
    "toon-memory": {
      "command": "npx",
      "args": ["-y", "toon-memory", "mcp"]
    }
  }
}
Add to ~/.codeium/windsurf/mcp_config.json:
{
  "mcpServers": {
    "toon-memory": {
      "command": "npx",
      "args": ["-y", "toon-memory", "mcp"]
    }
  }
}
Tip: You can configure toon-memory for multiple agents at the same time. Each agent gets the same shared memory file at
.toon-memory/memory/.
Memory is also exposed as MCP resources for direct context reading:
memory_remember({
  category: "decision",
  key: "use-zod",
  content: "Use Zod for validation — simpler than Joi, better TS support",
  file: "src/types.ts",
  tags: "validation;types"
})
// 🧠 Guardado: decision/use-zod (a1b2c3d4)
// Quality score: 0.65 (2 tags, detailed content)
// 🔗 Entradas relacionadas:
//   [pattern] zod-schemas — Shared Zod schemas for API validation
Tip: Use descriptive keys like
use-zodinstead of vague ones likevalidation. Your agent searches by key and content, so specificity helps. Saving with the same key auto-merges (union of tags, max confidence).
memory_remember({
  category: "knowledge",
  key: "sprint-deadline",
  content: "Sprint ends July 18, feature freeze is July 16",
  ttl: "7d"
})
// 🧠 Guardado: knowledge/sprint-deadline (x1y2z3w4)
// ⏰ TTL: 2026-07-19
// Quality score is calculated automatically.
Tip: Use TTL for temporary context like deadlines, sprint info, or time-sensitive notes. Entries with expired TTL are automatically filtered from search results.
memory_remember({
  category: "decision",
  key: "db-choice",
  content: "We chose Postgres over MySQL — JSONB for flexible schemas, better extension ecosystem",
  importance: "critical"
})
// 🧠 Guardado: decision/db-choice (a1b2c3d4)
// 🎯 Importance: critical (+0.3 boost) — surfaces above routine entries
Tip: Mark foundational decisions
criticalso they always rank near the top of recall.importanceacceptscritical,high,medium, orlow; leave it empty to let the system rank by recency and frequency automatically.
memory_remember({
  category: "bug",
  key: "redis-connection-timeout",
  content: "Redis connection timeout in production, increased pool size"
  // tags left empty — auto-inferred from content
})
// 🧠 Guardado: bug/redis-connection-timeout (a1b2c3d4)
// 🏷️ Tags inferidos: redis
// Quality score is calculated automatically based on inferred tags and content.
Tip: Leave
tagsempty and the system will infer them from your content using a built-in vocabulary of 20+ categories (redis, auth, api, db, security, etc.) plus a project vocabulary derived from your dependencies atinittime. So if your project depends onredis, any entry mentioning "redis" gets auto-taggedredis.
memory_recall({ query: "redis" })
// [bug] redis-pool-fix (i9j0k1l2)
//   Added max_connections=20
//   File: redis.ts | Tags: redis;fix | Date: 2026-07-10
Tip: Search before you read files. This saves tokens and gives your agent context it wouldn't get from code alone. Quality-weighted ranking ensures the most useful entries surface first. Or use
memory_smart_recallfor a more comprehensive result.
memory_recall({
  query: "redis",
  from_date: "2026-07-01",
  to_date: "2026-07-31"
})
Tip: Use date filters when you remember roughly when something happened but not exactly what. Quality-weighted ranking still applies.
memory_archive()
// 📦 Archivadas 5 entradas antiguas
// 📋 Quedan 42 entradas activas
Tip: Run this periodically to keep memory lean. Archived entries are still searchable via
memory_recallwith date filters. Entries with expired TTL are also archived automatically. Low-quality entries get lower recall priority. Low-quality entries get lower recall priority.
memory_diff({ since: "24h" })
// 📋 Cambios desde 2026-07-11:
//
// ➕ Nuevas (2):
//   [decision] use-zod (a1b2c3d4)
//     Use Zod for validation
//   [bug] redis-timeout (e5f6g7h8)
//     Redis connection timeout fix
Tip: Use
memory_diffat the start of a session to see what your agent learned since you last worked on the project. New entries include quality scores. New entries include quality scores.
memory_suggest({ context: "redis cache configuration" })
// 🔍 Sugerencias para "redis cache configuration":
//
// [decision] redis-cache-config (a1b2c3d4)
//   Redis cache layer for session storage
//   File: src/cache.ts | Tags: redis;cache | Date: 2026-07-10
//
// [bug] redis-pool-fix (i9j0k1l2)
//   Added max_connections=20
//   File: redis.ts | Tags: redis;fix | Date: 2026-07-10
Tip: Use
memory_suggestwhen you need context about a topic but aren't sure what to search for. Or usememory_smart_recallfor a more comprehensive result.
memory_smart_recall({ intent: "diseño de base de datos para backend" })
// [1] decision/use-postgres
//   Choose Postgres for ACID compliance and JSON support
//   tags: db;decision · edges: ->2
//
// [2] pattern/db-migrations
//   Use sequential migration files, never edit committed ones
//   tags: db;pattern · edges: ->1
//
// [3] bug/redis-timeout
//   Redis connection timeout — increased pool to 20
//   tags: redis;bug
Tip: Use
memory_smart_recallat the START of every task. It combines BM25 + graph + decay + quality in one call — no need to guess what to search for.
memory_recall({ query: "redis", explain: true })
// [decision] redis-cache-config (a1b2c3d4)
//   Redis cache layer for session storage
//   File: src/cache.ts | Tags: redis;cache | Date: 2026-07-10
//   ↳ 92% relevance · used 14× · used today · importance HIGH
The ↳ reason line is deterministic (relevance %, access count, last-used, importance) — no LLM involved. Use explain: true when you want to know why the agent was shown those entries.
budget_tokensmemory_recall({ query: "redis", budget_tokens: 300 })
// Entries accumulate greedily; the tail that would exceed the estimate is dropped.
// budget_tokens: 0 (default) = no limit.
Tip: Combine
budget_tokenswithbudget: "deep"for a context window that stays inside a hard token ceiling regardless of memory size.
context_generate({})
// # Project Briefing (full)
//
// ## Project
// - Name: my-app
// - Root: /path/to/project
// - Package Manager: npm
// - TypeScript: ✓ (v5.3)
//
// ## Git Status
// - Branch: main
// - 3 uncommitted, 0 untracked
//
// ## Memory (42 entries, 12 patterns, 8 bugs)
// [1] decision/use-postgres
//   Choose Postgres for ACID compliance
//   tags: db;decision
//
// ## Sessions
// - egraterol (main, 2m ago): 42 files touched
Tip: Use
context_generateat the start of a session to get full context in one call. Replaces 5-6 separate tool calls.
context_health({})
// # Memory Health (score: 87/100)
//
// ## Summary
// - 42 entries (12 patterns, 8 bugs, 15 decisions, 7 knowledge)
// - 65.3% average quality
//
// ## Issues (3)
// - Orphan link: pattern/db-migrations → pattern/db-seed (key not found)
// - Duplicate: [bug] redis-pool-fix has identical content
// - Expired TTL: [knowledge] sprint-deadline (expired 2026-07-20)
//
// ## Stale Files (1)
// - src/legacy.ts (deleted, 2 refs)
Tip: Run
context_healthwhen memory feels cluttered. Shows orphan links, duplicates, expired TTL entries, broken file references, missing-evidence entries (path_scope without file), and stale claims (overlapping content).
When you save with the same key, attributes are merged instead of overwritten:
// First save
memory_remember({
  category: "decision",
  key: "use-zod",
  content: "Use Zod for validation",
  tags: "types"
})
// 🧠 Guardado: decision/use-zod (a1b2c3d4)

// Later save with same key — merges automatically
memory_remember({
  category: "decision",
  key: "use-zod",
  content: "Use Zod for validation — also handles API response parsing",
  tags: "types;api"
})
// 🧠 Actualizado: decision/use-zod (a1b2c3d4)
// 🔗 Merge: tags combinados, fecha y links actualizados
// Tags now: "types;api" (union of both)
Tip: Use descriptive, stable keys. The same key = merge, different key = new entry.
Every entry gets an automatic quality score (0–1) based on structure:
High-quality entries surface first in recall. Check quality with memory_stats:
memory_stats()
// ...
// Calidad promedio: 0.58 (12 con score)
Each entry tracks how reliable the information is:
Confidence is preserved on merge (max of both entries).
The System Primer is an auto-generated knowledge map exposed as an MCP resource. Agents load it at session start for instant context:
// Exposed as toon://memory/summaries
// Auto-regenerates on every read
// Contains: top entries, categories, patterns
Tip: Add
toon://memory/summariesto your agent's system prompt for instant context at session start.
// First, set TOON_MEMORY_KEY in your environment (or .env file):
// export TOON_MEMORY_KEY="your-secret-key-here"

memory_encrypt()
// 🔐 Encriptación habilitada
Warning: The encryption key must be set via
TOON_MEMORY_KEYenv var before encrypting. Save it somewhere safe — if you lose it, your memory data is gone forever. Quality scores and confidence are preserved through encryption.
When you run several AI agent sessions in parallel (e.g. three OpenCode sessions on the same repo at once), they can accidentally clobber each other's work. toon-memory ships with memory_sessions, a file-based coordination tool that lets every session see what its siblings are doing — with no server, no network, and no LLM calls.
SessionStart hook writes a heartbeat file for the session at .toon-memory/memory/sessions/<id>.json. Each process writes only its own file, so there's no lock contention.memory_sessions toolmemory_sessions({ conflictsOnly: false })
// 🧭 Sesiones activas (2) — ventana 30 min:
//
// • opencode @ feature/auth (tú)
// id: a1b2c3d4
// hace 2 min
// Archivos:
// • src/auth.ts
//
// • claude @ feature/db
// id: e5f6g7h8
// hace 9 min
// • src/db.ts
//
// 🔥 Conflictos suaves (1):
// ⚠️ src/types.ts ↔ opencode @ feature/auth, claude @ feature/db
conflictsOnly: true to skip the session list and show only soft conflicts:
memory_sessions({ conflictsOnly: true })
// 🔥 Conflictos suaves (1):
//
// ⚠️ src/types.ts
//    ↔ opencode @ feature/auth (a1b2c3d4), claude @ feature/db (e5f6g7h8)
SessionStart hook already prints the other active sessions and any soft conflicts.memory_smart_recall({ intent: "what I'm working on" }) to get full context (memory + graph + quality).memory_sessions() to see the full picture (branches, files, last-seen) and memory_sessions({ conflictsOnly: true }) if you only care about clashes.Tip: This is purely local and lock-free — safe to run as often as you like. Combine it with
memory_smart_recall({ intent: "project context" })at session start for both cross-session memory and cross-session presence. The system primer (MCP resource) also provides instant context.
When your memory grows, a flat keyword search can return either too much (every match) or the wrong context (no relationships). toon-memory can treat memory as a lightweight knowledge graph so recall returns the right entries with fewer tokens. Combined with quality scoring, the most useful entries surface first.
It's fully deterministic and offline — no embeddings, no vector DB, no LLM, no server. Edges come from two sources:
links — keys you declare when saving an entry.[[key]] refs — any [[some-key]] mention inside the content.memory_remember stores links on the entry (space- or ;-separated keys). Quality score is calculated automatically.memory_recall({ mode: "graph" }) finds keyword matches (seeds), then expands the ego-subgraph up to hops (1 or 2) along the edges.limit, default 6) → smaller, more precise context for the agent. Or use memory_smart_recall for a unified call.memory_remember({
category: "decision",
key: "risk-engine-priority",
content: "The engine prioritizes risk over speed (see [[risk-spec]]).",
file: "spec.md:10",
tags: "risk;spec",
links: "engine-arch" // explicit edge to another entry
})
// 🧠 Guardado: decision/risk-engine-priority (a1b2c3d4)
// Quality score is calculated automatically based on tags, links, and content detail.
memory_recall({ query: "riesgo", mode: "graph", hops: 2 })
// [decision] risk-engine-priority (a1b2c3d4)
//   The engine prioritizes risk over speed (see [[risk-spec]]).
//   File: spec.md:10 | Tags: risk;spec | Date: 2026-07-01
//   links: engine-arch
//
// [knowledge] risk-spec (a2b3c4d5)
//   Risk specification for the engine.
//   links: risk-engine-priority;engine-arch
//
// [pattern] engine-arch (e6f7g8h9)
//   Engine architecture.
//   links: risk-spec
Tip: Use
mode: "graph"when a decision ripples across several entries (architecture, specs, related bugs). For isolated facts, the defaultflatmode is enough. Or usememory_smart_recallwhich combines graph + BM25 + quality automatically.
compact)When every token counts, pass compact: true to get a denser output:
memory_recall({ query: "riesgo", mode: "graph", hops: 2, compact: true })
// [1] decision/risk-engine-priority
//   The engine prioritizes risk over speed (see [[risk-spec]]).
//   tags: risk;spec · edges: ->2, ->3
//
// [2] knowledge/risk-spec
//   Risk specification for the engine.
//   tags: risk · edges: ->1
//
// [3] pattern/engine-arch
//   Engine architecture.
//   tags: engine · edges: ->1
How compact changes the output:
[1], [2], …) in score order.id, date, and file are dropped — only tags is kept.graph mode, edges render as ->2 (numeric, not key names)..toon file is never mutated — compact only reshapes the response.Tip: Combine
compact: truewithmode: "graph"for the smallest possible context window when recalling from a large, interconnected memory. For proactive/background recall, usebudget: "tiny"which returns just the key + one line (~50 tokens). Or just usememory_smart_recallwhich does this automatically.
Recall is deterministic and offline (no embeddings, no LLM). Each candidate entry gets a combined score:
id + category + key + content + file + tags + quality + confidence.d hops from a seed are multiplied by 0.5^d, so distant context ranks below nearby context.In graph mode, recall seeds on keyword matches, expands the ego-subgraph up to hops, and returns the top limit (default 6) by combined score. memory_smart_recall combines all these signals in one call.
On toon-memory init, the CLI scans your dependency manifests and writes a vocab table into .toon-memory/memory/config.json:
{
  "vocab": {
    "react": ["react"],
    "zod": ["zod"],
    "redis": ["redis"]
  }
}
memory_remember then matches new entries against this vocabulary on top of the built-in one, so mentioning a dependency in your content auto-attaches its tag. More tags = higher quality score. Supported manifests: package.json, Cargo.toml, requirements.txt, pyproject.toml, go.mod.
Tip: Re-run
toon-memory initafter adding major dependencies to refresh the vocabulary. Thevocabkey is merged (never clobbered) with theencrypted/captureflags inconfig.json. More tags = higher quality score.
Visualize your memory as an interactive force-directed graph. See entries, their connections, categories, and access patterns at a glance.
npx toon-memory viewer          # Start HTTP server + open browser
npx toon-memory viewer --port 3001  # Custom port
npx toon-memory viewer --export     # Save as static HTML
Once open, press r in the terminal to reload from disk, or r / ↻ in the browser to refresh the page.
Call memory_visualize in any MCP Apps–compatible host to render the graph inline — no server needed. The viewer appears as an interactive panel inside the chat interface.
| Graph view | Search highlights | Path finder | Detail panel |
|---|---|---|---|
| | | |
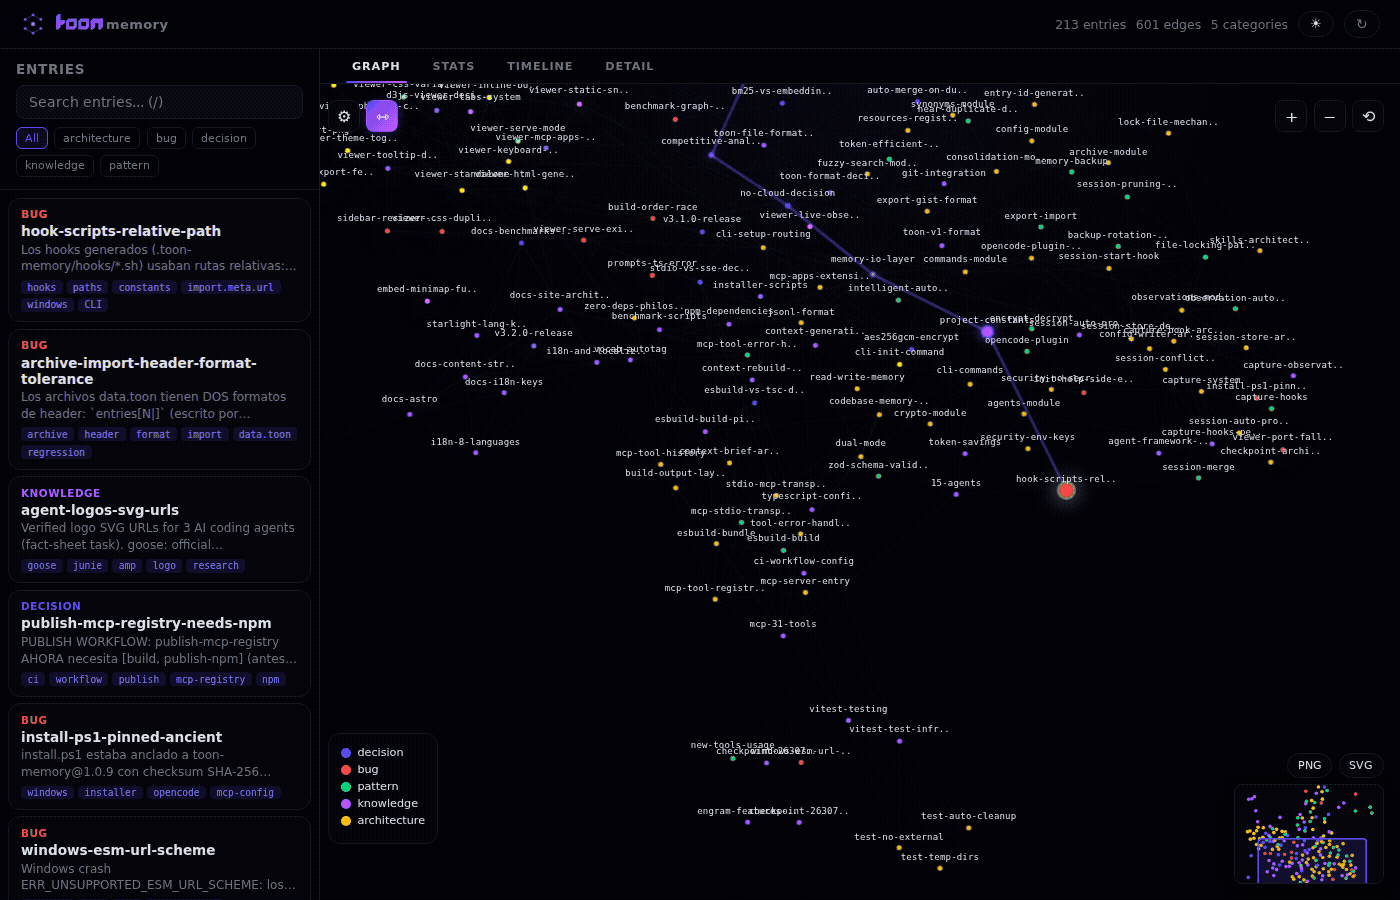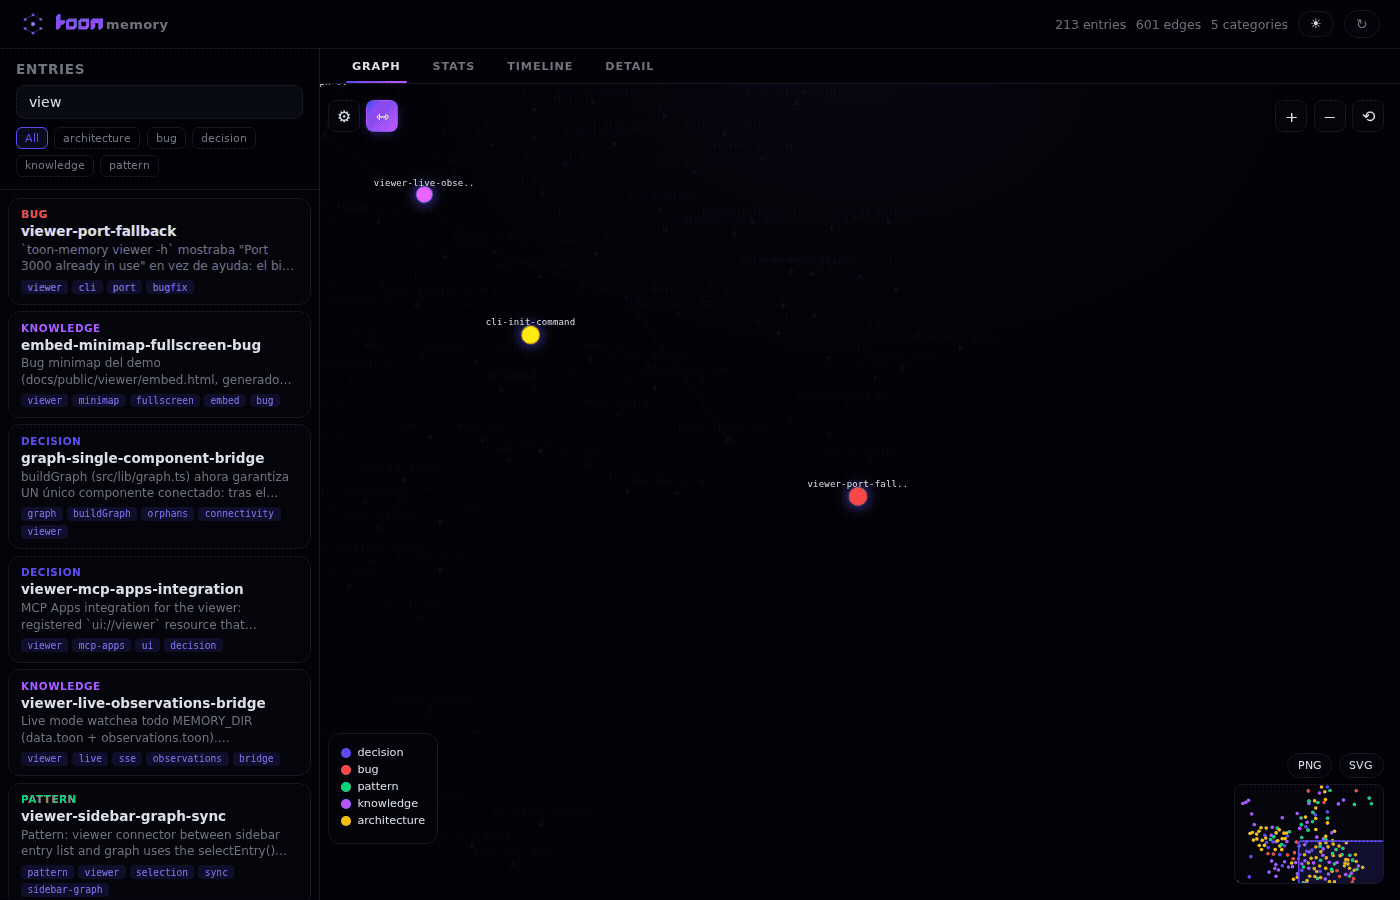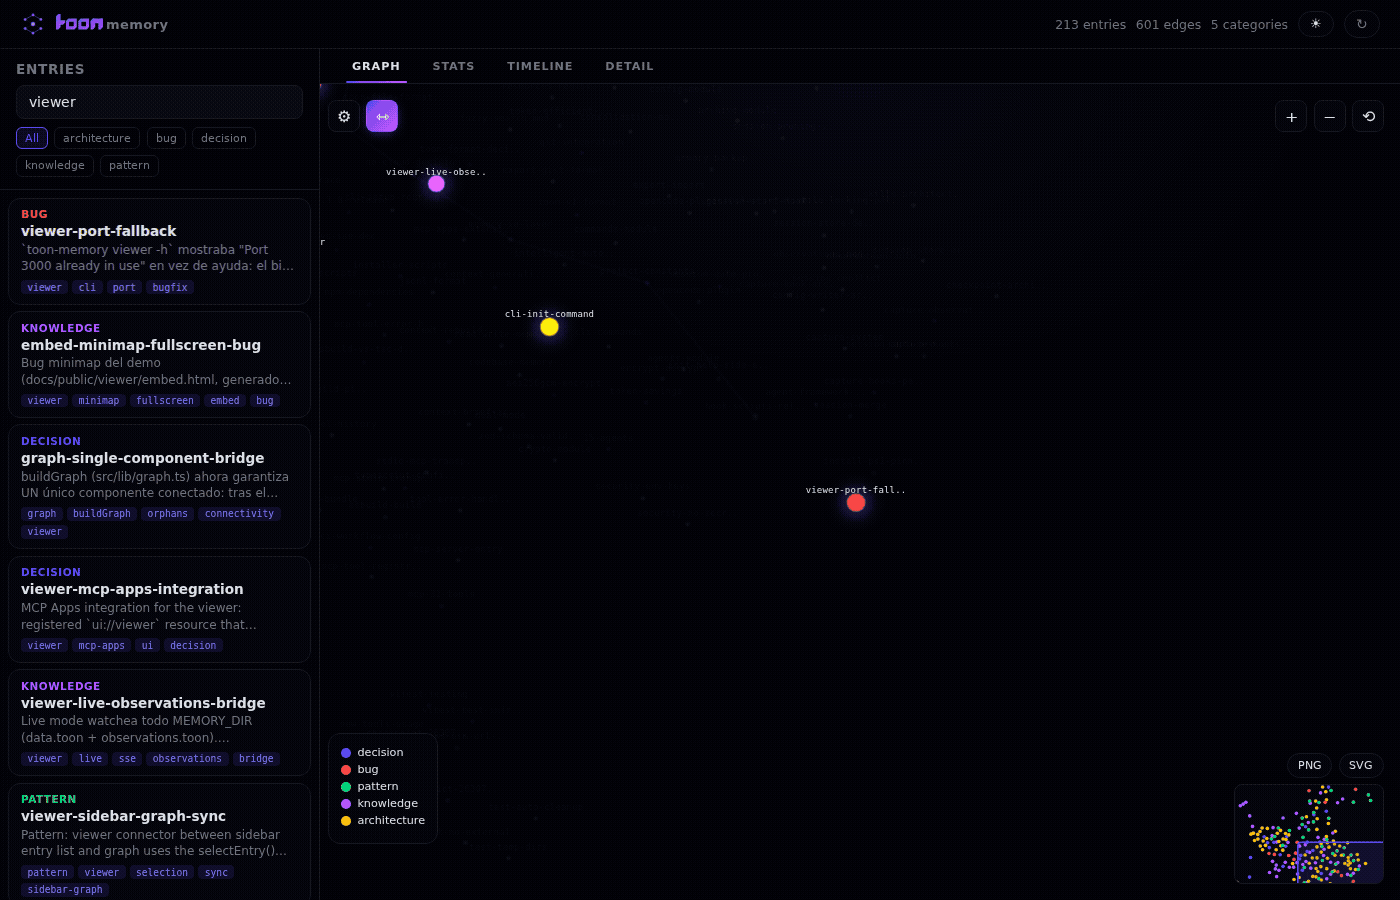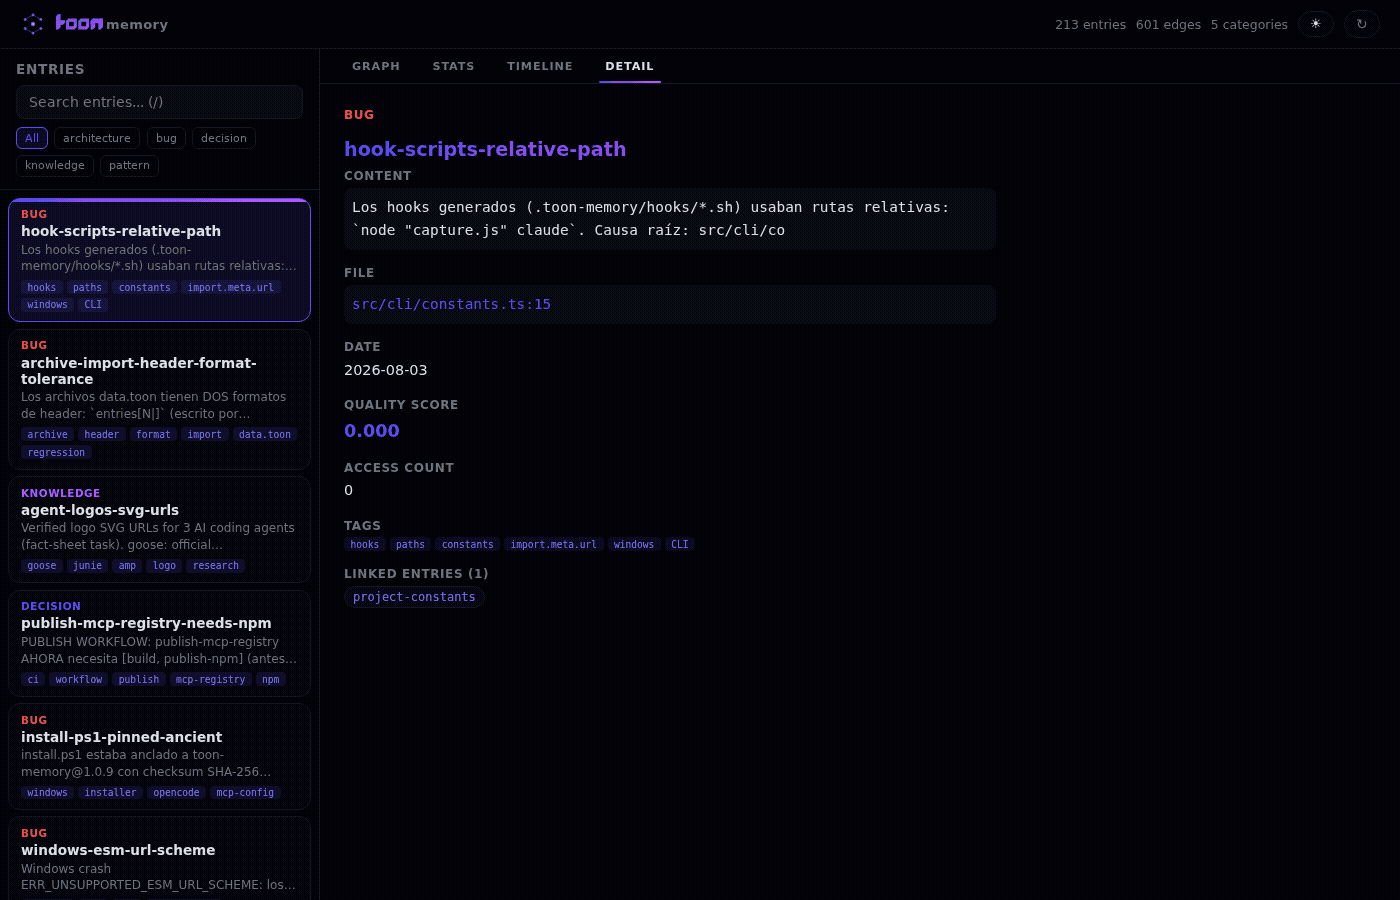
npm run capture:viewer
Requires Playwright (npx playwright install chromium) and ffmpeg.
Here are some patterns that work well with toon-memory:
At the beginning of every new session, run:
memory_smart_recall({ intent: "what I was working on" })
This gives your agent instant context about what happened before — combining BM25, graph, quality, and decay in one call.
Before closing a session, save anything important:
memory_remember({
  category: "decision",
  key: "auth-approach",
  content: "Chose JWT over sessions — stateless, works across microservices",
  file: "src/auth.ts",
  tags: "auth;architecture"
})
The entry automatically gets a quality score based on its structure (tags, content detail, links).
Tip: Don't overthink it. If it's something your future self (or agent) would want to know, save it. Detailed entries with specific tags score higher in quality.
Use semicolon-separated tags for easy filtering:
tags: "redis;performance;fix"
tags: "auth;jwt;security"
tags: "api;rest;versioning"
Tip: Keep tags short and consistent. They're not hashtags — they're search filters. More specific tags = higher quality score.
Run memory_archive() monthly to move old entries to the archive. Run memory_stats() to check the size and quality distribution. Low-quality entries (vague content, no tags) get lower recall priority automatically. Use memory_consolidate to merge duplicates and mode: "versions" to retire notes superseded by newer library versions.
npx toon-memory              # Interactive installer
npx toon-memory init         # Quick setup (no prompts)
npx toon-memory mcp          # Run MCP server directly
npx toon-memory status       # Check installation status
npx toon-memory stats        # View memory statistics
npx toon-memory export       # Export memory to JSON
npx toon-memory import <file> # Import memory from JSON
npx toon-memory viewer       # Open the memory graph viewer (http server)
npx toon-memory viewer --export # Save viewer as static HTML
npx toon-memory viewer --port 3001 # Custom port
npx toon-memory watch [options] # Auto-backup with options
npx toon-memory upgrade      # Update to latest version
npx toon-memory uninstall    # Remove from all agents
$ npx toon-memory stats

🧠 toon-memory stats

📊 Memory Stats
━━━━━━━━━━━━━━━━━━
Total entries: 45
├── decision: 12
├── pattern: 18
├── bug: 8
└── knowledge: 7
Last updated: 2026-07-10
File size: 12.4 KB
Tip: If memory gets too large (100+ entries), consider archiving or removing outdated entries with
memory_forget.
$ npx toon-memory export

🧠 toon-memory export

Exported 45 entries to:
  /path/to/project/toon-memory-export.json
Tip: Export before major refactors. You can always import the backup later if something goes wrong.
$ npx toon-memory import backup.json

🧠 toon-memory import

Imported 3 new entries
Skipped 2 duplicates
Tip: Duplicates are detected by key. If you want to re-import an entry, delete the old one first with
memory_forget.
$ npx toon-memory watch 15 -c -m 20

🧠 toon-memory watch

Watching memory file every 15 minutes...
Max backups: 20
Compression: enabled
Logging: disabled
Press Ctrl+C to stop

📦 Backup #1 created: 2026-07-11T16-00-00-000Z
📦 Backup #2 created: 2026-07-11T16-15-00-000Z
^C
✅ Watch stopped. 2 backups created.
Tip: Watch mode is great for long-running sessions. Use
-cto compress and-m 5to keep only 5 backups.
Watch Options:
npx toon-memory
The installer (requires a terminal) will:
✓ config found) and their supported scope (local/global or solo local)1,3,5), by name (claude,codex), all, Enter for all, or q to quit.toon-memory + agent configs in the repo) or (2) Global (~home configs)agent → scope → path (MCP/plugin/hooks/instrucciones)) and ask ¿Proceder? [Y/n]Sin una terminal (CI/pipes)
npx toon-memoryimprime la ayuda de instalación no interactiva. Usanpx toon-memory init [local|global]para instalar sin preguntas. Unknown commands print usage and exit with an error.
Add to .opencode/opencode.json or ~/.config/opencode/opencode.json:
{
  "mcp": {
    "toon-memory": {
      "type": "local",
      "command": ["npx", "-y", "toon-memory", "mcp"],
      "enabled": true
    }
  }
}
Hooks are delivered via a plugin, not a top-level
hookskey. OpenCode 1.17+ rejects"Unrecognized key: hooks"in its config —toon-memory initwrites.opencode/plugins/toon-memory.tsinstead. Do not addhookstoopencode.json.
Add to .mcp.json (project root):
{
  "mcpServers": {
    "toon-memory": {
      "command": "npx",
      "args": ["-y", "toon-memory", "mcp"]
    }
  }
}
Add to .vscode/mcp.json:
{
  "servers": {
    "toon-memory": {
      "command": "npx",
      "args": ["-y", "toon-memory", "mcp"]
    }
  }
}
Add to .codex/config.toml:
[mcpServers.toon-memory]
command = "npx"
args = ["-y", "toon-memory", "mcp"]
Add to .gemini/settings.json:
{
  "mcpServers": {
    "toon-memory": {
      "command": "npx",
      "args": ["-y", "toon-memory", "mcp"]
    }
  }
}
Add to ~/.config/zed/settings.json:
{
  "mcp_servers": {
    "toon-memory": {
      "command": "npx",
      "args": ["-y", "toon-memory", "mcp"]
    }
  }
}
Tip: Use global config if you want memory for every project. Use project-level config if you only want it for specific projects.
.toon-memory/memory/data.toonversion: 1
entries[3|]{id|category|key|content|file|tags|date|ttl|accessed|links|quality|confidence|lastAccessed|priority|path_scope|origin|status|supersededOn|importance|evidence}:
a1b2c3d4|decision|use-zod|Use Zod for validation|src/types.ts|validation;types|2026-07-10||0||0.65|1.0||0||agent|active|||verified
e5f6g7h8|pattern|pydantic-configs|Project uses Pydantic v2|config.py|python;patterns|2026-07-10||0||0.55|1.0||0||agent|active|||
i9j0k1l2|bug|redis-pool-fix|Added max_connections=20 (see [[use-zod]])|redis.ts|redis;fix|2026-07-10|7d|0|use-zod|0.70|0.9||0||agent|active|||conflict
summaries:
src/services/redis.ts: Redis connection pool with retry logic
.toon-memory/
├── memory/
│   ├── data.toon        # Main memory file
│   ├── archive.toon     # Archived entries (>30 days)
│   ├── config.json      # Encryption settings
│   └── backups/         # Watch mode backups
│       ├── backup-2026-07-11T16-00-00-000Z.toon
│       └── backup-2026-07-11T16-10-00-000Z.toon
└── hooks/
    ├── session-start-claude.sh
    ├── session-start-codex.sh
    ├── session-start-gemini.sh
    └── session-start-antigravity.sh
TOON (Token-Oriented Object Notation) is designed for LLMs:
Measured with gpt-tokenizer (cl100k_base) over 16 representative memory entries — see scripts/benchmark-toon.mjs (npm run bench).
The token savings compound at session time: npm run bench:impact simulates retrieving context with vs without memory and measures ~68% fewer tokens to get the same context (recall compact instead of re-reading source files). The full session benchmark (npm run bench:full) shows 80% fewer tool calls and 47% fewer tokens with context_* tools.
Tip: Fewer tokens = faster responses + lower API costs. Your agent reads memory files on every session start, so efficiency matters.
Format          Tokens (16 entries)    vs JSON
──────────────  ───────────────────    ───────
JSON            1097                   baseline
TOON            850                    -22.5%
Method                          Tokens to get context    vs re-reading files
──────────────────────────────  ─────────────────────    ───────────────────
Re-read source files            ~3000                    baseline
memory_recall (flat)            ~1200                    -60%
memory_recall (graph, compact)  ~900                     -70%
memory_smart_recall             ~850                     -72%
The context_* tools replace 3–6 separate tool calls with a single call, saving both tokens and tool-call overhead.
Scenario                          Without   With    Saved    Tools
────────────────────────────────  ────────  ──────  ───────  ──────
context_generate (full briefing)    5,556     378    93.2%   6 → 1
context_diff (incremental)            533     152    71.5%   4 → 1
context_focus (targeted)              413     225    45.5%   4 → 1
context_health (audit)                322     246    23.6%   5 → 1
context_export (injectable md)      1,178     218    81.5%   3 → 1
────────────────────────────────  ────────  ──────  ───────  ──────
TOTAL                              8,002   1,219    84.8%  22 → 5
What each scenario measures:
Tip: Use
context_generateat session start (93% token savings). Usecontext_difffor "what changed since last time?" (72% savings). Usecontext_focusfor deep dives on specific topics (45% savings).
Measured with gpt-tokenizer (cl100k_base) over realistic project scenarios — see scripts/bench-context-tools.mjs (npm run bench:context).
Simulates a complete 5-phase agent session (session start → debug → implement → review → wrap-up) across 3 approaches: without memory, with memory_recall, and with context_* tools.
Phase                                   Without memory     memory_recall      context_* tools
──────────────────────────────────────  ─────────────────  ─────────────────  ─────────────────
Phase 1: Session Start                  516 t /  6 c       409 t /  3 c       373 t /  1 c
Phase 2: Debug Issue                    176 t /  4 c       182 t /  2 c       252 t /  1 c
Phase 3: Implement Feature              189 t /  6 c       183 t /  3 c       305 t /  1 c
Phase 4: Code Review                    316 t /  4 c       130 t /  2 c       243 t /  1 c
Phase 5: Wrap-up                      1,214 t /  5 c        68 t /  2 c       117 t /  1 c
──────────────────────────────────────  ─────────────────  ─────────────────  ─────────────────
TOTAL                                 2,411 t / 25 c       972 t / 12 c     1,290 t /  5 c
Key findings:
The trade-off: memory_recall uses fewer tokens (972 vs 1,290) because it returns only matching entries. context_* tools return richer context (callers, related files, test files, health audit) — more tokens per call, but 80% fewer tool calls. In practice, the agent avoids 3-4 follow-up "find related" calls that context_focus already includes.
Where context_ wins big:*
context_health replaces 5 manual scansTip: Use
memory_recallwhen you need specific entries (fewer tokens). Usecontext_*when you need comprehensive context with fewer round-trips (fewer calls).
Measured with gpt-tokenizer (cl100k_base) — see scripts/bench-full-impact.mjs (npm run bench:full).
Tip:
memory_smart_recallcombines BM25 + graph + quality in one call, saving both tokens and tool-call overhead. Use it at the start of every task.
Since v3.7.0, recall ranks results with Reciprocal Rank Fusion over BM25 (×3) and graph-centrality ranks, with an adaptive k = clamp(3..60, round(sqrt(n))). Measured over 8 gold-standard queries with hand-labeled relevance (see scripts/bench-rrf.mjs, npm run bench:rrf):
Metric        linear (v3.6.x)     RRF (v3.7.0)
────────────  ─────────────────   ────────────────
nDCG@10       0.776               0.776   (parity)
MRR           0.917               0.917   (parity)
RRF matches the previous linear weighted score at zero ranking cost, while simplifying the scoring pipeline (BM25×3 + centrality, no importance/recency noise). Graph mode supersession is honored: obsolete entries stay excluded except for as_of point-in-time queries.
Since v4.1.0, retrieval is benchmarked against a frozen snapshot of real project memory — a LongMemEval-style test set with hand-authored gold queries. Corpus: 187 real data.toon entries (snapshot 2026-08-01), 42 gold queries across 6 categories (core-fact, temporal, knowledge-updating, multi-hop, meta/session, distractor). The measured code is the production pipeline (src/lib), bundled in-memory with esbuild — no faithful copies. A deterministic today parameter pins recency/decay so results can't drift with the wall clock; runs are read-only (no access tracking). Two priority meta-entries that describe the data file itself are excluded. See benchmarks/retrieval-corpus.toon, benchmarks/gold-queries.json (npm run bench:retrieval):
Mode            R@5     nDCG@5  MRR@5   answerable
─────────────   ─────   ─────   ─────   ──────────
linear         0.643   0.654   0.776   81.0%
rrf            0.861   0.764   0.788   97.6%
smart (unified) 0.829  0.739   0.760   92.5%
RRF is the top-ranked mode (0.861 R@5, 97.6% of queries answerable from the top-5); memory_smart_recall stays competitive in a single call.
Symptom: Agent says it doesn't have memory tools.
Fix:
npx toon-memory status to verify installationSymptom: memory_stats shows 0 entries.
Fix: This is normal on first install. Start using memory_remember to save entries.
Symptom: Same key appears multiple times.
Fix: memory_remember with the same key now auto-merges (union of tags, max confidence, latest date). Use memory_consolidate to merge all same-key entries and remove exact-content duplicates. For manual cleanup, use memory_forget.
Symptom: Can't decrypt memory.
Fix: Unfortunately, there's no recovery. The encryption key is not stored anywhere after generation. This is by design for security. You'll need to start fresh or restore from a non-encrypted backup.
Symptom: Agent responses are slow.
Fix:
memory_archive() to move old entries to archivememory_forget to remove irrelevant entriesYes, as long as it supports MCP (Model Context Protocol). We have auto-setup for 22 agents, with manual configuration available for others.
No. Everything stays on your machine. The MCP server runs locally over stdio — no network calls, no telemetry, no cloud.
Yes, if you sync the .toon-memory/memory/ directory (e.g., via Git or a shared folder). Each machine needs toon-memory installed, but the memory file is portable.
Each project gets its own memory file. Memory doesn't leak between projects.
No, encryption applies to the entire memory file. If you need selective encryption, keep sensitive data in a separate tool.
Markdown files aren't structured, aren't searchable by your agent in the same way, don't integrate via MCP, and don't have features like archiving, date filtering, quality scoring, merge-dedup, confidence tracking, or encryption. toon-memory is purpose-built for AI agents.
git clone https://github.com/LuiggiVal08/toon-memory.git
cd toon-memory
npm install
npm run build
npm test
toon-memory/
├── src/
│   ├── bin/
│   │   └── toon-memory.ts      # Entry point
│   ├── cli/
│   │   ├── setup.ts             # CLI commands
│   │   └── toon-memory.ts       # CLI runner
│   ├── mcp/
│   │   ├── server.ts            # MCP server (38 tools + 4 resources + 1 prompt)
│   │   ├── tools.ts             # Tool registration (38 tools)
│   │   ├── resources.ts         # Resource registration (4 resources)
│   │   ├── prompts.ts           # Prompt registration (1 prompt)
│   │   ├── session-store.ts     # Session layer (auto-promote, cleanup)
│   │   ├── memory-io.ts         # Memory file read/write
│   │   ├── entries.ts           # Entry parsing & utilities
│   │   ├── scoring.ts           # Entry scoring & access tracking
│   │   ├── archive.ts           # Archive management
│   │   ├── consolidation.ts     # Duplicate consolidation
│   │   ├── config.ts            # Config loading & saving
│   │   └── crypto.ts            # AES-256-GCM encryption
│   ├── lib/
│   │   ├── lock.ts              # Advisory file lock + atomic write
│   │   ├── sessions.ts          # Multi-session coordination
│   │   ├── graph.ts             # Memory graph (parse, build, BM25, centrality, compact render)
│   │   ├── quality.ts           # Quality scoring, merge-dedup, smart recall, system primer
│   │   ├── context.ts           # Context briefing generator (one-call context)
│   │   └── vocab.ts             # Project-vocabulary discovery from dependencies
├── tests/
│   ├── cli.test.ts              # CLI tests
│   ├── memory.test.ts           # Memory tests
│   ├── sessions.test.ts         # Multi-session tests
│   ├── graph.test.ts            # Memory graph tests
│   └── quality.test.ts          # Quality scoring, merge-dedup, smart recall, system primer tests
├── .github/workflows/
│   ├── ci.yml                   # CI (Node.js 20/22)
│   └── publish.yml              # Auto-publish on release
├── package.json
├── tsconfig.json
└── vitest.config.ts
Contributions are welcome! Please read our Code of Conduct and Contributing Guide first.
git checkout -b feature/amazing-feature)git commit -m 'feat: add amazing feature')git push origin feature/amazing-feature)toon-memory is designed with security and privacy as a core principle.
.toon-memory/memory/. No data is ever sent to external servers, cloud services, or third parties.memory_encrypt (requires TOON_MEMORY_KEY environment variable)..gitignore — The installer adds .toon-memory/memory/ to .gitignore to prevent accidental commits of memory data.MIT
Built with @toon-format/toon and @modelcontextprotocol/server.
Offline persistent memory for AI coding agents — 35 tools, 80% fewer calls, no LLM
{ "mcpServers": { "io.github.luiggival08-toon-memory": { "command": "npx", "args": [ "-y", "[email protected]" ], "env": { "TOON_MEMORY_KEY": "<secret>", "TOON_MEMORY_CAPTURE": "<value>", "TOON_MEMORY_SESSION_ID": "<value>", "TOON_MEMORY_BRANCH": "<value>", "TOON_MEMORY_NO_SESSION": "<value>", "GITHUB_TOKEN": "<secret>" } } }}เครื่องมือ
ยังไม่มีรายการเครื่องมือ เซิร์ฟเวอร์แบบรีโมตจะได้รายการหลังการตรวจสอบสถานะครั้งแรก
FAQ
คัดลอกคอนฟิก stdio สำหรับ Cursor, Claude Desktop, Claude Code หรือ VS Code ได้ในหน้านี้ คอนฟิกนี้ใช้การติดตั้งของผู้เผยแพร่ ไม่ใช่พร็อกซีของ PlugMCP
ผู้เผยแพร่ระบุตัวแปรสภาพแวดล้อมเหล่านี้: TOON_MEMORY_KEY, TOON_MEMORY_CAPTURE, TOON_MEMORY_SESSION_ID, TOON_MEMORY_BRANCH, TOON_MEMORY_NO_SESSION, GITHUB_TOKEN
Toon Memory ทำงานแบบโลคัลผ่าน stdio
ตรวจสอบล่าสุดเมื่อ 2026-11-09 Offline persistent memory for AI coding agents — 35 tools, 80% fewer calls, no LLM
