CrawlEyes — Web Scraping & Search Toolkit for AI Agents
English | 中文
Power your agent
คำสั่งของผู้เผยแพร่เอง ไม่ใช่เอนด์พอยต์ของ PlugMCP
Host a copy with our keys and logs.
uvx crawleyes==0.2.0Claude Code ไม่มีลิงก์ติดตั้งสำหรับคำสั่งแบบโลคัล ให้คัดลอกคำสั่งด้านล่างแล้วรันในเทอร์มินัล
SEARXNG_URL=<value> TAVILY_API_KEY=<secret> claude mcp add io.github.waiky-github-crawleyes -- uvx crawleyes==0.2.0รันในเทอร์มินัล
{ "mcpServers": { "io.github.waiky-github-crawleyes": { "command": "uvx", "args": [ "crawleyes==0.2.0" ], "env": { "SEARXNG_URL": "<value>", "TAVILY_API_KEY": "<secret>" } } }}claude_desktop_config.json
URL แบบรีโมตหรือคำสั่งบนเครื่องของคุณ? การติดตั้งสองแบบต่างกันอย่างไร
รันบน PlugMCP
A new server you create. It is not this listing's official endpoint. Use the publisher install when you want their URL and their credentials.
เปิดจากผู้เผยแพร่
English | 中文
Web scraping & search for AI agents: extract, SearXNG search, rerank, robots compliance. No API key.
CrawlEyes gives AI agents reliable full-text extraction (web_extract) and robust search (web_search) backends — the "eyes" that let agents see and read the web. Built and tested against Hermes Agent.
Also ships as a standard MCP server, so any MCP client (Claude Desktop, Cursor, other agents) can reuse the same search + extraction capabilities.
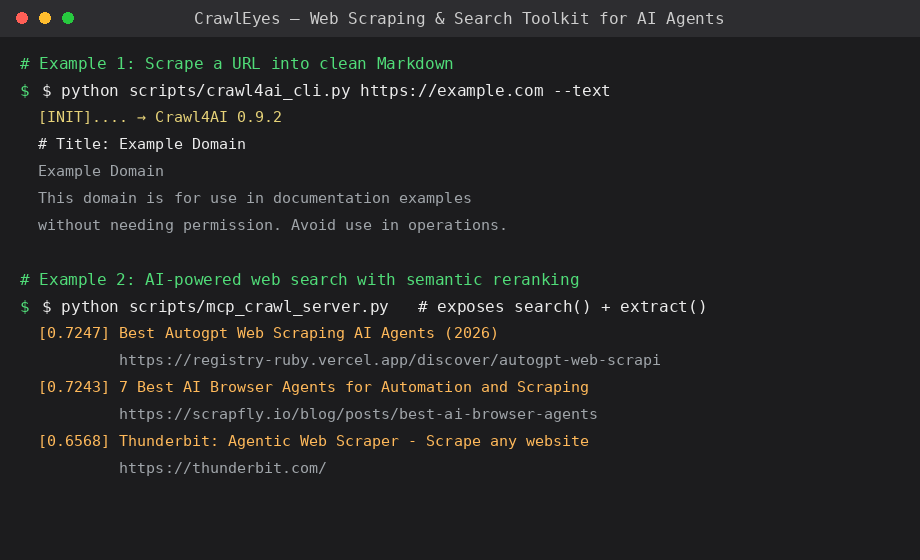
Most agent toolkits cover one slice of the pipeline. CrawlEyes is the rare all-in-one that you can actually run behind the Great Firewall without external accounts.
Zero API keys. Zero external accounts. One command. CrawlEyes is the only toolkit in this space that combines search + extraction + semantic reranking + MCP in a single, China-friendly, self-hosted package.
plugins/searxng-tavily/   Hermes web-search provider plugin (SearXNG → Tavily keyless fallback)
                          + three-state circuit breaker + shared SQLite cache
scripts/
  crawl4ai_cli.py          Universal scraping CLI (URL → Markdown), with denoise/retry/session/BM25
  crawl_search_standalone.py  Standalone search (SearXNG → Tavily) + optional semantic rerank.
                             No Hermes dependency — usable anywhere, powers the MCP server.
  mcp_crawl_server.py      Standard MCP server exposing search + extract + deep_research + sitemap (stdio)
  single_env_check.py      Verify crawl4ai provider registered+available+extracts (one profile)
  verify_searxng_tavily.py Verify searxng-tavily provider: normal path + forced fallback
  agent_link_check.py      Verify full agent tool chain: web_search_tool dispatch + logs
python3 -m venv .venv
# Use Tsinghua PyPI mirror for speed (or any mirror you prefer)
.venv/bin/pip install -i https://pypi.tuna.tsinghua.edu.cn/simple crawl4ai
# Playwright browser kernel — use npmmirror binary mirror if cdn.playwright.dev is blocked
PLAYWRIGHT_DOWNLOAD_HOST=https://registry.npmmirror.com/-/binary/playwright \
  .venv/bin/python -m playwright install chromium
.venv/bin/crawl4ai-setup
.venv/bin/python scripts/crawl4ai_cli.py https://example.com          # stdout Markdown
.venv/bin/python scripts/crawl4ai_cli.py https://example.com -o out.md  # to file
.venv/bin/python scripts/crawl4ai_cli.py URL --text --max-words 5000   # plain text, truncated

# Multi-format extraction (markdown|fit|raw|markdown_with_citations)
.venv/bin/python scripts/crawl4ai_cli.py URL --format raw              # unfiltered source markdown
.venv/bin/python scripts/crawl4ai_cli.py URL --format markdown_with_citations  # + source URLs

# Respect robots.txt (opt-in, default off)
.venv/bin/python scripts/crawl4ai_cli.py URL --respect-robots

# Denoise nav/ads + retry 3x + reuse session across scrapes
.venv/bin/python scripts/crawl4ai_cli.py URL --noise-filter --retry 3 --session s1
# Optional: local semantic rerank of results (fastembed + bge-small-zh, auto-downloaded)
.venv/bin/pip install -i https://pypi.tuna.tsinghua.edu.cn/simple fastembed

# SearXNG first, Tavily keyless fallback, then rerank
SEARXNG_URL=https://your-searxng .venv/bin/python -c "
import sys; sys.path.insert(0, 'scripts')
from crawl_search_standalone import CrawlSearch
r = CrawlSearch(rerank=True).search('your query')
print(r['data']['web'])"
China-network note: the embedding model downloads from HuggingFace, which is blocked on mainland networks. Set
HF_ENDPOINT=https://hf-mirror.comandHF_HUB_DISABLE_XET=1(hf-mirror doesn't support the xet protocol and returns 401 without this).
# Any MCP client can connect via stdio (default):
.venv/bin/python scripts/mcp_crawl_server.py
# Exposes tools:
#   search(query, limit)                 - SearXNG → Tavily keyless, rerank, retry+rate-limit
#   extract(url, max_words, format)      - markdown|fit|raw|markdown_with_citations
#   deep_research(topic, num_questions)  - multi-round cited report
#   sitemap(origin, max_urls)            - URL map from sitemap.xml / robots.txt

# Or serve over HTTP (streamable-http) for remote clients:
.venv/bin/python -m crawleyes.mcp_crawl_server --transport http --port 8765 --host 127.0.0.1
#   → clients connect to http://127.0.0.1:8765/mcp
#   (host/port configurable; default 127.0.0.1:8765)
For Hermes specifically, add to config.yaml:
mcp_servers:
  crawl:
    command: "/path/to/crawl/.venv/bin/python"
    args: ["/path/to/crawl/scripts/mcp_crawl_server.py"]
    timeout: 90
    connect_timeout: 60
/scrape endpointAlready using Firecrawl's Python SDK? Point it at CrawlEyes and keep your code:
.venv/bin/python -m crawleyes.firecrawl_api --port 8899 --host 127.0.0.1
#   POST /v2/scrape  →  { success, data: { markdown, metadata } }
#   GET  /healthz    →  health check
from firecrawl import Firecrawl
fc = Firecrawl(api_url="http://127.0.0.1:8899", api_key="ignored")
doc = fc.scrape(url="https://example.com")   # → { markdown, metadata }
This is a pragmatic subset of the Firecrawl API — the core /scrape contract
(success + data.markdown + data.metadata), backed by CrawlEyes' own
extraction engine. It does not implement Firecrawl's async /crawl queue,
/search, or /map — see the design notes for the rationale.
Copy plugins/searxng-tavily/ into a Hermes plugins dir, then:
hermes plugins enable web/searxng-tavily
hermes config set web.search_backend searxng-tavily
Set SEARXNG_URL in your Hermes profile .env to point at your SearXNG instance. If unset or unreachable, the provider automatically falls back to the Tavily keyless API (no API key required).
Note: the plugin only takes effect for newly started agent sessions.
# Requires the Hermes source tree + its venv
venv/bin/python scripts/verify_searxng_tavily.py $HERMES_HOME
venv/bin/python scripts/agent_link_check.py $HERMES_HOME
record_success() is only called when SearXNG itself succeeds.pwd.getpwuid, not $HOME — which Hermes profiles override), so all profiles share one cache. WAL + 5s timeout + try/except degrade-to-no-cache under concurrency.streamable-http (--transport http), so a single codebase serves both local process and remote HTTP clients.This project builds on a set of excellent open-source tools. All code here is an independent implementation (no copied code), but the ideas and interfaces are drawn from the following projects — full credit to their authors:
Design independence: the implementations here are written from scratch — we studied the above projects' approaches (denoising thresholds, rerank pipelines, backoff strategies, MCP tool patterns) but did not copy their source code. Dependencies are declared in
requirements.txt. If you believe any attribution is missing or incorrect, please open an issue.
CrawlEyes is a general-purpose fetch toolkit for legitimate research and personal use. It deliberately does not include proxy pools, fingerprint rotation, or CAPTCHA-solving (anti-scraping evasion) — those are out of scope.
Robots.txt is opt-in (default off): pass respect_robots=True to extract / markdown (or --respect-robots on the CLI) to check each target's robots.txt (RFC 9309) and refuse URLs it explicitly disallows. It's default-off so legitimate scraping isn't silently blocked by aggressive or broken robots rules — compliance is the caller's informed choice per use case. Always review each site's terms of service before scraping at scale.
MIT — see LICENSE.
公众号:AI Aperture —— 分享 AI 工程实践、多 Agent 系统与开源项目经验。
扫码关注,获取项目更新与更多技术内容。
Web scraping & search for AI agents: extract, SearXNG search, rerank, robots compliance. No API key.
{ "mcpServers": { "io.github.waiky-github-crawleyes": { "command": "uvx", "args": [ "crawleyes==0.2.0" ], "env": { "SEARXNG_URL": "<value>", "TAVILY_API_KEY": "<secret>" } } }}เครื่องมือ
ยังไม่มีรายการเครื่องมือ เซิร์ฟเวอร์แบบรีโมตจะได้รายการหลังการตรวจสอบสถานะครั้งแรก
FAQ
คัดลอกคอนฟิก stdio สำหรับ Cursor, Claude Desktop, Claude Code หรือ VS Code ได้ในหน้านี้ คอนฟิกนี้ใช้การติดตั้งของผู้เผยแพร่ ไม่ใช่พร็อกซีของ PlugMCP
ผู้เผยแพร่ระบุตัวแปรสภาพแวดล้อมเหล่านี้: SEARXNG_URL, TAVILY_API_KEY
CrawlEyes MCP Server ทำงานแบบโลคัลผ่าน stdio
ตรวจสอบล่าสุดเมื่อ 2026-11-10 Web scraping & search for AI agents: extract, SearXNG search, rerank, robots compliance. No API key.