STATECORE_SCOPE — Override the memory scope name (defaults to the git repository root, else the working directory)
FEATURE_LLM — Set to 'true' together with MODEL_* variables to enable background distillation of conversational events; everything else works without it
MODEL_API_KEY — OpenAI-compatible API key for background distillation (DeepSeek, OpenAI, Ollama, ...); not required for core memory, audit, and recall
MODEL_BASE_URL — OpenAI-compatible base URL for the distillation model (e.g. https://api.deepseek.com/v1)
MODEL_NAME — Model used for background distillation (e.g. deepseek-chat)
Claude Code ไม่มีลิงก์ติดตั้งสำหรับคำสั่งแบบโลคัล ให้คัดลอกคำสั่งด้านล่างแล้วรันในเทอร์มินัล
Auditable memory for coding agents and AI systems. Every fact StateCore holds carries its evidence, its version chain, and a recorded reason for every discard — so "why do you believe this, and what did you believe before?" always has an answer.
StateCore is a self-hosted, low-drift long-term memory runtime for local or BYO models. It turns memory from accumulated text into governed state: events are ingested, run through a deterministic digest pipeline, and merged into protected stable state. The LLM proposes; the pipeline decides.
Try it in 30 seconds
No server, no signup, no model key — one SQLite file over MCP:
claude mcp add statecore -- npx -y statecore-mcp # Claude Code
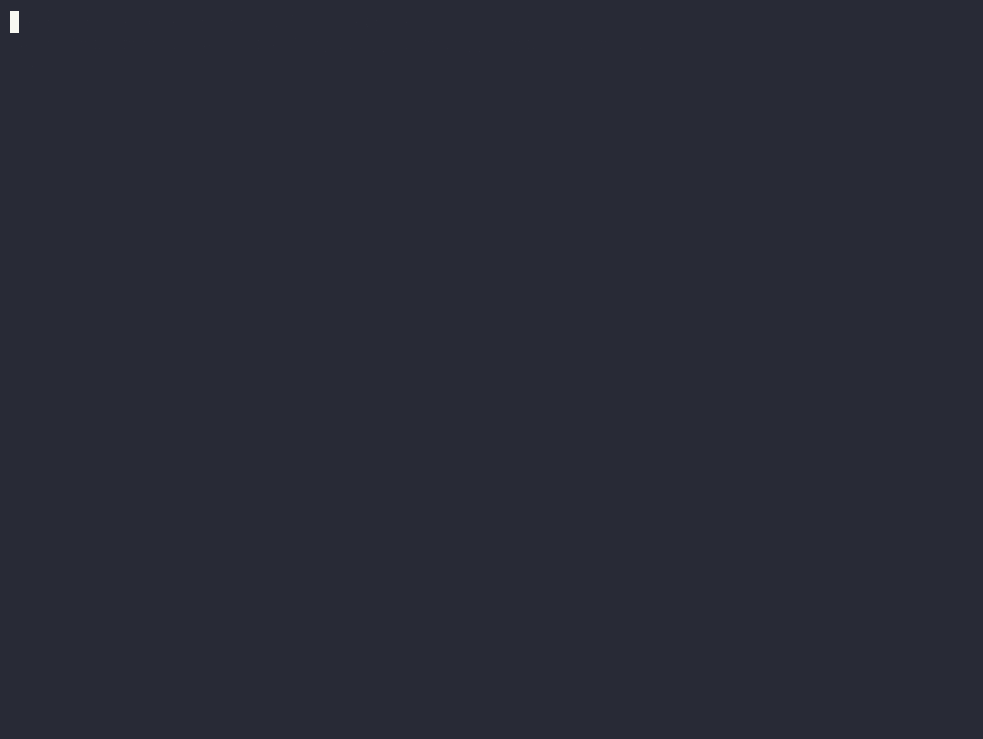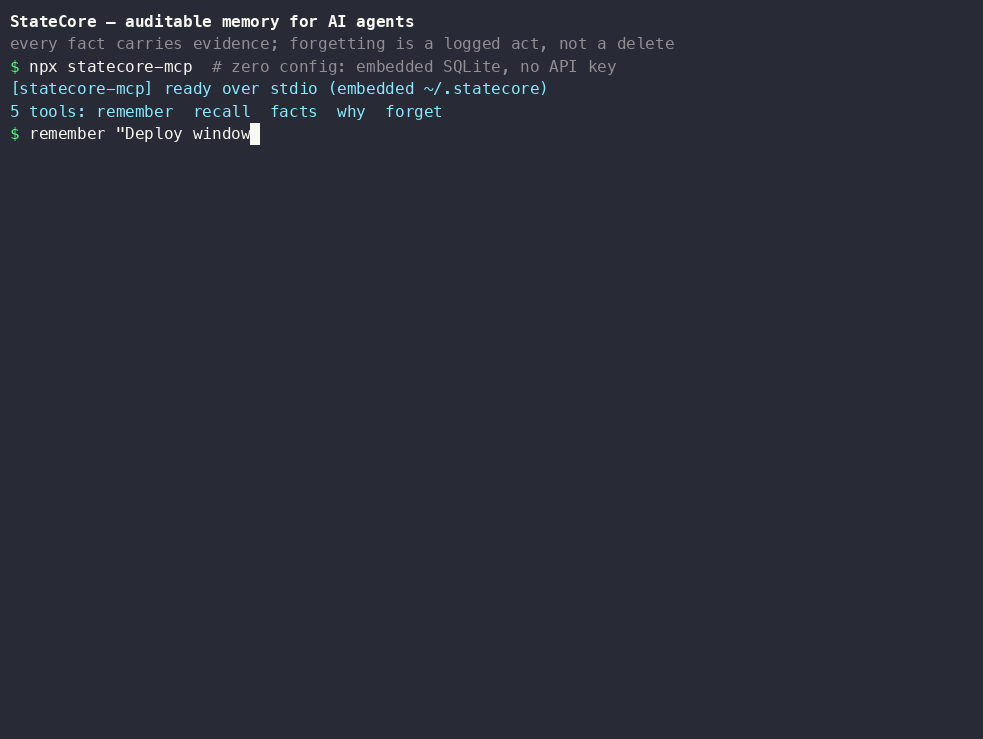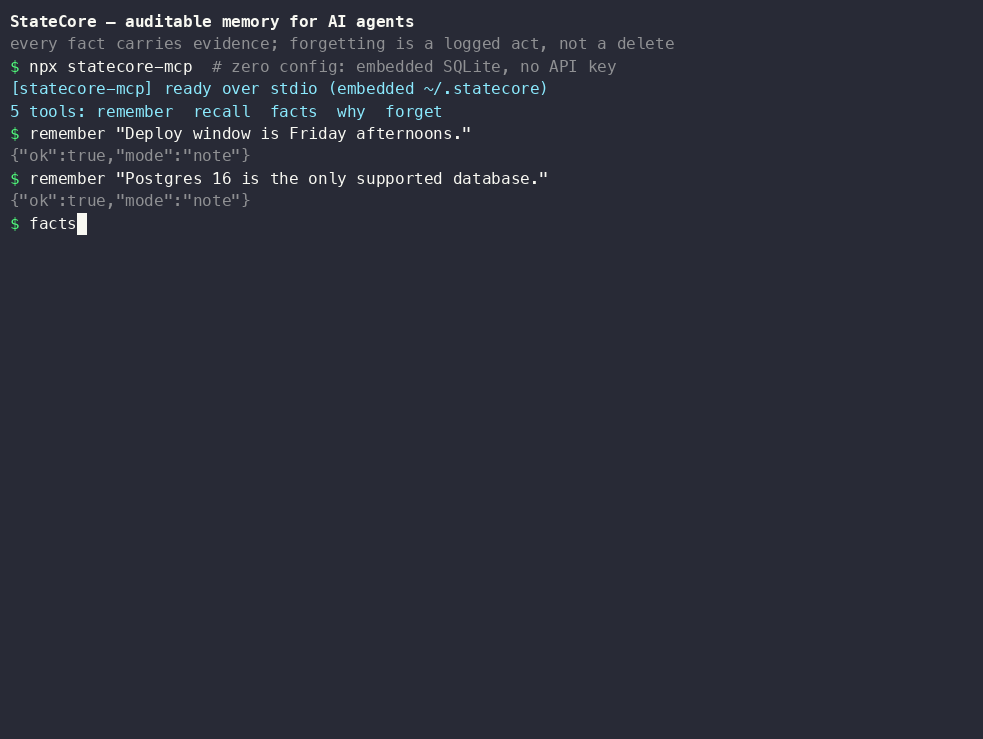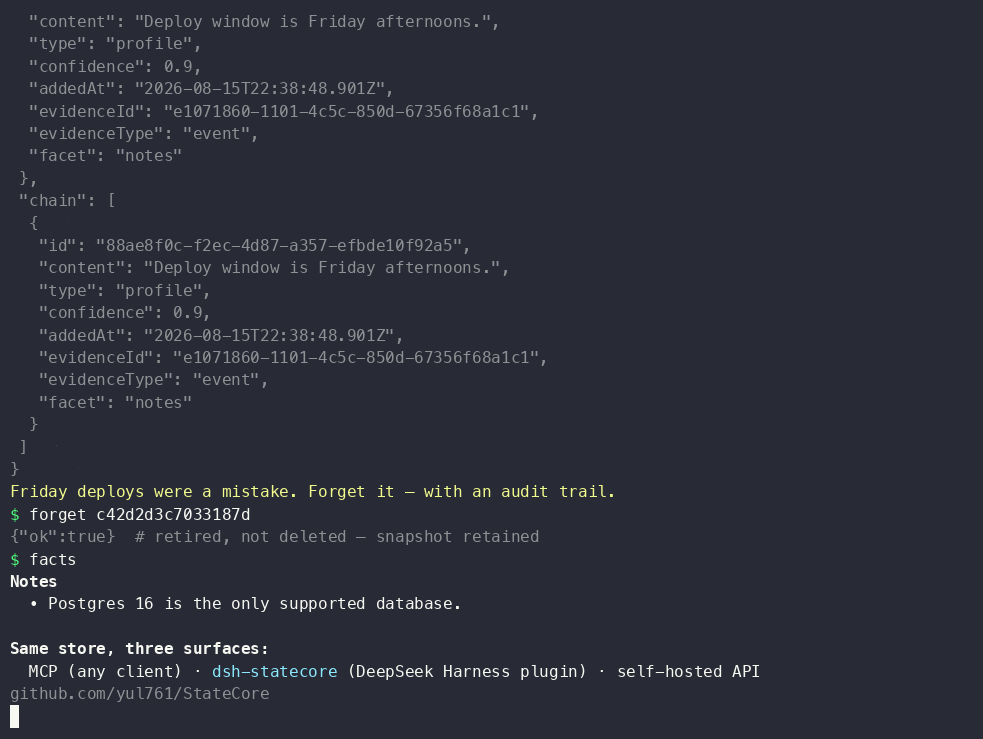
remember a decision in one session, ask why in the next: you get the fact, the evidence behind it, and its version history — superseded and retired facts stay on the record, marked, never deleted. And sessions hand off across vendors: handoff records where one session stopped, and the next one — Claude Code, Codex, Cursor, any MCP client on the same project — receives it at the top of recall, with every earlier stop-point still on the audit chain. Configs for Cursor, dsh, and every other MCP host: apps/mcp/README.md.
Capture is easy. Trust is hard.
Most agent-memory tools compete on capturing more — hook every event, compress the transcript, inject it back. Capture is the solved half of the problem. The unsolved half is what those tools' own issue trackers are full of: memories that silently stop being written, stale decisions injected as if still current, cross-project leakage, and no way to audit or repair what the store believes. That is not a rhetorical claim — docs/prior-art-failure-modes.md cites the verified issues, by number, across five systems.
StateCore is built for that second half:
Nothing is silently lost. Every discard is logged against a fixed set of reasons; every replaced fact keeps a supersededBy chain; retired facts are marked, never deleted.
Nothing is silently believed. Writes go through a deterministic pipeline with consistency gates — an LLM proposal alone cannot promote itself into stable state.
Nothing degrades silently. A failed digest carries degraded; the budget reports what it refused; retrieval reports which embedding stages failed and derives its mode from what actually ran, not from what was configured.
Everything is checkable.why returns a fact's evidence and full version history; a digest's selection report shows exactly what it kept and dropped.
How this compares to other memory systems, mechanism by mechanism: docs/why-auditable.md.
Features
Event store — ingest stream events and keyed documents into per-scope memory
Digest pipeline — background worker consolidates events into stable state through selection, merge, consistency checks, and retry
Protected state — goals, constraints, decisions, and todos are gated by a consistency gate; the LLM proposes, the pipeline enforces
Auditable facts — every fact carries its evidence and its supersession chain, and a fact that leaves the active set is retired rather than deleted, so "why do you believe this, and what did you believe before" stays answerable
Recorded discards — the digest logs what it dropped and why, against a fixed set of reasons; losing information is survivable, losing it silently is not
Replaceable ontology — facets come from a pack resolved per tenant and scope, so the engine stores, protects and supersedes without knowing what a facet means
Retrieval — hybrid keyword + optional pgvector semantic search over events and digests, packed into a caller-declared character budget that reports what it refused; pinned events and write-protected facts get a bounded ranking boost (never a filter), and embedding failures are itemised in retrieval.degraded instead of silently downgrading quality
Reminders — daily reminder job surfaces follow-up items from active scopes
Benchmarks — a published LongMemEval comparison against mem0 OSS at an equal context budget, plus a built-in synthetic regression suite that guards fact retention, goal stability, decision continuity, and retrieval MRR across commits
MCP server — statecore-mcp, a zero-deploy Model Context Protocol front end for coding agents; keyless by default, one SQLite file, no infrastructure
On OpenAI, pick a model that accepts reasoning_effort. The runtime turn
sends it on every request — assistant-runtime.ts defaults it to low rather
than leaving it unset — so POST /v1/memory/runtime/turn fails against a
gpt-4o* model, which rejects the parameter. Digest and answers do not send it
unless MODEL_STRUCTURED_OUTPUT_REASONING_EFFORT is set, so a gpt-4o* model
appears to work right up until the first runtime turn. Any endpoint that
accepts the parameter, or ignores unknown ones, is fine.
3. Start infrastructure
docker compose -f docker-compose.local.yml up -d
This starts Postgres (with pgvector) and Redis.
4. Prepare the database
pnpm db:generate
pnpm db:migrate
pnpm seed
5. Start the services
pnpm dev:api      # NestJS API on PORT (default 3002)
pnpm dev:worker   # background digest + reminder workers
The API is available at http://localhost:3002 (or whatever PORT is set to).
API
Authentication
All requests require an x-user-id header. For local development, set LOCAL_USER_TOKEN=local-dev-user in .env and send:
x-user-id: local-dev-user
Public surface (/v1)
The /v1 prefix exposes the stable, public-facing subset of the API. Full OpenAPI schema:
GET /openapi.json
Interactive Scalar UI:
http://localhost:3002/docs
Reference documentation: docs/api.md
Key endpoints
Method
Path
Description
POST
/v1/memory/events
Ingest a stream event or document
POST
/v1/memory/retrieve
Retrieve grounded evidence for a query, within an optional maxChars budget
POST
/v1/memory/digest
Trigger a State Layer digest job
GET
/v1/memory/facts
Grouped memory facts for a scope
GET
/v1/memory/facts/:factId/provenance
A fact's evidence and its full version chain
GET
/v1/memory/digests/:digestId/selection
What a digest kept, and what it discarded and why
GET
/v1/facet-pack
The active facet ontology for a scope or account
GET
/v1/scopes
List scopes
GET
/memory/stable-state
Current stable-state snapshot ¹
GET
/memory/working-state
Current working-memory snapshot ¹
GET
/memory/layer-status
Aggregated layer health ¹
The three audit readers in the middle are the ones that make the engine's memory
checkable rather than merely stored; docs/api.md lists the full frozen surface.
API stability: the /v1 contract is frozen and additive-only — see
STABILITY.md. It currently covers 22 operations across 20
paths. The contract carries its own version in the generated OpenAPI document
(info.version, currently 1.8.0), which is what tells you how current a spec
you are holding; it is not the release tag and not any package version.
¹ Internal read-model endpoints — registered only at /memory/..., not under /v1, and not part of the frozen /v1 contract.
Use it from your coding agent (MCP)
statecore-mcp is a separately published npm package that fronts this engine
over the Model Context Protocol — no
running server required. It runs the engine embedded (one process, one SQLite
file), keylessly by default:
npx -y statecore-mcp --data ~/.statecore
Point any MCP client at it, or run it against a full StateCore deployment via
--url for shared/multi-agent memory. Full docs, host configs, and the
keyless/keyed capability matrix: apps/mcp/README.md.
Client
Setup
Claude Code
claude mcp add statecore -- npx -y statecore-mcp (config)
dsh
pinned-executable overlay config included (config)
same stdio command; HTTP via --url against a deployment
Team memory: one self-hosted deployment as the shared project brain for every agent your team runs — dsh sessions, Claude Code, CI — with one audit trail across all of them: docs/team-memory.md.
Architecture
apps/api        NestJS HTTP server — ingestion, retrieval, runtime turns, diagnostics
apps/worker     BullMQ background workers — digest, working-memory updates, reminders
apps/mcp        statecore-mcp — MCP server, embedded or thin client against apps/api

packages/core       Memory engine (MemoryService, DigestService, RetrieveService, AssistantSession)
packages/contracts  Zod schemas for all API I/O
packages/db         Prisma schema, migrations, and client
packages/prompts    LLM prompt templates (digest, answer, runtime)
StateCore sits between your client and your model endpoint. Events flow in, the digest pipeline consolidates them into protected state, and retrieval pulls grounded evidence back out for answers or runtime turns.
Three-layer memory model:
Fast Layer — synchronous; assembles prompt context for the current turn from recent events, working memory, and stable state
Working Memory — lightweight, quickly-updated structured memory; bridges raw recent turns and slow stable-state consolidation
State Layer — authoritative, replayable, low-drift long-term memory; updated asynchronously through the digest control pipeline
See docs/vision-and-roadmap.md for the layered model design and roadmap.
Testing and Benchmarks
Run package tests:
pnpm --filter @statecore/core test
pnpm --filter @statecore/api test
Run the full latency + memory quality benchmark:
pnpm benchmark
Run the synthetic regression suite (no LLM required):
pnpm --filter @statecore/core eval
The synthetic suite is a regression guard, not a capability benchmark: every
scenario scores 1.000 on the current engine, deliberately — its job is to fail
when a change breaks retention, stability, or retrieval, not to rank systems.
The comparison that ranks systems is LongMemEval, below.
Benchmark methodology: docs/benchmarking.md
LongMemEval
Compared against mem0 OSS on
LongMemEval at an equal context
budget — the same number of characters of memory in the answerer's prompt,
rather than the same number of retrieved items. 194 questions, gpt-5 answering,
the official gpt-4o judge (2026-08-08):
system
4,000 tok
16,000 tok
64,000 tok
StateCore
51.0% ±7.0
80.9% ±5.5
87.6% ±4.6
mem0 OSS
61.3% ±6.9
59.8% ±6.9
61.3% ±6.9
No memory (recency window)
9.3% ±4.1
22.7% ±5.9
53.6% ±7.0
At 64k, StateCore also beats the 70.1% ±6.4 ceiling of pasting the entire
corpus into the prompt with no memory layer at all. At 4k it loses to mem0 by 10
points — a real difference in kind, explained rather than closed, in the full
write-up.
Numbers, caveats and what the benchmark does not measure:
docs/longmemeval.md. Harness, raw retrievals and
per-question judge verdicts:
memory-budget-bench.
Documentation
docs/start-here.md — orientation for new contributors
docs/repo-map.md — repo structure, where code belongs, and the full doc index
docs/philosophy.md — what the engine is for, and why auditability is the centre
docs/why-auditable.md — audit mechanisms compared with other memory systems, factually
docs/prior-art-failure-modes.md — the documented failure modes this design answers, with verified issue citations
docs/glossary.md — facet, pack, supersession, retirement, drop log
docs/api.md — full API reference and the /v1 contract rules
docs/vision-and-roadmap.md — positioning and roadmap, with a status map