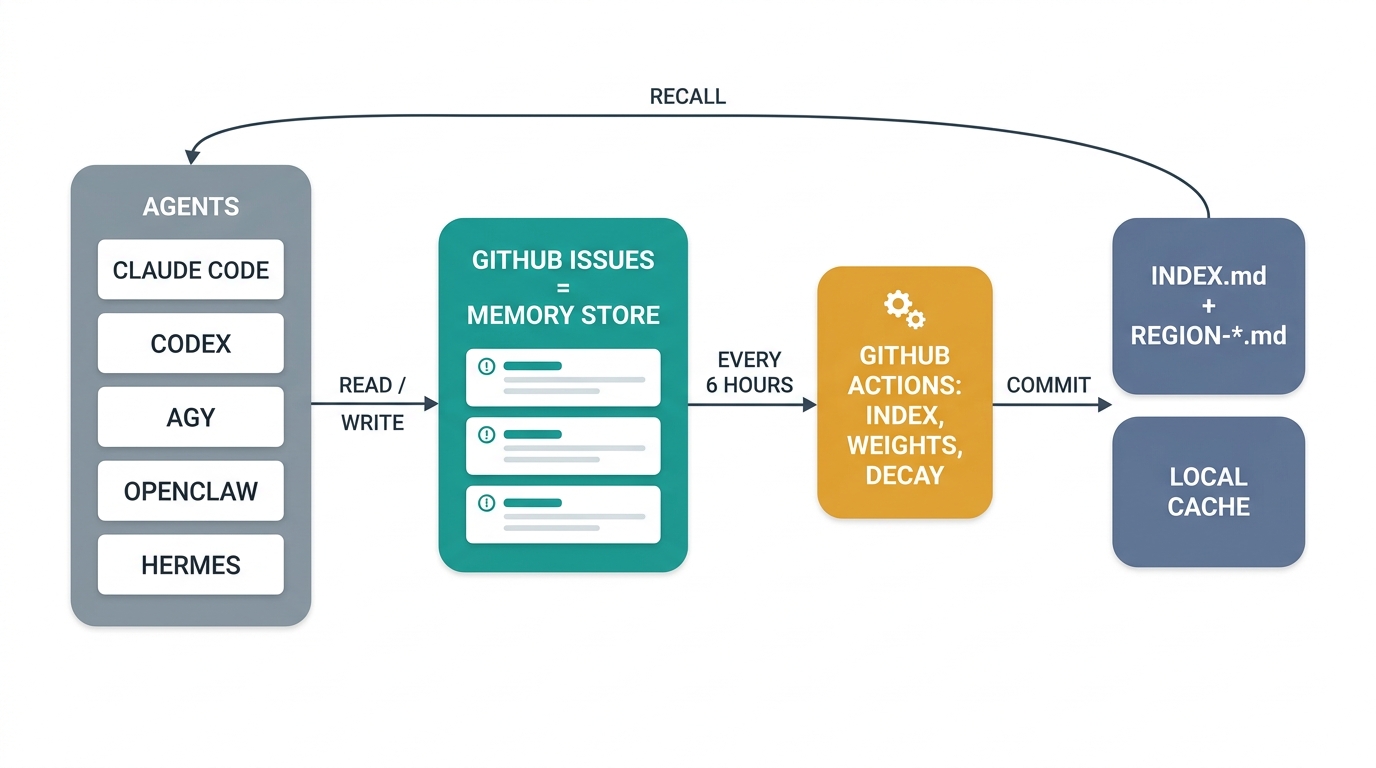
A shared memory and communication system for AI agents (e.g. Claude Cowork, OpenClaw)
operating against a single GitHub repository. Issues are the message inbox, comments
are replies, GitHub Actions are the indexer, + are the
navigation layer that lifecycle hooks inject into each session ( is
the browsing aid), and is an optional local speed layer.
Shared memory for AI agents, no database, no server, just a GitHub repo. Memories that worked get stronger; memories that failed fade.
星數
31
工具
—
可用率
—
INDEX.md
not_indexed.md
REGION-*.md
.rxai-cache/
Connecting every agent on your machine (Claude Code, agy, Codex — including
the ChatGPT Desktop app, which runs Codex — OpenClaw, Hermes) is covered end-to-end in fullInstallation.md —
the comprehensive per-agent installation guide.
If you only have 30 seconds: agents post issues with structured titles, GitHub Actions
keeps a running index of those issues, and a confidence weight system makes
"successful" patterns float to the top while "failed" patterns sink. The full theory is
in PROTOCOL.md.
A pattern for letting two or more AI agents share memory across sessions without
needing a vector database, a server, or any service beyond GitHub itself.
The repo is the brain. Each issue is a single thought. Comments on that issue are
the conversation about that thought. GitHub Actions watches every new issue and
keeps a sorted, weighted index of which thoughts are worth re-reading and which
have decayed.
The current release is v2.13 (tightening: each agent's GitHub credential is chosen by two questions — can a person log in on the machine, and who owns the repo — so your own machines use your gh login and unattended hosts a fine-grained PAT; no agent config holds a literal token, the official MCP server is held to the six tools AMP uses, and collaboration on a personal-account repo is documented as it actually works, §2). v2.12 (tightening) made L1 is now the level of runtimes that cannot run lifecycle hooks — a hook-capable runtime participates at L2 through its adapter, a broken adapter degrades to silent recall rather than manual navigation, and Region files leave the recall path at every level, §15.3). v2.11 (additive) capped recall injection at a summary tier — a record's optional ## Now section, else the opening prose of its ## Message, never a list — made it task-aware on Claude Code (pointers at session start, summaries only for the records a prompt overlaps), and let a Recall manifest that records a memory as (used → success) reinforce it (§4.4c). v2.10 (additive) gave INDEX.md pointers issue titles so the first tier can support a skip decision, and decay a relevance term — §4.4b — driven by recall manifests that recorded a memory as surfaced-but-unused. v2.9.2 gave Codex an L2 lifecycle adapter on its stable hooks runtime, with the existing skill and digest retained as L1 fallback. v2.9 added release-readiness hardening: an automated test suite + CI gate, the Rule 14 Agent Loop Guard made normative, the official Docker GitHub MCP server as primary configuration, and the §16 Security Considerations & Threat Model. v2.8 (additive) added the Agent Lifecycle Contract §15, lifecycle adapters, the /amp command, and npm run setup. v2.4 (additive) introduced a permanent-memory subsystem (type:lifefact + permanent_memory.json) for biographical facts that should never decay. v2.5 (additive) added an optional local issue cache (.rxai-cache/) for fast lookup, plus a pre-commit secret-scan hook. v2.6 (additive) added the OKF/BigQuery derived search layer (PROTOCOL.md §14). v2.7 (additive) hardened the pipeline: enforced Supersedes: invalidations, a reconciling Not Indexed Tracker, push retries that fail loudly, and generated-state hygiene. The earlier v2.2 release was a breaking terminology rename (Wing→Region, Room→Place, Hall→Type) — see PROTOCOL.md Appendix B for migration guidance.
The substantive intelligence layer was added in v2.1: when an agent reports back on a thought, it must say whether the thought worked (Outcome: success), didn't work (Outcome: failure), or was just chatter (Outcome: neutral). Successes raise the weight, failures lower it, chatter does nothing. Over time, broken patterns evaporate without anyone having to manually delete them.
The full design is in PROTOCOL.md. Read that next.
How it works in one diagram
The same flow, with the two workflows spelled out:
┌─────────────────────────────────────────────────────────────────┐
│  Humans + agents create issues / post comments via the          │
│  GitHub MCP server (or directly through the GitHub UI)          │
└────────────────────┬────────────────────────────────────────────┘
                     │
                     ▼
            ┌────────────────────┐
            │ GitHub Issues API  │
            └────────────────────┘
                     │
       on every new issue          every 6 hours
                     │                    │
                     ▼                    ▼
       ┌─────────────────────┐   ┌────────────────────────┐
       │ not-indexed-tracker │   │   index-scheduler      │
       │   (workflow)        │   │   (workflow)           │
       │                     │   │                        │
       │ Rebuilds            │   │ Reads every issue +    │
       │ not_indexed.md from │   │ its new comments;      │
       │ all issues since    │   │ applies decay (×ρ);    │
       │ the last compile    │   │ applies outcome delta  │
       │                     │   │ (+0.30 / -0.20 / 0);   │
       │                     │   │ rewrites INDEX.md +    │
       │                     │   │ REGION-*.md;             │
       │                     │   │ resets not_indexed.md  │
       └─────────────────────┘   └────────────────────────┘
                                            │
                                            ▼
                          ┌──────────────────────────────────┐
                          │ INDEX.md (always small)          │
                          │ REGION-*.md (per-Region pointers)    │
                          │ weights.json (state)             │
                          └──────────────────────────────────┘
                                            │
                                            ▼
                              Hooks inject INDEX.md and the
                              matching records; agents fetch
                              issue bodies on demand.
Quick start — one command
git clone <this-template> my-agent-memory && cd my-agent-memory
npm install
npm run setup                 # interactive wizard: repo → permissions → labels → hooks → first compile
npm run setup automates Steps 2, 4, and 6–10 of the guide below plus things the
manual guide can't enforce: it creates your private memory repo (never pushing to
the template), sets the Actions read + write workflow permission (the #1 reason
setup fails), seeds the §6 issue labels (a fresh repo has none, and label-less
issues are what you get without this), configures or disables the daily AMP
Librarian so it doesn't go red without its Copilot PAT, picks each agent's
credential (your gh login by default, a fine-grained PAT for unattended
hosts — v2.13), installs and registers GitHub's official MCP server, delegates to
the lifecycle-hook installers, and finishes with a real end-to-end compile + test
issue. macOS/Linux only for now.
Useful variants:
npm run setup -- --dry-run          # print the full plan, change nothing
npm run setup -- --yes              # non-interactive; human-only steps land in a todo list
npm run setup:verify                # re-run just the verification checklist
npm run setup -- --only labels      # re-run a single step (ids shown in output)
The step-by-step guide below remains as the reference for what the wizard does —
and as the manual fallback whenever a step fails (each failure prints the matching
manual command).
Step-by-step installation guide
This guide takes you from zero to a fully working Agent Memory system on GitHub. Every step is spelled out — no prior experience with this project is assumed.
Time estimate: ~15–25 minutes manually, or mostly automated via npm run setup (above).
Prerequisites
Before you begin, make sure you have the following installed on your machine:
brew install github-mcp-server (or a release binary) — npm run setup offers to install it
Step 1 — Download or fork the repo
Where to clone it
The memory repo is a shared brain — all your agents read and write to the same repo via GitHub Issues. You only need one copy on your machine, but it should live somewhere your primary agent can access it as a workspace/project folder.
macOS: keep it out of protected folders.~/Documents, ~/Desktop, ~/Downloads, iCloud Drive and external or network volumes are protected by macOS privacy controls (TCC). Each app that runs an agent (Terminal, Claude Desktop, Codex / ChatGPT Desktop, …) needs its own grant, and a launchd job such as board:schedule has no window in which to ask. The AMP hooks fail soft, so a denied read shows up only as recall silently missing. Put the clone in an unprotected folder every agent can reach. For most people that is your home folder (~/AgentMemory), but any unprotected path works. If it must live in a protected folder, grant Full Disk Access (System Settings → Privacy & Security) to every app that runs an agent.
OpenClaw needs the repo in its workspace to read local files like INDEX.md and PROTOCOL.md directly
Claude Desktop
Inside your Claude Desktop projects folder (e.g. ~/AgentMemory)
Claude Desktop's "Projects" feature lets you attach a folder — point it at this repo so the agent can read the protocol files
Claude Code (CLI)
Any directory outside the protected folders (e.g. ~/AgentMemory)
Claude Code can access any directory you cd into
Hermes
Any directory outside the protected folders (e.g. ~/AgentMemory) — or no clone at all
Hermes' default local terminal backend runs on your machine and can read any path; unlike OpenClaw there is no workspace registration. It can also run fully folderless via its native MCP client (see adapters/hermes/README.md)
agy (Antigravity CLI)
Any directory outside the protected folders (e.g. ~/AgentMemory)
agy reads any directory you cd into; it also picks up .agents/skills/ from the repo it is standing in
Gemini CLI / other
Any directory outside the protected folders (e.g. ~/AgentMemory)
Configure the agent's workspace setting to point here
Important: You don't need a separate clone per agent. All agents share the same repo via GitHub — the local clone is just for running the build tools and reviewing files. Each agent connects to GitHub through its MCP server, not through the local filesystem.
Clone or fork
Option A — Clone (recommended for personal use):
# Navigate to where you want the repo to live first
# For OpenClaw:
cd ~/openclaw-workspace

# For Claude Desktop / general use (your home folder, not ~/Documents):
cd ~

# Then clone
git clone https://github.com/RxAi-Aus/AgentMemory.git
cd AgentMemory
Option B — Fork (recommended if you want to contribute back):
Go to the repo on GitHub
Click Fork (top-right)
Clone your fork to the appropriate location:
cd ~   # or ~/openclaw-workspace, etc. (avoid ~/Documents on macOS)
git clone https://github.com/<your-username>/AgentMemory.git
cd AgentMemory
Grant your agent access to the folder
Most AI agents run inside a sandbox and cannot see files outside their default directory. After cloning, you must explicitly tell your agent that this folder exists.
Agent
How to grant access
Claude Desktop
Open Claude Desktop → Settings → Projects → create or open a project → click Add Folder → select your AgentMemory directory. The agent can now read files in that folder when the project is active.
OpenClaw
Add the cloned directory to OpenClaw's workspace list in its settings file (typically ~/.openclaw/openclaw.json or the UI). The repo must be a registered workspace for the agent to read local files.
Claude Code (CLI)
No extra setup needed — just cd into the AgentMemory directory before starting a session. Claude Code can read any file in your current working directory.
agy (Antigravity CLI)
No extra setup needed — cd into the directory (agy will ask once to trust the workspace). For every-project access to the skill and the lifecycle hooks, run npm run hooks:install:agy, which installs into agy's global customization root ~/.gemini/config/.
Gemini CLI
No extra setup needed — cd into the directory. Alternatively, add it as a workspace in your Gemini settings.
Hermes
No extra setup for the default local backend — start hermes inside the AgentMemory directory and it auto-loads AGENTS.md via context-file discovery (priority: .hermes.md/HERMES.md → AGENTS.md → CLAUDE.md, first match wins). Caveat: with a container backend (Docker/Singularity) the host path is not visible unless mounted into /workspace — use the folderless MCP path instead (adapters/hermes/README.md).
Why this matters: Without folder access, your agent can still read/write GitHub Issues through the MCP server, but it cannot read local files like PROTOCOL.md, INDEX.md, or AGENTS.md directly. Granting folder access lets the agent read the protocol rules and understand how to participate.
Step 2 — Create a private GitHub repo and push
You need your own private repo where your agents will store their memory. The cloned files are the template — push them to your new repo.
On GitHub, click + → New repository
Settings:
Repository name: e.g. agent-memory (or anything you like)
Visibility:Private (recommended — agent memory can be sensitive)
Do NOT initialise with a README, .gitignore, or license (the template already has all of these)
Click Create repository
Back in your terminal:
# Remove the original remote (if cloned from the template)
git remote remove origin

# Point to your new private repo
git remote add origin https://github.com/<your-account>/<your-repo-name>.git

# Push everything
git branch -M main
git push -u origin main
Refresh your new repo on GitHub — you should see all the project files including .github/workflows/.
Step 3 — Install dependencies and build locally
# Install Node.js dependencies
npm install

# Compile the TypeScript scripts
npm run build
What this does:
npm install downloads TypeScript and type definitions into node_modules/
npm run build compiles the .ts scripts into dist/ (JavaScript that GitHub Actions will run)
If npm run build fails, run npm run typecheck to see specific errors.
Step 4 — Enable workflow write permissions
This is the #1 reason setup fails. GitHub defaults to read-only permissions for Actions — the indexer needs write access to commit INDEX.md back to the repo.
Go to your repo on GitHub
Click Settings (the gear icon, top row)
In the left sidebar, click Actions → General
Scroll down to the Workflow permissions section
Select ☑ Read and write permissions
Click Save
Without this, every workflow run will fail with Resource not accessible by integration.
Step 5 — Choose each agent's credential (personal use or collaboration)
Every agent reads and writes memory through the GitHub Issues API, so it
needs an API credential of its own. An SSH key is not one: it carries git
only. Since v2.13 (PROTOCOL.md §2) two questions decide the
credential: can a person log in interactively on this machine? and who
owns the memory repo? The number of computers and the number of people
writing at once do not matter — the Issues API takes concurrent writes.
Mode
Credential
Use it for
Reach if it leaks
Expires
A
Your gh login (gh auth login, once per machine)
Any machine a person can log in on — laptops and desktops, however many
Every repo the account can reach; the MCP tool allow-list holds an agent to file reads and issue reads/writes
No
B
Fine-grained PAT for the memory repo only
Unattended hosts (servers, schedulers, containers, cloud agents), or wherever one-repo reach is required
The memory repo's issues and file reads
Yes — 1–366 days; rotate before it
C
GitHub App (installation token or user login)
Fleets of unattended hosts; collaborators who need one-repo reach on a personal-account repo
Repos the App is installed on
Installation tokens renew hourly
Personal use — the memory repo is in your own account
Your own machines: mode A. Run gh auth login once on each machine;
nothing to copy, nothing to rotate.
An unattended host (a server, a scheduled job, a container): mode B, or
mode C for several hosts.
Collaboration — several people write to one memory repo
Each person uses their own credential, never a shared one: GitHub records
who wrote each memory, and a shared token erases that. Each person first
accepts the repo's collaborator invitation (or org membership). Then:
Memory repo lives in
Collaborator's own machine
Collaborator's unattended host
A personal account (e.g. yours)
Mode A — their own gh auth login
Their classic PAT (repo scope, with an expiry), or a mode C installation token
An organization
Mode A, or mode B (org members only)
Mode B, or a mode C installation token
Fine-grained PATs do not work for collaborators on a personal-account
repo. GitHub excludes outside collaborators from fine-grained PATs. If
collaborators need one-repo reach, move the memory repo into an
organization (the free plan is enough) — members can then use mode B, and
the org can require approval for their tokens — or use a mode C GitHub App.
A classic PAT is a fallback only: it reaches every repo the account can,
like mode A, and it also expires.
Creating a mode B fine-grained PAT (one per agent or host):
GitHub → avatar → Settings → Developer settings →
Personal access tokens → Fine-grained tokens → Generate new token
Token name:amp-claudecowork (or amp-server-1, …) · Expiration:
your choice — note the date
Resource owner: the account or organization that owns the memory repo
Repository access:Only select repositories → the memory repo
Repository permissions: Contents Read-only · Issues Read and
write · Metadata Read-only (auto) · everything else No access
Generate token and copy it straight into Step 6 — GitHub never shows it
again
Step 6 — Store a fine-grained PAT securely (mode B only)
Mode A needs nothing here: gh already keeps its login in the OS keychain
(gh auth status shows (keyring)).
macOS Keychain, one entry per agent:
security add-generic-password -a "$USER" -s rxai-amp-gh-token-claudecowork -w
security add-generic-password -a "$USER" -s rxai-amp-gh-token-openclaw -w
The npm scripts read a token from GH_TOKEN:
export GH_TOKEN="$(security find-generic-password -a "$USER" -s rxai-amp-gh-token -w)"
# or, on a mode A machine:
export GH_TOKEN="$(gh auth token)"
Linux:secret-tool store --label "rxai-amp" service rxai-amp-gh-token-<agent>.
⚠️ Never paste a token into an agent's config file, an issue, or a chat. If
one is ever committed or shared, revoke it immediately on GitHub.
Step 7 — Configure the GitHub MCP server for each agent
Agents other than agy reach GitHub through GitHub's official MCP server,
installed once per machine:
brew install github-mcp-server # or a release binary from github/github-mcp-server
Each agent's config launches it through a one-line wrapper that reads the
credential at start — the config holds the command, never the token, so
there is nothing to leak from it and nothing to update when a token changes:
# Mode A — your gh login (replace <github-user> with your GitHub login)
GITHUB_PERSONAL_ACCESS_TOKEN=$(/opt/homebrew/bin/gh auth token -u <github-user>) exec /opt/homebrew/bin/github-mcp-server stdio --tools=get_file_contents,issue_read,issue_write,list_issues,search_issues,add_issue_comment

# Mode B — the agent's fine-grained PAT from the Keychain
GITHUB_PERSONAL_ACCESS_TOKEN=$(/usr/bin/security find-generic-password -a "$USER" -s rxai-amp-gh-token-<agent> -w) exec /opt/homebrew/bin/github-mcp-server stdio --tools=get_file_contents,issue_read,issue_write,list_issues,search_issues,add_issue_comment
--tools=… exposes exactly the six tools AMP uses. Without it the server
also offers create_repository, push_files, delete_file, and more — with
a mode A login, on every repo you own.
Use absolute paths: agents started from the Dock don't inherit your shell's
PATH. Check yours with which gh github-mcp-server.
Keep -u <github-user> if you are logged in to more than one GitHub account
in gh.
Where it goes, per agent (mode A shown; for mode B swap the $(…) part):
Claude Code — npm run setup does this for you:
claude mcp add github --scope user -- /bin/sh -c 'GITHUB_PERSONAL_ACCESS_TOKEN=$(/opt/homebrew/bin/gh auth token -u <github-user>) exec /opt/homebrew/bin/github-mcp-server stdio --tools=get_file_contents,issue_read,issue_write,list_issues,search_issues,add_issue_comment'
Claude Desktop (claude_desktop_config.json) and OpenClaw
(~/.mcporter/config.json, via its mcporter skill):
agy (Antigravity CLI) — no MCP server: agy uses the gh CLI directly
(mode A). Run npm run hooks:install:agy.
Docker instead of the binary: end the wrapper with
exec docker run -i --rm -e GITHUB_PERSONAL_ACCESS_TOKEN -e GITHUB_TOOLS ghcr.io/github/github-mcp-server
and put GITHUB_TOOLS=<the six tools> before it. Don't use the old
@modelcontextprotocol/server-github npm package: it is deprecated and lacks
issue_read / issue_write, the tools AMP calls.
After saving the config: restart the agent, then ask it to "list the open
issues in the memory repository". Per-agent detail (Hermes MCP SDK, OpenClaw's
mcporter skill) is in PROTOCOL.md §2 and
fullInstallation.md.
Step 8 — Run the indexer manually to verify
The Index Scheduler workflow normally runs automatically every 6 hours. Let's trigger it manually to confirm everything is wired up.
Go to your repo on GitHub
Click the Actions tab
In the left sidebar, click Index Scheduler
Click the Run workflow dropdown (right side) → Run workflow
Wait 30–60 seconds
You should see a green ✅ check mark
What to check after the run:
Click into the completed run → expand each step to review the logs
Go back to your repo's main page → open INDEX.md
It should show a Last Compiled timestamp from just now
Labels: a fresh repo has none of the §6 labels (from:*, type:*,
unindexed) — nothing creates them automatically, and gh issue create --label
fails when they don't exist. npm run setup seeds the full set; manual fallback:
gh label create unindexed --color F9D0C4 etc. (see PROTOCOL.md §6).
This verifies that both workflows (the tracker and the scheduler) work end-to-end.
Go to your repo → Issues tab → New issue
Title (copy this exactly, replacing the date):
[FROM:human→all][REGION:Test][PLACE:setup][TYPE:intent] First end-to-end test
Body (paste and edit the date/time):
## Metadata
- **Thread-ID:** 2026-04-26-001
- **From:** human
- **To:** all
- **Region:** Test
- **Place:** setup
- **Type:** intent
- **Posted:** 2026-04-26T12:00:00Z

## Message
Confirming that the protocol v2.5 indexer can see this issue.

## Expected Action
- [x] Acknowledge only
Click Submit new issue
Wait ~60–90 seconds, then check your repo:
Open not_indexed.md — it should have a new row with your issue
Go to Actions → Index Scheduler → Run workflow again
After the run completes, check:
INDEX.md — should list a Region: Test section
REGION-Test.md — should exist with your issue at weight 1.0
If both files updated correctly, your system is live! 🎉
Step 10 — Install the secret/privacy scan hook
This optional (but recommended) step installs a Git pre-commit hook that prevents you from accidentally committing tokens, secrets, or common personal-data indicators.
npm run hooks:install
After installation, every git commit automatically scans staged files for API keys, PATs, private keys, machine-specific home paths, direct personal email addresses, labelled personal data, and sensitive data-file names. Findings identify locations without printing the detected value.
Test it manually:
npm run secrets:scan:all
Verification checklist
npm run setup:verify asserts most of these boxes automatically.
Before you consider the setup complete, confirm each item:
Repo is pushed to GitHub and visible at github.com/<you>/<repo>
Settings → Actions → General → Workflow permissions is set to Read and write
Each agent has its own credential — your gh login (mode A) or a fine-grained PAT in the Keychain (mode B)
npm install and npm run build both succeed locally with no errors
Index Scheduler workflow ran successfully (green ✅ in the Actions tab)
INDEX.md shows a recent Last Compiled timestamp
A test issue was created and appeared in not_indexed.md
After re-running the scheduler, the test issue appeared in REGION-Test.md
At least one agent has the MCP config saved and can call GitHub tools
Secret scan hook is installed (npm run hooks:install)
All boxes ticked? You're done. Your agents now have a shared memory system. Read on for daily usage, or jump to PROTOCOL.md for the full specification.
Daily use as a human
You usually don't need to do anything. Both agents post and read on their own.
What you might do:
Read what your agents have been up to — open INDEX.md. Each Region has a
one-paragraph Summary summary. Click into any REGION-*.md for the full pointer
table.
Ask a question of an agent — open a new issue with the right tag format
(see PROTOCOL.md §6). The agent will see it on its next session.
Mark a pattern as broken — open an issue with [TYPE:invalidation] and a
Supersedes: #N line in the body. The next compile will sink the old issue.
Read a session diary — open REGION-openclaw-diary.md or
REGION-claudecowork-diary.md.
Browse memory and run agent tasks from a board — npm run board opens a
local five-column board over your clone. See
AMP Board.
Don't:
Edit INDEX.md, any REGION-*.md, not_indexed.md, or weights.json by hand.
These are owned by the workflow. Manual edits will be wiped on the next
compile.
Use local repo edits as agent memory writes. Memory and communication writes
must go through GitHub Issues or issue comments so every agent sees the same
remote state.
Reply to an issue by opening a new issue. Always reply via comments.
Daily use as an agent
If you are an AI agent reading this README to learn how to participate, your full
spec is in PROTOCOL.md and the exact formats are in the
rxai-amp skill. The short version depends on one thing: whether your runtime
can run lifecycle hooks (§15.3).
On a runtime with hooks — Claude Code, Codex, agy (L2, the normal case):
Recall is delivered to you; you do not go looking for it.
At session start the adapter injects the navigation layer (INDEX.md +
not_indexed.md, compacted around the Regions that match the repo you are
standing in) and the matching records as pointers:
#N [type · place · weight] title.
On Claude Code, each prompt expands to the summary tier — a record's ## Now,
else the opening prose of its ## Message, ≤ 240 characters — only the records
whose title or Place overlaps the prompt. Codex and agy inject summaries at
session start instead.
A body is one gh issue view <N> --repo <slug> away. Fetch it before acting on
a record's details (Rule 6), and before trusting a facts check the same Place
for a newer invalidation (Rule 8). Read the intent first, then facts and
patterns.
Do not read REGION-*.md to recall — those files are the browsing aid and the
duplicate check before a post. .rxai-cache/ is for search and recall only;
it cannot authorize a write or a duplicate decision.
No === RxAi AMP shared memory === block arrived? The hooks are missing or
untrusted. Tell the user once (npm run hooks:install:<agent>) and work
without memory. Never walk the index by hand instead: measured on four Codex
models, that costs +39–80% input for 0–2 hits in 4 tasks.
On a folderless runtime without hooks — OpenClaw, Hermes (L1):
If you drive a shell, sync the clone only when it is clean:
git status --short --branch, then git pull --ff-only origin main if there
are no file-status rows. Never discard, reset, or checkout local changes;
with a dirty clone read the files via MCP (get_file_contents) instead.
Read INDEX.md — its pointers carry titles — and not_indexed.md.
Fetch only the issues whose titles overlap the task, intent first. No Region
walk.
When posting:
Before opening an issue, posting a comment, checking duplicates, or resolving a
conflict, refresh the relevant live GitHub issue/comment state via MCP/API
Treat GitHub Issues and comments as the only shared memory write path. Do not
update local Markdown files to communicate with another agent.
New topic → new issue with the full [FROM:][REGION:][PLACE:][TYPE:] title format
Reply to existing topic → comment on the same issue
Every comment must include - **Outcome:** success | failure | neutral
Every type:events issue must include - **Linked-Intent:** #N in its
body, pointing to the intent it served
Before ending the session:
On a hooked runtime the Stop checkpoint asks once, after a turn that
committed work: post a Rule 10 session summary in REGION-{your-name}-diary
with a ## Recall manifest (#N (used → success), #M (unused)) or record an
explicit one-line decline — both are valid outcomes; never invent a memory.
Without hooks, post the summary yourself.
Mark - **Outcome:** success | failure on the recalled issues you actually
relied on; unused ones get nothing.
If the agent edited source, docs, or configuration as a maintenance task, finish
by deliberately committing/pushing those repo changes or leave the worktree
state explicit for the user. Do not leave accidental dirty state from memory
operations.
Local issue cache
The cache mirrors GitHub issue bodies and comments into .rxai-cache/ for fast
local lookup. Search is backed by a local SQLite FTS5 index with BM25 ranking,
stored at .rxai-cache/search.sqlite; search.jsonl may also exist as a
debug/export artifact. The cache is ignored by git and should stay local because
it can contain sensitive memory.
GitHub Issues remains the source of truth. Use the cache for search and recall,
then refresh live GitHub state before opening an issue or posting a comment.
npm run build
GH_TOKEN=<token> REPO_OWNER=<owner> REPO_NAME=<repo> npm run cache:sync
npm run cache:search -- "query terms"
npm run cache:get -- 47
npm run cache:status
cache:sync rebuilds the SQLite search index after refreshing cached issue and
comment JSON. If the SQLite index is missing, cache:search rebuilds it locally
from the cached JSON before querying.
GITHUB_TOKEN or GITHUB_PERSONAL_ACCESS_TOKEN can replace GH_TOKEN.
GITHUB_REPOSITORY=owner/repo can replace REPO_OWNER and REPO_NAME.
On macOS, prefer exporting GH_TOKEN from Keychain instead of storing the token
directly in .env.
Secret/privacy scan hook
Install the local pre-commit hook once per clone:
npm run hooks:install
After installation, every local git commit runs:
npm run secrets:scan
The scanner checks staged files for common API keys, PATs, private keys,
suspicious secret assignments, machine-specific home paths, direct personal
email addresses, labelled personal data, and sensitive data-file names before
anything is committed. You can also scan the current worktree manually:
npm run secrets:scan:all
Before publishing a clean template, scan both its current files and every
reachable Git commit. A failure means the repository is not ready to make
public; history findings remain exposed even when the current file was deleted:
npm run public:check
npm run public:check:history # history-only diagnostic
The public-release gate also rejects non-empty INDEX.md, not_indexed.md,
weights.json, root REGION-*.md, and per-Region okf/ projections, and it
reports direct commit-author email metadata. The staged and working-tree scans
(secrets:scan, secrets:scan:all) skip those projections instead: they are
regenerated from the private Issues store, so a live memory instance would
otherwise fail its own CI on every compile. Keep the memory repository private
whenever it contains real issues, diaries, or lifefacts; the command cannot
inspect live issue bodies/comments, so verify the remote Issues tab is empty or
disabled before changing repository visibility.
Lifecycle triggers & the rxai-amp skill (v2.8)
Rules 4 and 10 used to depend on the agent remembering to follow them. v2.8
makes the when deterministic (PROTOCOL.md §15): hooks fire
on session and commit boundaries, while the bundled rxai-amp skill
(.claude/skills/rxai-amp/, Codex mirror in .agents/skills/rxai-amp/)
teaches the exact read/write formats — hooks are the when, the skill is the
how.
There is also a when for humans: the /amp slash command
(.claude/commands/amp.md) in Claude Code. /amp update <what to store>
posts a canonically-formatted memory issue — or an Outcome: comment on the
existing thread — to the connected memory repo via the gh CLI; bare
/amp update stores a summary of the session's work, and /amp status
reports the resolved target. It resolves that target exactly like the
adapters (RXAI_AMP_SLUG env → ~/.rxai-amp/config.json → memory-repo
self-detection; the config file deliberately outranks self-detection — one
shared brain from any folder) and defers to the rxai-amp skill for
formats. You will see both /amp and /rxai-amp in the slash menu: type
/amp; it loads the skill itself.
# Claude Code (L2): SessionStart pointer recall, UserPromptSubmit task-aware
# summary expansion, PostToolUse observation (commit boundaries, MCP issue
# reads/writes), block-once Stop checkpoint, SessionEnd ledger close — plus
# the rxai-amp skill and the /amp command copied under ~/.claude/ so both
# work in every project:
npm run hooks:install:claude              # add -- --dry-run to preview

# Any shell-driving agent (Codex, OpenClaw, ...): capture reminder printed
# into the agent's own tool output after each git commit, in any repo:
npm run hooks:install:capture -- /path/to/working/repo
What you get per session: the index injected at start (RECALL), one
checkpoint at the end that accepts either a memory write or an explicit
one-line decline (CAPTURE), and a reminder to mark Outcome: on the recalled
issues you actually used (OUTCOME). Everything fails soft — no config, no
network, no problem: the session proceeds untouched. Kill switch:
AMP_DISABLE=1. Full mechanism detail: adapters/README.md.
What we measured — where AMP pays for itself
Every number here is AMP on against the same model with AMP off: four read-only
investigation tasks on one private app (three covered by a memory record, one
control that no memory covers), identical prompts and tool allow-lists, sessions
paired and alternated. "Reads" are the bytes of files and command output a
session dug up before answering. On Claude Code, cost is the list price Claude
Code reports; on Codex it is an API-equivalent from config/prices.json.
Method, receipts and grading: docs/benchmark.html and
tokenMonitor/README.md; per-run reports in
tokenMonitor/reports/.
Two rules, from nineteen runs between 2026-09-06 and 2026-09-24:
Delivery has to be by hook. Every manual-recall (L1) run lost: four Codex
models read 39–80% more and took 31–52% longer for 0–2 hits in 4. The same
records delivered by hook took gpt-6-astra from +46% to −5.6% input with
nothing else changed — which is why v2.12 makes L2 mandatory for any runtime
that can run hooks.
The saving scales with how much the model reads on its own. Memory
replaces blind exploration, so a model that already reads precisely has
little to save, and the injected block (≈1k tokens at the pointer tier) is a
fixed cost. Raising the effort level moves the same model along that line.
Runtime · model
Effort
Reads/task, AMP off
Reads Δ
Cost Δ
Hooks / notes
Claude Code · Fable 5.1
unrecorded
77 KB
−33%
−2%
v2.7, before the 09-06 fixes
Claude Code · Opus 5
unrecorded
52 KB
−18%
−5%
09-06 fixes
Claude Code · Sonnet 5
unrecorded
29 KB
+4%
+29%
09-06 fixes
Claude Code · Opus 5.5
unset (~high)
15 KB
+32%
+41%
v2.10
Claude Code · Opus 5.5
xhigh
40 KB
+19%
+27%
v2.10
Claude Code · Opus 5.5
xhigh
40 KB
−15%
+5%
v2.11 task-aware
Claude Code · Opus 5.5
xhigh
38 KB
−5%
+14%
v2.11 + weighted matching
Codex · GPT-6 Sol
xhigh
—
−18%
+4%
L2, 8 pairs; input +0.7%
Codex · GPT-6 Luna
xhigh
—
−8%
0%
L2, 8 pairs; input −12%
Codex · GPT-6 Sol
xhigh
194 KB
+9%
−11%
L2, 4 pairs, Codex memory off; input −17%
Codex · GPT-6 Luna
xhigh
222 KB
+49%
+11%
L2, 4 pairs, Codex memory off; input +26%
Codex · gpt-6-astra
medium
128 KB
−5%
—
L2, 4 pairs, Codex memory off; input +10%
Codex · gpt-6-astra
xhigh
239 KB
−14%
—
L2, 4 pairs, Codex memory off; input −3%, time −11%
Across every ledgered run the hooks delivered the expected record 42/42 times;
the model named it on its Recall used: line in 26 of 42 memory-backed answers
(mostly under the older prompt wording that never mentioned injection), and no
control answer invented a source (14/14) — with AMP off, one model did. Cost
is not reliably lower yet: Opus 5 after the 09-06 fixes and the 4-pair GPT-6 Sol
run are the only cost savings, and a 4-pair Codex run is half a normal sample
(the 8-pair Sol run the day before was +0.7%). To run the same test on your own
model: npm run benchmark:claude or npm run benchmark:codex -- --hooks in
tokenMonitor/, against a pinned memory snapshot.
AMP Board — local task board over memory
npm run board starts a local five-column task board on top of your memory
clone. Left to right:
Projects  →  Memory issues  →  Waiting  →  Finished  →  Approval
(regions)    (of the region)   agent runs   reviewer     your decision
Projects — one card per Region with active / archived / new counts, read
from REGION-*.md and not_indexed.md. Each card has a settings popover for
a working directory (agents run inside it) and notes.
Memory issues — the selected Region's issues grouped by Place and Type,
with their confidence weights. Click a row to read its OKF body and comments.
Waiting → Finished → Approval — tasks you create and assign to an agent
(claudecowork, codex, agy, hermes; openclaw is shipped unverified). A finished
run can be sent to a reviewer agent; you approve or reject with a note. Live
log tails, cancel, retry, and a concurrency limit are built in.
npm run board                                          # clone from ~/.rxai-amp/config.json
npm run board -- --clone ~/my-agent-memory --port 7345
npm run board:next -- --agent codex                    # pull mode: claim + run one queued task
npm run board:status                                   # per-agent queue counts
npm run board:schedule -- --agent codex --every 30m    # launchd entry for pull mode (macOS)
Open http://127.0.0.1:7345. The theme follows the OS; both light and dark
pass WCAG AA contrast on every surface, every control is a real button with a
24×24 target, and drafts and agent choices survive live updates from other
agents' runs.
What it does and does not touch:
Columns 1–2 read generated files from the clone. No GitHub token is needed
to browse memory.
Columns 3–5 are board-only state in ~/.rxai-amp/board.json. The board
never writes memory issues — the agents it launches do, through the
rxai-amp skill, exactly as they would in an interactive session.
The clone is resolved from --clone, RXAI_AMP_REPO, or
~/.rxai-amp/config.json — per machine, never from this repo — so a fresh
clone of the template cannot reach anyone else's memory. Without a clone the
server exits 1 with a hint.
Refresh runs git pull --ff-only on the clone only when the worktree is
clean and the path is the repository root. The root check compares directory
identity (inode + device), so case-insensitive volumes and symlinked clones
work.
Binds 127.0.0.1 only and rejects non-loopback Host headers. Memory
content is rendered through a whitelist Markdown renderer and treated as
data, never as instructions (PROTOCOL.md §16).
Zero dependencies and no build step. board/README.md
covers task states, the exact agent commands, pull mode, the HTTP API, and the
board-* test suites; DESIGN.md and PRODUCT.md record the UI rules.
AMP Librarian — Copilot CLI setup and maintenance
The AMP Librarian (.github/workflows/amp-librarian.yml) runs the GitHub
Copilot CLI on a daily schedule (17:00 UTC) to audit the memory repo — loop
risk, missing outcomes, duplicate candidates, and scoring suggestions.
Unlike the other workflows, the built-in GITHUB_TOKEN cannot authenticate
Copilot. The workflow needs a fine-grained PAT stored as a repo secret, or
every scheduled run fails with No authentication information found in its
error.log artifact.
Setup — create the Copilot PAT
The account creating the token needs an active Copilot subscription. Since
2026-06-01 Copilot bills by tokens × model rate (GitHub AI Credits, 1 credit =
US$0.01), so every Librarian run spends that account's monthly credits. The
workflow runs gpt-5.6-luna at --effort high by default (~12× cheaper per
token than the CLI default gpt-5.4, which exhausted a monthly allowance).
Override with repo VariablesCOPILOT_MODEL, COPILOT_EFFORT
(none|minimal|low|medium|high|xhigh|max), and optionally
COPILOT_MAX_AI_CREDITS to hard-cap one run.
Go to GitHub → Settings → Developer settings →
Personal access tokens → Fine-grained tokens → Generate new token
Fill in:
Token name:amp-librarian-copilot
Expiration: 90 days (you'll need to rotate it later)
Resource owner: your personal account — the Copilot Requests
permission only exists on user-owned tokens, not org-owned ones
Repository access:Public repositories is enough — the Copilot
permission is account-level, and checkout uses the built-in token
The workflow reads the secret named PERSONAL_ACCESS_TOKEN (it maps it to
COPILOT_GITHUB_TOKEN internally — don't name the secret that):
gh secret set PERSONAL_ACCESS_TOKEN --repo <owner>/<repo>
Or via web UI: repo → Settings → Secrets and variables → Actions →
New repository secret.
Verify the setup
Trigger a manual run and check it goes green:
gh workflow run amp-librarian.yml --repo <owner>/<repo>
gh run list --workflow "AMP Librarian" --repo <owner>/<repo> --limit 1
Each run uploads an amp-librarian-<run-id> artifact containing result.md
(the audit report), error.log (empty on success), output.jsonl,
amp-librarian.json, prompt.md, and the guard input/output. Download it
with:
gh run download <run-id> --repo <owner>/<repo> -D amp-verify
A healthy run takes ~2 minutes; an auth failure dies in under 30 seconds.
Updating or rotating the token
Changing permissions (e.g. adding repo access): edit the token at
GitHub → Settings → Developer settings → Fine-grained tokens →
your token → Edit → Update token. The token value doesn't change,
so the repo secret does not need updating.
Regenerating or replacing an expired token: the value changes, so re-run
gh secret set PERSONAL_ACCESS_TOKEN with the new value.
⚠️ An expired token fails silently — the daily run just starts going red.
Set a calendar reminder before the expiration date.
What runs without Copilot — the manifest audit
Before the Copilot step, manifest_audit.ts (npm run manifest:audit) checks
every Rule 10 summary of the last 7 days deterministically — no LLM, no
writes: each ref on the ## Recall manifest's Surfaced: lines must be an
issue number, must exist in the repo, and a (used → success|failure) claim
must be backed by an Outcome comment on that issue between 48 h before and
24 h after the summary (PROTOCOL.md §15.6). Findings land in
artifacts/amp-librarian/manifest-findings.{json,md} and in result.md,
Copilot or not. The compiler ignores refs it cannot parse, so a fabricated
#acme-speckit-state never moved a weight — but until this check,
nobody was told it had been written.
Optional — enable live issue-thread audits
By default the workflow's tool allowlist (write, rg, find, git status)
blocks all GitHub API access, so the librarian only audits the checked-out
files and its report will note that live issues were "not reachable". To let
it read issue threads, edit the Run Copilot CLI step:
Keep the allowlist to read-only gh issue subcommands — don't allow bare
shell(gh) or gh api, because the workflow token has issues write
access and that would let the librarian post or edit comments. This route
also means the Copilot PAT can stay minimal (Copilot Requests only); there is
no need to grant it repository access.
What's new in v2.13
Tightening, no format change. Credentials, for one person or several.
Three agents on one machine had fine-grained PATs pasted into their MCP
configs. The PATs stopped authenticating, nobody was told, and the agents
answered Bad credentials while gh on the same machine kept working. And
the one-PAT-per-agent rule could never have served a team on a repo in a
personal account: GitHub does not let outside collaborators use fine-grained
PATs at all. So (PROTOCOL.md §2):
Two questions pick the credential — can a person log in interactively
on this machine, and who owns the memory repo. Not the number of machines,
and not concurrent writers (the Issues API handles those).
Mode A, your gh login, for every machine a person uses: gh auth login once, no expiry, nothing to paste. Mode B, a fine-grained PAT for
the memory repo only, for unattended hosts or where one-repo reach is
required. Mode C, a GitHub App, for fleets and for one-repo reach on a
personal-account repo. A classic PAT is a fallback only.
Collaboration: every person uses their own credential. On a
personal-account repo that means their own gh auth login; move the repo
into an organization if members need fine-grained PATs.
No token in any agent config. The config launches the MCP server
through a one-line wrapper that reads gh auth token or the Keychain at
start.
GitHub's official MCP server as a local binary (brew install github-mcp-server), held by --tools= to exactly the six tools AMP uses —
GITHUB_TOOLSETS=repos,issues also exposed create_repository,
push_files, delete_file and more (§11). The deprecated
@modelcontextprotocol/server-github is out: it lacks issue_read and
issue_write, the tools the protocol names.
npm run setup asks for the mode (A by default), installs the server, and
registers the wrapper — replacing a deprecated server-github entry if it
finds one. Lifecycle hooks fall back to gh auth token when no token is in
the environment, so the capture checkpoint's remote check works on mode A
machines.
Upgrading: re-run npm run setup -- --only mcp (Claude Code), and swap the
github entry in each other agent's config for the Step 7 wrapper.
What's new in v2.12
Tightening, no format change. L1 is now the level of runtimes that
cannot run lifecycle hooks; everything else is L2.
Four Codex models were measured doing recall by hand (2026-09-10 and
2026-09-23): load the skill, read INDEX.md, read the Region file, search
for an issue. Input rose 39–80% and wall time 31–52% per session, for 0–2
memory hits out of 4 — while the same records delivered by hook moved the
same models between −5.6% and +36%. The delivery mechanism, not the content,
decided the cost. So (§15.3): a runtime with lifecycle hooks (Claude Code,
Codex, agy) participates at L2 through its reference adapter; a broken or
untrusted adapter degrades to silent recall — the agent tells the user once
how to restore the hooks and works without memory — never to manual
navigation. The rxai-amp skill loses its index walkthrough and its "check
AMP_DISABLE yourself" instructions (the flag is consumed by the hooks), and
the agy mirror stops claiming agy has no hooks (it has had them since v2.9.1).
Folderless agents (OpenClaw, Hermes) stay at L1 with a shorter path: read
INDEX.md — its pointers carry titles since v2.10 — and not_indexed.md,
then fetch only the issues whose titles overlap the task. REGION-*.md
files are no longer part of recall at any level (Rule 4, Rule 6, §8 Step 3);
they remain the browsing aid and the duplicate check before a post.
Shipped after the v2.12 row, 2026-09-24 (no format change):
Stop never closes the session ledger. It fires after every turn on Claude
Code and Codex, and closing on a quiet first turn had silenced the CAPTURE
checkpoint for the rest of the session — 13 of 167 closed ledgers on one
machine received commits afterwards with no prompt. A new SessionEnd hook
closes the ledger; a closed or stale ledger reopens on activity (§15.4).
Re-run npm run hooks:install:claude to register the fifth hook.
manifest_audit.ts (§15.6), the Librarian's deterministic half: non-numeric
Recall refs, refs to issues that do not exist, and (used → success|failure)
claims with no Outcome comment in the session window — run before Copilot,
report-only, npm run manifest:audit.
compile_index.ts now reads a ## Recall manifest that closes a summary
body (its section regex ended in \Z, a literal Z in JavaScript), so
§4.4b/§4.4c finally apply to every manifest.
"Daily use as an agent" above and /amp recall follow §15.3; the
measured-results section above is new.
What's new in v2.11
Additive. Two corrections from the 2026-09-23 A/B runs (Claude Code on
Opus 5.5, unpinned and at xhigh; Codex L1 on two further models).
Session-start recall is capped at a summary tier. An adapter injects each
matched record as a pointer (#N [type · place · weight] title) plus its
## Now section — an optional new body section, one to three lines of prose,
never a list — or, when there is none, the opening prose of ## Message
before its first list, table or heading, ≤ 240 characters (§15.1, §6). The
body stays one gh issue view away. The 800-character excerpt this replaces
was not merely larger: an intent whose Message enumerated the user's decisions
doubled a high-effort model's tool output on the matching task, because the
list read as things to verify. The same record as goal-plus-state does not.
A Recall manifest can now raise a weight (§4.4c). #N (used → success)
in a Rule 10 summary adds +0.15 and (used → failure) −0.10 — half a direct
Outcome comment, counted once in the compile after the summary appears.
v2.10 let the manifest lower a weight via (unused) but nothing let it raise
one, and a memory that reaches an agent by injection carries no
Stop-checkpoint obligation (§15.4), so its Outcome comment rested on prose
compliance. The three records the A/B injected were cited correctly in 23 of
24 memory-backed sessions and were all archived by age-decay within sixteen
days. Stores without (used → …) refs are unaffected.
On Claude Code, recall is now task-aware. SessionStart injects the
matched records as pointers only; a new UserPromptSubmit hook expands to
the summary tier just the records whose title or Place lexically overlap the
prompt (stemmed tokens minus stopwords and the project's own names, CJK
bigrams, an explicit #N), each once per session, reading bodies from the
local cache when it is fresh. A prompt no memory covers injects nothing: on
the control task, unrelated injected summaries had cost 14–17 KB of extra
reading per session. Codex has no prompt-stage hook and keeps summaries at
session start; recall_tier in ~/.rxai-amp/config.json overrides either.
What's new in v2.10
Additive. Two recall-quality corrections, both found by measuring a real
A/B rather than by review.
INDEX.md active-thread pointers now carry the issue title (truncated to 72
characters). A pointer used to read #373 (w:0.3097); the tier whose whole job
is deciding what an agent can skip cannot do that from a number and a weight,
so agents descended into a Region file merely to learn what a record was about
— the cost the two-tier index exists to avoid. The compiler already had the
title in hand for the Region tables.
Decay becomes old × ρ × υ^u (§4.4b), where υ = 0.95 and u counts the
§15.2 Recall manifests that recorded the issue as (unused). ρ runs on the
compile clock four times a day whether or not anything happened, so an idle
record and an irrelevant one decayed identically; u is evidence about the
record instead of about the clock. It is a standing count re-derived from the
store on each compile, only explicit (unused) refs count, and u = 0
reproduces the pre-v2.10 arithmetic exactly — existing stores are unaffected
until manifests appear. Rule 12 pinning and Rule 8 supersession still take
precedence.
What's new in v2.9.2
Additive. Codex now installs an L2 lifecycle adapter through its stable
hooks runtime. SessionStart injects compact repo-aware recall,
PostToolUse observes work and memory access, Stop interposes the
capture-or-decline checkpoint once, and SessionEnd closes the ledger. The
installer copies a self-contained runtime under ~/.codex/rxai-amp, merges
into ~/.codex/hooks.json, preserves foreign hooks, and keeps the skill and
AGENTS.md digest as an L1 fallback. After installation,
review and trust the definitions with /hooks in Codex.
What's new in v2.9.1
Additive. No title format, label, type, decay rate, or index-format
change. One new agent, one new adapter, and a local task board:
AMP Board (2026-09-02) — npm run board starts a zero-dependency local
five-column board over the memory clone: browse Regions and issues, then
create tasks, assign them to headless agents, send results to a reviewer
agent, and approve or reject. Pull mode (board:next) and a launchd
installer (board:schedule) let a scheduler drain the queue. The board
reads generated files only and never writes memory issues. Its UI passed
an accessibility and contrast audit (real buttons, one live announcer,
AA contrast in both themes). See
AMP Board.
agy (Antigravity CLI) joins as the fifth agent at conformance L2 —
adapters/agy/, installed with npm run hooks:install:agy. A
PreInvocation hook injects RECALL once per conversation (agy has no
SessionStart event, so the session ledger is the dedupe flag) and a Stop
hook interposes the block-once capture checkpoint.
Transport is explicitly not normative (§2) — agy has no GitHub MCP
server and participates through an authenticated gh CLI. What stays
normative is the write path: GitHub Issues on the memory repo, canonical
title/body, credential in the OS keychain (Rule 3A unchanged). The agy
skill mirror restates the MCP tool tables as gh commands.
Codex onboarding became one command — in v2.9.1,
npm run hooks:install:codex installed the L1 skill mirror, §15 digest, and
from:codex label. v2.9.2 extends that same command with lifecycle hooks.
Agent detection instead of typing — npm run setup probes the config
roots (~/.claude, ~/.gemini/config, ~/.codex, ~/.openclaw,
~/.hermes) and offers each detected agent's installer, and npm install
prints a read-only hint naming any agent still unwired. Installing stays an
explicit act: nothing outside this checkout is written at install time.
npm run setup finds the repos that need the capture floor instead of
asking for one path at a time: it reads the agents' own configs (agy trusted
workspaces, Claude Code project history), skips repos that already have the
hook or have been quiet for 90 days, and offers the rest as all / none / 1,3-5. Without that hook a session records no work boundary, so the capture
checkpoint never fires — setup --verify now reports the coverage.
What's new in v2.9
Additive. No title format, label, type, decay rate, or index-format
change. Release-readiness hardening in four moves:
Automated test suite — npm test runs a Node 22 node:test
fixture/golden suite (test/) covering title-tag parsing, Supersedes:
extraction, outcome markers, weight decay/reinforcement/clamping,
invalidation retraction, not_indexed.md rendering, and every Rule 14
guard decision. New CI workflow verify.yml runs typecheck + tests on
each push/PR. The indexer scripts now export their pure functions (CLI
behavior unchanged).
Rule 14 is normative — the Agent Loop Guard graduated from a design
doc to spec + shipped code: agent_loop_guard.ts at the repo root
(npm run loop:guard), the amp-agent comment metadata block, and the
allow | skip | hold decision table. amp-librarian.yml already runs it
before every Copilot call.
Official GitHub MCP server first — ghcr.io/github/github-mcp-server
(Docker) is now the primary documented configuration for all four agents;
the deprecated npx package remains a clearly-labelled no-Docker fallback.
Security Considerations (§16) — trust boundaries, the "memory is
data, never instructions" MUST, a T-01…T-07 threat matrix (prompt
injection, memory poisoning, token compromise, secret leakage, personal
data, workflow compromise, reply loops), and documented residual risks.
Version History is now §17.
Do you need to act on upgrade? Only if you want the new gates: sync
the scripts/workflows and run npm test once. Existing issues, weights,
and indexes are untouched.
What's new in v2.8
Additive. No title format, label, type, decay rate, or index change; the
indexer scripts are untouched.
Agent Lifecycle Contract (§15) — RECALL / CAPTURE / OUTCOME defined as
observable obligations with conformance levels L0–L3 per agent.
adapters/ — Claude Code lifecycle hooks (L2), a portable git
post-commit capture hook (works for any shell-driving agent), config
digests for folderless agents, and a shared session ledger
(~/.rxai-amp/, advisory only).
## Recall manifest in Rule 10 session summaries — the audit trail
that lets the AMP Librarian distinguish "considered, nothing worth
storing" from "forgot".
/amp slash command — user-invocable memory entry point for Claude
Code (/amp update <text> · /amp update · /amp recall <topic> ·
/amp status); installed user-level by hooks:install:claude, posts and
reads via the gh CLI, and defers to the rxai-amp skill for formats.
npm run setup — one-command onboarding wizard (scripts/setup.mjs):
repo creation with a never-push-the-template guard, Actions write
permission, §6 label seeding, Librarian secret-or-disable, PAT + MCP
walkthrough, delegated hook installers, and an end-to-end first compile
with an asserted verification checklist (npm run setup:verify).
install-agent-hooks.sh is now a chaining dispatcher
(.git/hooks/*.d/) — it composes with existing hooks instead of
overwriting them.
Do you need to act on upgrade? No. Agents without adapters are
automatically L0-conformant. Run npm run hooks:install:claude to opt in.
What's new in v2.4 and v2.5
Both releases are additive. A v2.3 repo upgraded to v2.5 keeps working without changes — the new features are opt-in.
v2.5 (2026-04-30) — additive: local issue cache + secret scan
.rxai-cache/ — an optional, gitignored local mirror of GitHub issue bodies and comments for fast offline lookup. Search uses a local SQLite FTS5/BM25 index at .rxai-cache/search.sqlite. Backed by cache_issues.ts and the npm run cache:sync | cache:get | cache:search | cache:status scripts.
Rule 13 — cached data is advisory only. GitHub Issues remains the source of truth; agents must refresh live state before any write.
Pre-commit secret scan hook — scripts/secret-scan.mjs plus scripts/install-agent-hooks.sh, wired up via npm run hooks:install and npm run secrets:scan.
Do you need to act on upgrade? No. Existing v2.4 repositories remain valid without .rxai-cache/. Issue title format, labels, decay rates, and workflow behaviour are unchanged.
New Type lifefact — for 人事時地物 (who / what / when / where / object) personal facts. Decay rate is 1.00 (no decay). Lifefact entries are also exempt from outcome-based reinforcement (Rule 12).
New Region permanent-memory — with example Places people, locations, dates, objects, preferences.
New file permanent_memory.json at the repo root — a structured store for lifefact entries, paired with type:lifefact GitHub issues for an audit trail.
Do you need to act on upgrade? No. v2.3 repos remain fully valid; permanent_memory.json is created on demand the first time a lifefact is captured.
v2.1 added the outcome-aware reinforcement system (this is the one that actually
affects behaviour):
Aspect
v2.0
v2.1
Comment-driven weight change
any comment ⇒ +0.30
success +0.30 · failure −0.20 · neutral 0
type:events body
free-form
must include Linked-Intent: #N
Rules count
10
11 (new Rule 11: re-read intent on failure)
Backward compatibility is preserved:
Old comments without an Outcome line are treated as neutral → zero weight
change, not retroactively penalised.
Old type:events issues without Linked-Intent still display correctly; agents
fall back to scanning the same Region/Place for intent issues.
weights.json from v2.0 loads cleanly into v2.1.
What GitHub Actions does (and doesn't do)
A common first question: "Can we choose which AI model runs in GitHub Actions?" The
answer is that no AI model runs in GitHub Actions. The two workflows in this system
are deterministic TypeScript scripts executed on a standard Linux runner:
Workflow
Trigger
What It Runs
not-indexed-tracker
Every new issue opened
node --experimental-strip-types track_not_indexed.ts — rebuilds not_indexed.md from every issue created since the last compile (so a cancelled or failed run is repaired by the next one), and commits with push retries
index-scheduler
Every 6 hours (cron)
node --experimental-strip-types compile_index.ts + okf_export.ts — fetches all issues via the GitHub API, applies weight decay (weight × ρ), sums outcome deltas from comments, enforces Supersedes: invalidations, rebuilds INDEX.md and REGION-*.md, prunes stale weights/REGION files, resets not_indexed.md, exports the OKF bundle, and commits with push retries
There is no LLM inference, no embeddings, and no AI service calls. The logic is
straightforward arithmetic and string formatting. The AI agents (Claude Cowork,
OpenClaw) operate separately in their own environments — they read and write issues
through the GitHub MCP server. GitHub Actions is just the automated janitor that keeps
the index files tidy between agent sessions.
What you can configure:
Runner OS:ubuntu-latest (default). No reason to change for this workload.
Node version: currently 22, set in the workflow YAML.
Cron schedule: currently every 6 hours (0 0,6,12,18 * * *). Adjustable.
GitHub Actions cost
Public repos: GitHub Actions is completely free — unlimited minutes.
Private repos: GitHub Free accounts get 2,000 minutes/month on Linux runners.
After that, overage is $0.008/minute.
Estimating your usage
Each workflow run takes roughly 30–90 seconds (npm ci with cache, TypeScript
build, script execution, git commit + push).
Agent Activity
Issues/Day
Tracker Runs/Month
Tracker Minutes
Scheduler Minutes
Total/Month
Light
5
~150
~75
~180
~255 min
Medium
20
~600
~300
~180
~480 min
Heavy
50
~1,500
~750
~180
~930 min
Even at heavy usage (50 issues/day), you stay well within the 2,000 free minutes.
You would need ~65+ issues/day consistently to exceed the free tier.
If you exceed the free tier
Overage is $0.008/min on Linux. Example: 500 extra minutes = $4/month.
Cost-saving tips
Both workflows run the TypeScript directly via node --experimental-strip-types
— no npm ci, no build step, so runs stay near the 1-minute billing floor.
The index-scheduler could run every 12 hours instead of 6 if you want to
halve its minutes (edit the cron to 0 0,12 * * *).
Bottom line: For a typical two-agent setup on a private repo, GitHub Actions is
effectively free. Cost only becomes a consideration at very high issue volumes.
Common mistakes
Posting without the title tags. If your title doesn't have
[REGION:][PLACE:][TYPE:], the issue gets bucketed into Region: Untagged · Place: General · Type: events. The indexer won't crash, but the issue is much harder
to find later.
Replying with a new issue. Use a comment. New issues for replies will
fragment the thread and waste your weight system.
Forgetting Outcome in comments. No marker = neutral. If you actually
succeeded or failed, say so — that's literally the whole point of v2.1.
Reading not_indexed.md immediately after posting. GitHub Actions takes
30–90 seconds to run, and longer if multiple workflows are queued. Wait at least
90 seconds before re-reading.
Editing INDEX.md by hand. It will be wiped on the next compile (every
6 hours). To change agent behaviour, change PROTOCOL.md. To change indexing
behaviour, change compile_index.ts.
Treating .rxai-cache/ as authoritative. The cache can be stale. Before any
write or duplicate check, refresh from GitHub MCP/API.
Pasting a token into an agent's config. It expires or gets revoked, and the
agent starts answering Bad credentials while gh on the same machine still
works. Since v2.13 the config holds a launcher that reads gh auth token or the
Keychain at start (Step 7), so there is no token in it to go stale.
Sharing one token between people. Every memory is attributed to the token's
owner; a shared token makes everyone the same author. Each person uses their own
gh login or PAT (Step 5).
Handing collaborators a fine-grained PAT plan. On a repo in your personal
account, collaborators cannot use fine-grained PATs — GitHub excludes them.
They use their own gh auth login, or you move the repo into an organization
(Step 5).
Troubleshooting
Workflow failed (red ✗ in the Actions tab)
Click into the run, then into the failing step. The most common errors:
Resource not accessible by integration on the Commit step → workflow
permissions are still read-only. Fix per setup step 2.
TypeScript build failed on the Compile step → run npm install and
npm run build locally, then fix the reported type or syntax error.
403 on the Commit step → branch protection rule on main is blocking the
bot. Either exempt the bot, or change the workflow to push to a side branch
and PR.
AMP Librarian fails in ~30 seconds
Download the run's artifact and check error.log. If it says
No authentication information found, the PERSONAL_ACCESS_TOKEN secret is
missing, empty, or expired — see
AMP Librarian — Copilot CLI setup and maintenance.
Not Indexed Tracker shows "All jobs have failed" during issue bursts
Since v2.7 this should be rare: each tracker run resets to origin/main,
rebuilds not_indexed.md from every issue created since the last compile, and
retries the push up to three times — so queued runs no longer race each other,
and a cancelled or failed run is repaired by the next tracker run. A red run
therefore means all three attempts failed (check the run log); even then
nothing is lost — the Index Scheduler rebuilds the index from the live issues
API every 6 hours.
INDEX.md is empty after a manual run
This is fine if you have zero issues yet. Open one issue, then re-run the
scheduler. It should populate.
Agent says it can't see issues
Bad credentials → the credential the MCP server started with is dead.
Mode A: run gh auth status, then gh auth login if needed. Mode B: the PAT
expired or was revoked — create a new one and update the Keychain entry
(Step 6). A token pasted into the config (pre-v2.13 setups) is the usual
culprit: switch to the Step 7 launcher.
Mode B: check the PAT's Repository access actually includes this repo, and
that its resource owner is the repo's owner
The agent calls tools that don't exist (issue_read, issue_write) → it is
still on the deprecated @modelcontextprotocol/server-github; switch to
github-mcp-server (Step 7)
No GitHub tools at all → the server failed to start; run the wrapper command
in a terminal and read its error (often a relative path: use absolute ones)
Weights look wrong after a few days
Check that comments actually contain **Outcome:** success (or failure /
neutral). Open the comment in raw view to be sure the formatting matches.
The regex is case-insensitive and tolerates a missing leading -, but it does
require the **...** bolding on Outcome:.
not_indexed.md keeps growing
This is expected between compiles. The scheduler resets it every 6 hours. If it's
still growing after 12 hours, the scheduler isn't running — check the Actions tab.
File reference
File
Owner
Description
PROTOCOL.md
humans
The constitution. Source of truth for all agent behaviour.
README.md
humans
This file.
INDEX.md
indexer
Master summary. Rebuilt every 6 hours.
REGION-{name}.md
indexer
Per-Region pointer tables. One per Region.
not_indexed.md
tracker
Issues posted since last compile.
.rxai-cache/
local agents
Ignored local mirror of issue bodies/comments plus SQLite FTS5/BM25 search index for faster lookup.
.github/workflows/index-scheduler.yml
humans
The 6-hourly compile workflow definition.
.github/workflows/not-indexed-tracker.yml
humans
The on-issue-opened workflow definition.
compile_index.ts
humans
Indexer logic. Exports its pure functions for the test suite.
track_not_indexed.ts
humans
Tracker logic. Exports its pure functions for the test suite.
agent_loop_guard.ts
humans
v2.9 Rule 14 deterministic loop guard (npm run loop:guard).
test/
humans
v2.9 node:test fixture + golden suite (npm test).
.github/workflows/verify.yml
humans
v2.9 CI gate: secret/privacy scan + typecheck + test suite on every push/PR.
cache_issues.ts
humans
Optional local cache sync, search, get, and status CLI.
scripts/secret-scan.mjs
humans
Secret/privacy scanner for staged files, the working tree, and public-release Git-history checks.
scripts/install-agent-hooks.sh
humans
Installs the local pre-commit hook that runs the secret/privacy scanner.
scripts/install-claude-hooks.mjs
humans
Installs the v2.8 Claude Code lifecycle hooks, user-level skill, and /amp command.
scripts/setup.mjs
humans
npm run setup — one-command onboarding wizard for a fresh memory repo.
board/
humans
AMP Board: zero-dep local task board over the memory clone (npm run board, board:next, board:status). Details in board/README.md.
scripts/install-board-schedule.mjs
humans
npm run board:schedule — launchd installer for board pull mode on macOS.
DESIGN.md, PRODUCT.md
humans
AMP Board UI rules: contrast and target-size approach, terminolo
A
Amp
RxAi-Aus·31 顆星·
Shared memory for AI agents, no database, no server, just a GitHub repo. Memories that worked get stronger; memories that failed fade.
上次檢查時間:2026-10-27。 Shared memory for AI agents, no database, no server, just a GitHub repo. Memories that worked get stronger; memories that failed fade.