IdeaGauntlet is an open-source CLI and library that turns a raw product idea into adversarial critique, multi-role debate, synthetic user objections, validation plans, and idea comparison.
Built for founders, indie hackers, and product engineers who want sharper pre-validation before spending weeks building the wrong thing.
⚔️ Stress-test your product and startup ideas before writing code. An adversarial AI tool for multi-role debate, synthetic user feedback, and validation planning.
星數
4
工具
—
可用率
—
Most AI tools help you generate more ideas. IdeaGauntlet helps you survive the one you already have.
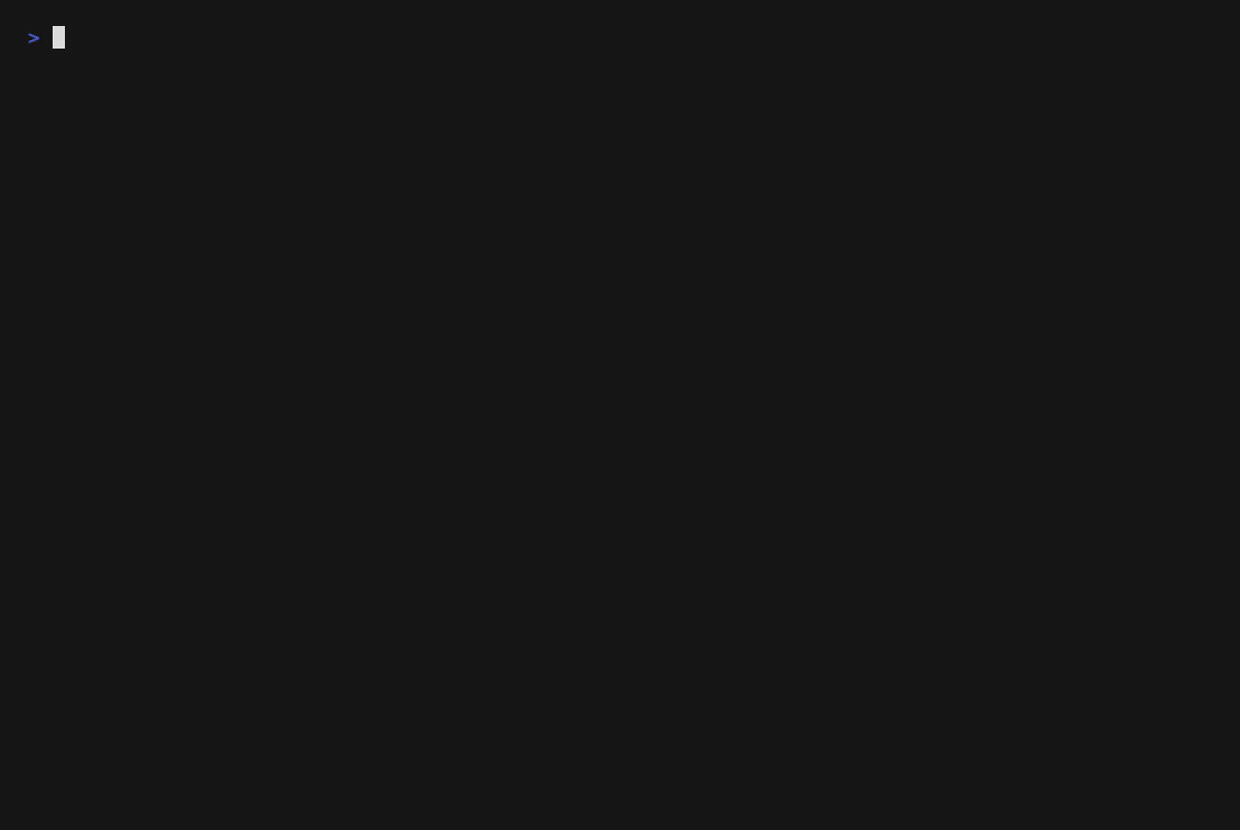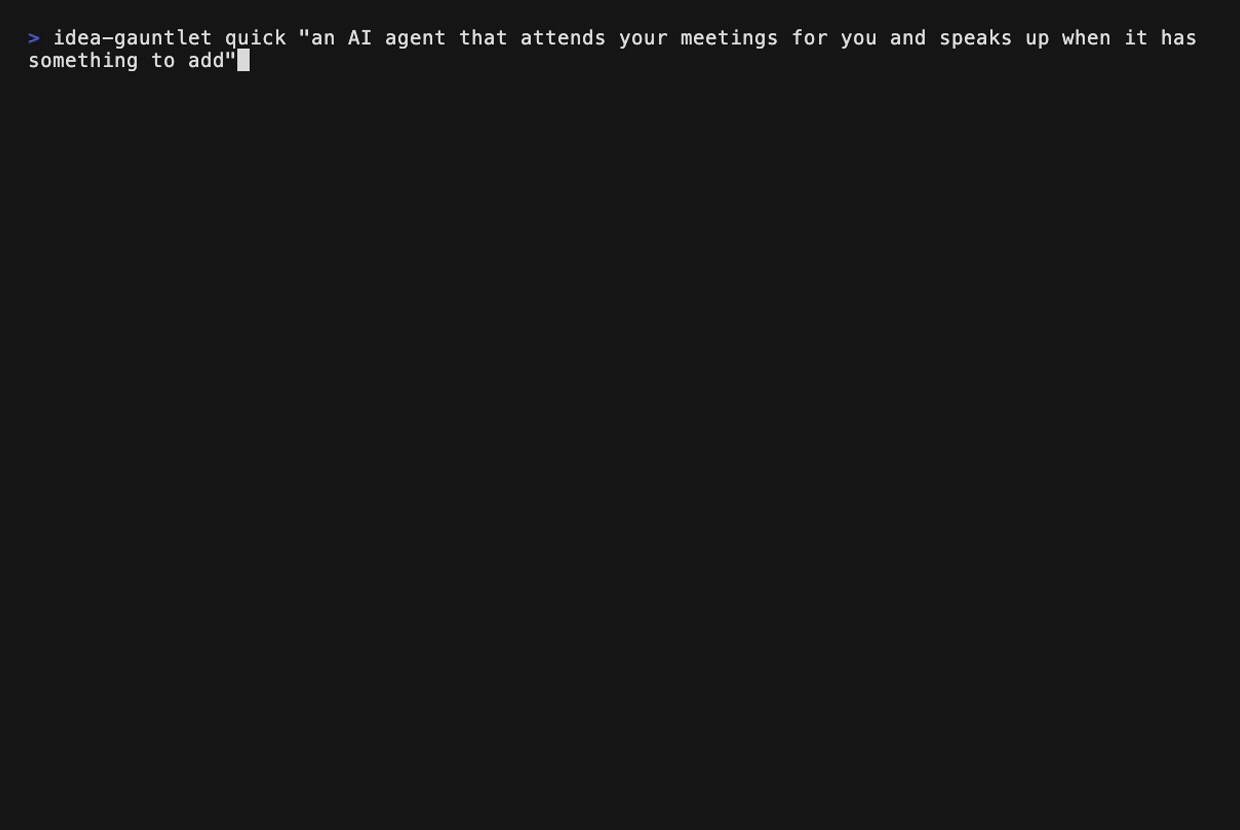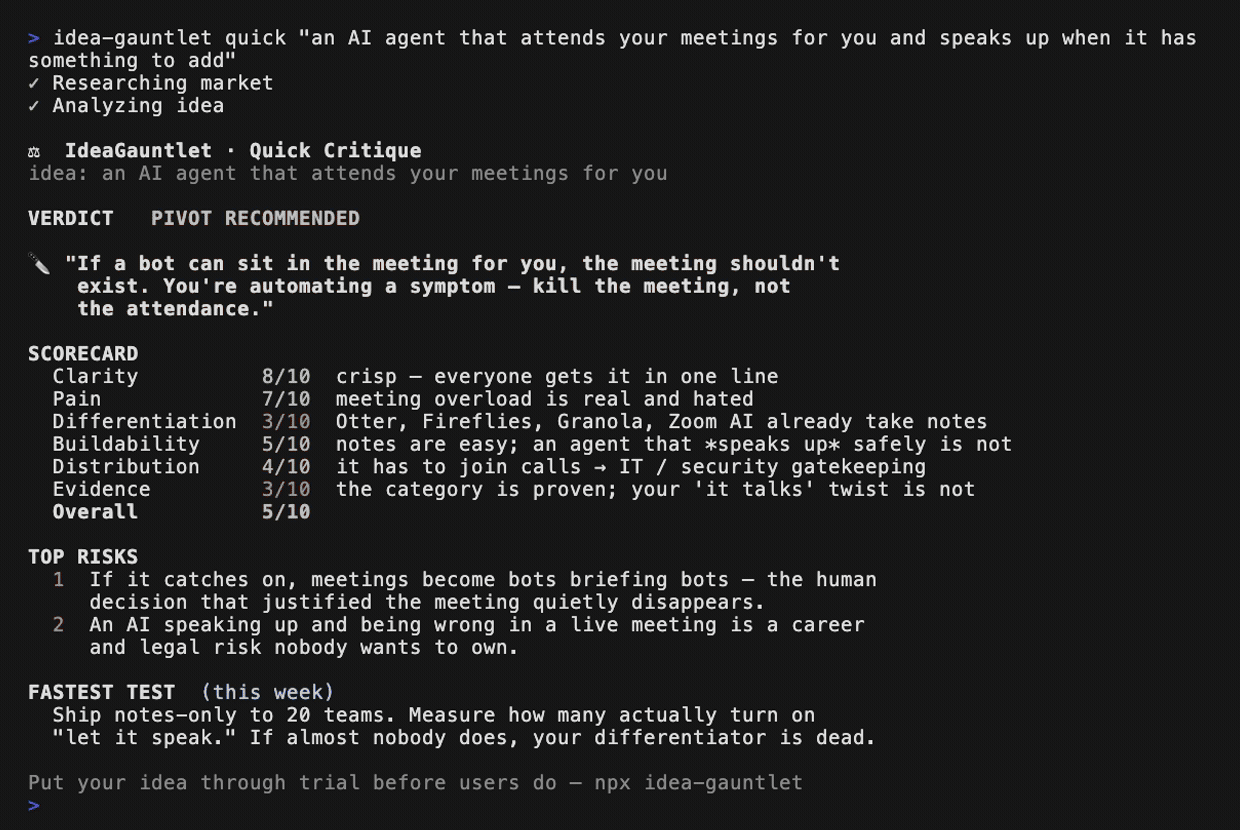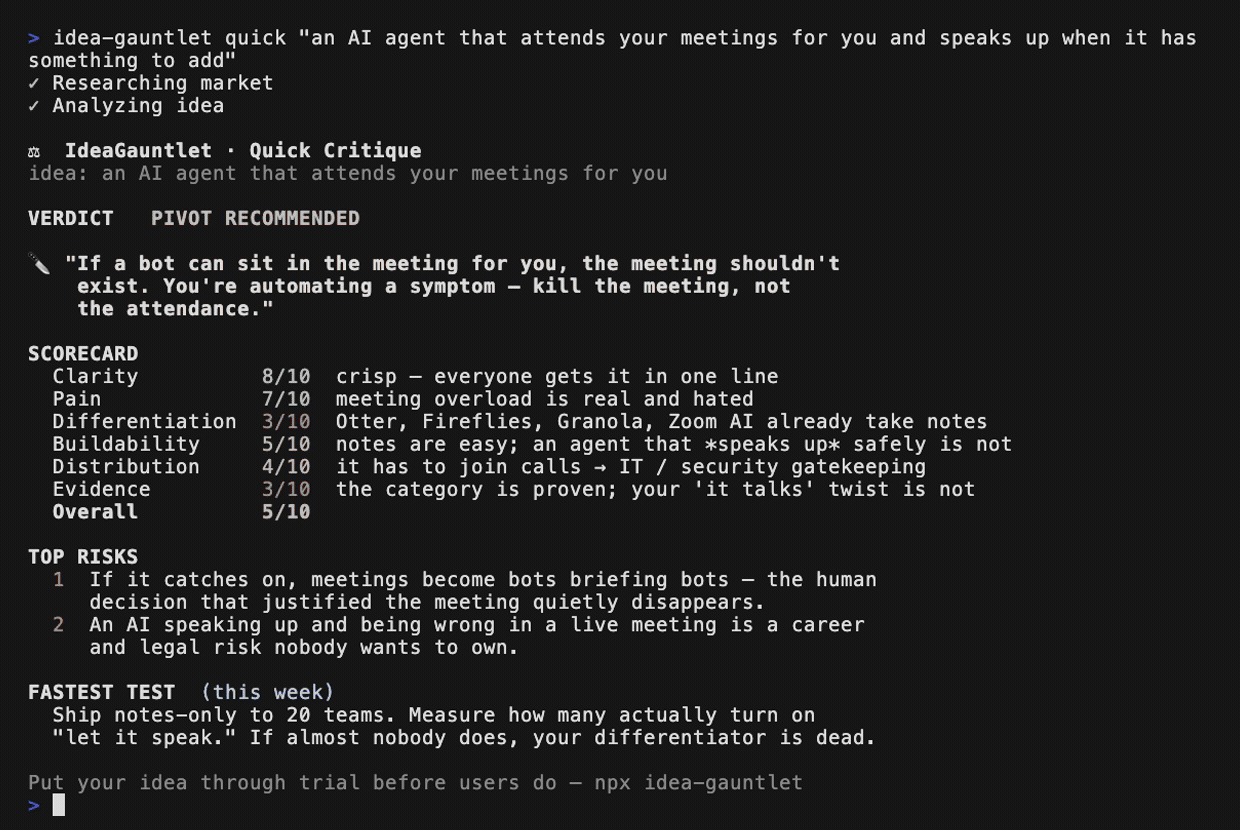
One command gives you a verdict, an evidence-backed scorecard, the risks that actually
kill the idea, and the cheapest test that could disprove it this week.
npx idea-gauntlet quick "an AI agent that attends your meetings for you"
On global install, IdeaGauntlet performs best-effort integration setup for detected Claude Code, Codex, Cursor, and MCP-compatible clients. All writes are non-destructive (never overwriting your files) and fully reversible via idea-gauntlet uninstall. The install downloads no browser and runs no network install; if postinstall was skipped (e.g. --ignore-scripts), run idea-gauntlet install yourself.
Try it
Inside Claude Code / Codex / Cursor
After installing, open your AI coding tool and ask:
Use IdeaGauntlet court mode to stress-test this idea:

A focus-room app for remote workers that pairs people into silent 50-minute work sessions.
No IdeaGauntlet API key is needed. The AI coding tool supplies the model and context. If postinstall did not detect your tool, run idea-gauntlet install later.
Important: Agent-native integrations execute workflows natively. They do not run the idea-gauntlet CLI first. If you type idea-gauntlet court "..." in chat, the assistant treats it as analysis intent, not a shell command.
In the terminal — 30 seconds, no install
One command, nothing to install globally — just an API key:
ANTHROPIC_API_KEY=sk-ant-... npx idea-gauntlet quick "A focus-room app for remote workers"
Groq (GROQ_API_KEY=gsk_...), any OpenAI-compatible endpoint, or local Ollama (--ollama)
work too — see Provider setup.
Get a card you can actually post
Add --format card to any command to render the verdict as a self-contained
1200×630 image (OG / Twitter preview size) — verdict badge, overall score, score
radar, top risks, and the one-line brutal takeaway. Built to screenshot and share:
🔪 Focusmate has done exactly this since 2016 — "FocusRoom" as described is a feature, not a company; without a niche it can't defend, you're volunteering to fight a funded incumbent with a worse version of their product.
Dimension
Score
Evidence
Differentiation
2/10
Focusmate already offers paired 50-min silent coworking since 2016; no stated wedge.
Distribution
3/10
Two-sided cold-start: an empty room is worthless; paid ads can't fix it.
Buildability
8/10
Matchmaking queue + timed video room — a fake-door + manual matching is enough to test.
Core features
Workflow
What it does
Use it when
Output
Assumption ledger
Falsifiable assumptions, each with a kill threshold and the cheapest test that could disprove it
You want to know what to test first, before building
Ordered test plan, kill thresholds, days/cost to de-risk
Score calibration
Marks every score sourced or judgment, and discards citations not found in the retrieved research
You want to know which numbers are evidence and which are guesses
Basis per dimension, evidence ratio, flagged unverified citations
Quick critique
Fast adversarial review: top risks, assumptions, best/worst case, fastest test
You want a fast sanity check
Risks, assumptions, scores, validation test
Court mode
Structured multi-role debate with 7 specialist roles and judge verdict
The idea needs deeper critique
Role arguments, evidence audit, kill tests, scores, verdict
GTM Strategy
Distribution channel priority matrix, 100-customer playbook, launch milestones
Side-by-side scoring across 10 dimensions with per-idea kill tests
You need to choose what to validate
Comparison matrix, tradeoffs, recommendation
Batch mode
Run critique on multiple ideas from a file
You have several ideas to screen
Bulk reports with scores + verdicts
History & evolution
Save reports, track score deltas over time
You want to measure idea improvement
Saved reports, score deltas, evolution timeline
Interactive mode
REPL for iterative refinement, drill-down, mode switching
You want to refine an idea live
Re-runs, benchmark, diagrams, exports
HTML export
Styled dark-mode HTML report with radar chart + diagrams
You need shareable visual reports
Self-contained HTML page
Score benchmarking
Compare scores against a synthetic reference set of 50 idea archetypes
You want rough distributional context for your scores
Percentile ranking, similar archetypes
Synthetic users are fictional — not research evidence. Scores are diagnostic signals, not predictions.
Two things IdeaGauntlet refuses to fake
1. It tells you which scores are evidence, and which are guesses
Most AI analysis tools present a retrieved fact and a confident guess in the same
font. IdeaGauntlet separates them. Every scored dimension is labelled:
Dimension
Score
Basis
Evidence
Differentiation
2/10
sourced
Focusmate has run paired 50-min sessions since 2016
Distribution
3/10
judgment
Two-sided cold start — no source retrieved
A model cannot mark its own work as sourced. It is asked to cite the sources it
used, and those citations are then checked against the research that was actually
retrieved. A citation that isn't there is stripped, flagged as unverified in the
report, and the dimension drops to judgment. Verification can only ever downgrade
a score's basis, never promote it.
Each report then states the ratio plainly:
Evidence-backed: 1/3 scored dimensions ●○○
1 of 3 scored dimensions cite a source found in the research brief; 2 rest on
model judgment alone. 1 claimed citation was not found in the brief and was not
counted as evidence.
When no research is available at all, every dimension is judgment — the report
says so instead of implying grounding it doesn't have.
This applies to both quick and court. Court reaches its scores through a
seven-role debate rather than a single rubric call, but the judge's citations go
through exactly the same verification before any dimension is allowed to read as
evidence-backed.
2. It tells you what would prove the idea wrong, and what that costs
A verdict you can't act on is entertainment. assumptions turns the idea into a
falsification plan — what must be true, the number that declares it dead, and the
cheapest way to find out:
idea-gauntlet assumptions "A focus-room app for remote workers"
#
Assumption
If false
Test
Timebox
Cost
Kill threshold
1
Remote workers will pay $10/mo rather than use a free timer
FATAL
Fake-door landing page + Stripe link
3d
$50
Fewer than 8 of 40 visitors leave an email
2
A new room is never empty at peak hours
FATAL
Manually match 20 volunteers for a week
7d
$0
Under 60% of requested slots get matched
3
IT teams will not block the video room
MINOR
5 IT admin interviews
10d
$0
3 of 5 admins say they would block it
Resolving every fatal assumption: 10 days, $50.
Two design decisions make this useful rather than decorative:
Kill thresholds must name a number. "Low signup rate" is not a threshold;
"fewer than 8 of 40 visitors leave an email" is. Deciding what counts as failure
before running the test is the whole point — it is how you avoid talking
yourself past a bad result.
The test order is computed, not asked for. Ordering is criticality × uncertainty × cheapness, calculated in code. Models are agreeable about
ranking and tend to echo whatever they listed first; arithmetic at least stays
consistent.
If the model returns something unusable, the command fails instead of inventing
thresholds — a ledger of made-up numbers is worse than no ledger.
Quick start examples
# 1. Quick critique
idea-gauntlet quick "A focus-room app for remote workers"

# 2. Go-to-Market strategy
idea-gauntlet gtm "A focus-room app" --budget "$5000" --timeline "90 days"

# 3. Deep competitive intelligence
idea-gauntlet compete "A focus-room app" --depth deep

# 4. Revenue model exploration & pricing tiers
idea-gauntlet revenue "A focus-room app"

# 5. Founder-market fit evaluation
idea-gauntlet founder "A focus-room app" --background "8 years distributed engineer, worked remotely for 3 years"

# 6. AI-simulated customer discovery interview
idea-gauntlet interview "A focus-room app" --persona "Senior Remote Engineer"

# 7. Investor pitch deck draft (YC, Sequoia, a16z)
idea-gauntlet pitch "A focus-room app" --template yc --company "FocusGauntlet"

# 8. Idea evolution & pivot coaching
idea-gauntlet evolve "A focus-room app" --focus monetization

# 9. Regulatory & compliance scanner
idea-gauntlet compliance "A focus-room app" --regions us,eu

# 10. Multi-model ensemble consensus
idea-gauntlet ensemble "A focus-room app" --models "gpt-4o,claude-sonnet-5"

# 11. Trend monitoring (re-research saved ideas)
idea-gauntlet trend <saved-idea-id>

# 12. Court mode (save to file)
idea-gauntlet court "Your idea" --output report.md

# 13. Compare multiple ideas
idea-gauntlet compare "Idea A" "Idea B"

# 14. Export HTML report
idea-gauntlet quick "Your idea" --format html --output report.html

# 15. Batch mode (one idea per line in file)
idea-gauntlet batch ideas.txt --mode quick --output reports/

# 16. Interactive REPL
idea-gauntlet interactive "Your idea"
Agent-native integrations
IdeaGauntlet installs instructions for supported coding tools:
Tool
What gets installed
Claude Code
Skills, agents, slash-commands, MCP config
Codex
AGENTS.md / config bridge
Cursor
Rules per workflow
MCP clients
MCP server config
# Rerun integration setup if postinstall skipped a tool
idea-gauntlet install
Use natural language:
Use IdeaGauntlet court mode and focus on distribution risk:
...
Evidence-aware analysis
Inside tools that provide web/search access, IdeaGauntlet agent-native court mode may perform a brief market evidence scan before the debate. It uses this research to build a research brief, competitor landscape, evidence gaps, and source notes before the judge verdict.
Terminal CLI mode does not guarantee live web browsing. It uses the configured provider and any context you provide.
Provider setup
Direct CLI and MCP generation require a provider. Agent-native workflows do not.
Anthropic Claude (Native):
Simply set your Anthropic API key, or provide a key with the prefix sk-ant- as IDEAGAUNTLET_API_KEY:
export ANTHROPIC_API_KEY="your-anthropic-key"
# Optional model override (default: claude-sonnet-5)
export IDEAGAUNTLET_MODEL="claude-sonnet-5"
Groq (Native):
Set your Groq API key, or provide a key with the prefix gsk_ as IDEAGAUNTLET_API_KEY:
export GROQ_API_KEY="your-groq-key"
# Optional model override (default: llama-3.3-70b-versatile)
export IDEAGAUNTLET_MODEL="llama-3.3-70b-versatile"
Generate a single, self-contained 1200×630 card (OG / Twitter preview size) built to
screenshot and share — verdict badge, overall score, score radar, top risks, and the
one-line brutal takeaway:
Open the file, screenshot it, and post it. The card carries the tool name and install
line, so every share is a link back.
Use in CI (GitHub Action)
Run IdeaGauntlet automatically on every pull request that touches IDEA.md and post the
verdict as a single, auto-updating PR comment — idea review as part of your workflow, like
code review.
A copy-pasteable version lives at .github/workflows/example-idea-gauntlet.yml.
Add your key as a repo secret named IDEAGAUNTLET_API_KEY (Anthropic sk-ant-… or Groq gsk_…) — it is passed via env and never logged.
Interactive mode
Refine ideas iteratively in a REPL:
idea-gauntlet interactive "Your idea"
Commands:
Command
Purpose
/idea <text>
Update idea text
/mode <mode>
Switch mode (quick, court, users, mvp, compare)
/run
Run analysis with current idea + mode
/benchmark
Compare scores to benchmark dataset
/diagram
Generate Mermaid diagram (MVP mode only)
/save
Save report to history store
/export html
Export HTML report
/drill <n>
Drill down into risk #n + optional court re-run
/help
Show available commands
/quit
Exit interactive mode
Score benchmarking
Compare your scores against a synthetic reference set of 50 idea archetypes with illustrative (hand-authored, not measured) outcomes and scores. This gives rough distributional context — it is not real-company data and must not be read as a prediction.
In interactive mode, run /benchmark after analysis to see:
Per-dimension percentile ranking
Overall percentile
Similar ideas from the benchmark dataset
Outcome distribution of similar ideas
Benchmark is a directional guide, not a prediction. Dataset is small and retrospective.
Batch mode
Run critique on multiple ideas from a text file (one idea per line):
Outputs individual reports to the specified directory, or prints all to stdout.
History and evolution tracking
Save reports and track how scores change as you iterate:
# Save a report (use --save flag on any command)
idea-gauntlet quick "Your idea" --save

# List all saved reports
idea-gauntlet history

# View a specific report
idea-gauntlet history <id>

# Compare score deltas between two saved reports
idea-gauntlet history <new-id> --evolve <old-id>
Interactive Court Defense
When running in Interactive mode, you can defend your idea against skeptics in Court mode:
[
  {
    "roleName": " distribution skeptic",
    "perspective": "Question how this reaches users without paid acquisition."
  }
]
Optional project-local setup
Global install is the normal path. To commit IdeaGauntlet instructions into a specific repo:
idea-gauntlet setup --all
Dry run: idea-gauntlet setup --dry-run --all
Maintenance
# Check global install status
idea-gauntlet status

# Rerun integration setup
idea-gauntlet install

# Remove integrations before uninstalling
idea-gauntlet uninstall
npm uninstall -g idea-gauntlet
Development
npm install
npm run typecheck
npm run test
npm run build
npm pack --dry-run
License
MIT
I
IdeaGauntlet
Thuong180702·4 顆星·
⚔️ Stress-test your product and startup ideas before writing code. An adversarial AI tool for multi-role debate, synthetic user feedback, and validation planning.
上次檢查時間:2026-11-12。 ⚔️ Stress-test your product and startup ideas before writing code. An adversarial AI tool for multi-role debate, synthetic user feedback, and validation planning.