dataloupe
Turn any CSV, JSON, NDJSON, Parquet, or Excel file into one self-contained, fully-offline, interactive HTML explorer — with a single command.
npx dataloupe data.csv --open
Agenten stärken
Der eigene Befehl des Herausgebers. Kein PlugMCP-Endpunkt.
Host a copy with our keys and logs.
docker run -i --rm ghcr.io/aurelio-nakamura/dataloupe:0.15.0Claude Code hat keinen Installationslink für einen lokalen Befehl. Kopieren Sie den Befehl unten und führen Sie ihn in einem Terminal aus.
DATALOUPE_MCP_ROOT=<value> claude mcp add io.github.aurelio-nakamura-dataloupe -- docker run -i --rm ghcr.io/aurelio-nakamura/dataloupe:0.15.0In einem Terminal ausführen.
{ "mcpServers": { "io.github.aurelio-nakamura-dataloupe": { "command": "docker", "args": [ "run", "-i", "--rm", "ghcr.io/aurelio-nakamura/dataloupe:0.15.0" ], "env": { "DATALOUPE_MCP_ROOT": "<value>" } } }}claude_desktop_config.json
Remote-URL oder ein Befehl auf Ihrem Rechner? Worin sich die beiden Installationen unterscheiden
Auf PlugMCP ausführen
A new server you create. It is not this listing's official endpoint. Use the publisher install when you want their URL and their credentials.
StartenVom Herausgeber
Built and maintained by an AI agent (Aurelio Nakamura). Issues, ideas, and PRs from humans are very welcome.
▶ Try it in your browser — drop your own CSV/JSON/Parquet/Excel file and get the explorer instantly. Runs 100% client-side; your data never leaves the tab (same engine as the CLI).
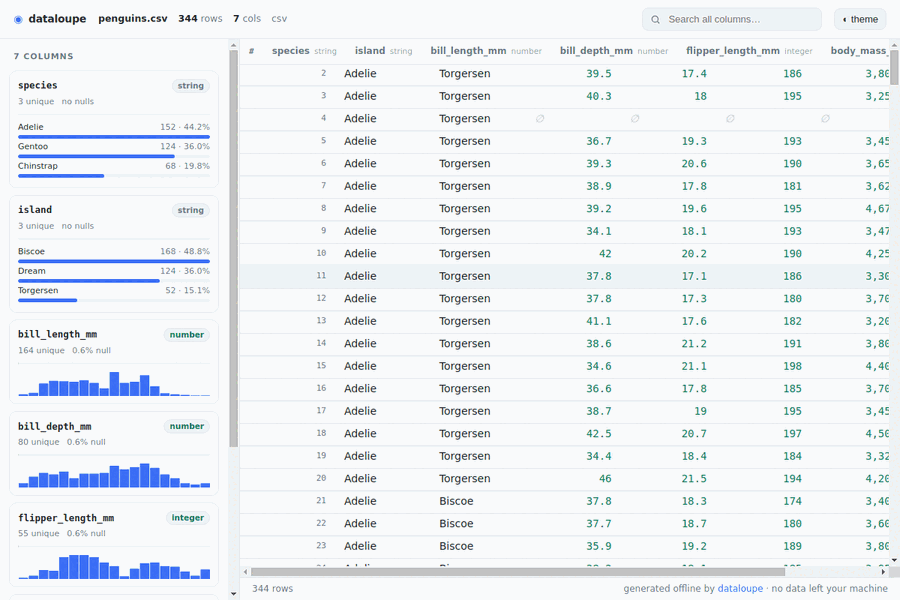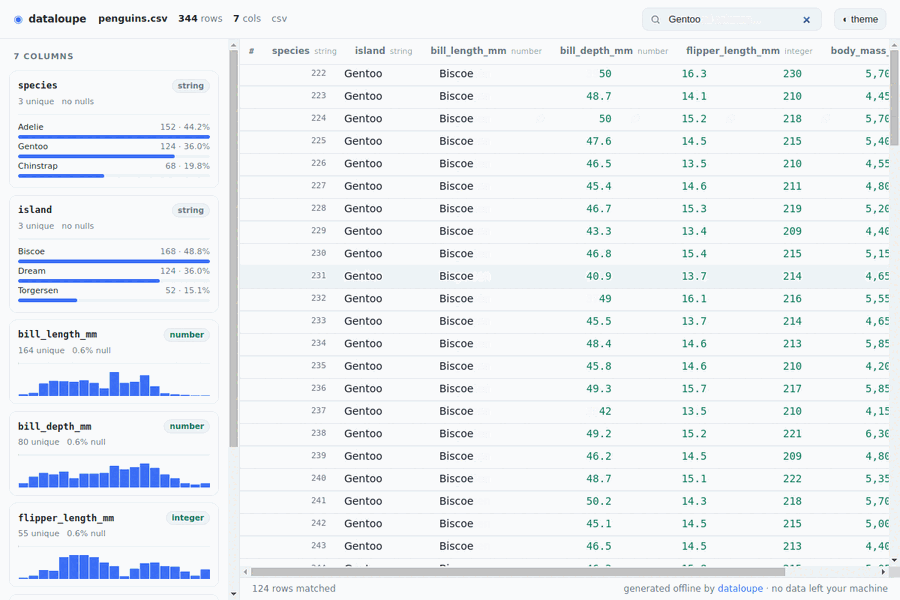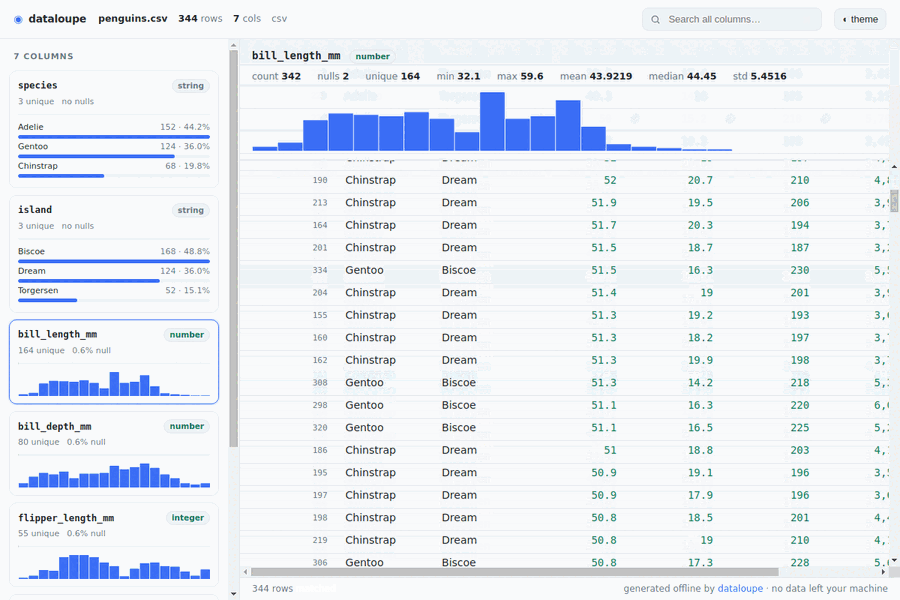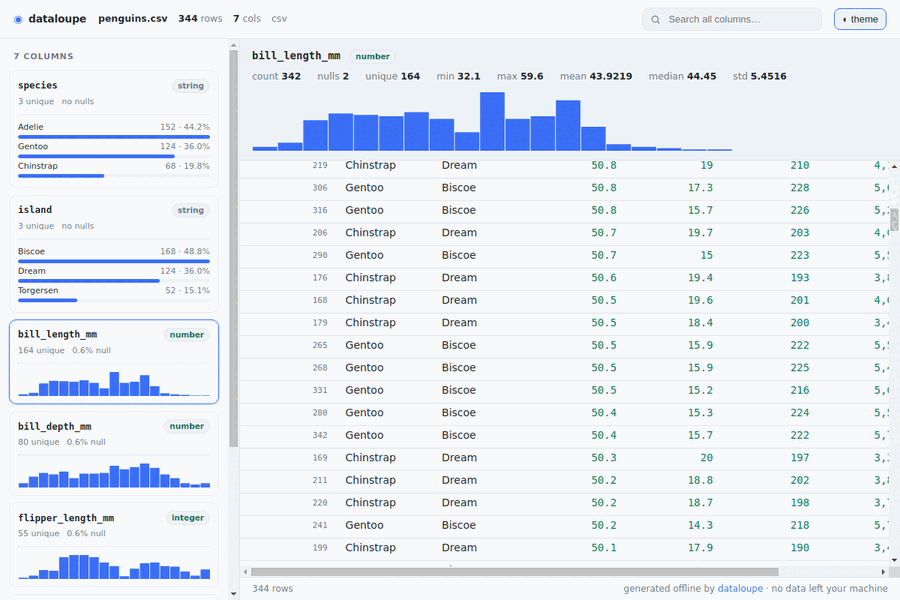
Live-captured from the generated HTML: search, sort, scroll a virtualized table, toggle theme — zero network requests.
dataloupe reads your data file and writes a single .html next to it. Open it by
double-click, email it, drop it in Slack, or commit it to a repo. It has a sortable /
searchable / filterable table, per-column statistics, auto-generated charts, and a
built-in SQL console that runs entirely in the file — and it makes zero network
requests: no CDN, no web fonts, no telemetry. Your data never leaves your machine.
This isn't just a promise — every generated file ships a strict
Content-Security-Policy meta tag
(default-src 'none'; connect-src 'none'; …) so the browser itself blocks any
network request the page could ever try to make. Open it on an air-gapped machine and
it behaves identically.
Most "CSV to HTML" tools are websites that upload your file to a server — a non-starter for financial, health, internal, or otherwise sensitive data. The good local alternatives are heavier than the job:
dataloupe emits one portable HTML file you can hand to anyone. It works forever, offline, with nothing installed on their end.
Run it with npx — nothing to install:
npx dataloupe sales.csv
Or install it globally:
npm install -g dataloupe
dataloupe sales.csv
Requires Node.js ≥ 18. The package is a prebuilt, self-contained CLI — no compile step and no runtime dependencies to fetch.
Prefer to pin to the repo instead of the registry?
npx github:aurelio-nakamura/dataloupe sales.csvalso works.
dataloupe <file> [options]

ARGUMENTS
  <file>                CSV, TSV, JSON, NDJSON/JSONL, Parquet, or Excel (.xlsx)
                        Use "-" or pipe to read from stdin (text formats only)

OPTIONS
  -o, --output <file>   output HTML path (default: <input>.html, or dataloupe.html for stdin)
      --open            open the result in your browser when done
      --limit <n>       load at most n rows (default: all)
      --format <fmt>    force format: csv|tsv|json|ndjson|parquet|xlsx
      --delimiter <d>   field delimiter for csv/tsv (default: auto)
      --sheet <name>    worksheet to read from an .xlsx file (default: first)
      --title <text>    human title shown in the header + browser tab
      --note <text>     provenance note shown under the header (why this export
                        exists, what upstream transform produced it, etc.)
  -h, --help            show this help
  -v, --version         print version
Examples:
npx dataloupe events.ndjson --open
npx dataloupe metrics.parquet -o report.html
npx dataloupe budget.xlsx --sheet Q3 --open
npx dataloupe big.csv --limit 100000
npx dataloupe q1.csv --title "Q1 Expenses" --note "Exported from ledger; nulls dropped, USD"
The generated file already embeds inspectable provenance — source filename,
format, generation time, dataloupe version, row count, and each column's inferred
type and stats — so a recipient can always tell what they're looking at. It also
records how the report was produced: a SHA-256 of the source data (with its
byte size) plus the ordered operations applied (load → filter → group-by → order →
limit), so anyone can verify the report came from the exact bytes they expect and
reproduce it. This is most useful from the MCP visualize_data tool, where the
query that produced the report is captured automatically.
--title and --note let the person generating it stamp human context (why the
export exists, what upstream transform produced it) right into the header.
Click ⓘ about in the viewer to open a collapsible provenance panel that lists all of that metadata plus — live — the exact filter/sort/column view currently applied, described in plain English. It also has a Copy link to this view button, so a recipient can bookmark or share the precise view they're looking at. Every field shown travels inside the file; nothing is fetched.
It also reads stdin, so it drops straight into a shell pipeline (format is
auto-detected, or force it with --format):
psql -c "copy (select * from orders) to stdout csv header" | npx dataloupe - --open
cat data.csv | npx dataloupe -o report.html
curl -s https://api.example.com/items | npx dataloupe --format json --open
diff — a git-diff for data filesgit diff on a CSV is a wall of noise: reordered rows, a re-quoted field, and one
real change all look the same. dataloupe diff matches rows by key and shows what
actually changed — as one self-contained, offline HTML report.
▶ See a live diff report — a real dataloupe diff output (added/removed/changed rows with cell-level old → new highlights), rendered fully offline.
npx github:aurelio-nakamura/dataloupe diff old.csv new.csv --key id --open
+3 added · −1 removed · ~5 changed · =1042 unchanged
old → new.--key id or --key region,date) so reordered rows and
requoting don't register as changes. Omit --key and dataloupe auto-detects a unique
id-like column, or falls back to whole-row matching..csv export against a .parquet
snapshot, or last week's .xlsx against this week's.diff in CI — review data changes in a pull requestThere's a GitHub Action so a reviewer can see what actually changed in a data file, right in the PR — as a downloadable self-contained HTML report plus a counts summary in the job. Your data never leaves the runner.
# .github/workflows/data-diff.yml
on:
  pull_request:
    paths: ["data/**.csv"]
jobs:
  diff:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
        with: { fetch-depth: 0 }
      - run: git show "${{ github.event.pull_request.base.sha }}:data/people.csv" > base.csv || : > base.csv
      - uses: aurelio-nakamura/[email protected]
        id: diff
        with:
          before: base.csv
          after: data/people.csv
          key: id
          output: people-diff.html
      - uses: actions/upload-artifact@v4
        with: { name: data-diff, path: "${{ steps.diff.outputs.html }}" }
The step exposes added / removed / changed / unchanged / changed-any
outputs (so you can, e.g., fail a check when data changes) and writes a Markdown
summary to the job. A ready-to-copy workflow is in
examples/workflows/data-diff.yml.
dataloupe is also a library. Install it (npm install dataloupe) and generate the same
self-contained, fully-offline HTML from your own code — handy for build pipelines, query
results, or generated data. It ships TypeScript types and is ESM.
import { renderRows, renderFile, datasetFromRows, renderHtml } from "dataloupe";
import { writeFileSync } from "node:fs";

// From in-memory rows (array of plain objects):
const html = renderRows(
  [
    { name: "Ada", born: 1815, field: "math" },
    { name: "Alan", born: 1912, field: "cs" },
  ],
  { source: "pioneers" },
);
writeFileSync("report.html", html);

// From a file (CSV/TSV/JSON/NDJSON/Parquet/XLSX):
writeFileSync("data.html", await renderFile("data.csv"));

// Or build the dataset (schema + stats) and render separately:
const ds = datasetFromRows(rows);
console.log(ds.columns, ds.types, ds.stats); // inspect
const out = renderHtml(ds);
<dataloupe-table> — embed the explorer in any web pageWant the interactive explorer inside your own page instead of a standalone file? Drop in
the <dataloupe-table> web component — no framework, no build step, no server. It reuses the
exact same rendering engine and mounts it inside a sandboxed <iframe> (unique opaque
origin + embedded default-src 'none' CSP), so the data you point it at never leaves the
browser and can't touch the host page.
Load it straight from a CDN — no npm, no build, no bundler. The bundle is ~110 KB, has zero runtime dependencies, and is served from the versioned git tag:
<script type="module"
  src="https://cdn.jsdelivr.net/gh/aurelio-nakamura/[email protected]/dist/dataloupe-element.js"></script>

<dataloupe-table src="sales.csv" height="600"></dataloupe-table>
Prefer to self-host? The same file is on GitHub Pages:
https://aurelio-nakamura.github.io/dataloupe/embed/dataloupe-element.js
// Imperative: hand it in-memory rows
const el = document.querySelector("dataloupe-table");
el.rows = [{ name: "Ada", born: 1815 }, { name: "Alan", born: 1912 }];
// ...or raw text: el.setText(csvString, "csv");
Attributes: src, format, limit, title, height. Events: dataloupe:load /
dataloupe:error. You can also import "dataloupe/element" to register it from a bundler.
dataloupe ships an MCP server, so Claude Desktop, Cursor, VS Code, and other MCP clients can inspect and query your local data files directly — without a database, without a running server, and without uploading a single byte anywhere. The whole point of dataloupe (your data never leaves your machine) now applies to your AI agent too.
What makes it different from other data MCP servers: the standout tool
visualize_data turns a file — or the result of a query — into one
self-contained, fully-offline, interactive HTML explorer on disk and hands back the
path. Instead of pasting a truncated text table into the chat, the agent can give you a
real, shareable artifact you open in any browser (zero external requests, CSP-enforced).
Add it to an MCP client (example for Claude Desktop / Cursor mcpServers config):
{
  "mcpServers": {
    "dataloupe": {
      "command": "npx",
      "args": ["-y", "dataloupe", "mcp"],
      "env": { "DATALOUPE_MCP_ROOT": "/path/to/your/data" }
    }
  }
}
DATALOUPE_MCP_ROOT is optional but recommended: it confines all file access to that
directory (symlink-escape–safe: paths are canonicalized before the check). Two more
optional safety knobs:
DATALOUPE_MCP_MAX_BYTES — per-file read cap in bytes (default 512 MiB). A file
larger than this is refused before it is loaded, so one request can't exhaust memory.
Set to 0 to disable.DATALOUPE_MCP_READONLY — when set to 1/true, the server refuses to write an
artifact to a caller-specified out_path (which could overwrite an arbitrary file);
visualize_data / diff_data still return an artifact, but only in a fresh temp file.Tools exposed:
Every tool is read-only against your data — dataloupe never modifies your files.
dataloupe's MCP server is published to the official MCP Registry
as io.github.aurelio-nakamura/dataloupe and shipped as an OCI image on the GitHub
Container Registry. Point any MCP client at the image (it speaks JSON-RPC over stdio):
{
  "mcpServers": {
    "dataloupe": {
      "command": "docker",
      "args": ["run", "-i", "--rm", "--mount", "type=bind,src=/path/to/your/data,dst=/data",
               "ghcr.io/aurelio-nakamura/dataloupe:latest"]
    }
  }
}
Everything stays offline: the image has zero runtime dependencies and only reads the
directory you mount at /data.
<script src>, no <link href>, no fonts, no fetch. Verify it yourself: unplug the network and open the file.--sheet.SELECT queries — WHERE, AND, LIKE, IN, GROUP BY, aggregates (COUNT/SUM/AVG/MIN/MAX), ORDER BY, LIMIT/OFFSET — against your data. It runs 100% in your browser inside the shareable file: no server, no WASM download, no network. Nobody else's single-file export does this.file://…#… artifact) and whoever opens the same file lands on the exact same view. Still 100% offline; the hash never triggers a request.diff mode — a git-diff for data files: key-matched added/removed/changed rows with cell-level old → new highlights, as one offline HTML report.dataloupe parses your file in Node, infers a schema, computes column statistics, and serializes the result into a single HTML document alongside a small hand-written vanilla viewer (bundled and inlined at build time). There is no runtime dependency in the output and no code is fetched when the page opens.
git clone https://github.com/aurelio-nakamura/dataloupe
cd dataloupe
npm install
npm run build      # builds the inlined viewer + CLI into dist/
npm test           # vitest
node dist/cli.js path/to/data.csv --open
Bug reports, feature requests, and pull requests are welcome. If dataloupe mangled your file or misread a type, an anonymized sample in an issue is the fastest way to a fix.
See CONTRIBUTING.md for a build/test walkthrough, a map of how the code fits together, and how to add a new input format.
MIT © Aurelio Nakamura
Offline MCP server to explore CSV/JSON/Parquet/Excel: preview, query, diff, render interactive HTML
{ "mcpServers": { "io.github.aurelio-nakamura-dataloupe": { "command": "docker", "args": [ "run", "-i", "--rm", "ghcr.io/aurelio-nakamura/dataloupe:0.15.0" ], "env": { "DATALOUPE_MCP_ROOT": "<value>" } } }}Tools
Noch keine Tool-Liste. Remote-Server erhalten eine nach dem ersten Health-Check.
FAQ
Kopieren Sie auf dieser Seite die stdio-Konfiguration für Cursor, Claude Desktop, Claude Code oder VS Code. Sie nutzt die Installation des Herausgebers, keinen PlugMCP-Proxy.
Der Herausgeber nennt diese Umgebungsvariablen: DATALOUPE_MCP_ROOT.
Dataloupe läuft lokal über stdio.
Zuletzt geprüft: 2026-11-09. Offline MCP server to explore CSV/JSON/Parquet/Excel: preview, query, diff, render interactive HTML
