Lexicon
Dictate to your agent. Keep your spelling.
A personal lexicon for voice-to-agents.
One YAML file of the words speech-to-text gets wrong, applied everywhere your voice lands: MCP, Claude Code, the browser, macOS.
Live demo · Quickstart · Docs · lexicon.ashlr.ai
You said:        "tell Ashlr.AI to deploy the Kubernetes auth service"
STT heard:       "tell Ashler to deploy the Cooper Nettie's off service"
Agent received:  "tell Ashlr.AI to deploy the Kubernetes auth service"
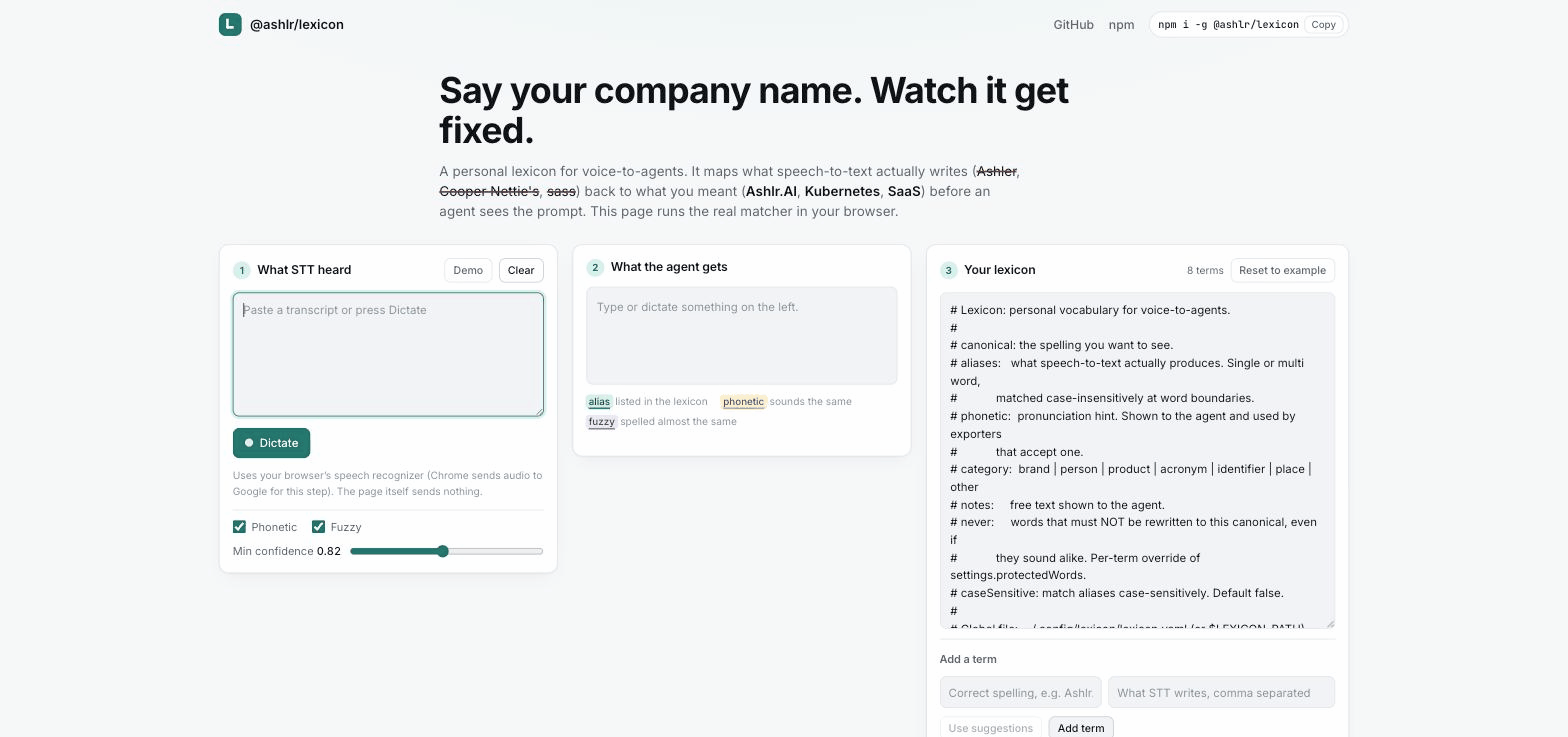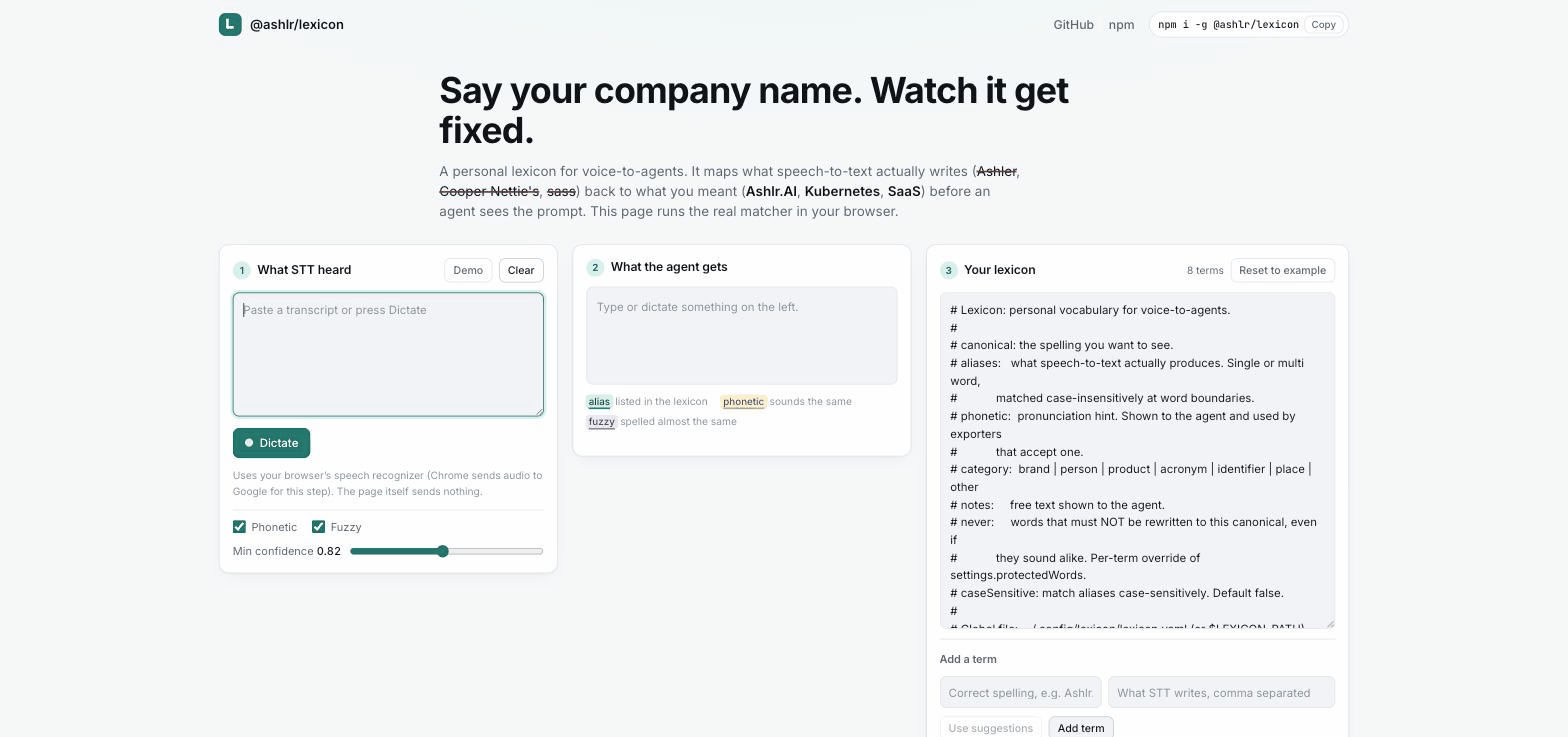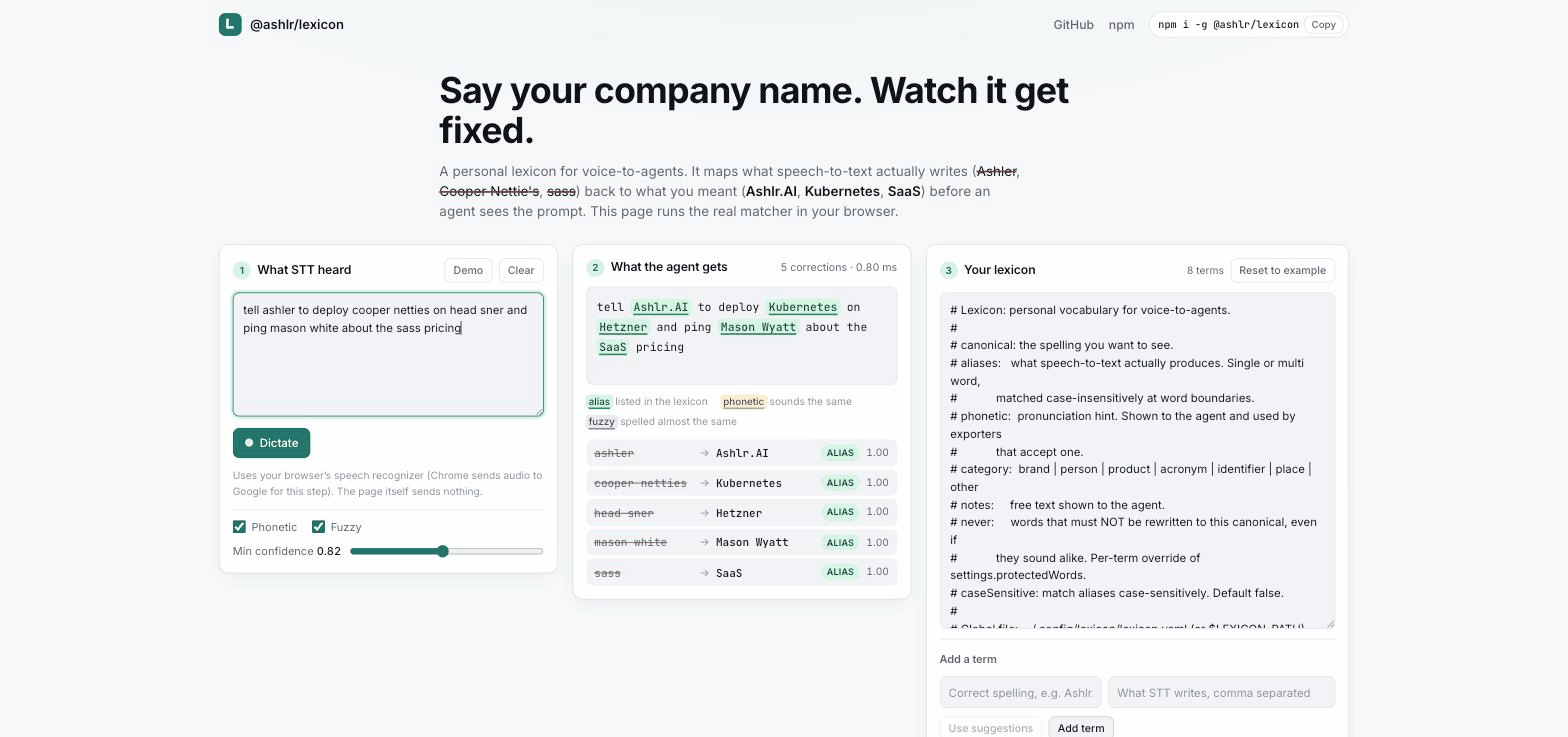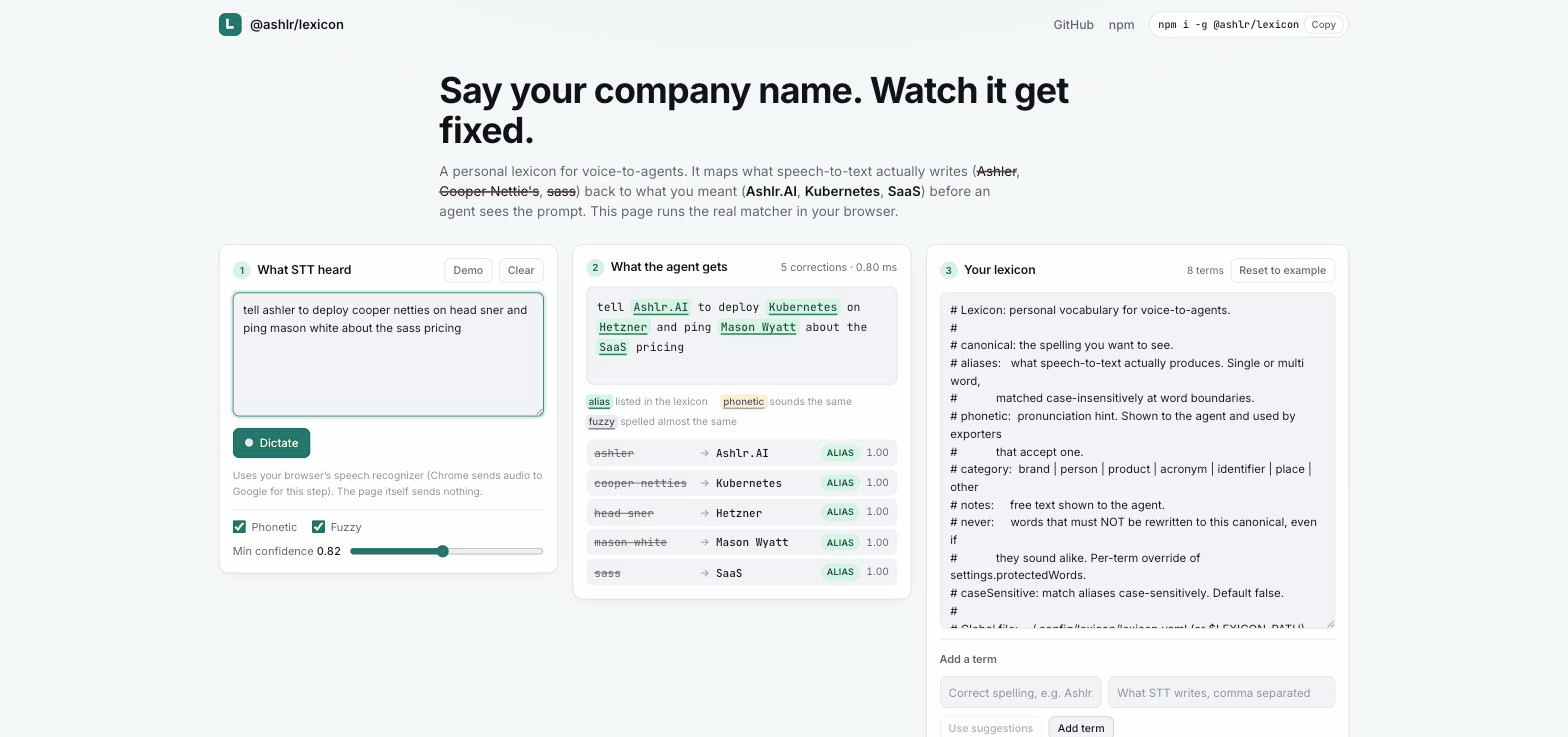
That is the live demo running this repo's real matcher on your text, in your browser, with nothing installed. (Its Dictate button uses your browser's own speech recognizer, which in Chrome sends audio to Google.)
Measured
Method, full tables and every failing case are in docs/BENCHMARK.md. Reproduce with npm run bench (no setup beyond a clone), or npm run bench:audio && npm run bench:compare (needs macOS and whisper.cpp).
Against the alternatives. 330 clips of synthesized (text-to-speech) audio through whisper.cpp small.en, three voices. Same audio, same recognizer, same 70-term lexicon in every row; the only thing that changes is how the proper nouns get fixed.
| how the words get fixed | proper nouns recovered | clean prose wrongly changed |
|---|---|---|
| nothing, raw whisper.cpp | 45.9% | n/a, nothing runs |
| exact-string substitution, the macOS Text Replacement approach | 62.0% | 0 of 72 |
| the same, plus a casing rule per term | 71.3% | 0 of 72 |
whisper.cpp's own --prompt hint list | 76.0% | n/a, nothing runs |
| Lexicon | 91.0% | 0 of 72 |
Every row uses the same curated seventy-term lexicon (bench/lexicon.yaml). The prose column is a property of the terms in the file as much as of the matcher, so a lexicon assembled some other way is a different measurement.
Exact substitution recovers the spellings someone already wrote down, and nothing else. It cannot reach Versal, Superbase, CloudFloor or pedantic, because no table written by hand contains the mistake you have not heard yet. The phonetic and fuzzy tiers exist for that gap and recover 31 of the 279 term slots on their own, which is 11 points. The remaining 9 points over the casing-aware row come from the alias tier's tolerance for how the recognizer breaks a name into words, since that row already matches case. --prompt is a complement rather than a rival: stacked with the lexicon it reaches 95.7%.
Two honest notes about that table. Raw whisper.cpp cannot wrongly change prose because nothing runs, which is the absence of the feature rather than an advantage. --prompt is not the same case: it biases the recognizer itself, so whatever it changes is already in the transcript before scoring begins, while the metric counts sentences a post-pass altered. That cell is unmeasured rather than zero. Telling which way it goes would mean diffing prompted transcripts against unprompted ones, which this harness does not do.
Before and after.
| corpus | proper nouns recovered, raw STT | after lexicon | clean prose wrongly changed |
|---|---|---|---|
| TTS audio, whisper.cpp base.en (330 clips) | 41.9% | 82.8% | 0 of 72 |
| TTS audio, whisper.cpp small.en with prompt hints | 76.0% | 95.7% | 0 of 72 |
| synthetic STT errors (402 sentences, 70 terms) | 5.1% | 96.5% | 0 of 95 |
Latency is about 0.3 ms per sentence. The TTS-audio rows use macOS text-to-speech read into whisper.cpp, so they are cleaner than a phone microphone.
The synthetic 5.1% is not a claim that speech-to-text gets 5% of proper nouns right in general. Every sentence in that corpus was written to contain a mis-hearing, so 5.1% is only the handful that came out right anyway. The honest "before" number is the TTS-audio one, 41.9%.
The last column counts ordinary prose only. Each corpus also contains sentences deliberately built to trip the matcher (a bare "llama" next to an Ollama term, sound-alikes, code spans), marked expected-hard; with those included the false-positive rate is 15.3% (19 of 124) synthetic and 16.7% (15 of 90) on audio. Both numbers, and every failing case, are in docs/BENCHMARK.md.
Held-out check (separate internal run, unseen voice). The tables above use a lexicon written for the test terms. To test the harder case, aliases were learned only from other sentences and voices, then scored on a voice and sentences never used for learning (63 clips). Synthetic speech from three open text-to-speech voices read into whisper.cpp, clips counted correct when every target term was recovered.
| recognizer | raw | Lexicon, canonical terms only | Lexicon, plus aliases learned from other clips |
|---|---|---|---|
| whisper.cpp base.en | 16 of 63 | 38 of 63 | 44 of 63 |
| whisper.cpp small.en | 25 of 63 | 39 of 63 | 42 of 63 |
Clean prose changed by Lexicon: 0 of 60 in that run.
Whisper-prompt caveat. On the same 378 clips, whisper's --prompt hint list alone lifted base.en from 97 to 228 and small.en from 141 to 320 clips correct, so a prompt is a strong baseline and Lexicon adds less on top of it (base.en 271, small.en 339 with Lexicon). The prompt also made base.en produce 55 degenerate transcripts (empty or looping text) against 5 without it, so a prompt is not free on small models. All audio here is synthetic, not microphone speech, and the harness is not yet published, so treat these as internal numbers until it is.
Install
The package is @ashlr/lexicon; the command is lexicon.
curl -fsSL https://ashlrai.github.io/lexicon/install.sh | sh   # CLI + the setup wizard
brew install ashlrai/tap/lexicon                               # or Homebrew (macOS, Linux)
npm i -g @ashlr/lexicon                                        # or npm (Node 20+)
Then open Claude Code and say a sentence with your company name in it. Done.
The install script runs lexicon setup for you when it has a terminal to ask questions on; without one (CI, a Dockerfile), under sudo, or with LEXICON_NO_SETUP=1 it installs only and tells you to run lexicon setup yourself, as after a Homebrew or npm install. Every step is optional and safe to rerun, and lexicon setup --dry-run writes nothing while describing the run you would get from the same command without it: the steps it would perform, and the ones it would stop and ask about, with the answer pressing Enter gives each.
With Homebrew, always use the full tap name ashlrai/tap/lexicon. Plain brew install lexicon installs dns-lexicon, an unrelated DNS tool in homebrew-core.
- Seeds the lexicon with your name and your company, with the misspellings STT will produce for each.
- Offers the starter packs as a checklist.
- Harvests the current repo for names already in your code.
- Registers the MCP server and hooks in every agent client it detects.
- Installs the local API as a login service.
- Exports to your dictation app.
- Dictates a sentence built from the terms it just seeded, and shows you the correction.
The full walkthrough, with the real terminal output, is in docs/QUICKSTART.md.
Or skip the wizard and add one term by hand. The first argument is the canonical spelling, the rest are what STT actually produces:
lexicon add Ashlr.AI Ashler Ashlar "Ashler AI" --phonetic ASH-ler
lexicon normalize "tell Ashler to ship it"
# tell Ashlr.AI to ship it
Ten minutes in, teach it the names you actually say. lexicon import --guided asks where your proper nouns live (your contacts, your calendar, your GitHub), shows each candidate with where it was seen, and writes only the ones you approve. Nothing is read until you check its box, and email and chat stay out entirely.
Claude Code plugin, if you would rather not install a CLI at all. No Node install step, no build:
claude plugin marketplace add ashlrai/lexicon
claude plugin install lexicon@ashlrai
lexicon doctor checks the install. There is no telemetry. Vocabulary and
application state are local files; ordinary hooks, correction, MCP, local API
and extension paths do not send transcripts to a remote service. Explicit
network operations include lexicon voice fetching a whisper model on first
use, lexicon pack fetching community packs from a --registry URL with
checksum verification, and opting into the GitHub source in
lexicon import --guided. That source calls the GitHub API through your existing gh configuration
and login (normally api.github.com) for profile, organization membership,
member-login and repository-name metadata; no new OAuth scopes are requested. The source is
selected before inspection, and candidates are reviewed before writes. The
install script, npm and Homebrew fetch the package itself. See
SECURITY.md.
The guided GitHub importer ships in 0.5.5 (PR #25); npm latest is currently 0.5.4.
MCP setup
lexicon install <client> --apply does this for you. To wire it by hand:
# Claude Code
claude mcp add lexicon -- npx -y -p @ashlr/lexicon lexicon-mcp
# Codex
codex mcp add lexicon -- npx -y -p @ashlr/lexicon lexicon-mcp
Cursor (~/.cursor/mcp.json):
{ "mcpServers": { "lexicon": { "command": "npx", "args": ["-y", "-p", "@ashlr/lexicon", "lexicon-mcp"] } } }
The environment variables the server reads (LEXICON_PATH, LEXICON_HARVEST_ROOTS, LEXICON_REGISTRIES and the rest) are listed in docs/MCP.md.
Why
Speech-to-text is about 95% accurate on ordinary English and much worse on invented names. In the benchmark above, raw whisper.cpp base.en transcribed 117 of 279 dictated proper nouns correctly. "Ashlr.AI" becomes "Ashler", "Kubernetes" becomes "Cooper Nettie's", "SaaS" becomes "sauce", "auth" becomes "off". Those are exactly the words an agent needs to get right.
Dictation apps (Wispr Flow, Superwhisper, Aqua) each keep their own dictionary and none of them share it. Agents (Claude Code /voice, ChatGPT voice, Codex, local Whisper) run their own recognizer with no user vocabulary at all. This is the portable layer in between: corrections happen after STT and before the model, wherever the text passes through.
This is not a dictation app. It sits between whatever dictation you already use and whatever agent you talk to. The research behind that call, including the kill criteria, is in docs/RESEARCH.md.
What you get
- Twenty MCP tools, two resources and two prompts, for Claude Code, Codex, Cursor, Windsurf, Gemini CLI, VS Code and Claude Desktop. Your agent can run its own setup:
setup_lexicon,lexicon_doctor,install_client,trust_project,import_dictionary,import_vocabularyandsuggest_termsmean "set up my lexicon" works without a terminal. The tools that change your machine preview first:setup_lexiconandinstall_clientreturn a plan and write nothing until the agent passesapply: true,trust_projectasks you directly (an MCP elicitation prompt the agent cannot answer) before pinning a file,import_dictionarytakesdryRun, andimport_vocabularyreads only explicitly selected sources, then requires a saved preview token and approved candidate ids withapply: true. - A Claude Code plugin: MCP server,
SessionStartandUserPromptSubmithooks, alexiconskill and a/lexiconcommand. Installs from this repo's marketplace with no build step. - A CLI with 26 commands, from
lexicon addtolexicon voice. - 176 starter terms in four packs (developer, AI, business, voice tools), one command each, plus community packs from registry indexes (
lexicon pack search cardiology --registry <index>): checksums pinned at install, every install and update previewed before it writes. - Fifteen export formats (Wispr Flow, Superwhisper, macOS Text Replacement, espanso, Whisper and OpenAI prompts, Deepgram, AssemblyAI, Azure, Google, CLAUDE.md, markdown, text, CSV, JSON) and eight importers (including the CLAUDE.md table it writes) for the dictionary you already trained.
- Repo harvesting, a guided vocabulary import (
lexicon import --guided: your contacts, calendar and GitHub, each source opt-in, every candidate approved before it is written), correction learning ("it's Ashlr.AI not Ashler"; corrections the prompt hook notices are also queued for review inpending-aliases.yamlnext to your global lexicon, and nothing in the queue changes matching until you runlexicon pending accept <id>;lexicon pending reject <id>drops one,LEXICON_QUEUE_CORRECTIONS=0turns the queue off), usage stats, suggestions mined from your voice history, and a trust gate for project lexicons. - A plain library.
normalize()is a pure function: text plus lexicon in, corrected text and a replacement list out.
Where it applies
| Surface | How | Docs |
|---|---|---|
| Claude Code | Plugin, or MCP server plus two hooks that correct the prompt before the model reads it | CLIENTS.md |
| Codex, Cursor, Windsurf, Gemini CLI, VS Code, Claude Desktop | lexicon install <client> --apply registers the MCP server | CLIENTS.md |
| Any MCP client | stdio server, twenty tools | MCP.md |
| ChatGPT, Claude.ai, Grok, Gemini, Perplexity, Poe, Copilot | Browser extension: rewrites the composer when you press send | EXTENSION.md |
| Any macOS app, any dictation tool | LexiconBar menu bar app: rewrites dictated text in the focused field through Accessibility, with an undo bubble | MACOS-APP.md |
| Shortcuts, Raycast, scripts, your own app | lexicon serve: loopback HTTP API on 127.0.0.1:41733 behind a bearer token | LOCAL-API.md |
| Dictation without a dictation app | lexicon voice: ffmpeg records, whisper.cpp transcribes with your canonicals as prompt hints, the lexicon corrects | VOICE.md |
| Any text field, any OS | lexicon daemon --once --paste on a hotkey | DAEMON.md |
| Wispr Flow, Superwhisper, macOS Text Replacement, espanso, Deepgram, Azure, Google | Export into their own dictionaries and biasing parameters | EXPORTS.md |
| Your own STT pipeline | npm i @ashlr/lexicon, call normalize() between transcription and the model | LIBRARY.md |
| Any of the above, on Windows or Linux | Which surfaces are tested in CI on each OS, which work but have never been run on real hardware, and which are not there at all | PLATFORMS.md |
How it works
Three tiers over token windows: exact alias first, then double-metaphone phonetic, then Damerau-Levenshtein fuzzy above a confidence floor. Exact hits win the span; matches never overlap. A stoplist of about 3400 common English words, per-term never lists, and (with the default skipCode) code spans, URLs, emails, paths and glued identifiers are all off limits. That is why zero clean sentences changed in the benchmark. Every replacement reports its reason and confidence.
lexicon normalize --diff "deploy to head sner with cuban eatties"
# stderr:  "head sner" -> "Hetzner" (alias, 1.00)
#          "cuban eatties" -> "Kubernetes" (phonetic, 0.86)
# stdout:  deploy to Hetzner with Kubernetes
The rules in full, including every guard, are in docs/MATCHING.md.
Documentation
The full index is in docs/, grouped by task: get started, use it
with your client, understand how it works, contribute, internals. The three pages most
people need:
| Page | What it covers |
|---|---|
| QUICKSTART.md | Five minutes from nothing to corrections in Claude Code, with what each setup step writes |
| CLIENTS.md | Installing into Claude Code (plugin, hooks, headless) and every other agent client |
| FAQ.md | The questions people ask before installing |
Writing an agent that installs this for someone? docs/AGENTS.md is written to you. Changing the code? Start at CONTRIBUTING.md and docs/ARCHITECTURE.md.
Also at the root: SECURITY.md, CODE_OF_CONDUCT.md, CHANGELOG.md.
Downloads
Every GitHub release attaches the browser extension for Chrome/Edge/Brave and for Firefox, LexiconBar.app.zip for macOS, the npm tarball for offline installs, and SHA256SUMS. The Homebrew formula lives in ashlrai/homebrew-tap. After 0.5.6 is published, npm i -g github:ashlrai/lexicon#v0.5.6 installs that tag straight from GitHub and builds on install.
Roadmap and non-goals
Non-goals: this is not a dictation app, and there are no hosted accounts and no sync service. It is a file.
- Chrome Web Store and Firefox AMO listings for the extension. Today it installs from the release zip.
- Notarized macOS app. LexiconBar is ad-hoc signed, so the first launch needs right-click and Open.
- Linux tray app with the same push-to-talk and fix-clipboard actions. The Windows one is built: see docs/WINDOWS-APP.md.
- Non-English phonetics. Double metaphone is tuned for English; names in other languages fall back to fuzzy matching.
- Real-microphone benchmark. The audio corpus is macOS text-to-speech read into whisper.cpp, not recorded speech.
Part of the Ashlr ecosystem
Lexicon is one of the open-source tools from Ashlr, a forward-deployed engineering company: Phantom Secrets, Locus, Ashlr Stack, Ashlr Markdown and the Ashlr plugin.
Phantom: INTEGRATION.md is a sketch, written from Lexicon's side, of the contract Phantom would integrate against (the lexicon file, the trust gate, the normalize entry points). It changes nothing in Phantom core.
Post-quantum readiness: docs/PQ-READINESS.md records what Lexicon does with cryptography today (SHA-256 and SHA-512 hashes for integrity; no encryption, key exchange or signing in the shipped source) and what a migration would touch. It makes no claim that Lexicon is quantum-safe.
Contributing
Good first issues are labelled and scoped: a new starter pack, an exporter, an importer, a harvester source. CONTRIBUTING.md has the setup, the test layout and a recipe for each.
Found a name it gets wrong? Open a misheard term issue.
License
MIT. Copyright 2026 AshlrAI, Inc.