lean-memory
Embedded, local-first agent memory. No server, no daemon, no mandatory cloud key.
Status (2026-07): first public release line (0.2.1) is live on PyPI and the MCP Registry (MCP-first launch); the Claude Code plugin ships in this repo (marketplace listing pending). Roadmap and rationale:
docs/superpowers/specs/2026-07-08-strategic-direction-design.md. Public benchmark runs (LongMemEval/LoCoMo) are deliberately deferred until after launch; the harness is complete (bench/phase2_*.py) and the engine flaws it exposed are fixed — seedocs/phase2-learnings.md.
from lean_memory import Memory

mem = Memory(root="./data")

mem.add("user-42", "I work at Acme Corp.")
mem.add("user-42", "I now work at Globex.")          # supersedes Acme automatically

mem.search("user-42", "where does the user work?")   # → "I now work at Globex."
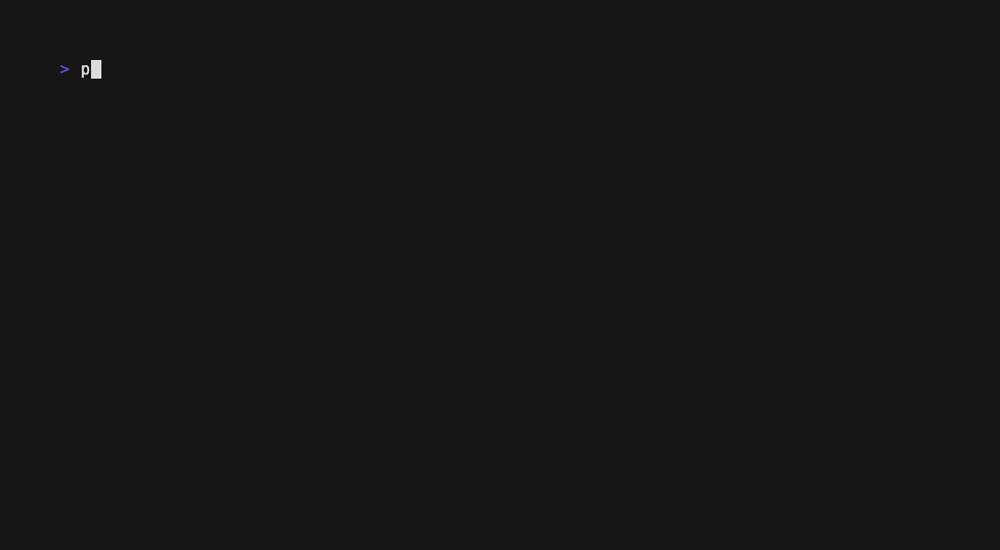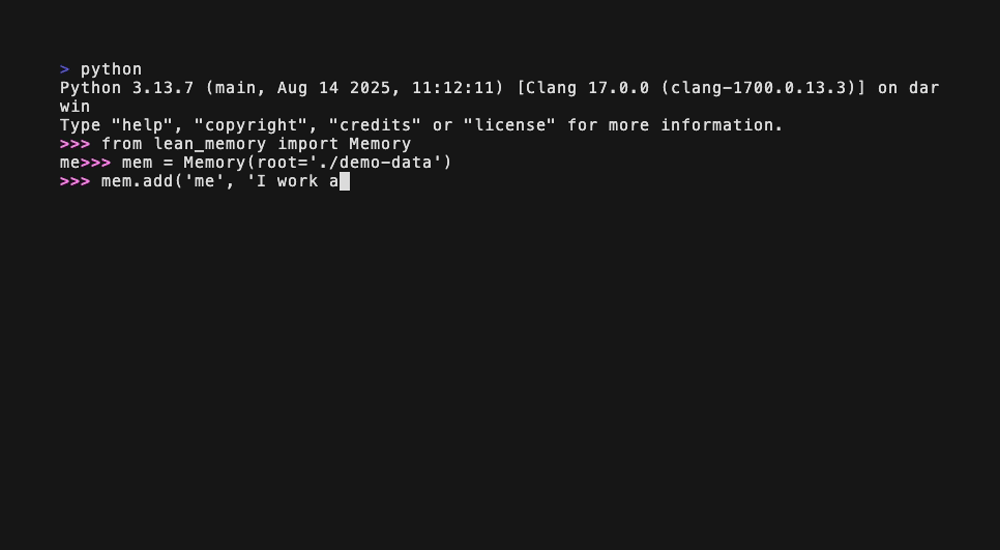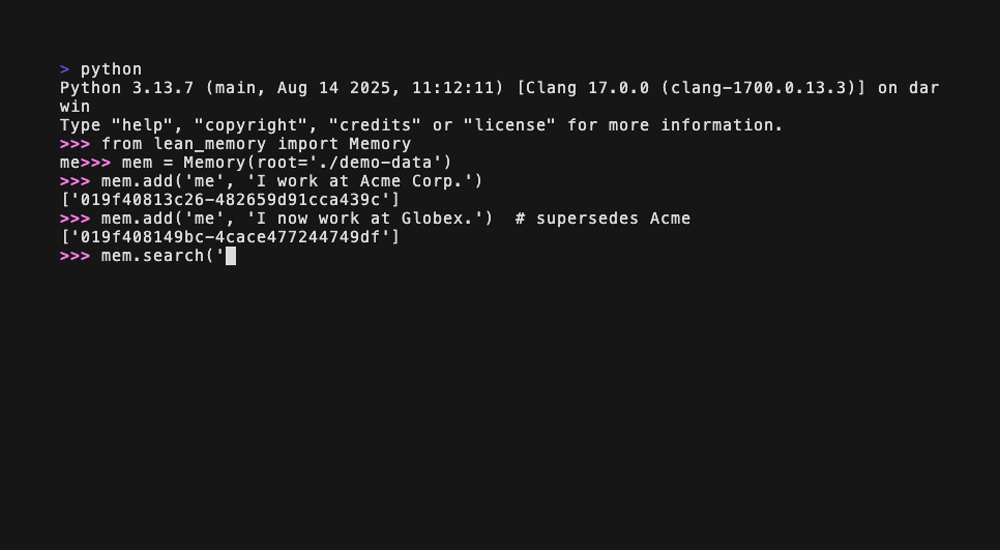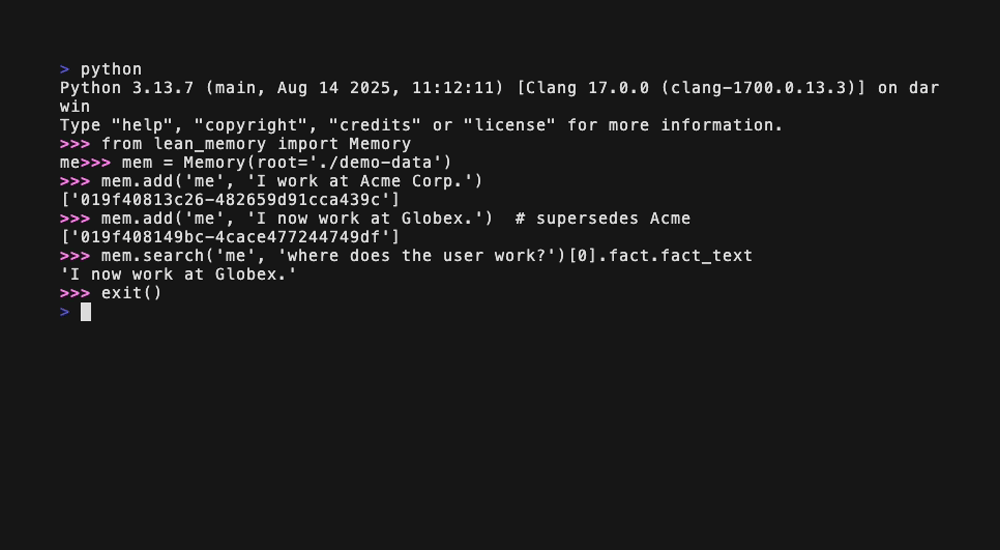
Facts are extracted from natural language, stored in a per-namespace SQLite file, and retrieved with hybrid dense+sparse search. Old facts are never deleted — they're superseded and queryable at any past point in time.
Install
pip install lean-memory
Runs fully offline out of the box. Optional extras unlock real model quality:
| Extra | What it adds |
|---|---|
lean-memory[models] | Real embedder + reranker (Qwen3-0.6B + Ettin-32M) |
lean-memory[extract] | GLiNER2 candidate generation for richer extraction |
lean-memory[llm] | Ollama-backed LLM typing pass |
lean-memory[mcp] | MCP server bridge for Claude Desktop / Claude Code |
lean-memory[examples] | Terminal demo agent (requires anthropic SDK) |
Quickstart
from lean_memory import Memory

mem = Memory(root="./data")   # one SQLite file per namespace, stored under ./data/

# Store facts in natural language
mem.add("alice", "I work at Stripe.")
mem.add("alice", "I now work at Vercel.")   # supersedes Stripe automatically

# Retrieve — the superseded Stripe fact drops out; only the current one is returned
results = mem.search("alice", "what does Alice do for work?", k=3)
for hit in results:
    print(hit.fact.fact_text, hit.final_score)
# → I now work at Vercel. 0.89

# Point-in-time query — what was true at a specific moment?
mem.search("alice", "employer", as_of=1_700_000_000_000, is_latest_only=False)  # epoch ms

# Always close when done (flushes WAL)
mem.close()
Demo Agent
A terminal chatbot showing the full memory loop — add, retrieve, supersede, restart. The demo script lives in the repo (it is not installed with the package):
git clone https://github.com/Wuesteon/lean-memory && cd lean-memory
pip install -e '.[examples]'
export ANTHROPIC_API_KEY=sk-ant-...
python examples/chat.py                  # uses offline stubs by default
python examples/chat.py --namespace bob  # separate memory tenant, persists across restarts
No API key? The demo still runs — it echoes the retrieved memory context instead of calling Claude, so you can watch the engine work offline.
MCP Server — memory for Claude Code / Claude Desktop
Give any MCP agent persistent local memory: three tools (memory_add,
memory_search, memory_clear), one SQLite file per namespace, nothing
leaves your machine.
pip install 'lean-memory[mcp,models,extract]'
First run downloads three open models (~2.0 GB total: Qwen3-Embedding-0.6B
- Ettin-32M reranker for retrieval, plus GLiNER2-base (~0.8 GB) for real extraction — all ungated). Pre-warm once so your MCP client never waits on a download:
python -c "from lean_memory.embed.sentence_transformer import SentenceTransformerEmbedder; \
from lean_memory.retrieve.rerank import CrossEncoderReranker; \
SentenceTransformerEmbedder().embed_one('warm'); CrossEncoderReranker().score('warm', ['up']); \
from lean_memory.extract.gliner_extractor import Gliner2Generator; from lean_memory.types import Episode; \
Gliner2Generator().generate(Episode(namespace='w', raw='I work at Acme.', t_ref=0, source='user'))"
Claude Code:
claude mcp add lean-memory -- lean-memory-mcp
Claude Desktop — add to mcpServers (or copy examples/mcp_config.json):
{ "lean-memory": { "command": "lean-memory-mcp", "env": { "LM_DATA_ROOT": "~/.lean_memory" } } }
Data root: LM_DATA_ROOT (default ~/.lean_memory). Works offline-only too —
the server opportunistically upgrades each backend that its extra is installed
for ([models] → real embedder + reranker, [extract] → GLiNER2 extraction)
and otherwise falls back to deterministic stub backends (fine for CI,
semantically meaningless for real use — install [mcp,models,extract]).
What the optional
[llm]extra buys. The canonical[mcp,models,extract]install has no LLM typing pass, so the ~15% of candidates that escalate — almost all of them inferential (derives) facts — are typed by a deterministic stub instead of a model. Assertional facts are unaffected; inference-type facts are effectively second-class on the default path. Adding[llm](a local Ollama model) upgrades that escalated tier to real constrained typing. See ARCHITECTURE.md → Known Limitations.
Sleep-time maintenance & review
Memory accumulates cruft: the same fact restated a dozen ways, old records that never come up, clusters begging to be summarized. lean-memory cleans it up the way sleep consolidates memory — an offline job you run off-hours that dedupes, summarizes, and demotes low-value records, then hands you the judgment calls to click through the next morning, in the web console or conversationally in Claude Code.
The CLI (lean-memory-maintain) is the primary trigger. It is dry-run by
default — it reports what it would do and writes nothing:
lean-memory-maintain --root ~/.lean_memory              # dry-run: report only, zero writes
lean-memory-maintain --root ~/.lean_memory --apply      # auto-apply safe transforms + stage the rest
lean-memory-maintain --root ~/.lean_memory --auto-only   # with --apply: ONLY the provably-safe band, stage nothing
lean-memory-maintain --root ~/.lean_memory --json        # one machine-readable object, stable keys
--root defaults to $LM_DATA_ROOT; add --namespace NS to run a single
namespace instead of every *.db under the root. Overnight, on a schedule —
one crontab line runs the safe band nightly at 3am and stages everything else
for you:
0 3 * * * lean-memory-maintain --root ~/.lean_memory --apply >> ~/.lean_memory/maintain.log 2>&1
Next-morning review in Claude Code. Judgment calls (near-duplicate merges,
summaries, evictions) are staged as proposals — nothing changes in stored
memory until you approve. Run the /review-memory plugin command (or invoke the
review-memory-maintenance MCP prompt on the console server) and Claude walks
you through the queue,
grouped by entity with before/after evidence, recording only the verdicts you
give. Four MCP tools back it — memory_maintenance_run (dry-run by default,
like the CLI), memory_maintenance_status, memory_review_queue, and
memory_review_decide — available on the core lean-memory-mcp server and both
console MCP surfaces. Set LM_MAINT_AUTO=1 to opt into a background auto-run
(safe band only) on the first tool call of a stale namespace; it is off by
default.
Or click through it in the console. The memory console ships a Review page: the same queue grouped by entity, before/after evidence per proposal (both texts + cosine for near-duplicates, sources + proposed text for summaries, score evidence for evictions), with Approve / Keep / Edit-then-approve / Promote verbs, batch-approve per entity, and a run-maintenance button (dry-run by default; apply sits behind a confirm). Both frontends drive the same proposal store with compare-and-set decisions, so deciding in one place shows up as "already decided" in the other instead of double-applying.
The safety story in one paragraph. Nothing is ever deleted — maintenance
only appends, retires (the same superseded_by flip ordinary supersession
uses), or demotes to a cold tier, so your full history stays queryable as-of any
past point in time, bit-for-bit identical at the store predicate and pinned by
executable tests. Only two transforms auto-apply: exact-duplicate retirement and
a strict eviction band; everything judgmental is staged for a human, and an
unreviewed proposal expires after 30 days rather than auto-applying —
silence is never consent. Cold-demoted facts stay reachable via as_of queries
and search(..., include_cold=True), and promotion back to the hot tier is
explicit-only, so a read never durably changes what your agent sees.
Real Model Quality
The default backends are offline stubs — deterministic and dependency-free, but semantically meaningless. Swap in real models for production-quality retrieval:
pip install 'lean-memory[models]'
With Qwen3-Embedding-0.6B + Ettin-32M reranker, retrieval jumps from 1/5 to 4/5 on the internal benchmark with zero code changes.
For benchmark results, architecture decisions, and implementation status see ARCHITECTURE.md.
How It Works
Each mem.add() call runs a 4-pass hybrid extraction pipeline:
- Rules — regex + dateparser for common predicates (
works_at,lives_in, …) - GLiNER2 — open-vocabulary NER candidate generation (offline stub by default)
- Router — recall-biased escalation: low-confidence, coreference, and inferential (
derives) facts escalate to the LLM pass - LLM typing — constrained relation typing via a local Ollama model (stub by default)
Contradiction detection runs cheap-first (slot match → cosine → token subsumption → LLM). Conflicting facts are superseded, not deleted — the old fact stays with is_latest=False and a superseded_by pointer.
Entity identity resolves on a normalized name key — NFC + Unicode case-fold + whitespace collapse — so Acme, ACME and acme are one subject and dedupe/supersession actually apply to them. It is a full Unicode fold, not SQLite's ASCII-only NOCASE: Café/CAFÉ and ЖУК/жук collate too. Punctuation and diacritics are deliberately not folded (Yahoo! ≠ Yahoo, Café ≠ Cafe), and the display name keeps the first spelling you used. The trade-off: two genuinely distinct subjects differing only by case (Mercury the planet vs mercury the metal) collate into one — nothing is deleted, and the retired fact stays readable via search(as_of=…, is_latest_only=False).
Retrieval fuses two-stage Matryoshka dense search (256-dim coarse KNN → full-dim (1024 for the default embedder) re-score) with BM25 sparse, applies RRF fusion, reranks with a cross-encoder, and scores with salience-decay (0.6·relevance + 0.2·recency + 0.2·importance).
Develop
git clone https://github.com/Wuesteon/lean-memory
cd lean-memory
python -m venv .venv && source .venv/bin/activate
pip install -e '.[dev]'
pytest -q    # full offline suite, no downloads
Project Layout
src/lean_memory/
  memory.py                   Memory facade — the public API
  types.py                    Episode / Fact / RetrievedFact types
  store/                      Store interface + SqliteStore (vec0 + FTS5)
  embed/                      Embedder interface, FakeEmbedder, SentenceTransformer
  extract/                    4-pass extraction pipeline
  retrieve/                   Reranker interface, retrieval pipeline
examples/
  chat.py                     Terminal demo agent
  mcp_config.json             Drop-in MCP client config
tests/                        offline test suite
bench/                        Retrieval quality + BET-2 ablation harnesses
License
Apache-2.0