
██████╗ ███████╗ ██████╗ █████╗ ██╗     ██╗
██╔══██╗██╔════╝██╔════╝██╔══██╗██║     ██║
██████╔╝█████╗  ██║     ███████║██║     ██║
██╔══██╗██╔══╝  ██║     ██╔══██║██║     ██║
██║  ██║███████╗╚██████╗██║  ██║███████╗███████╗
╚═╝  ╚═╝╚══════╝ ╚═════╝╚═╝  ╚═╝╚══════╝╚══════╝
Recall
[!NOTE] EdHeltzel's Persistent Memory for Agents
TL;DR
Recall is a retrieval-first memory layer: everything lands in one searchable database, the best of it is ranked and injected where a host supports session-start context, and decisions carry confidence, importance, and a lifecycle across any coding agent/harness.
A SQLite-backed persistent memory layer for coding agents. Host lifecycle adapters capture sessions automatically, MCP tools expose them mid-session, hybrid search (FTS5 + embeddings) retrieves them, and a tiered L0/L1 recall block injects identity + top-ranked records on supported hosts. MCP and skills connect supported hosts to one local database where each host supports them; lifecycle automation is host-specific.
Got questions about the project? I'd suggest using DeepWiki from Devin/Cognition to ask questions about the project.
All coding agents forget when a session ends. Recall doesn't — it extracts, indexes, and recalls what matters across every session, across every agent you use.
Built on the Model Context Protocol. One SQLite file. Retrieval does not phone home. Optional Jev is off unless JEV_RECALL_KEY is set in the process environment or in ~/.env. A non-blank environment value wins. When the key is present, Jev sends scrubbed extracted candidates to TypeSafe. No vendor lock-in. Optional ~/.agents/Recall/config.json can point query, extraction, or cluster at a harness. Recall starts Claude, Pi, and Codex. OpenCode, Grok, JCode, omp, and Cursor fail that step until a stdin contract is proven. Anything else is a command you write. A missing file keeps today's local search and extractors. Install never writes the file.
Stable on Claude Code. Beta on Pi and OpenCode. Codex CLI has native MCP, skills, automatic capture, and session-start injection. Grok Build CLI has automatic capture but no automatic injection. omp has native main-session capture with skills and MCP kept separate. JCode remains MCP and skills only after a bounded live probe. See Roadmap.
The Problem
AI agents have no memory between sessions. Context is lost. You repeat yourself. Decisions made last week are forgotten today. Every new session re-learns the basics.
How Recall Fixes It
Install once, then forget about it. Recall runs silently in the background:
┌──────────┐    ┌────────────────┐    ┌──────────────┐    ┌───────────────┐    ┌──────────────┐
│ You Work │───▶│ Stop hook fires│───▶│ Auto-Extract │───▶│ SQLite + FTS5 │───▶│ Next Session │
└─────▲────┘    │ (end of turn)  │    └──────────────┘    └───────────────┘    └──────┬───────┘
      │         └────────────────┘                                                    │
      └───────────────────────────── Memory Available ───────────────────────────────┘
- Automatic capture — supported lifecycle adapters preserve session progress without manual dumps; each host's exact capture and extraction behavior follows its verified lifecycle surface
- Full-text + semantic search — find anything from any past session
- Tiered session-start context — L0 identity (who you are) + L1 importance-ranked top records load automatically on supported hosts
- Zero friction — no workflow changes, no manual steps
- MCP integration — your agent searches memory automatically through standard MCP tools
Why Recall
Four things that set Recall apart from cloud-hosted memory layers and from agent-specific scratch files:
- Local-first, zero infrastructure. One SQLite file at
~/.agents/Recall/recall.db(override viaRECALL_DB_PATH). WAL mode,0600perms. No vector database, no graph database, no agent server. Keyword and hybrid retrieval need no API key and do not phone home. Optional Ollama for embeddings stays local. Optional Jev is the exception: withJEV_RECALL_KEYin the environment or~/.env, scrubbed extracted candidates go to TypeSafe. A non-blank environment value wins. Missing from both, Jev is off and those rows are written unchanged. - Multi-agent native. One memory layer across the agents you actually use. Claude Code, Pi, OpenCode, Codex, Grok, JCode, and omp share the same database through their supported MCP, skill, and lifecycle surfaces. Automatic capture and injection depend on each host's supported lifecycle surfaces; see the capability matrix below.
- Structured taxonomy, not a flat blob. Decisions (with supersede/revert lifecycle and confidence scoring), learnings, breadcrumbs, and Library of Alexandria entries (Automatic-capture LoA and Curated LoA) — each has a purpose and a query path. Importance scoring (1–10) surfaces what matters first.
- Hybrid search that works offline. FTS5 keyword search ships with SQLite — no embedding infrastructure required to find anything. Optional Ollama embeddings layer on top for semantic queries. Both are merged via Reciprocal Rank Fusion. Lose Ollama, lose nothing — the keyword path keeps working.
Quick Start
First-run walkthrough (install, first commands, where the database lives, how a session starts, how MCP/hooks get wired): Getting Started.
Recall requires Bun (it uses bun:sqlite and Bun-native hooks).
Do not install recall-memory from npm; that name belongs to an unrelated project (#312). Follow the canonical Installation guide for the current source-checkout or local-tarball bootstrap, then use the matching host guide below.
recall stats        # Database overview
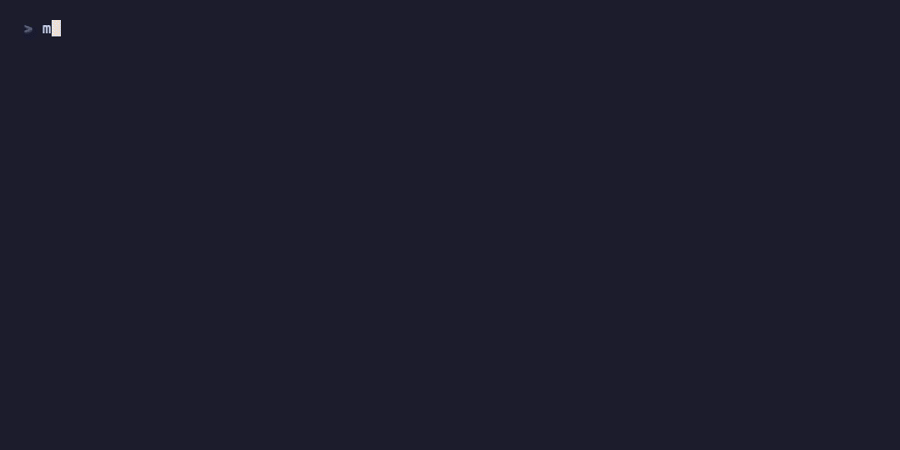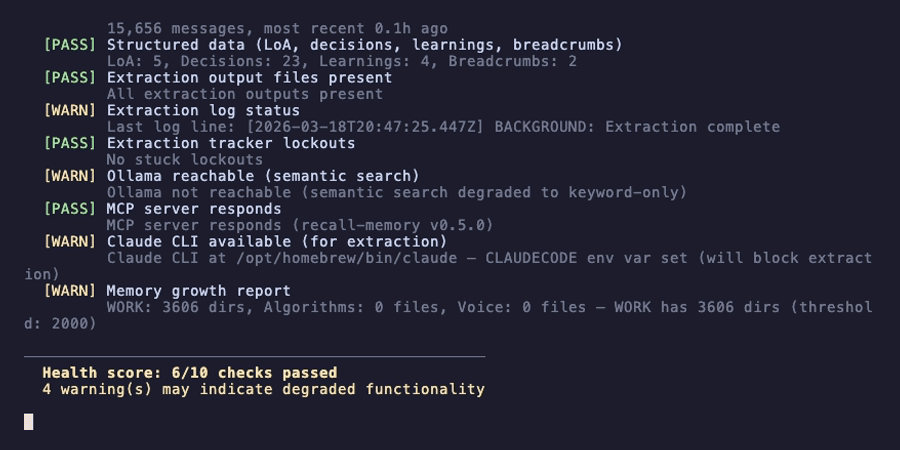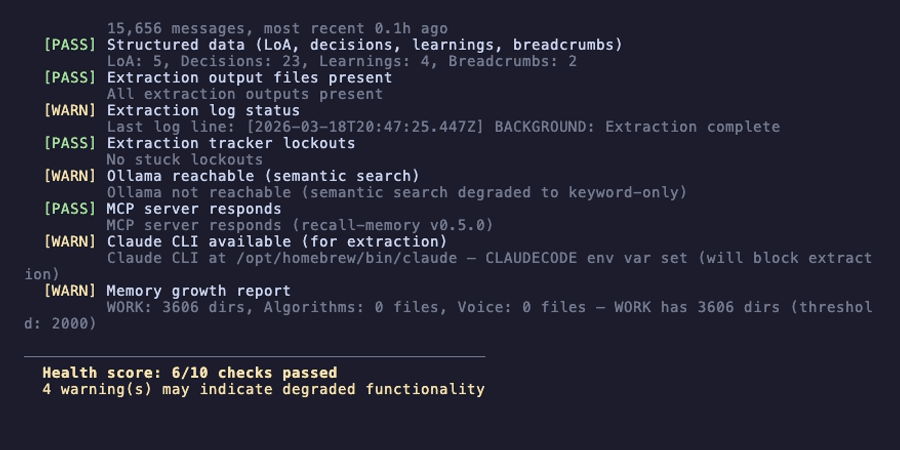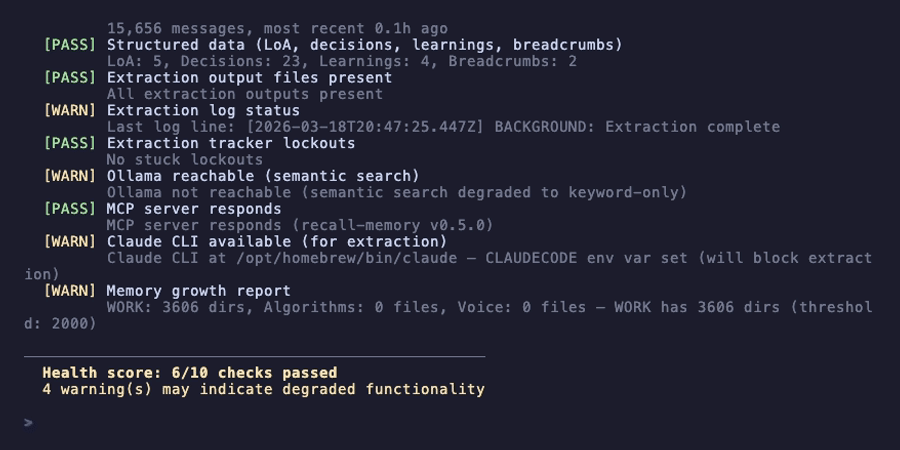
recall doctor       # Health check
Restart each attached agent so it loads the plugin, extension, or snippets.
The Installation guide owns the bootstrap sequence. Managing Recall explains when to use recall install versus ./packaging/install.sh for installer-owned surfaces.
First run: set your identity
Recall's supported session-start integrations inject a small identity file at the top of a session (the L0 tier — your role, projects, tools, and working preferences). Without it, L0 is empty and every new session has to re-learn the basics.
recall onboard
A 7-question interview that writes the resolved global identity file. On a new
install this is ~/.agents/Recall/MEMORY/identity.md; an existing user-owned
Claude identity remains authoritative. See the installation guide
for the shared resolver's precedence. Run it once.
Re-run whenever your role, active projects, or working preferences change.
Use | (not ,) to separate values so a phrase like no force-push, ever
survives as a single entry.
Updating
From inside Claude Code, /do-recall-update prints the current vs. latest
release and the exact command to run. From a shell:
./packaging/update.sh --check   # version check only
./packaging/update.sh           # full update: pull, build, migrate, re-register hooks
Installed from a local tarball? Follow the tarball upgrade procedure.
Uninstalling
./packaging/uninstall.sh --dry-run   # preview, touch nothing
./packaging/uninstall.sh             # surgical remove; preserves ~/.agents/Recall/ (DB + backups)
./packaging/uninstall.sh --purge     # destroy runtime + DBs; preserve identity/distilled snapshots (confirmed)
Installed from a local tarball? Follow the tarball cleanup procedure for removal, purge, or a preview.
Full installation guide — prerequisites, platform support, session extraction setup, uninstalling
How Recall Works
Recall sits between your agent and a single SQLite database. A WRITE path captures sessions where a host exposes a supported lifecycle surface; a READ path injects memory where a host supports session-start context. The diagram below shows the shared flows side-by-side, with the line styles in the legend distinguishing capture (solid), recall (dashed purple), and the write-only markdown mirror (dashed gray).
┌──────────────────────────────────────────────────────────────────────┐
│                        DATA ENTRY POINTS                             │
│                                                                      │
│  ┌────────────┐  ┌────────────┐  ┌──────────────┐  ┌────────────┐    │
│  │ CLI Direct │  │ MCP Server │  │  Stop Hook   │  │   Batch    │    │
│  │  recall add   │  │ (Claude    │  │ SessionExt-  │  │  Extract   │    │
│  │  recall dump  │  │  Code)     │  │  ract.ts     │  │  (cron)    │    │
│  └─────┬──────┘  └─────┬──────┘  └──────┬───────┘  └─────┬──────┘    │
└────────┼────────────────┼────────────────┼────────────────┼──────────┘
         │                │                │                │
         ▼                ▼                ▼                ▼
┌───────────────────────────────────────────────────────────────────────┐
│                      PROCESSING LAYER                                 │
│                                                                       │
│  Direct Inserts:              Session Extraction Pipeline:            │
│  recall add breadcrumb ──┐       Read JSONL                              │
│  recall add decision  ───┤         → Filter noise (tool results)         │
│  recall add learning  ───┤         → Dedup check (.extraction_tracker)   │
│  memory_add (MCP)  ───┤         → Acquire lock                        │
│                       │         → Automatic-capture Extractor         │
│                       │           (claude-cli, then ollama)           │
│                       │           (>120K? chunk → meta-extract)       │
│                       │         → Quality gate                        │
│                       │           (requires SUMMARY + MAIN IDEAS)     │
│                       │              │                                │
└───────────────────────┼──────────────┼────────────────────────────────┘
                        │              │
                        ▼              ▼
┌──────────────────────────────────────────────────────────────────────┐
│                    STORAGE LAYER (Dual-Write)                        │
│                                                                      │
│  SQLite (~/.agents/Recall/recall.db)  Memory Files (~/.agents/Recall/MEMORY/) │
│  ┌────────────────────────────┐     ┌──────────────────────────────┐ │
│  │ sessions ←── messages      │     │ DISTILLED.md    (archive)    │ │
│  │ decisions    learnings     │     │ HOT_RECALL.md   (last 10)    │ │
│  │ breadcrumbs  loa_entries   │     │ SESSION_INDEX.json           │ │
│  │ embeddings (1024-dim vecs) │     │ DECISIONS.log                │ │
│  │                            │     │ REJECTIONS.log               │ │
│  │ FTS5 indexes (auto-sync)   │     │ ERROR_PATTERNS.json          │ │
│  │ WAL mode · 0600 perms      │     └──────────────────────────────┘ │
│  └────────────────────────────┘                                      │
└──────────────────────────────────────────────────────────────────────┘
                        │
                        ▼
┌──────────────────────────────────────────────────────────────────────┐
│                      RETRIEVAL LAYER                                 │
│                                                                      │
│  ┌───────────────┐  ┌────────────────┐  ┌─────────────────────────┐  │
│  │Keyword (FTS5) │  │Semantic (Embed)│  │  Hybrid (RRF Fusion)    │  │
│  │recall search     │  │recall semantic    │  │  recall hybrid (DEFAULT)   │  │
│  │memory_search  │  │embed → Ollama  │  │  FTS5 rank ─┐           │  │
│  │               │  │cosine sim      │  │  Embed rank ─┤→ merged  │  │
│  └───────────────┘  └────────────────┘  │  RRF(k=60) ◄┘           │  │
│                                         └─────────────────────────┘  │
│  Direct: recall recent · recall show · memory_recall · context_for_agent   │
└──────────────────────────────────────────────────────────────────────┘
                        │
                        ▼
┌──────────────────────────────────────────────────────────────────────┐
│  CONSUMERS:  Coding agents (MCP)  ·  CLI user (recall)  ·  Sub-agents   │
└──────────────────────────────────────────────────────────────────────┘
The source .excalidraw file lives at assets/how-recall-works.excalidraw — drop it onto excalidraw.com to edit.
Where Jev sits
Jev scores structured extraction: one POST, one Choice per candidate. recall capture does not call it. If neither a non-blank process value nor $HOME/.env provides a key, or if a Jev request fails, Recall still writes the parsed rows.
flowchart TD
  subgraph scored [Structured extraction]
    claude["Claude Stop hook"] --> extract["RecallExtract"]
    batch["OpenCode and Pi markdown drops"] --> batchExtract["RecallBatchExtract --reextract-md"]
    batchExtract --> extract
    import["conversation import"] --> structured["writeStructuredExtraction"]
    extract --> parse["parse decisions, learnings, breadcrumbs"]
    structured --> parse
    parse --> key{"Jev key resolves?"}
    key -->|no| write["write every parsed row"]
    key -->|yes| jev["one POST, one Choice per candidate"]
    jev -->|scored| gate{"keep / demote / drop"}
    jev -->|timeout or bad response| write
    gate -->|keep| write
    gate -->|demote| low["write at importance 3"]
    gate -->|drop| omit["omit that row"]
  end
  subgraph bypass [Native raw capture]
    omp["omp session_stop"] --> door["recall capture"]
    codex["Codex Stop"] --> door
    grok["Grok lifecycle hook"] --> door
    door --> raw["write raw text, skip Jev"]
  end
Set JEV_RECALL_KEY in the environment or in ~/.env. A non-blank environment value wins. Walk through that once in Score one memory item with Jev.
Claude Code Session Lifecycle
- Session starts — A
SessionStarthook injects two tiers of context: L0 identity (your global or project-localidentity.md, always on) and L1 top records (top 12 by importance score, with 4 slots reserved for curated Library of Alexandria entries). L2/L3 stay on disk and are pulled on demand via MCP search. - During the session — your agent searches memory via MCP tools (
memory_search,memory_hybrid_search,memory_recall,context_for_agent) before falling back to git history. Decisions, learnings, and breadcrumbs are recorded in real-time withmemory_add. - End of every turn — A
Stophook firesRecallExtract.ts, which self-spawns a background process (non-blocking). It checks.extraction_tracker.jsonand only re-extracts if the conversation has grown meaningfully since last time — so capture is incremental, not just an "on exit" event. - Extraction pipeline — The conversation JSONL is filtered, deduplicated, and run through the Automatic-capture Extractor (default
claude-cli, thenollama; chunking for sessions >120K chars). A quality gate rejects low-quality extractions before they're stored. Optional per-path config: architecture. - PreCompact flush — When Claude Code is about to compact its context, a
PreCompacthook (RecallPreCompact.ts) flushes the in-flight messages first, so the squashed window is never lost. - Dual-write storage — Results are written to SQLite (the only query surface — every CLI/MCP read hits this) and to markdown artifacts (
DISTILLED.md,HOT_RECALL.md, etc., write-only, human-readable). - Batch catchup (optional) — A cron job (
RecallBatchExtract.ts) sweeps any sessions the Stop hook missed during crashes or interruptions, and ingests sessions dropped by the OpenCode plugin and Pi extension into~/.agents/Recall/MEMORY/{opencode,pi}-sessions/. For scheduling, see optional batch extraction and managed quarterly aging. - TELOS auto-sync (PAI users) — If you use Personal AI Infrastructure (PAI), Recall ships a
RecallTelosSync.tsSessionStart hook that watches~/.claude/skills/PAI/USER/TELOS/for changes and silently runsrecall telos import --updatewhen any file is newer than the last import. This is automatic — no action required once Recall is installed and PAI's TELOS directory exists. You can also import manually at any time withrecall telos import --yes. If you don't use PAI, the hook checks for the directory, finds nothing, and exits in under 1ms.
Search Strategies
Narrowing by record type — table vs bias_type. Both let you steer results toward decisions, learnings, breadcrumbs, LoA entries, or raw messages, but they differ in strength:
-t/tableis a hard filter — only the named record type comes back.--bias-type/bias_typeis a soft boost — matching records of that type rank higher, but every other type can still appear when it's relevant.
Where it's available: table and bias_type act on FTS5 ranking, so they exist only on the keyword path — recall search, recall "query" -k, and the MCP memory_search tool. They are silently ignored elsewhere: plain recall "query" (default hybrid), recall "query" -v (semantic), and memory_hybrid_search rank by embedding distance and have no bias_type. Valid types: messages, decisions, learnings, breadcrumbs, loa.
Architecture deep-dive — database tables, FTS5 indexes, extraction pipeline details
What You Get
- Auto-captured session memory — Claude Stop shells
recall captureand still extracts; Codex, Grok, omp, and Pi shutdown call the same door; OpenCode stays on its markdown drop; JCode calls it only when text is supplied - MCP server (
recall-mcp) —memory_search,memory_hybrid_search,memory_recall,memory_add,memory_dump,context_for_agentexposed to your agent mid-session.memory_searchsupportstablehard filters andbias_typesoft boosts. - Hybrid search — FTS5 keyword search + optional Ollama embeddings, fused via Reciprocal Rank Fusion. Lose Ollama, lose nothing — keyword path keeps working. Type targeting (
table/bias_type) is a keyword-path feature — see Search Strategies. - Tiered RecallStart (v0.7.0+) — resolved L0 identity + L1 top 12 records ranked by importance, with 4 reserved slots for curated Library of Alexandria entries. L2/L3 fetched on demand
- Importance scoring (1–10) — every record carries an importance score that drives what surfaces in L1. Manage with
recall pin/recall unpin/recall importance backfill - PreCompact flush —
RecallPreCompact.tswrites in-flight messages to SQLite before Claude compacts its context window, so the squashed chunk is never lost - Decision lifecycle —
recall decision supersede/reverttracks when a decision was replaced or rolled back; confidence scoring (high/medium/low) on every decision and learning - Cross-host ingestion — Claude, Codex, Grok, omp, Pi, and supplied-text JCode write ambient text through
recall capture. OpenCode keeps its drop-and-batch path. One database remains searchable from every connected host - Library of Alexandria — Automatic-capture LoA from session extract (importance 6, excluded from reserved L1 LoA slots). Curated LoA from
recall loa/ dump via thefabricExtractor (extract_wisdom); default importance 8, reserved L1 slots. Optional per-path Extractor config: architecture - TELOS integration (PAI users) —
RecallTelosSync.tsauto-imports your TELOS framework files (goals, mission, projects, strategies) from PAI'sUSER/TELOS/directory on every session start. Changes are detected by mtime; unchanged files are skipped. Manual import:recall telos import --yes - Breadcrumbs, decisions, learnings — three structured record types for non-session memory, addable from CLI (
recall add), MCP (memory_add), or thedo-recall-addagent skill - Codebase scouting —
/do-recall-scout [focus]produces a memory-first scout report (repo map, key paths, tests, risks, next steps) for orienting in an unfamiliar repo, with a strict no-secrets boundary and chat-only-by-default output - Benchmark harness —
recall benchmark run Bmeasures wake-up context efficiency against locked baselines so regressions are visible - Onboarding —
recall onboardruns a 7-question interview that writes your L0 identity file
Measured wake-up efficiency
Suite B measures the byte cost of session-start memory injection. Latest tracked run (2026-04-18, scope atlas-recall):
v2 is 51% smaller than v1 on this corpus. CLAUDE.md is hand-written static context; Recall is auto-extracted dynamic memory — the two are complementary, not competitors. Numbers scale with your own DB and L0 identity; reproduce with recall benchmark run B. Methodology and caveats live in docs/benchmarks/README.md.
CLI at a Glance
recall "kubernetes auth"          # Search your memory
recall onboard                    # Seed your L0 identity tier (one-time)
recall dump "Session Title"       # Save this session
recall add decision "Use X" ...   # Record a decision
recall decision list              # List decisions with status and confidence
recall pin decisions 42           # Pin a record to high importance
recall benchmark run B            # Measure wake-up context efficiency
recall prune                      # Preview stale records for removal
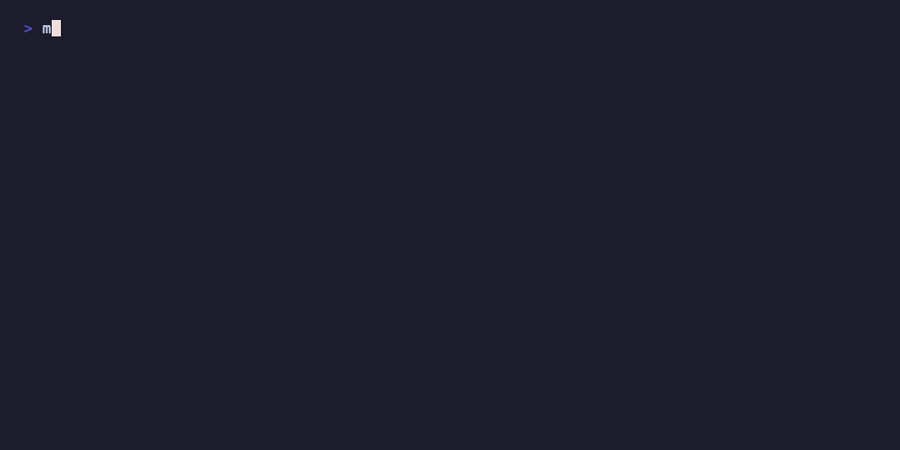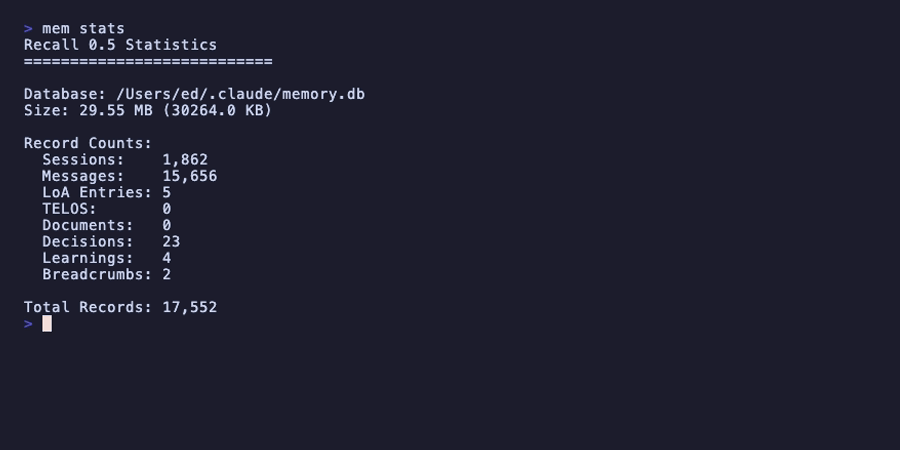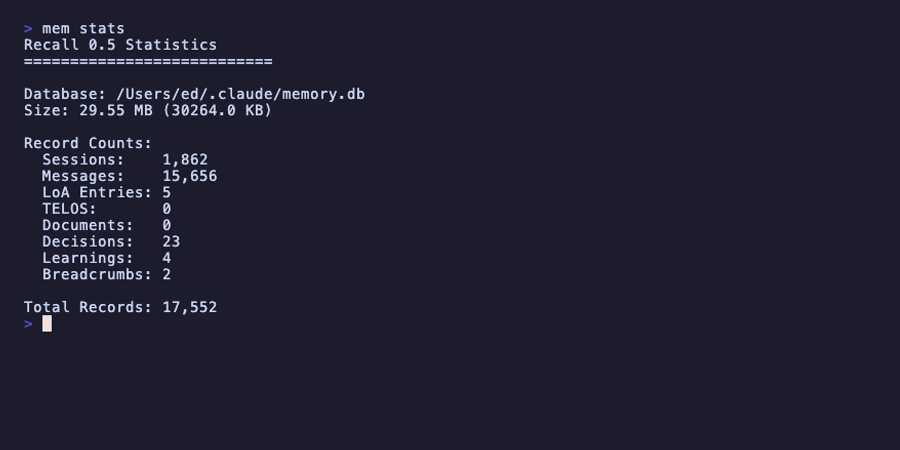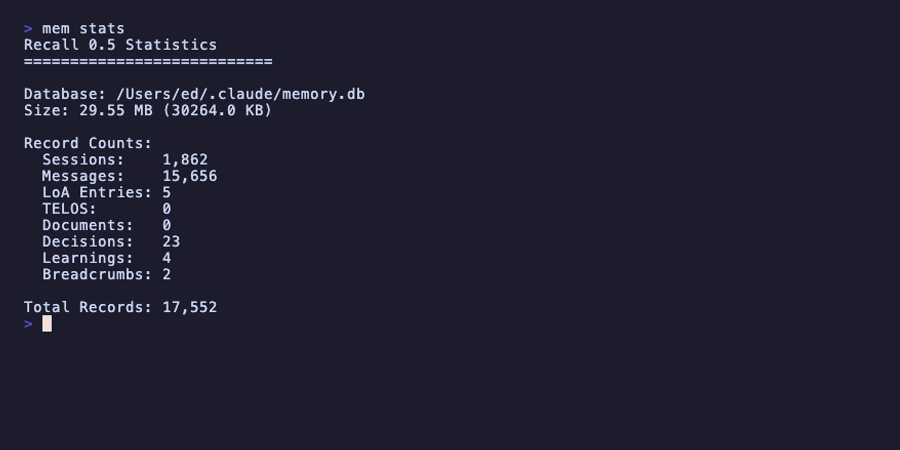
recall stats                      # See what's stored
recall doctor                     # Health check
| Search | Stats |
|---|---|
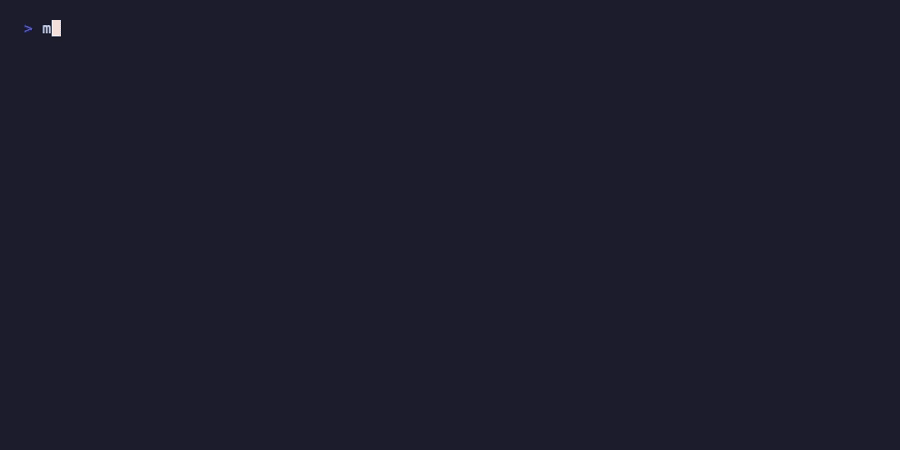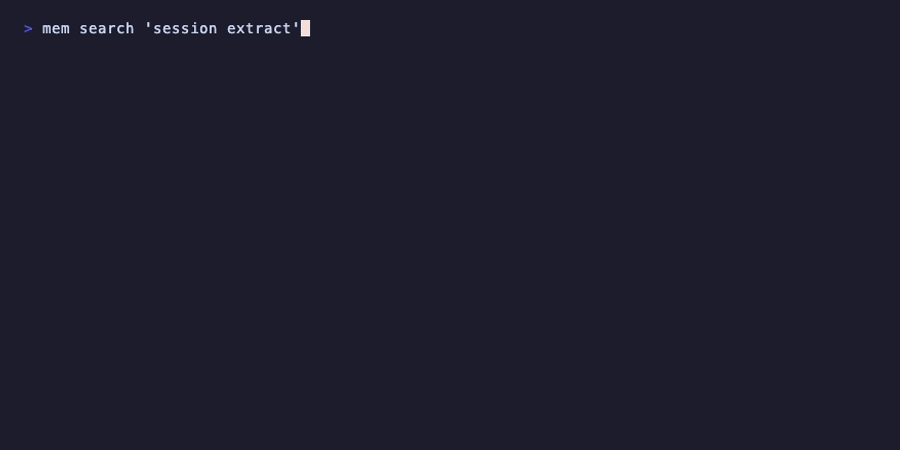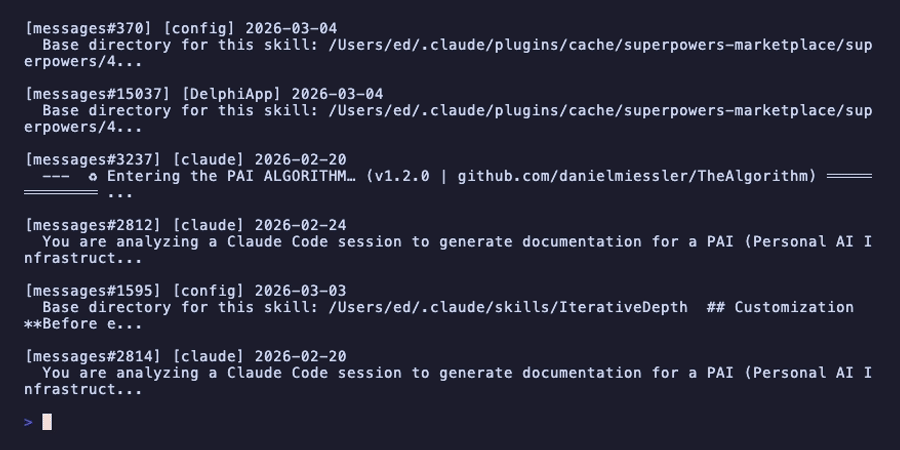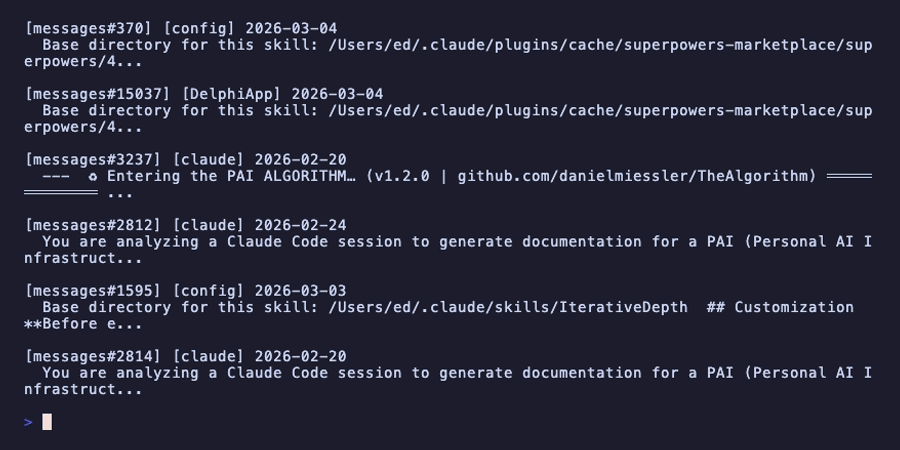 |  |
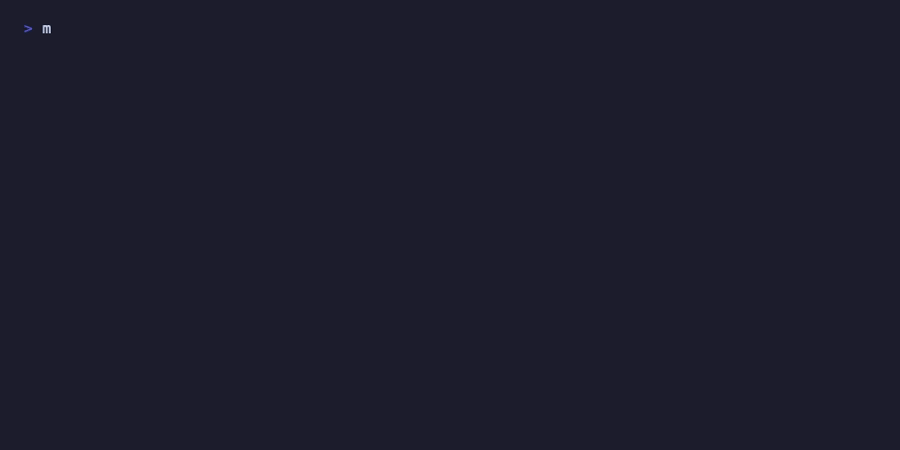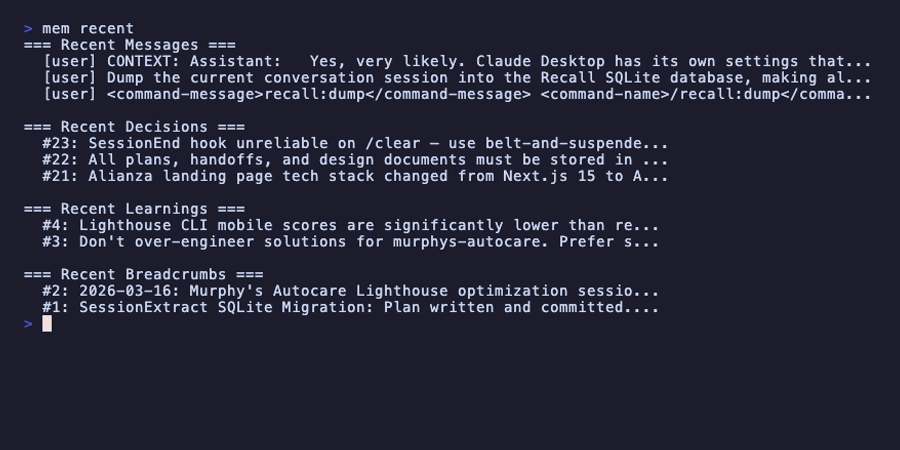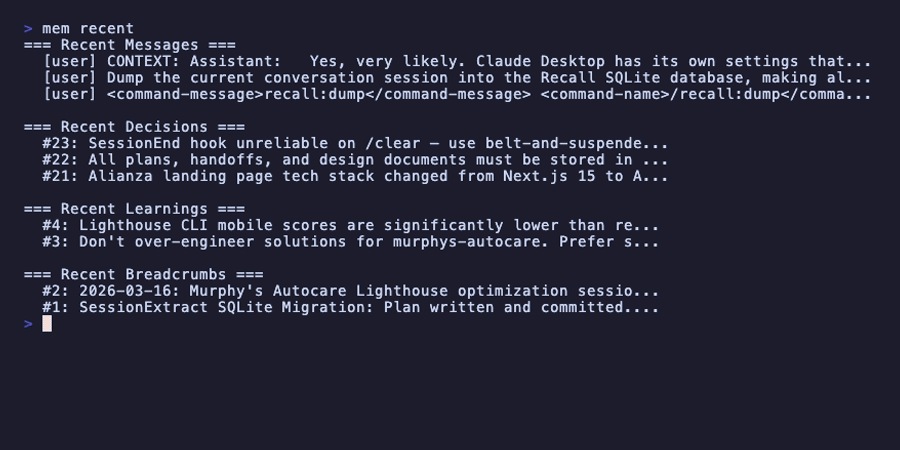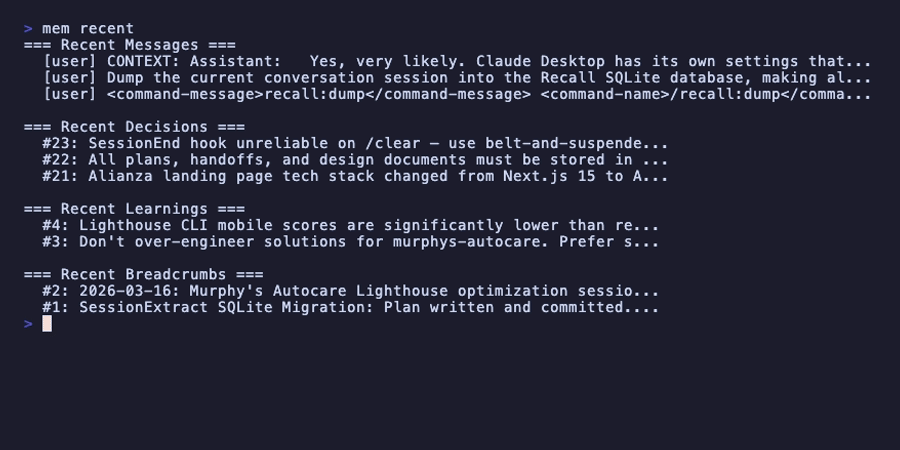
| Health Check | Recent Memory |
|---|---|
 |  |
For AI Agents
If you're an AI agent reading this repository:
Roadmap
Recall separates MCP and skills, automatic capture, and automatic injection. A host can support one without supporting the others.
Cursor sessionStart uses unqualified recall start --format cursor (templates/cursor/). Cursor.app GUI PATH typically lacks ~/.bun/bin, so the hook is a no-op until recall is on that app PATH. CLI Cursor or a shell where recall resolves is fine. Durable GUI PATH / recall start --format cursor accuracy is pending FM-321/327; do not invent a wrapper in the meantime.
Unattended lifecycle writes pass the scrub gate from #50. Agent Skill bodies remain canonical under #228. Installer-owned files follow surgical ownership from #236.
Have an agent you'd like to see supported? Open an issue — Recall is designed to be agent-agnostic, and any host that speaks MCP is a candidate.
Documentation
Acknowledgments
Graciously borrowing and features inspired by:
- MemPalace — tiered session-start context, PreCompact hook, importance scoring
- Personal AI Infrastructure (PAI) — TELOS framework integration
License
MIT