
noapi-google-search-mcp
If you want to support noapi-google-mcp or gpt-oss-20B/120B-Vision and other open source models in the pipeline please add to my GPU compute fund: around $3000 are needed.
If you find this useful, consider supporting continued development and new features.BTC:
16DT4AHemLyn7C6P116YepjY518gu9wUUHETH:0x7287D1F9c77832cFF246937af0443622bFdACD04
38 tools. Zero API keys. Give any local LLM real Google search, live feeds, vision, OCR, and full video understanding.
An MCP server that turns your local LLM into a fully connected assistant. Real Google results, live news and social feeds, reverse image search, offline OCR, YouTube transcription and clip extraction — all running locally through headless Chromium and open-source ML models. No API keys, no usage limits, no cloud dependency.
Works with LM Studio, Claude Desktop, OpenClaw, Ollama, and any MCP-compatible client.
What's New in v0.3.1 — Anti-Bot Detection & Neural Net CAPTCHA Solver
Google started catching headless Chromium browsers and serving CAPTCHAs instead of search results (#2). Fixed it properly and then added a neural net CAPTCHA solver just for the hell of it.
Stealth patches:
- JavaScript injection before every page load patches
navigator.webdriver, fake browser plugins,chrome.runtime, and removes Playwright fingerprints - Fixed User-Agent mismatch (was
aarch64, now matches the actual Chromium binary) - Cookie persistence between sessions so Google sees a returning browser, not a fresh bot
- Human-like random delays between page interactions
- Clear error messages when rate-limited instead of cryptic timeouts
Neural net CAPTCHA solver (MobileNetV2 + OpenCV):
- When Google serves a reCAPTCHA image challenge ("Select all images with traffic lights"), the server now attempts to solve it automatically
- Uses MobileNetV2 (ImageNet classifier, ~13MB ONNX model, auto-downloads on first encounter)
- OpenCV splits the CAPTCHA grid into cells, each cell is classified by the neural net and matched against the prompt
- Covers 22 common CAPTCHA categories: traffic lights, buses, bicycles, motorcycles, cars, bridges, boats, trains, trucks, fire hydrants, parking meters, tractors, and more
- Human-like mouse movement for clicking cells and the verify button
- Falls back gracefully if the challenge type isn't supported
Will it solve every CAPTCHA? No. But it'll get through some of them, and honestly we mostly built it because we could.
What's New in v0.3.0 — 16 New Tools
YouTube RAG — Subscribe, Transcribe, Search, Clip
A full local retrieval-augmented pipeline for YouTube. Subscribe to any channel, and when you check feeds the server automatically downloads the audio, transcribes it with Whisper, and stores the full transcript in SQLite with FTS5 full-text search. Every word from every video becomes searchable — ask your LLM a question and it pulls the answer from the right video.
Found something interesting? Ask the LLM to extract that segment as a clip. It reads the transcript, finds the exact timestamps, and cuts the video for you. This is the beginning of AI/LLM-powered video editing — your LLM understands the content and cuts clips based on what's being said, not just timestamps.
How it works:
subscribeto a YouTube channel — by handle (@3Blue1Brown), URL, or channel IDcheck_feeds— new videos are fetched and auto-transcribed locally with faster-whisper. Transcripts are written into the database for instant search. Up to 5 videos per check, cached so nothing gets re-downloaded.search_feeds— full-text search across all transcripts. Supports AND, OR, NOT, and quoted phrases. Your LLM finds the exact video and passage that answers your question.extract_video_clip— tell the LLM what you're interested in and it cuts the clip from the video. The LLM uses the transcript to find the right segment and extracts it automatically.
"Subscribe to @AndrejKarpathy on YouTube"
"Check my feeds"
"Search my feeds for backpropagation explained"
"What did Karpathy say about tokenization?"
"Extract the part where he explains gradient descent"
"Cut a clip of the hardware comparison section"
No embeddings, no vector database, no API — just Whisper + SQLite FTS5 running on your machine.
Roadmap: The clip extraction is the first step toward full AI-driven video editing. Future releases will add music/audio overlay, video remixing, multi-clip compilation, vertical reformat for TikTok/Reels/Shorts, and automated highlight reels — all driven by your LLM understanding the content.
Live Feed Subscriptions
Subscribe to news, Reddit, Hacker News, YouTube channels, Twitter/X profiles, GitHub repos, arXiv papers, and podcasts. Content is fetched, stored locally in SQLite with full-text search, and available to your LLM instantly.
Pre-configured news sources — subscribe with one word: bbc, cnn, nyt, guardian, npr, aljazeera, techcrunch, ars, verge, wired, reuters
arXiv shortcuts — ai, ml, cv, nlp, robotics, crypto, systems, hci
"Subscribe to BBC News, r/LocalLLaMA, and Hacker News"
"Follow @elonmusk on Twitter"
"Subscribe to the YouTube channel @3Blue1Brown"
"Watch anthropics/claude-code on GitHub for new releases"
"Subscribe to the machine learning arXiv category"
"Check my feeds"
"Search my feeds for transformer architecture"
"What's new in my Reddit feeds?"
Local File Processing
Transcribe meetings, convert formats, read documents — all local, no cloud.
Email, Web Utilities & Cloud
Pull emails, generate QR codes, shorten URLs, archive pages, look up Wikipedia, upload to S3.
"Transcribe this recording: ~/meeting.mp3"
"Convert video.mp4 to mp3"
"Read this PDF: ~/report.pdf"
"Check my email: [email protected] password: xxxx"
"Shorten this URL: https://very-long-url..."
"Generate a QR code for https://mysite.com"
"Archive this article: https://news.example.com/story"
"Wikipedia: quantum computing"
"Upload report.pdf to my MinIO bucket"
Zero extra dependencies for feeds. Built entirely on Python stdlib — SQLite for storage, FTS5 for search, urllib for fetching, xml.etree for parsing. YouTube and Twitter use the existing Playwright browser. FFmpeg required for convert_media (commonly pre-installed).
All 38 Tools by Category
Live Feed Subscriptions
Google Search & Web
Travel & Commerce
Finance & Info
Vision & OCR
Video & Audio Intelligence — AI-Powered Video Editing
Documents & Data
Web Utilities
Cloud Storage
Supported File Formats
Documents (read_document)
Audio & Video (transcribe_local, transcribe_video, convert_media)
Images (google_lens, google_lens_detect, ocr_image, list_images)
Why This Instead of API-Based Alternatives?
Tool Details & Parameters
Feed Subscription Tools
subscribe — Add a Content Source
Identifier formats by type:
- news: preset name (
bbc,cnn,nyt,guardian,npr,aljazeera,techcrunch,ars,verge,wired,reuters) or any RSS URL - reddit: subreddit name (e.g.
LocalLLaMA,programming) - hackernews:
top,new, orbest - github:
owner/repo(e.g.anthropics/claude-code) - arxiv: shortcut (
ai,ml,cv,nlp,robotics,crypto) or category likecs.AI - youtube: channel handle (
@3Blue1Brown), URL, or channel ID (UCxxxx) - podcast: RSS feed URL
- twitter: username with or without
@
check_feeds — Fetch New Content
search_feeds — Full-Text Search
get_feed_items — Browse Recent Items
Google Search Tools
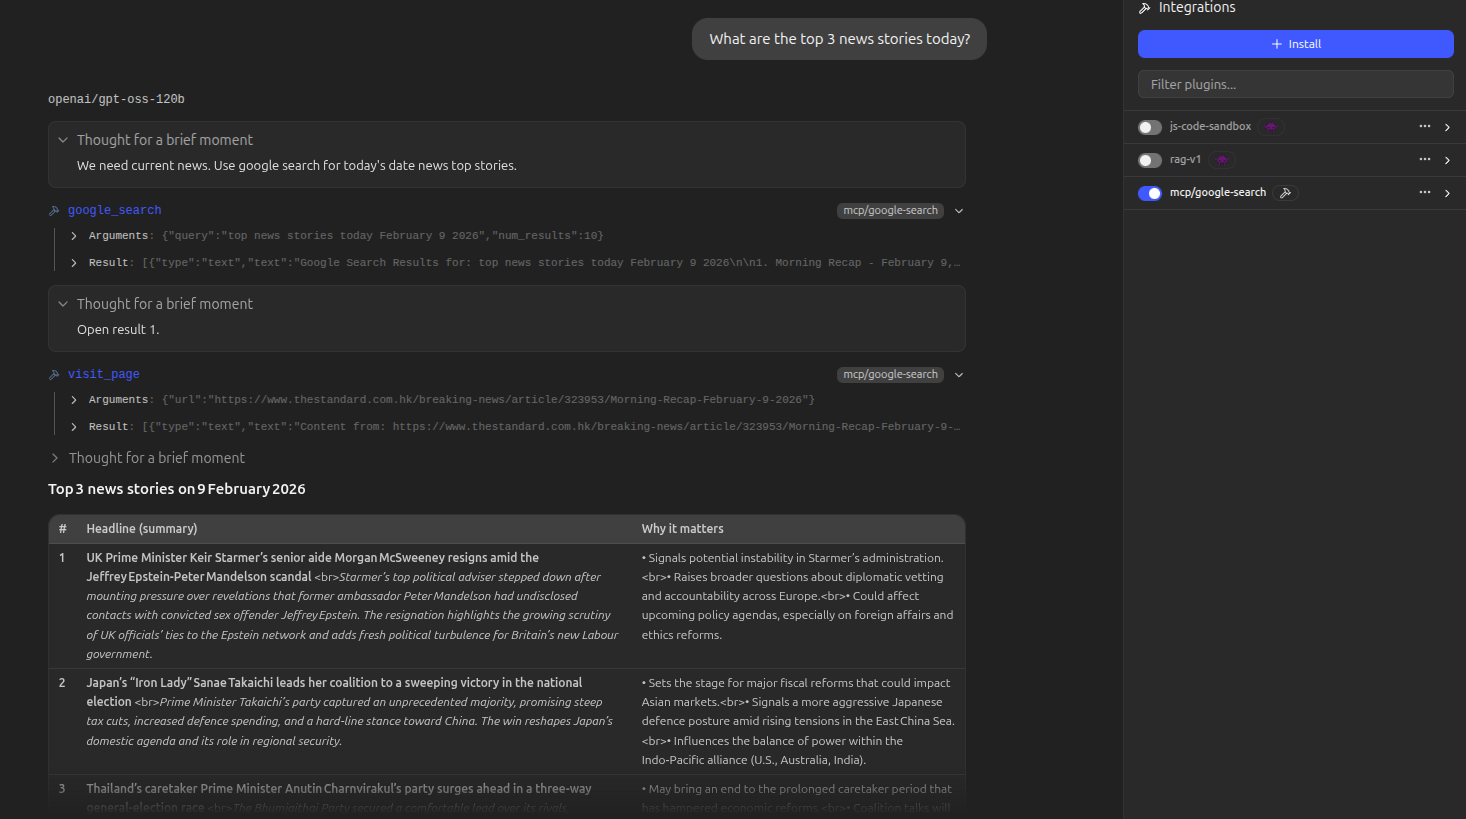
google_search — Web Search
google_shopping — Product Search
google_flights — Flight Search
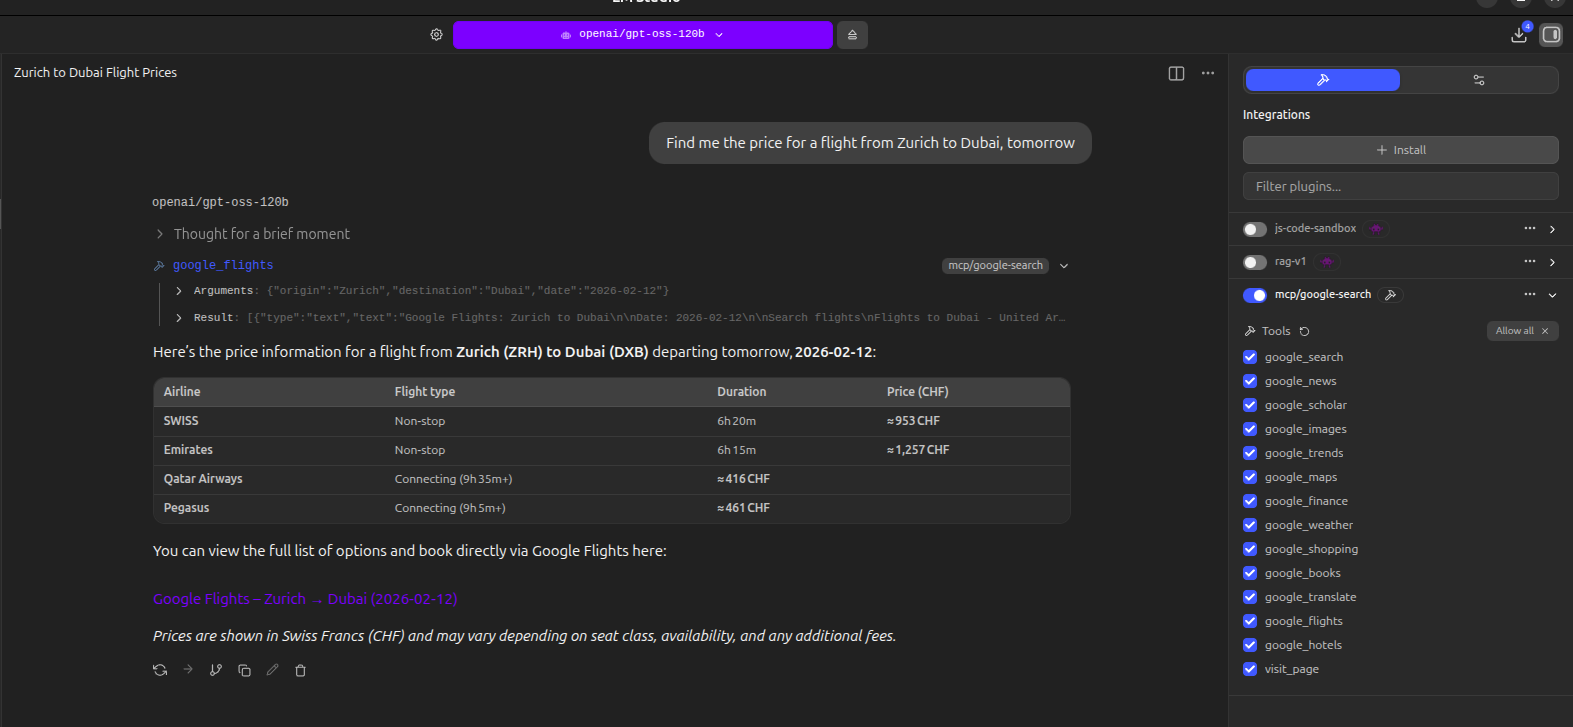
google_hotels — Hotel Search
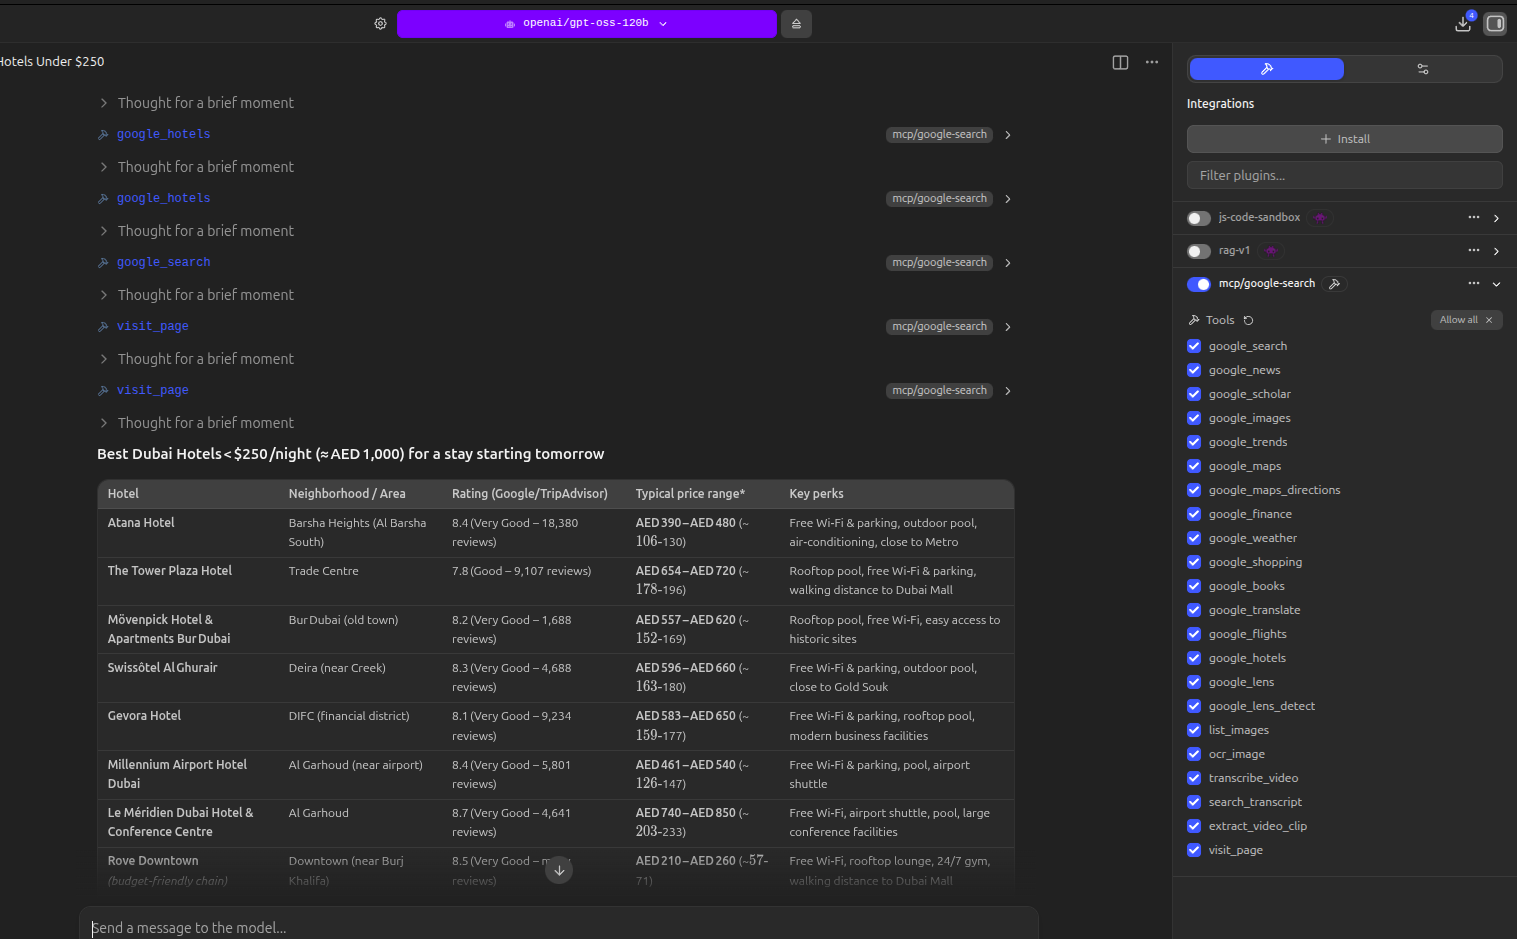
google_translate — Translation
google_maps — Places Search with Map Screenshot
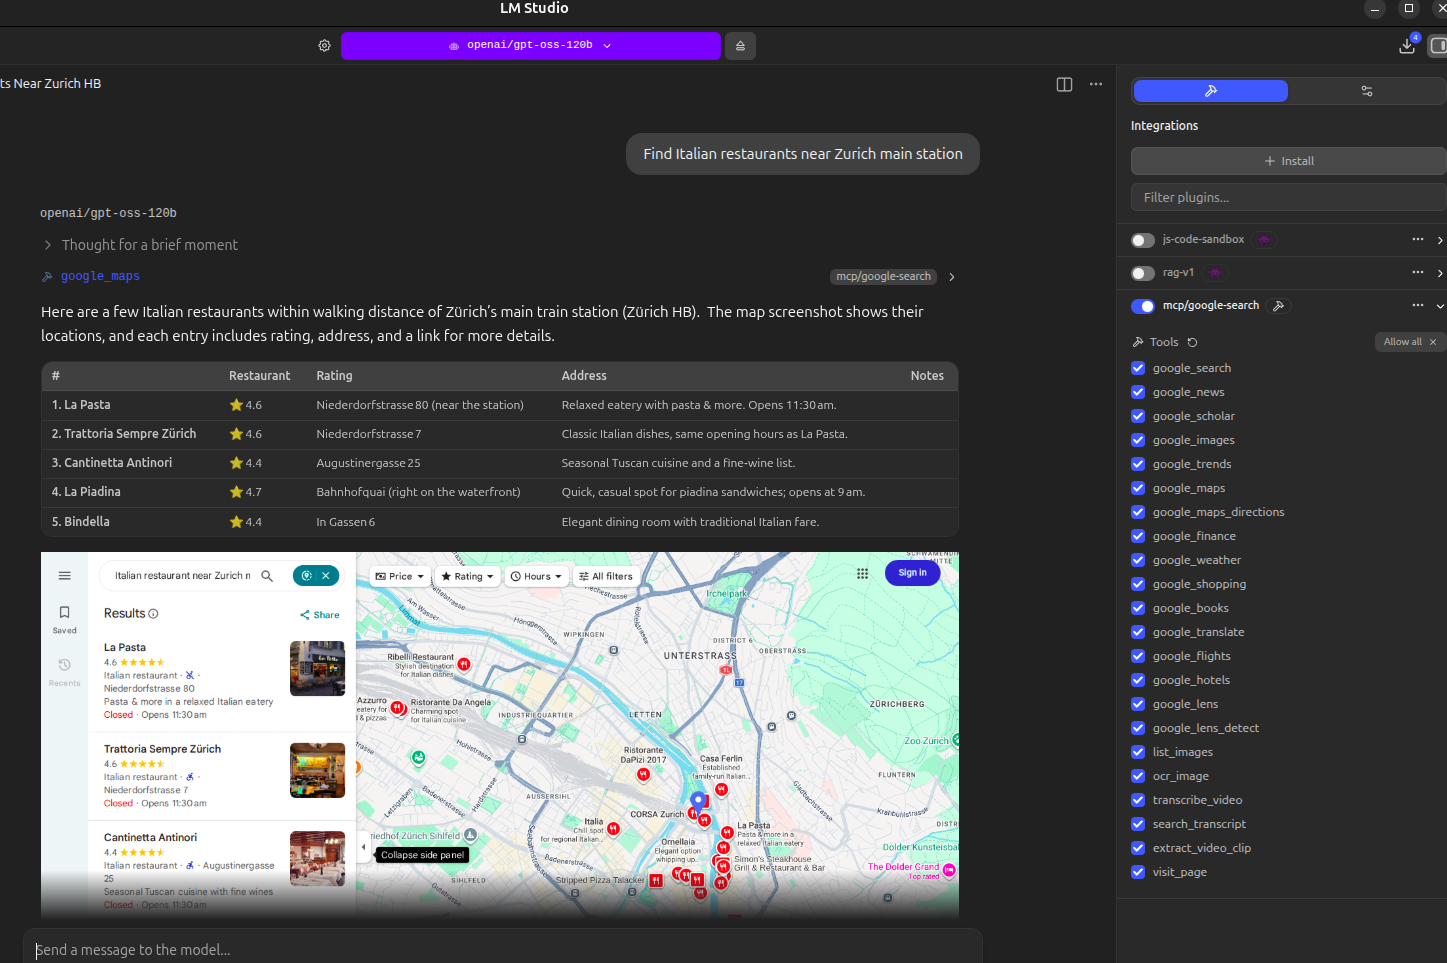
google_maps_directions — Route Directions with Map
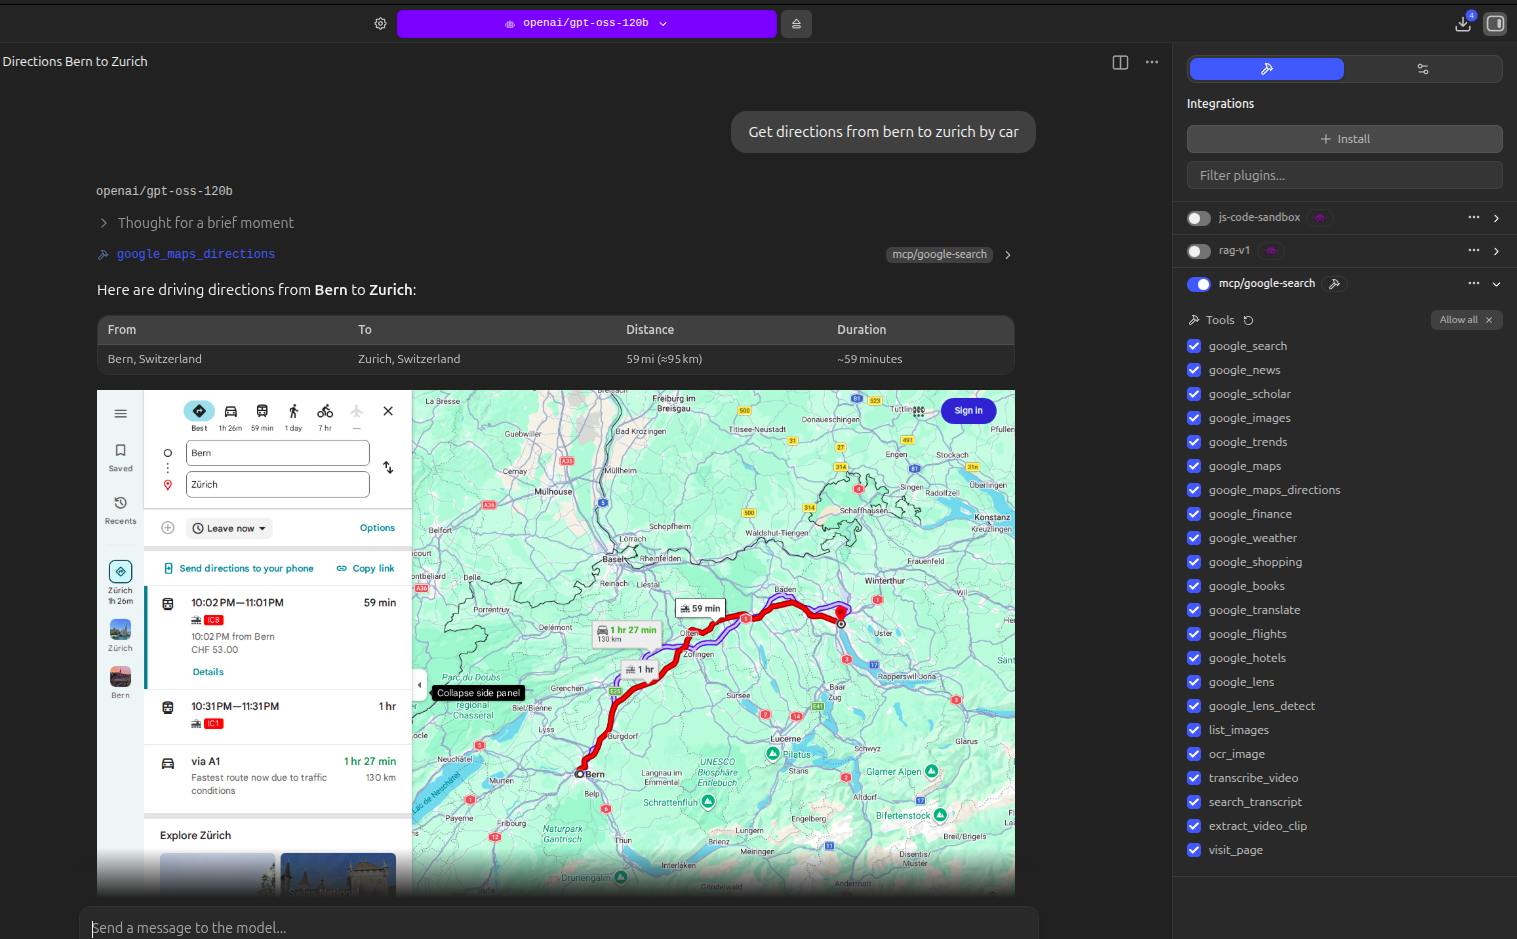
google_weather — Weather
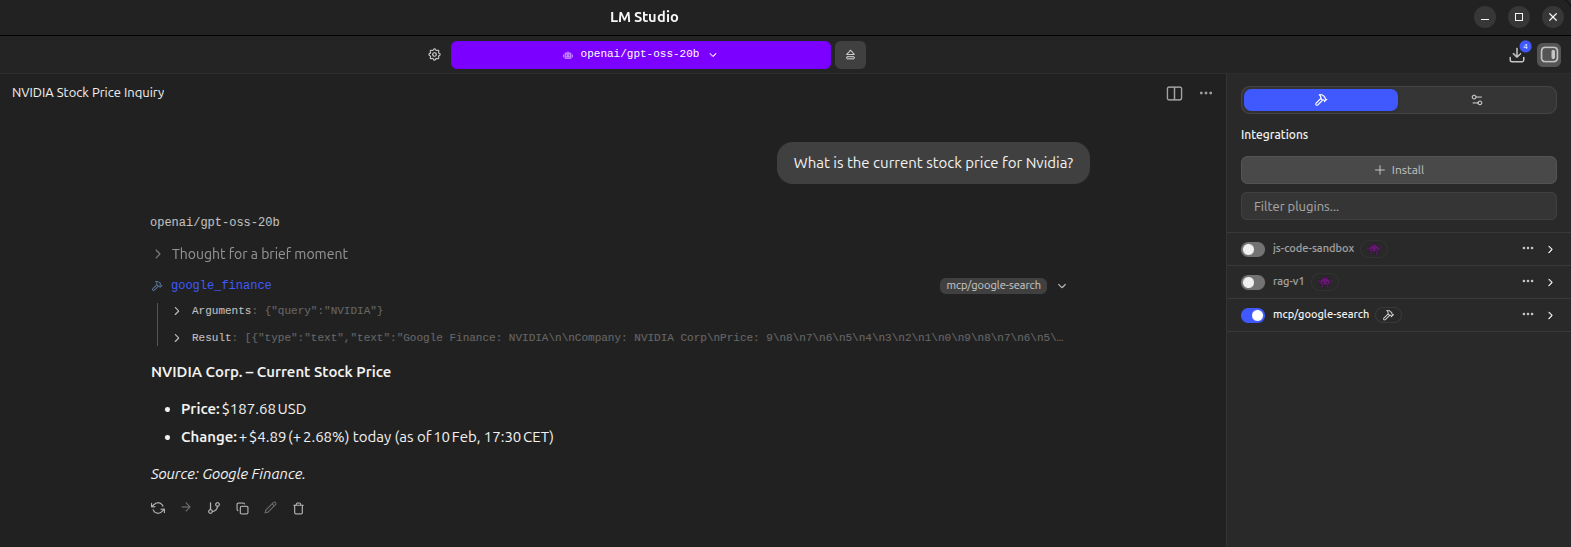
google_finance — Stock & Market Data
google_news — News Search
google_scholar — Academic Search
google_books — Book Search
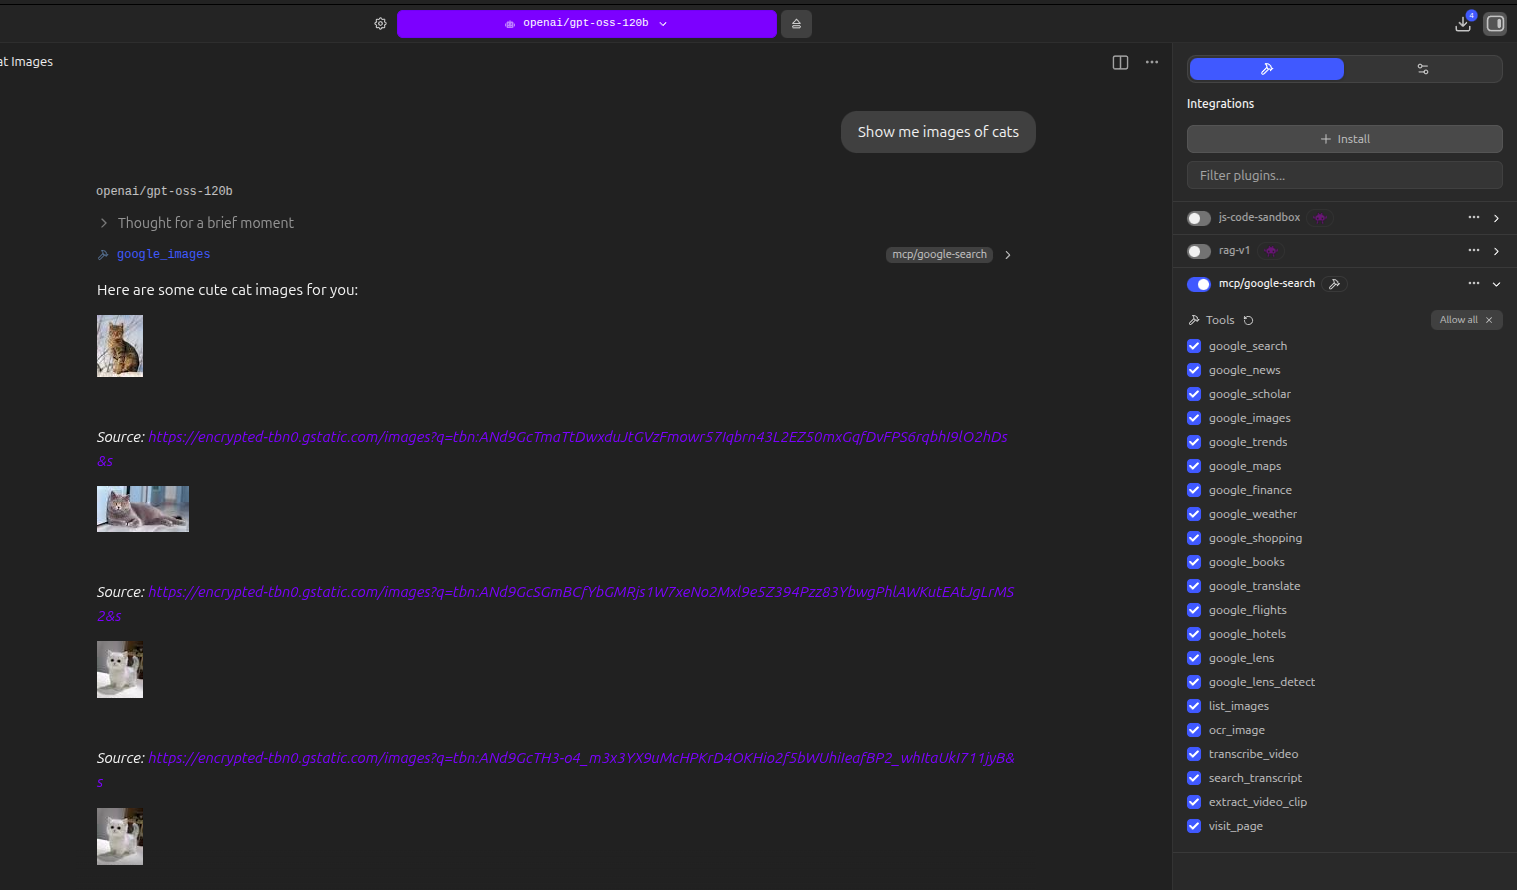
google_images — Image Search (inline in chat)
google_trends — Trends
Vision & OCR Tools
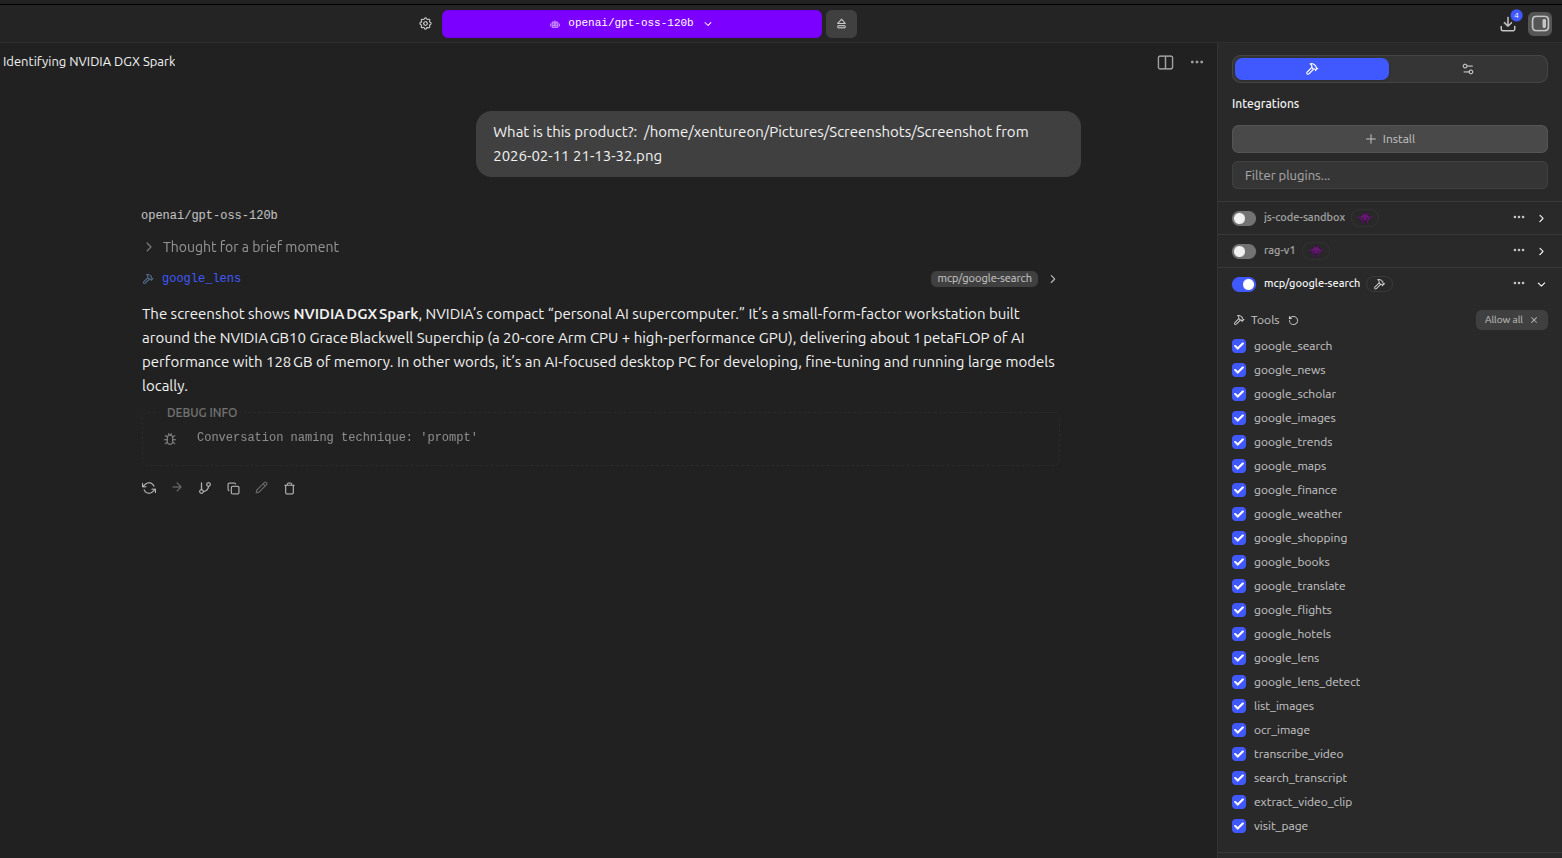
google_lens — Reverse Image Search
Identify objects, products, brands, landmarks, and text. Supports URLs, local files, and base64 drag-and-drop.
google_lens_detect — Object Detection + Identification
Detect all objects (OpenCV), crop each one, identify individually via Lens.
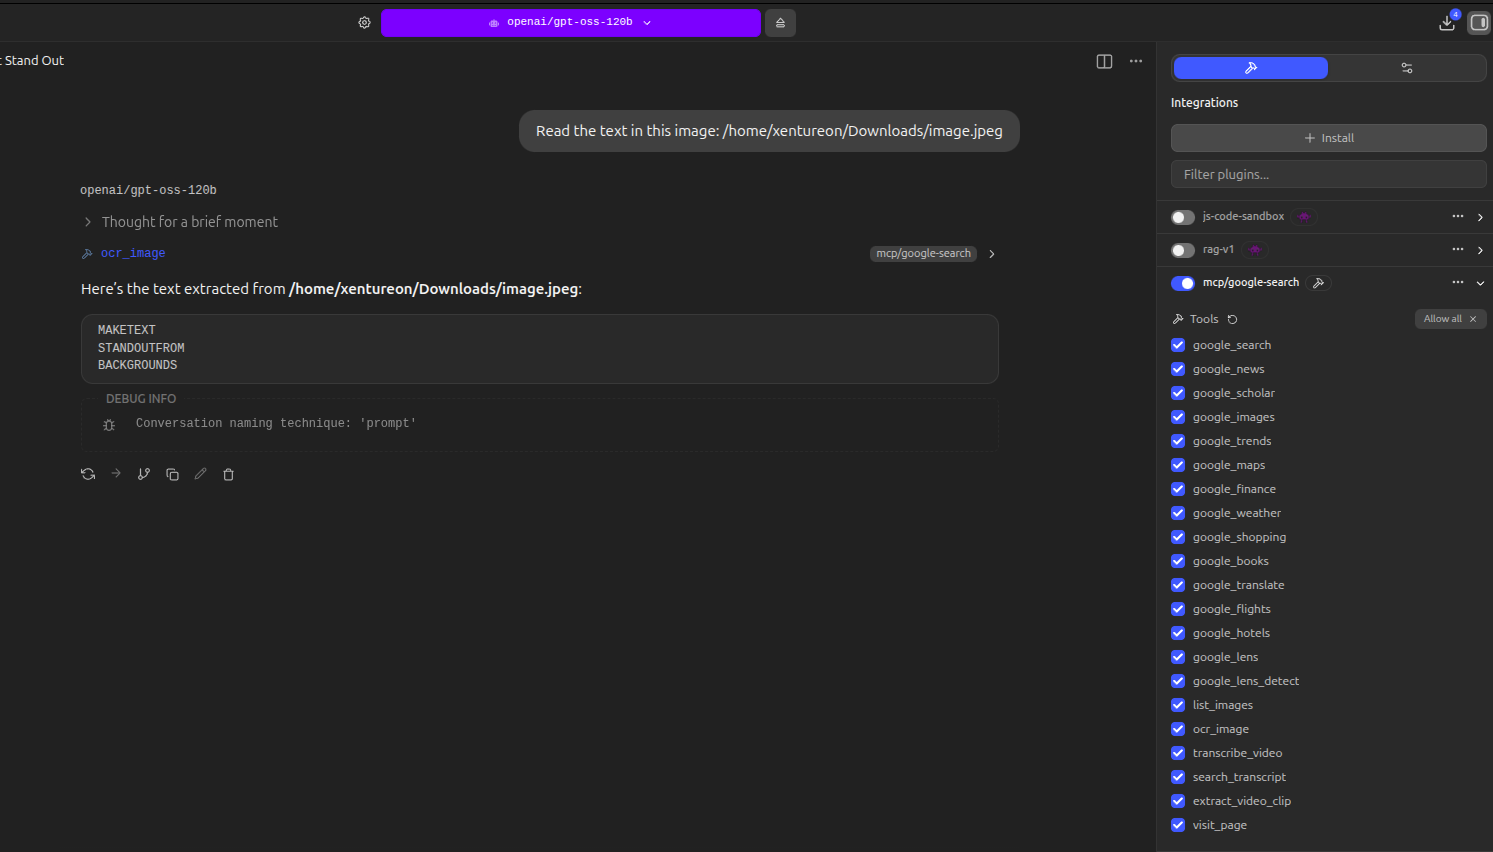
ocr_image — Local OCR (offline)
Extract text from images using RapidOCR. No internet needed.
list_images — Image Discovery
Video Intelligence Tools
transcribe_video — Video Transcription
Download and transcribe any YouTube video (or video URL) with timestamps using faster-whisper.
search_transcript — Transcript Search
extract_video_clip — Clip Extraction by Topic
Ask "extract the part about X" and the LLM finds timestamps from the transcript and cuts the clip.
Sample Prompts
Feed Subscriptions
Web Search
Shopping & Travel
Maps & Directions
Finance, Weather & Info
Images & Vision
Tip: To enable drag-and-drop images with text-only models in LM Studio, add a
model.yamlfile in the model directory withmetadataOverrides: { vision: true }. The image will be sent as base64 and the MCP tools handle it automatically.
Video Intelligence & AI-Powered Clip Extraction
Documents & Email
Web Utilities & Cloud
Installation
Quick Install (pipx - recommended)
pipx install noapi-google-search-mcp
playwright install chromium
Install in a Virtual Environment
python3 -m venv ~/.local/share/noapi-google-search-mcp
~/.local/share/noapi-google-search-mcp/bin/pip install noapi-google-search-mcp
~/.local/share/noapi-google-search-mcp/bin/playwright install chromium
Python 3.13 / OCR
The core package installs on every supported Python, including 3.13. OCR is
opt-in because rapidocr-onnxruntime does not yet ship a Python 3.13 wheel
upstream (RapidAI/RapidOCR#579).
Everything except the OCR tools (ocr_image and the scanned-PDF fallback in
read_document) works without it.
To enable OCR, add the [ocr] extra on a compatible Python (3.10–3.12):
pipx install "noapi-google-search-mcp[ocr]"
If you install the core package and later call an OCR tool without the extra,
the tool returns a short message telling you to install
"noapi-google-search-mcp[ocr]" instead of crashing.
Configuration
LM Studio
Add to ~/.lmstudio/mcp.json:
{
  "mcpServers": {
    "google-search": {
      "command": "noapi-google-search-mcp",
      "env": {
        "PYTHONUNBUFFERED": "1"
      }
    }
  }
}
If installed in a venv, use the full path: ~/.local/share/noapi-google-search-mcp/bin/noapi-google-search-mcp
How much page text visit_page returns
visit_page truncates at 8000 characters by default. That suits a small
local model and is not enough for reading long documentation, so it is
settable from the same env block:
{
  "mcpServers": {
    "google-search": {
      "command": "noapi-google-search-mcp",
      "env": {
        "PYTHONUNBUFFERED": "1",
        "MAX_PAGE_CHARS": "20000"
      }
    }
  }
}
max_characters is accepted as an alias. Values are clamped to 200000 —
this text goes into a model's context window, and a tool that can return a
megabyte turns one careless page visit into a blown context. A value that
is not a positive number is ignored and the default is used, so a typo here
cannot stop the server from starting.
Claude Desktop
Add to your Claude Desktop config (claude_desktop_config.json):
{
  "mcpServers": {
    "google-search": {
      "command": "noapi-google-search-mcp"
    }
  }
}
OpenClaw
Add to your agent configuration:
mcp_servers:
  google-search:
    command: "noapi-google-search-mcp"
    env:
      PYTHONUNBUFFERED: "1"
This gives your OpenClaw agent access to all 38 tools — real Google search, live feeds, vision, OCR, and video intelligence — with zero API keys.
As a CLI
noapi-google-search-mcp
Or:
python -m google_search_mcp
Development
git clone https://github.com/VincentKaufmann/noapi-google-search-mcp.git
cd google-search-mcp
pip install -e .
playwright install chromium
License
MIT