
memalyze
MCP-native, self-hosted memory for AI agents — with the governance an enterprise will actually ask for.
One static binary. Local embeddings. No cloud, no graph database, no Python stack. Redaction happens before anything is written; every read is audited.
Website · MCP Registry · v0.1.0
./memalyze # MCP over stdio, for Claude Code / Cline / any harness
v0.1.0 is out — static binaries for linux/darwin/windows, checksums published alongside.
The problem
Every agent framework ships its own memory: a vector table here, a JSON file there, a "notes" folder somewhere else. Three things follow, and all three hurt in production:
- You cannot audit it. "Which customer's data did the agent read last Tuesday?" has no answer, so security review stops the project.
- You cannot deploy it offline. Most options either call a cloud API or download model weights from HuggingFace at runtime — both fail inside a bank, a hospital, or a factory.
- You cannot keep it small. Twenty-three tools, a graph database, and a Python dependency tree later, the "memory feature" is a second product to operate.
memalyze is the middleware that fixes those three, and nothing else.
What is different
* A database trigger rejects UPDATE on audit_log; DELETE is not blocked, so anyone
with the database file can remove rows. It is append-only at the SQL level, not WORM — export
to object-lock or syslog storage if deletions are inside your threat model
(SECURITY.md).
Not another mem0, and not Basic Memory either: those are good at remembering. memalyze assumes remembering is becoming a commodity and competes on governance, offline operation, and a deliberately small surface.
30-second demo
No Ollama, no network, no MCP client:
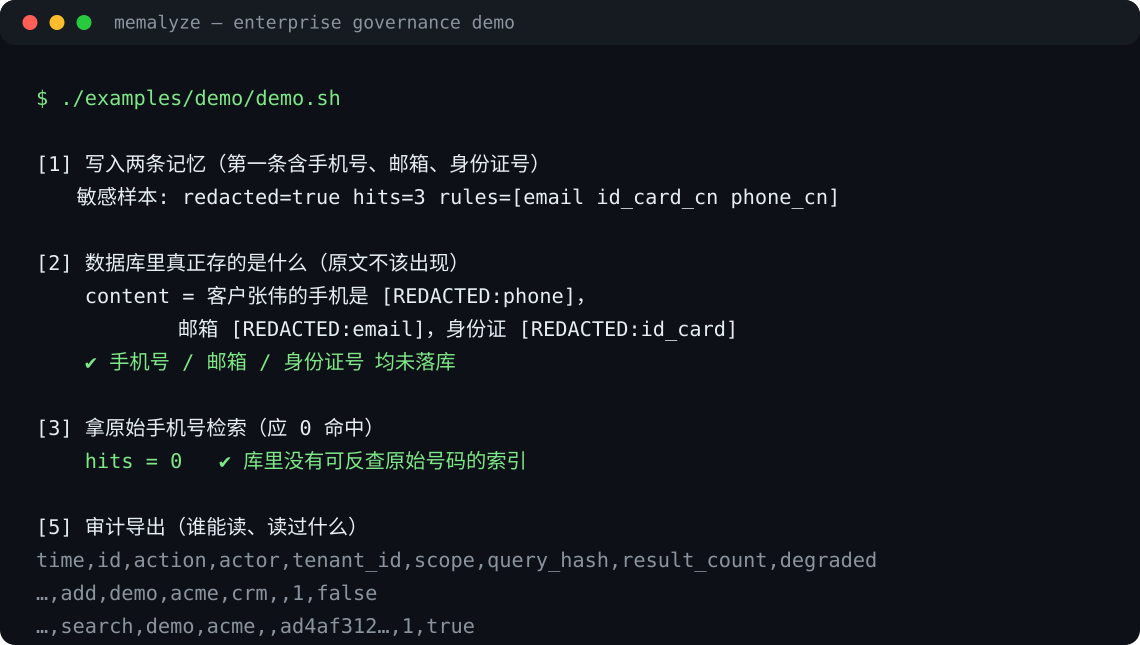
./examples/demo/demo.sh
# or: go run ./cmd/memalyze demo
It writes a memory containing a phone number, an e-mail and a resident ID, then shows:
- what is actually stored (
[REDACTED:phone], not13800138000); - that searching for the original number returns 0 hits;
- that a business-word search still hits, returning the redacted text;
- the audit rows for the two writes and the two reads.
Details and transcripts: docs/s15-redaction-audit.md.
Quick start
1. Binary + local embedding model
Prebuilt, checksum-verified (Linux/macOS; Windows: take the .exe from the release page):
curl -fsSL https://raw.githubusercontent.com/mahaoboy/memalyze/main/scripts/install.sh | sh
ollama pull qwen3-embedding:0.6b      # ~640 MB, 1024-dim, strong on Chinese
memalyze --version
From source (Go 1.27+): make build, then ./memalyze --version.
2. Wire it into a harness
Claude Code (project scope):
claude mcp add --scope project memalyze -- "$(pwd)/memalyze"
cp examples/claude-code/CLAUDE.md ./CLAUDE.md   # makes Claude search before answering
Cline: copy examples/cline/cline_mcp_settings.json and .clinerules.
Generic harness: examples/custom-harness/ — one prompt contract
plus pseudocode. All options: examples/README.md.
3. Or one-click in Claude Desktop (MCPB)
Download the bundle for your platform from the
v0.1.0 release and open it.
Claude Desktop shows an install sheet and asks where to keep memalyze.db.
The binary inside is the same v0.1.0 build as above. These bundles are new and have not
been opened on a real macOS/Windows desktop yet — if the install sheet does not appear,
use the plain binary. The server is also listed in the
MCP Registry.
4. Or run it in Docker (memalyze + Ollama + model pull)
printf 'MEMALYZE_HTTP_TOKEN=%s\n' "$(openssl rand -hex 24)" > .env
docker compose up -d --build
curl -s http://127.0.0.1:8080/healthz     # {"status":"ok","version":"dev"}
Point a Streamable-HTTP MCP client at http://127.0.0.1:8080/mcp with
Authorization: Bearer $MEMALYZE_HTTP_TOKEN. See docs/s16-docker.md.
Tools
Four, on purpose. Every extra tool is a decision the model has to make.
There is no memory_context tool: memory_search already returns text you can paste
into a prompt, and two overlapping tools make model choice worse (D-017).
Governance
Redaction (write path). Rules run in memory.Service.Add before dedup, FTS and
embedding — so plaintext never reaches the main table, the full-text index or a vector.
Modes: enforce (default), dry-run (count only, for tuning), off (debugging).
Custom rule packs are JSON: examples/redaction-rules.json.
Audit (read path). Append-only audit_log (a database trigger rejects UPDATE):
actor, tenant, scope, action, memory id, timestamp, result count, degraded, redaction
count. The search text itself is stored as SHA-256 + length unless you explicitly set
MEMALYZE_AUDIT_QUERY_PLAIN=1.
memalyze audit export --from 2026-10-01 --to 2026-10-31 --format csv --out audit.csv
memalyze audit export --tenant acme --format json
What is not here yet: per-user authentication (one token per process, actor from
env), audit retention/purge, reversible redaction, audit UI.
Retrieval, measured
Numbers from S8 on a 60-memory Chinese corpus, 16 queries, measured not assumed
(docs/s8-retrieval-report.md):
Two counter-intuitive findings that shaped the design: SQLite FTS5's default tokenizer cannot search Chinese at all (0.19 recall until we stored bigram text), and RRF fusion scored worse than vector-only, so v0.1 does not fuse. See D-012.
Latency (S14, cold start fixed): warmup 37.8 s in background, then search 1.14 s with
degraded=false; after five idle minutes a fresh process answers in 1.52 s. If the vector
path is unavailable, search degrades to keyword in ≤3 s instead of hanging (D-015/D-018).
How it works
harness (Claude Code / Cline / your agent)
   │  MCP: stdio or Streamable HTTP
   ▼
internal/mcp     4 tools, argument conversion only
   ▼
internal/memory  redact → dedup → store → embed; search: vector → keyword → degraded
   ├── internal/govern     rule engine (8 families, JSON configurable)
   ├── internal/store      interface; sqlite impl (memories, embeddings, audit_log)
   ├── internal/embed      float32 BLOB codec, cosine; Ollama client
   └── internal/search     CJK bigram tokenizer + FTS5 MATCH builder
- SQLite (WAL) with ULID ids, partial unique index for dedup, soft delete, TTL.
- Vectors are
float32little-endian BLOBs; search is brute-force cosine (fine under ~10k memories, and the honest limit of a single-binary design). - Schema migrations are versioned via
PRAGMA user_version(v1 → v2 adds the audit table).
Operations
memalyze audit export --from 2026-10-01 --format csv --out audit.csv   # who read what
memalyze backup --out /var/backups/memalyze-$(date +%F).db             # consistent snapshot
memalyze health --url http://127.0.0.1:8080/healthz                    # probe
- systemd:
deploy/systemd/memalyze.service+docs/s16-systemd.md(hardened unit, env file, backup timer). - Docker:
docs/s16-docker.md. backupusesVACUUM INTO, so snapshots are consistent under WAL and include the audit table; it refuses to overwrite an existing file.
Configuration
All through environment variables; defaults work out of the box.
Status
Honest snapshot — this is an early-stage project, not a 1.0.
Known gaps: no per-user auth, no audit retention, the Docker image has not been built in CI (no daemon in the dev environment), brute-force vector scan, Chinese-first defaults (English works, but the tokenizer is tuned for CJK).
Docs
Pilot
Two-week pilot: we install memalyze in your environment, tune the redaction rules to your data, review the audit export with you, and write down the threat-model gaps we find. No fee; you keep the deployment and the notes.
Request a pilot · Integration notes
Non-goals
- Not a SaaS: you self-host, we do not hold your data.
- Not an agent framework: it never takes over the harness.
- Not a knowledge graph: no entity extraction pipeline, no graph database.
- Not feature-maximal: four tools, one binary, and a hard "no" to anything that needs an operator.
License
AGPL-3.0-or-later (LICENSE). Commercial licensing for embedding in closed products:
open an issue titled commercial license.
Contributions: see CONTRIBUTING.md. Security reports: see
SECURITY.md.