VOICEVOX TTS MCP
English | 日本語
A text-to-speech MCP server using VOICEVOX
🎮 Try the Browser Demo — Test VoicevoxClient directly in your browser
What You Can Do
- Make your AI assistant speak — Text-to-speech from MCP clients like Claude Desktop
- UI Audio Player (MCP Apps) — Play audio directly in the chat with an interactive player (ChatGPT / Claude Desktop / Claude Web etc.)
- Multi-character conversations — Switch speakers per segment in a single call
- Smooth playback — Queue management, immediate playback, prefetching, streaming
- Cross-platform — Works on Windows, macOS, Linux (including WSL)
UI Audio Player (MCP Apps)
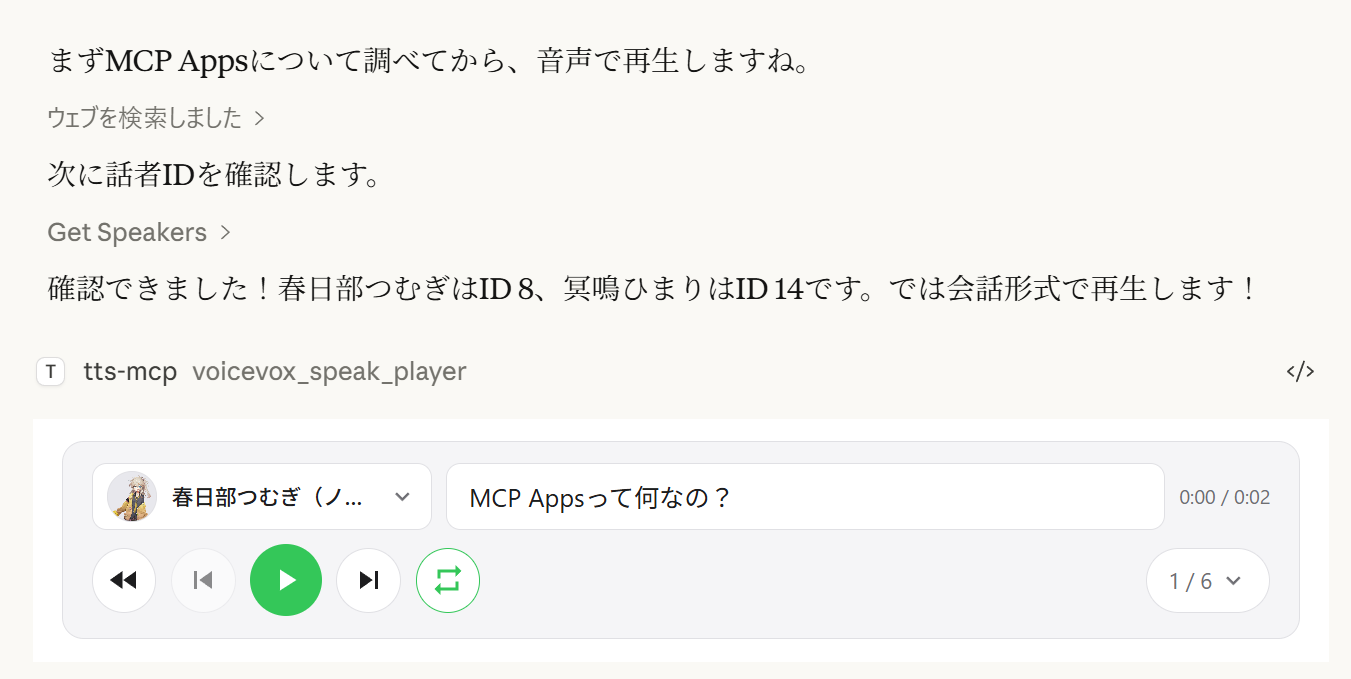
The voicevox_speak_player tool uses MCP Apps to render an interactive audio player directly inside the chat. Unlike the standard voicevox_speak tool which plays audio on the server, audio is played on the client side (in the browser/app) — no audio device needed on the server.
Features
- Client-side playback — Audio plays in Claude Desktop's chat, not on the server. Works even over remote connections.
- Play/Pause controls — Full playback controls embedded in the conversation
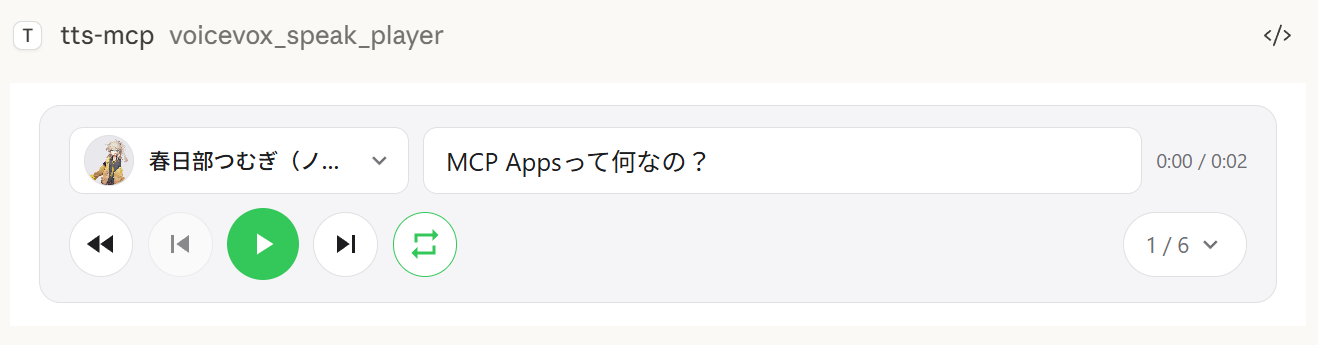
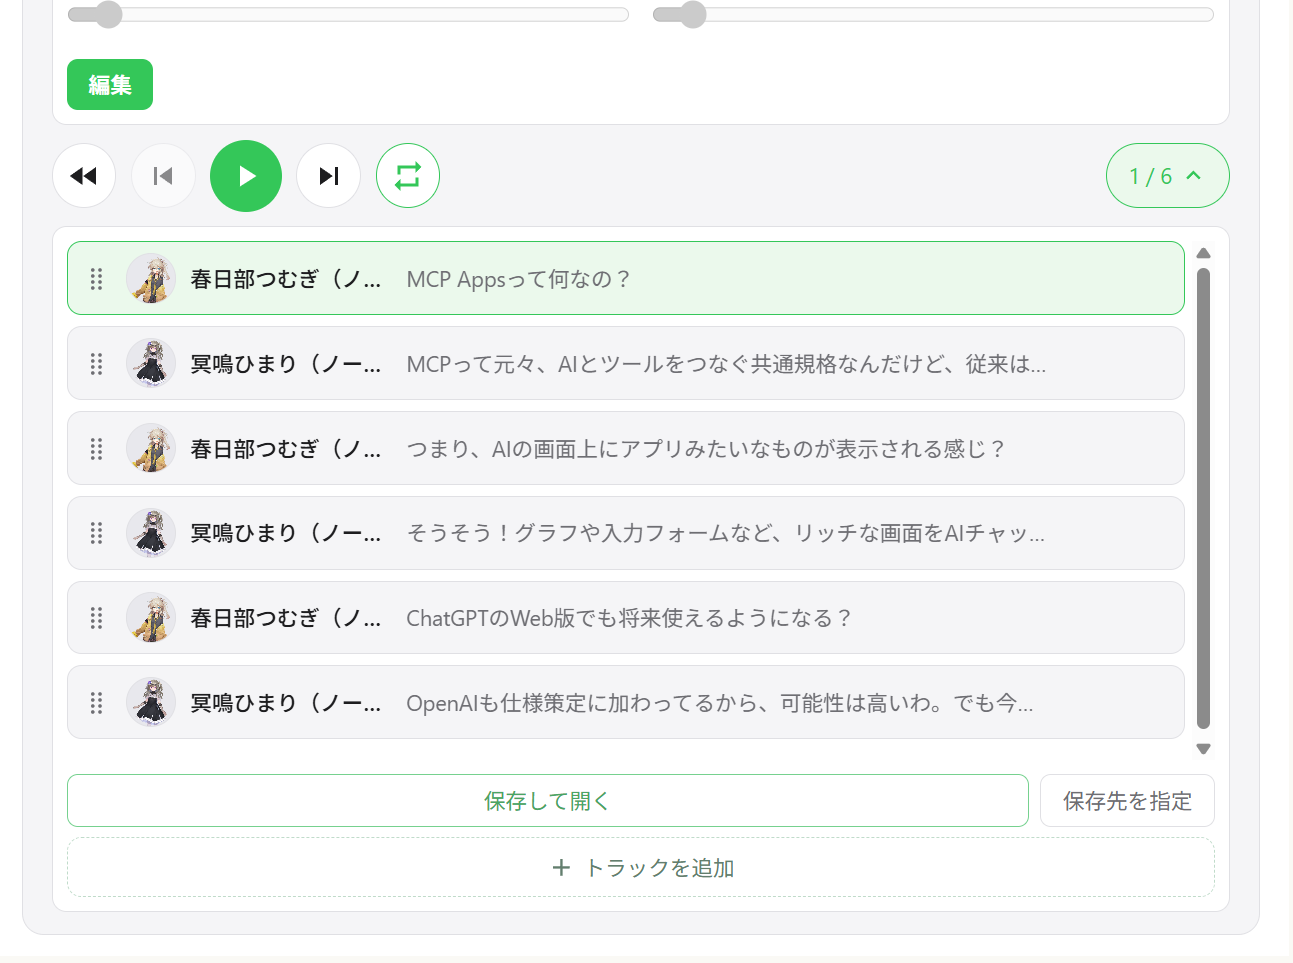
- Multi-speaker dialogue — Sequential playback of multiple speakers in one player with track navigation
- Speaker switching — Change the voice of any segment directly from the player UI
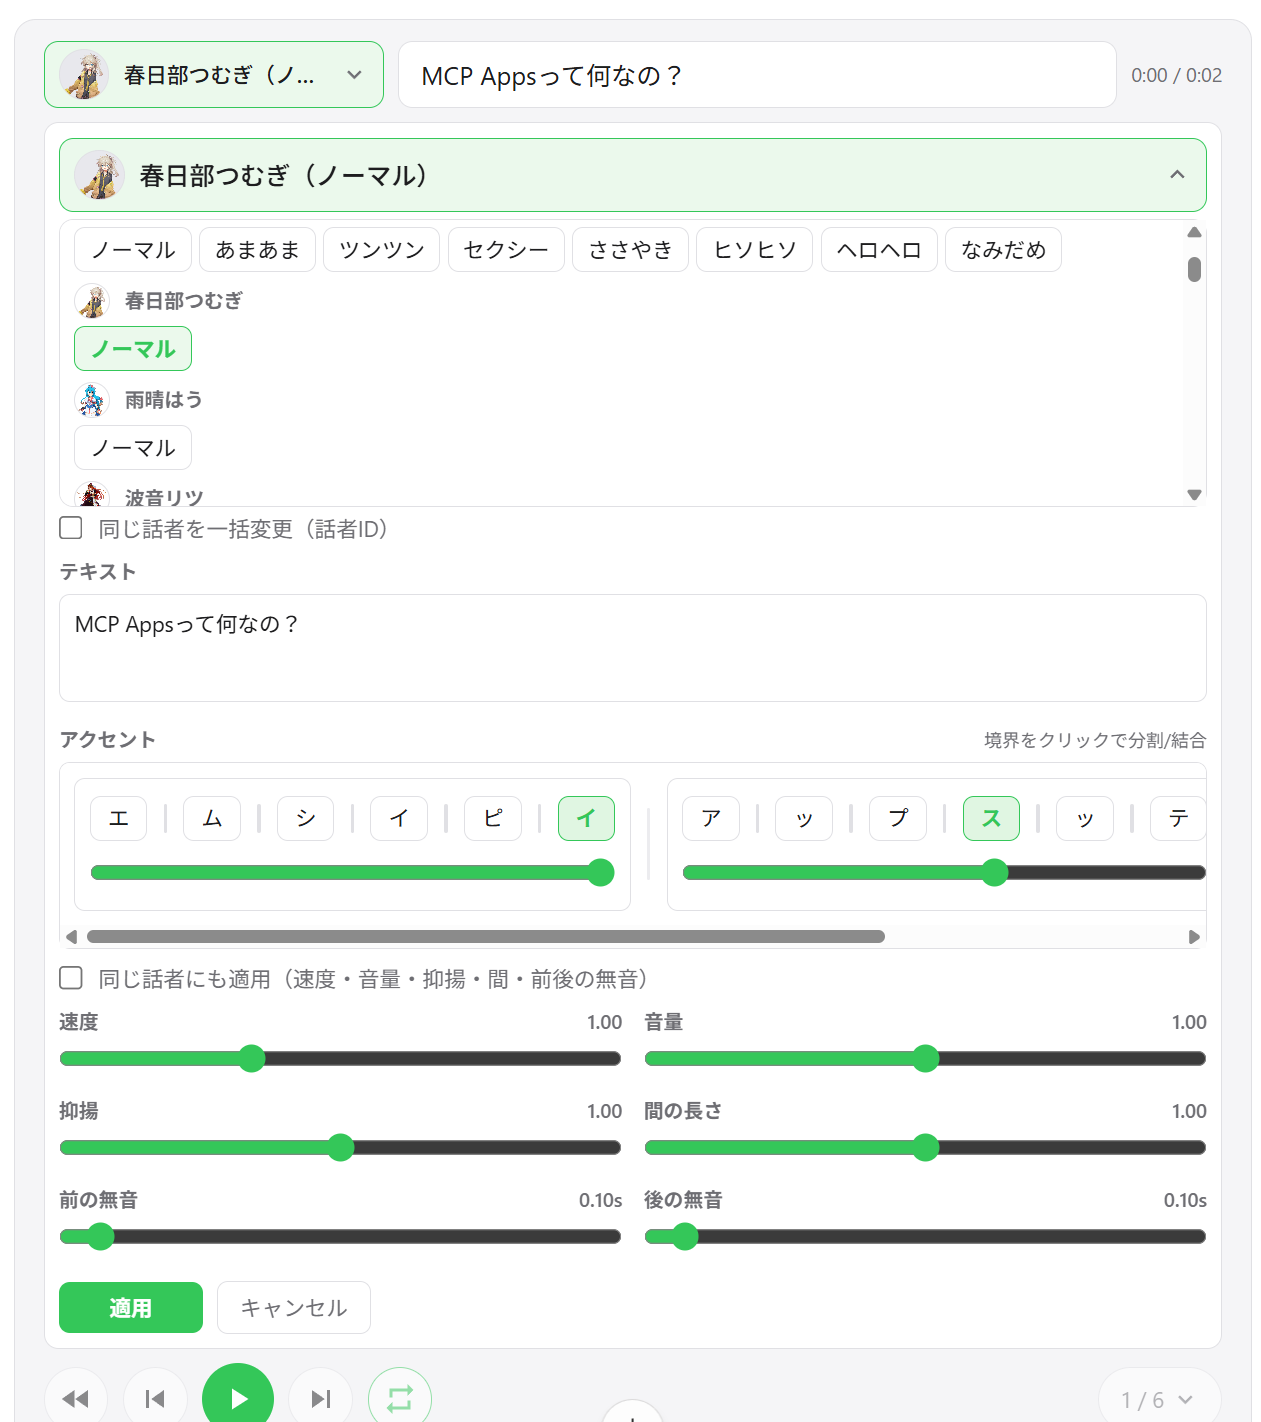
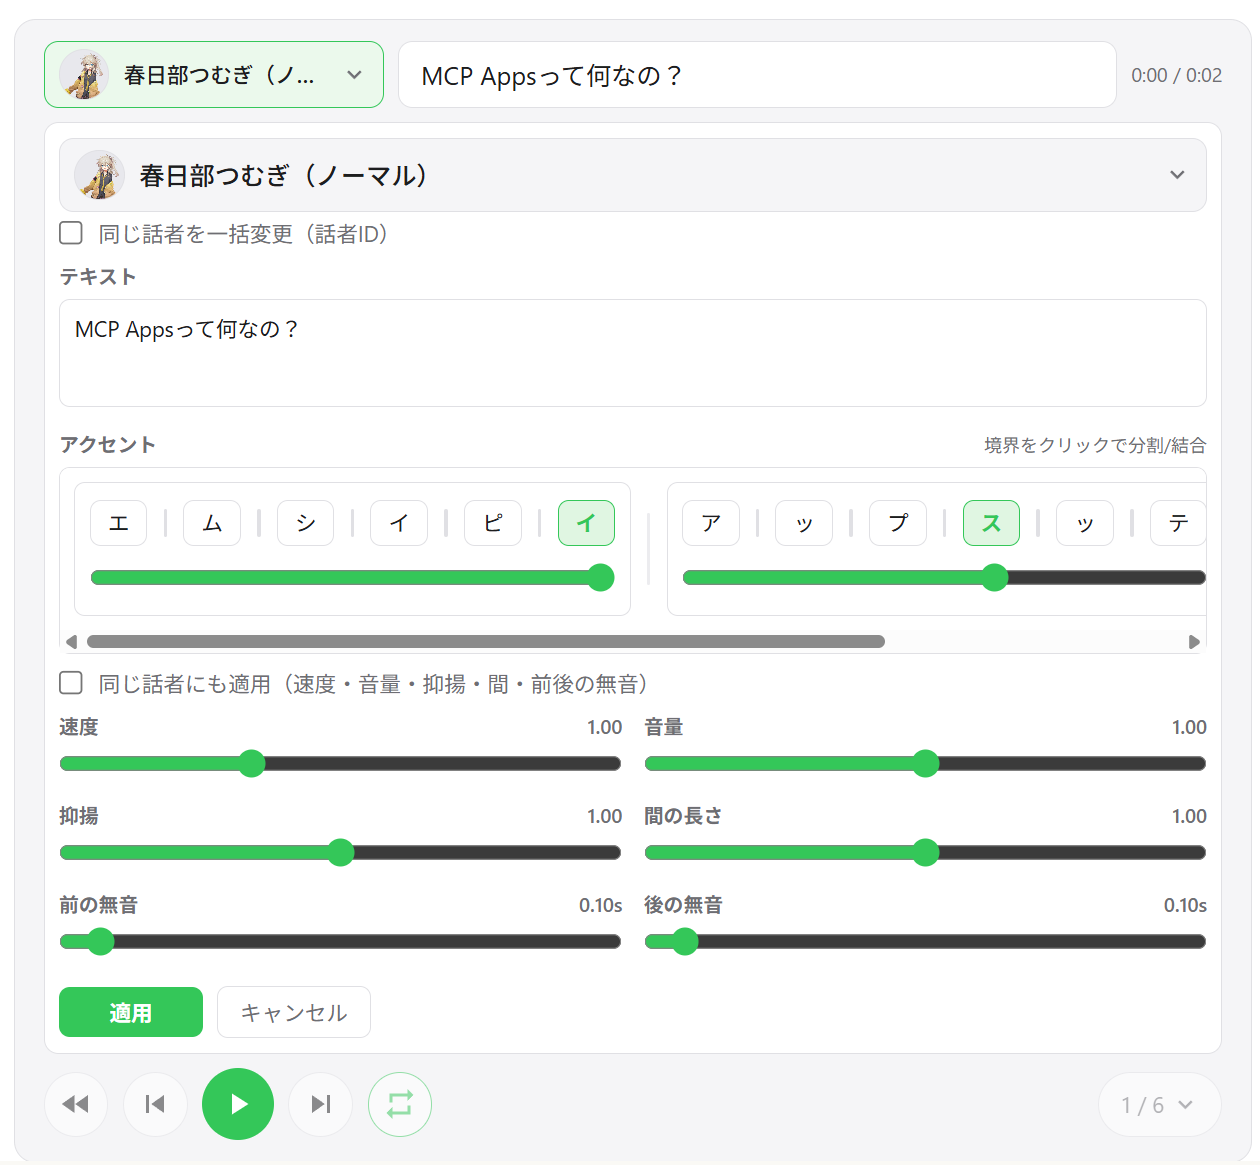
- Segment editing — Adjust speed, volume, intonation, pause length, and pre/post silence per segment
- Accent phrase editing — Edit accent positions and mora pitch directly in the UI
- Add / delete / reorder segments — Drag-and-drop track reordering; add new segments inline
- WAV export — Save all tracks as numbered WAV files and open the output folder automatically
- User dictionary manager — Add, edit, and delete VOICEVOX user dictionary words with preview playback
- Cross-session state restore — Player state is persisted on the server; reopening the chat restores previous tracks
Export behavior by environment:
Save and openalways exports WAV files. If opening the file explorer is not supported, export still succeeds and the save path is shown in the UI.Choose output folderuses a native directory picker on Windows/macOS. On unsupported environments, this action falls back to the default export directory.
| Multi-speaker playback | Track list | Segment editing |
|---|---|---|
 |  |  |
| Speaker selection | Dictionary manager | WAV export |
|---|---|---|
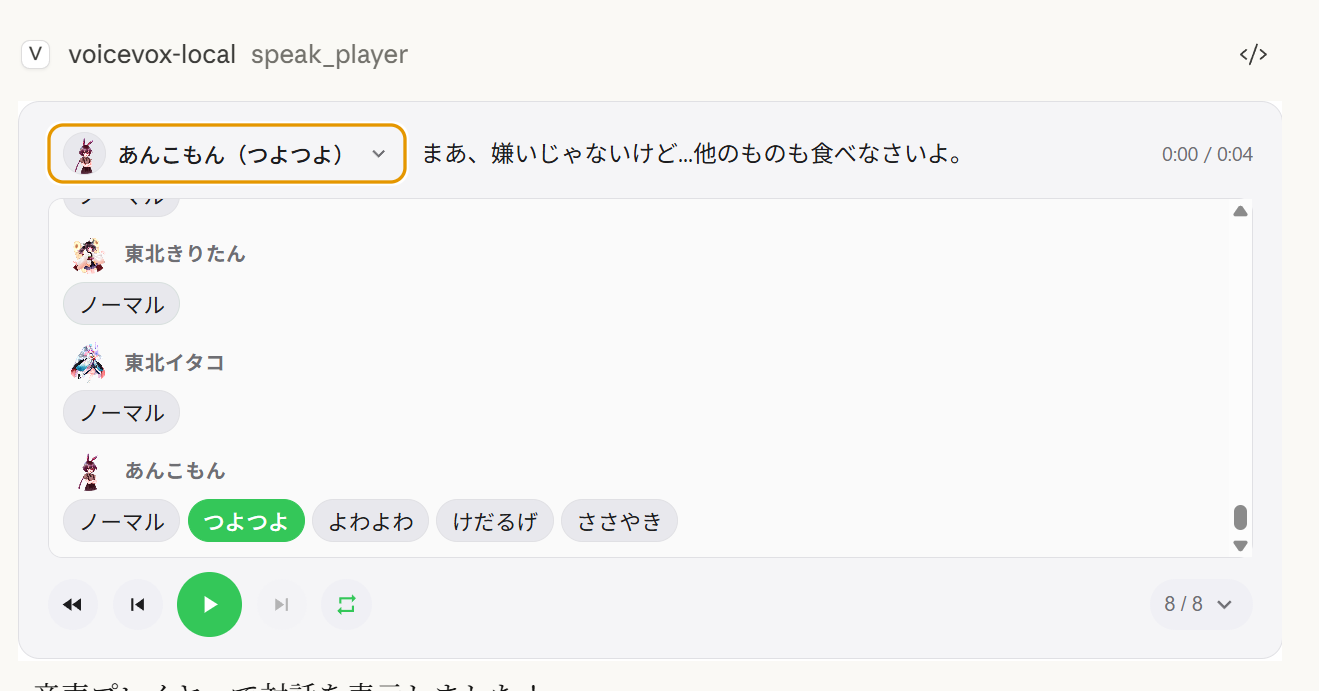 | 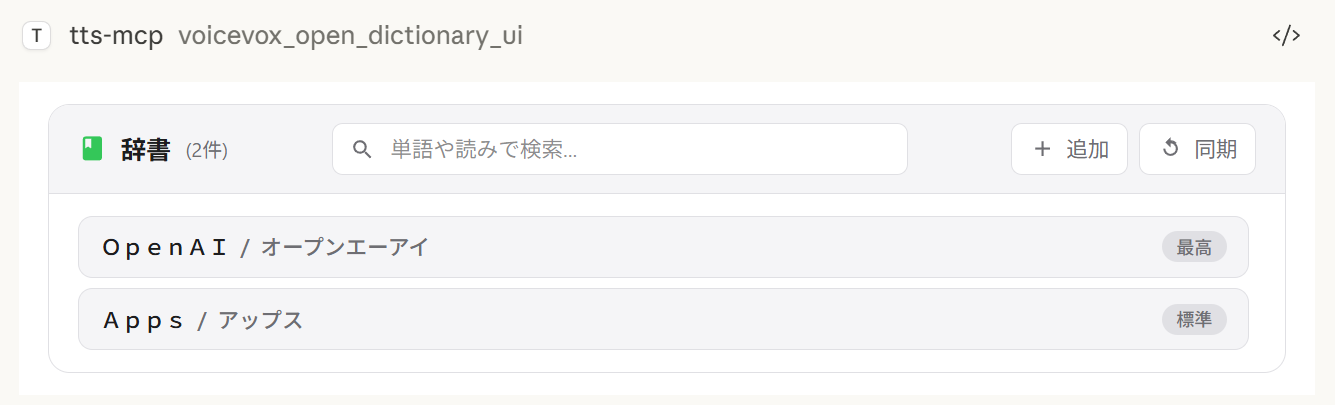 |  |
Supported Clients
Note:
speak_playerrequires a host that supports MCP Apps. In hosts without MCP Apps support, the tool is not available andspeak(server-side playback) can be used instead.
Player MCP Tools
Quick Start
Requirements
- Node.js 24.0.0 or higher (or Bun) or Docker
- VOICEVOX Engine (must be running; included in Docker Compose)
- ffplay (optional, recommended — not needed with Docker)
Installing FFplay
ffplay is a lightweight player included with FFmpeg that supports playback from stdin. When available, it automatically enables low-latency streaming playback.
💡 FFplay is optional. Without it, playback falls back to temp file-based playback (Windows: PowerShell, macOS: afplay, Linux: aplay, etc.).
- Easy setup: One-liner installation for each OS (see steps below)
- Required:
ffplaymust be in PATH (restart terminal/apps after installation)
Installation examples:
-
Windows (any of these)
- Winget:
winget install --id=Gyan.FFmpeg -e - Chocolatey:
choco install ffmpeg - Scoop:
scoop install ffmpeg - Official builds: Download from https://www.gyan.dev/ffmpeg/builds/ or https://github.com/BtbN/FFmpeg-Builds and add the
binfolder to PATH
- Winget:
-
macOS
- Homebrew:
brew install ffmpeg
- Homebrew:
-
Linux
- Debian/Ubuntu:
sudo apt-get update && sudo apt-get install -y ffmpeg - Fedora:
sudo dnf install -y ffmpeg - Arch:
sudo pacman -S ffmpeg
- Debian/Ubuntu:
PATH Setup:
- Windows: Add
...\ffmpeg\binto environment variables, then restart PowerShell/terminal and editor (Claude/VS Code, etc.)- Verify:
powershell -c "$env:Path"should include the ffmpeg path
- Verify:
- macOS/Linux: Usually auto-detected. Check with
echo $PATHif needed, restart shell. - MCP clients (Claude Desktop/Code): Restart the app to reload PATH.
Verification:
ffplay -version
If version info is displayed, installation is complete. CLI/MCP will automatically detect ffplay and use stdin streaming playback.
3 Steps to Get Started
1. Start VOICEVOX Engine
2. Add to Claude Desktop config file
Config file location:
- Windows:
%APPDATA%\Claude\claude_desktop_config.json - macOS:
~/Library/Application Support/Claude/claude_desktop_config.json
{
  "mcpServers": {
    "tts-mcp": {
      "command": "npx",
      "args": ["-y", "@kajidog/mcp-tts-voicevox"]
    }
  }
}
💡 If using Bun, just replace
npxwithbunx:"command": "bunx", "args": ["@kajidog/mcp-tts-voicevox"]
3. Restart Claude Desktop
That's it! Ask Claude to "say hello" and it will speak!
Quick Start with Docker
You can run both the MCP server and VOICEVOX Engine with a single command using Docker Compose. No Node.js or VOICEVOX installation required.
1. Start the containers
docker compose up -d
This starts the VOICEVOX Engine and the MCP server (HTTP mode on port 3000).
2. Add to Claude Desktop config file (using mcp-remote)
{
  "mcpServers": {
    "tts-mcp": {
      "command": "npx",
      "args": ["-y", "mcp-remote", "http://localhost:3000/mcp"]
    }
  }
}
3. Restart Claude Desktop
Security (Docker):
docker-compose.ymlpublishes port 3000 without authentication.MCP_ALLOWED_HOSTSis not a defense here — non-browser clients can send anyHostheader they like — so anyone who can reach the port can use the server. SetMCP_API_KEY(and send it asX-API-Key), or keep the port bound to a trusted network / localhost only. Consider also settingVOICEVOX_ALLOWED_OUTPUT_DIRSto limit where file-writing tools may write.
Limitations (Docker): The Docker container has no audio device, so the
voicevox_speaktool (server-side playback) is disabled by default. Usevoicevox_speak_playerinstead — it plays audio on the client side (in Claude Desktop) and works without any audio device on the server. See UI Audio Player for details.
MCP Tools
voicevox_speak — Text-to-Speech
The main feature callable from Claude.
immediate/waitForStart/waitForEnddisappear from the tool schema when the matching--restrict-*option is set.
Examples:
// Simple text
{ "text": "Hello" }

// Specify speaker
{ "text": "Hello", "speaker": 3 }

// Different speakers per segment
{ "text": "1:Hello\n3:Nice weather today" }

// Wait for completion (synchronous processing)
{ "text": "Wait for this to finish before continuing", "waitForEnd": true }

// Control the accent with inline notation (`,` separates phrases, `[` marks the accent)
{ "text": "こんにちは世界", "phrases": "コン[ニ]チワ,セ[カ]イ" }
Inline Accent Notation
phrases (and the pronunciation field of the user dictionary tools) accepts katakana with an inline accent marker:
,separates accent phrases —コン[ニ]チワ,セ[カ]イ[marks where the pitch drops after;コン[ニ]チワmeans the accent falls onニ- Omitting the brackets for a phrase keeps VOICEVOX's own accent estimation for it
text stays required even when phrases is given — pass the plain text there and the notation is what gets spoken.
voicevox_get_accent_phrases returns the same notation for a given text, so you can read the estimated accent, tweak the bracket, and feed it back into phrases.
User dictionary tools (group dictionary):
Any tool can be turned off individually with --disable-tools / VOICEVOX_DISABLED_TOOLS, or by group with --disable-groups / VOICEVOX_DISABLED_GROUPS.
Configuration
VOICEVOX Settings
Playback Options
Restriction Settings
Restrict AI from specifying certain options.
Disable Tools
# Disable individual tools
export VOICEVOX_DISABLED_TOOLS=speak_player,synthesize_file

# Disable a built-in group of tools
export VOICEVOX_DISABLED_GROUPS=player

# Combine groups and individual tools
export VOICEVOX_DISABLED_GROUPS=dictionary
export VOICEVOX_DISABLED_TOOLS=synthesize_file
Built-in groups for VOICEVOX_DISABLED_GROUPS / --disable-groups:
UI Player Settings
File Output Settings
Server Settings
Command line arguments take priority over environment variables.
The complete, up-to-date list of options is always available via npx @kajidog/mcp-tts-voicevox --help.
# Basic settings
npx @kajidog/mcp-tts-voicevox --url http://192.168.1.100:50021 --speaker 3 --speed 1.2

# HTTP mode
npx @kajidog/mcp-tts-voicevox --http --port 8080

# With restrictions
npx @kajidog/mcp-tts-voicevox --restrict-immediate --restrict-wait-for-end

# Disable individual tools
npx @kajidog/mcp-tts-voicevox --disable-tools speak_player,synthesize_file

# Disable a tool group
npx @kajidog/mcp-tts-voicevox --disable-groups player
You can use a JSON config file instead of (or in addition to) environment variables and CLI arguments. This is useful when you have many settings to configure.
Priority order: CLI args > Environment variables > Config file > Defaults
Generate a config file
npx @kajidog/mcp-tts-voicevox --init
This creates .voicevoxrc.json in the current directory with all default settings. Edit it as needed.
Use a custom config file path
npx @kajidog/mcp-tts-voicevox --config ./my-config.json
Or via environment variable:
VOICEVOX_CONFIG=./my-config.json npx @kajidog/mcp-tts-voicevox
Example .voicevoxrc.json
{
  "url": "http://192.168.1.50:50021",
  "speaker": 3,
  "speed": 1.2,
  "http": true,
  "port": 8080,
  "disable-tools": ["synthesize_file"],
  "disable-groups": ["dictionary"]
}
Keys can be written in kebab-case (use-streaming), camelCase (useStreaming), or internal key names (defaultSpeaker). If .voicevoxrc.json exists in the current directory, it is loaded automatically.
For remote connections:
Start Server:
# Linux/macOS
MCP_HTTP_MODE=true MCP_HTTP_PORT=3000 npx @kajidog/mcp-tts-voicevox

# Windows PowerShell
$env:MCP_HTTP_MODE='true'; $env:MCP_HTTP_PORT='3000'; npx @kajidog/mcp-tts-voicevox
Claude Desktop Config (using mcp-remote):
{
  "mcpServers": {
    "tts-mcp-proxy": {
      "command": "npx",
      "args": ["-y", "mcp-remote", "http://localhost:3000/mcp"]
    }
  }
}
Per-Project Speaker Settings
With Claude Code, you can configure different default speakers per project using custom headers in .mcp.json:
Example .mcp.json:
{
  "mcpServers": {
    "tts": {
      "type": "http",
      "url": "http://localhost:3000/mcp",
      "headers": {
        "X-Voicevox-Speaker": "113",
        "X-API-Key": "your-api-key"
      }
    }
  }
}
This allows each project to use a different voice character automatically.
Priority order:
- Explicit
speakerparameter in tool call (highest) - Project default from
X-Voicevox-Speakerheader - Global
VOICEVOX_DEFAULT_SPEAKERsetting (lowest)
Connecting from WSL to an MCP server running on Windows:
1. Get Windows Host IP from WSL
# Method 1: From default gateway
ip route show | grep -oP 'default via \K[\d.]+'
# Usually in the format 172.x.x.1

# Method 2: From /etc/resolv.conf (WSL2)
cat /etc/resolv.conf | grep nameserver | awk '{print $2}'
2. Start Server on Windows
Add the WSL gateway IP to MCP_ALLOWED_HOSTS to allow access from WSL:
$env:MCP_HTTP_MODE='true'
$env:MCP_ALLOWED_HOSTS='localhost,127.0.0.1,172.29.176.1'
npx @kajidog/mcp-tts-voicevox
Or with CLI arguments:
npx @kajidog/mcp-tts-voicevox --http --allowed-hosts "localhost,127.0.0.1,172.29.176.1"
3. WSL Configuration (.mcp.json)
{
  "mcpServers": {
    "tts": {
      "type": "http",
      "url": "http://172.29.176.1:3000/mcp"
    }
  }
}
⚠️ Within WSL,
localhostrefers to WSL itself. Use the WSL gateway IP to access the Windows host.
To use with ChatGPT, deploy the MCP server in HTTP mode to the cloud with access to a VOICEVOX Engine.
1. Deploy to the Cloud
Deploy with Docker to Render, Railway, etc. (Dockerfile included).
2. Set Up VOICEVOX Engine
Run VOICEVOX Engine locally and expose it via ngrok, or deploy it alongside the MCP server.
3. Configure Environment Variables
4. Add Connector in ChatGPT
Go to ChatGPT Settings → Connectors → Add MCP server URL (https://your-app.onrender.com/mcp).
The basic steps are the same as ChatGPT, but the VOICEVOX_PLAYER_DOMAIN value is different.
Claude Web requires ui.domain to be a hash-based dedicated domain. Compute it with the following command:
node -e "console.log(require('crypto').createHash('sha256').update('Your MCP server URL').digest('hex').slice(0,32)+'.claudemcpcontent.com')"
Example: If your MCP server URL is https://your-app.onrender.com/mcp:
node -e "console.log(require('crypto').createHash('sha256').update('https://your-app.onrender.com/mcp').digest('hex').slice(0,32)+'.claudemcpcontent.com')"
# Example output: 48fb73a6...claudemcpcontent.com
Set this output value as VOICEVOX_PLAYER_DOMAIN.
Note: Since ChatGPT and Claude Web require different
VOICEVOX_PLAYER_DOMAINvalues, a single instance cannot serve both clients simultaneously. Deploy separate instances for each, or switch the environment variable depending on your target client.
Troubleshooting
1. Check if VOICEVOX Engine is running
curl http://localhost:50021/speakers
2. Check platform-specific playback tools
- Check package installation:
npm list -g @kajidog/mcp-tts-voicevox - Verify JSON syntax in config file
- Restart the client
Package Structure
Setup
git clone https://github.com/kajidog/mcp-tts-voicevox.git
cd mcp-tts-voicevox
pnpm install
Commands
The package manager is pnpm (npm / yarn are not supported).
Dev servers live in the server package, so run them with a filter:
License
ISC