
zerikai_memory 🧠
⚠️ Platform Support Notice:
Note: This project is developed and actively maintained on Windows. GitHub Actions verifies that basic installation compiles across Windows, macOS, and Linux, but the maintainer cannot troubleshoot platform-specific runtime errors on Mac or Linux. Community pull requests fixing Mac/Linux bugs are highly welcome!
🆕 New — Jev Semantic Judgment Layer
zerikai_memory now integrates Jev, TypeSafe AI's System One model — a fast, structured judgment engine that decides which retrieved passages actually answer your question and attaches a plain-text evidence report to every answer.
- What it is: a second, narrow AI layer beside your LLM. Your LLM writes the answer; Jev judges the evidence it is built from. It returns calibrated probabilities — not prose.
- What it does: per-passage relevance / evidence / contradiction / prompt-injection scoring, better passage ordering (replaces keyword rerank), and a plain-text
Assessment / Evidence / Guidancereport the agent can act on. Injection attempts are dropped. - Off by default: with
ENABLE_JEV=falsebehavior is byte-identical to before, and it is fully fail-open — if Jev is unavailable, the normal pipeline runs. - Activate it: set
TYPESAFE_API_KEYandENABLE_JEV=truein.env, then restart the server. - Get the API key: TypeSafe early access → console.typesafe.ai.
📖 Full details — how the judgment layer works and every parameter: documentation/10-jev-judgment-layer.md
The Problem
Every new chat session starts completely cold. When you switch contexts or open a new window:
- Your AI Agent forgets every architectural decision, convention, and stack choice made over hours
- You waste critical tokens and 10–15 minutes re-explaining the codebase setup in every single chat
- Large raw file dumps inflate your token costs and shrink your available context window instantly
- Switching IDEs (e.g., VS Code to Cursor) forces you to restart your conversation history from scratch
How Zerikai Memory Solves It
Zerikai Memory runs as a local STDIO MCP server between your IDE and your LLM. It parses your codebase using tree-sitter, indexes code entities into a local ChromaDB vector store, and injects highly relevant context snippets dynamically through natural language.
Your Codebase  →  tree-sitter (local parse)  →  ChromaDB (.brain/)
                                                      │
Your IDE       →  MCP Server (:stdio)        →        ▼
                                             Ollama / DeepSeek
                    │                      (auto-routed synthesis)
          ┌─────────┴──────────────┐
          │   4-Stage Pipeline     │
          │   L1  Vector Search    │  ChromaDB L2 distance matching
          │   L2  Lexical Re-rank  │  Keyword overlap boost on names
          │   L3  Auto-Routing     │  Ollama (free) vs. DeepSeek Cloud
          │   L4  LLM Synthesis    │  Answer + inline #file:line citations
          └────────────────────────┘
Architecture
Cost Model — The Context Tax Mitigation
Tip: The project brief acts as a stable prefix. After your first query, DeepSeek caches it — making subsequent repeated queries 50–100× cheaper (rate depends on whether you are in peak or off-peak hours). See the DeepSeek Pricing section for current rates.
Quick Start
I have added a YouTube video walkthrough of the installation and setup process in the first step below. If you prefer text instructions, just follow along with the code snippets.
1. Install
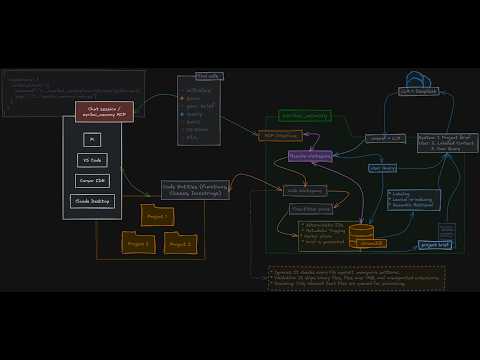
Click the image below to watch a step-by-step walkthrough of the installation and setup process:
git clone https://github.com/kikeven/zerikai_memory.git
cd zeriakai_memory

# Create and activate a virtual environment (Python 3.11+)
python -m venv venv
source venv/bin/activate  # Windows: .\venv\Scripts\activate

pip install -r requirements.txt
2. Configure Environment
Remove the .example from the .env.example file in the root directory and rename it to .env:
DEEPSEEK_API_KEY=your_deepseek_key_here

# Memory Mode controls which LLM is used for operations:
# - "cloud": Use DeepSeek for all operations (scan, brief, queries) - highest quality, tracked usage
# - "hybrid": Use Ollama for file scanning, DeepSeek for briefs and escalated queries
# - "local": Use Ollama for everything (free, but lower quality briefs)
MEMORY_MODE=cloud

# Enable token tracking and cost reporting (SQLite database at .brain/token_usage.db)
# Set to "false" to disable tracking
ENABLE_TOKEN_TRACKING=true

# Enable deepseek-v4-pro for complex architectural queries (design, architecture, tradeoffs)
# v4-pro is ~4× more expensive than deepseek-flash. See DeepSeek Pricing section below
# for current peak/off-peak rates.
# Recommended: keep this "false" unless you need maximum reasoning capability
ENABLE_DEEPSEEK_PRO=false

# DeepSeek thinking mode (chain-of-thought). Docs:
# https://api-docs.deepseek.com/guides/thinking_mode/
# Thinking is ON by default at effort "high" when no parameter is sent.
# Options per path: enabled | disabled. "disabled" is right for extractive work.
# NOTE: briefs and query synthesis are separate pipelines with separate toggles.
DEEPSEEK_THINKING_BRIEF=disabled   # 9-section project brief generation
DEEPSEEK_THINKING_SCAN=disabled    # per-file indexing summaries
DEEPSEEK_THINKING_QUERY=disabled   # query_memory answer synthesis

# Reasoning effort per path when that path is "enabled": low | high | max.
# Ignored when the matching path is "disabled". "low" is the cheapest enabled tier.
DEEPSEEK_REASONING_EFFORT_BRIEF=low
DEEPSEEK_REASONING_EFFORT_SCAN=low
DEEPSEEK_REASONING_EFFORT_QUERY=low

# Semantic search relevance cutoff for query_memory (L2 distance).
# Lower = stricter. Watch "best dist=X.XX" in server.log to calibrate.
# Typical: <0.8 strong match, 0.8-1.5 related, >1.5 noise.
QUERY_DISTANCE_THRESHOLD=1.0

# File extensions to skip during scanning when tree-sitter produces zero
# entities (no functions, classes, headings, semantic HTML elements, etc.).
# Saves API calls on bare config files, trivial templates, empty CSS, etc.
# Format: ['.py', '.html', '.md', '.css']
# Default: [] (empty — no extensions skipped, all fall through to LLM).
SKIP_BARE_FILES=['.py', '.html', '.md', '.css']

# Enable lexical re-ranking in query_memory.
# When true, results passing the distance threshold are reordered by a
# weighted combination of semantic distance and keyword overlap in entity
# name and docstring text. Nothing is dropped — pure reorder.
# Default: false (existing pure-semantic behaviour preserved).
ENABLE_LEXICAL_RERANK=true

# Weight applied per keyword hit during lexical re-ranking.
# The 1/dist spread across the valid-hit band (0.85–0.98) is ~0.156.
# Keep this value below that spread to avoid keyword hits overriding
# a genuinely closer semantic result.
# Recommended starting point: 0.05 (one hit = +0.05, two hits = +0.10).
LEXICAL_RERANK_WEIGHT=0.05

# Candidate pool per section for project-brief synthesis. Each section queries
# ChromaDB, re-ranks locally, then trims to a per-section cap (20/25/30).
# Decoupled from FETCH_CAP (query-only) so a tight query pool doesn't starve
# the brief. Default: 20.
BRIEF_FETCH_CAP=20
2a. Verify
python -c "from main import scan_workspace, query_memory; print('OK')"
You should see the startup banner followed by OK.
3. IDE Rule Enforcement
To stop your AI agent from ignoring the memory protocol, copy these directives into your IDE's agent rules profile (e.g., .cursorrules or system prompt guidelines):
IDE Rules in: agent_rules/ide_agent_rules.md
- Universal-Brain First: The agent must query
universal-brainbefore attempting raw file searches. - Source Discipline: Every answer must surface actual
file.py:linecitations with zero fabrication.
4. IDE Registration
- Press
Ctrl+Shift+P→ MCP: Add Local Server - Choose STDIO
- Set command:
C:\path\to\zerikai_memory\venv\Scripts\python.exe C:\path\to\zerikai_memory\main.py
Add to your claude_desktop_config.json profile:
{
  "mcpServers": {
    "universal-brain": {
      "command": "C:\\path\\to\\zerikai_memory\\venv\\Scripts\\python.exe",
      "args": ["C:\\path\\to\\zerikai_memory\\main.py"]
    }
  }
}
5. Setup the .memignore file
Works like .gitignore: one pattern per line. scan_workspace reads this file and skips matching paths.
Each project should have its own .memignore in its root directory. Forgetting to configure it before the first scan is the most common reason to use drop_memory.py and start fresh:
Examples of what to ignore: Expand to view
# Directories (trailing slash required)
.git/
node_modules/
venv/
__pycache__/
.brain/
dist/
build/

# File/Folder patterns
**/test/
**/tests/
.env
*.log
*.lock
*.pyc
6. Embedding-Docstring Skill
Before running your first index scan, optimize your codebase's docstrings for vector search. Ask your AI Agent:
- To install the embedding-docstring globally in your IDE and run it against your codebase to rewrite docstrings into a more embedding-friendly format.
- You can find it in the embedding-docstring skill guide.
"Audit and optimize docstrings across this project using the embedding-docstring skill, respecting .memignore."
7. Chat with Memory
Simply instruct your IDE's active AI agent using natural language commands:
prefix queries with "universal-brain: <command>" to ensure they route through the MCP server and leverage your indexed memory:
- Scan the workspace for the first time:
"Set up memory for this project" - Ask a question:
"What are the main architectural components of this project?"
Frequently used follow-ups:
- After a code change:
"Rescan the workspace and force a refresh of the project brief." - Save part of a chat:
"Save the following context to memory: [your custom notes or constraints here]" - Ask how much have you used:
"Get me a cost report for my memory usage so far."
See below for a full reference of available commands and their descriptions.
Safe Upgrade Process
Upgrading zerikai_memory while keeping your already indexed workspaces is safe as long as the workspace path never changes.
Your workspace identity is a stable UUID derived from its absolute filesystem path
(_derive_workspace_id in main.py). Because .brain/ is gitignored, a git pull
never touches your indexed memory, project briefs, or workspace registry.
Upgrade in place — never copy, rename, clone, or move the project directory.
The whole point is to preserve your already-indexed .brain/ data — back it up,
upgrade the code, restore it, and you get your old memory back exactly as it was.
No re-indexing needed.
# 1. Stop the MCP server (close the IDE / kill main.py) — releases the ChromaDB lock

# 2. Back up your existing indexed data so you don't lose it
#    (do NOT rename the whole project — only back up .brain/)
#    Windows (PowerShell):  Copy-Item -Recurse .brain .brain.bak
#    macOS / Linux:         cp -r .brain .brain.bak

# 3. Pull the latest code
git pull

# 4. Reinstall dependencies only if requirements.txt changed
#    Windows:  .\venv\Scripts\python.exe -m pip install -r requirements.txt
#    macOS/Linux:  venv/bin/python -m pip install -r requirements.txt

# 5. Restore .brain/ (only needed if the upgrade replaced it), restart, and verify
#    the workspace still resolves to the same UUID — your old memory is back
⚠️ Do NOT rename the folder (e.g.
zerikai_memory_old), clone into a differently-named folder, or move the project to a new parent directory. Any of these changes the path → generates a new UUID → orphans your old collection and brief. If you already did this, recover withmerge_workspaces.
Full step-by-step guide, backup/restore, and recovery instructions: documentation/09-upgrading.md
MCP Tools Reference
You never run these commands directly; your active AI agent executes them on your behalf.
Workspace Management
Memory & Briefs
Usage & Diagnostics
Project Brief Matrix
When a workspace is scanned, Zerikai compiles a dense 1,000–1,200 token project brief across 9 locked components:
Memory Modes
Adjust your operation profile via the MEMORY_MODE environment toggle to balance privacy, speed, and API costs.
💡 Deterministic First: All high-resolution code parsing (functions, classes, methods) is performed locally and deterministically using Tree-Sitter for $0 cost. The engines below are only used for text-file fallbacks and generating the architectural Project Brief.
Configuration Reference
DeepSeek Pricing
DeepSeek uses peak / off-peak pricing across all tiers. Off-peak rates are exactly half of peak rates.
⏰ Peak hours (UTC):
01:00–04:00and06:00–10:00, Monday–Friday only. Weekends are always off-peak.
Rate Table (USD per 1M tokens)
The tool automatically resolves the correct tier at call time — no manual configuration needed.
Off-Peak Windows by Region
⚠️ Peak hours apply Monday–Friday only. Weekends are always off-peak regardless of time. Offsets shown for summer / daylight saving time (DST). In winter, US timezones shift 1 hour later; European zones shift 1 hour earlier — meaning off-peak windows shift accordingly.
Key insight: For US users working standard hours on weekdays, most of the working day is already off-peak (cheaper). European users in GMT+2 zones benefit from off-peak pricing through most of the afternoon and evening — and all weekend queries cost even less. Saturday and Sunday queries are always billed at off-peak rates.
Auxiliary Scripts & Troubleshooting
Workspace Reset
If you accidentally execute a workspace crawl before setting up your .memignore configurations, run the auxiliary wipe script to delete stale workspace data:
# Windows
.\venv\Scripts\python.exe drop_memory.py "Workspace Name"

# macOS / Linux
venv/bin/python drop_memory.py "Workspace Name"
Live Log Diagnostics
Monitor server activity, runtime operations, and auto-routing logs inside .brain/server.log:
# Live stream logs (macOS/Linux)
tail -f .brain/server.log

# Live stream logs (Windows PowerShell)
Get-Content .brain\server.log -Wait -Tail 30
Security & Data Privacy
- All active vector spaces, tracking registries, and context details reside directly on your local machine.
- Add
.envand.brain/explicitly to your global or project.gitignorepatterns to prevent API keys and secure indexes from leaking to version control platforms.
To read more about the underlying design principles, architecture decisions, and future roadmap for Zerikai Memory, check out the insight article.
License
MIT License © Zerikai