
🥞 fln
A local, explainable context compiler for AI coding agents. Retrieval without embeddings. Context without a server.
fln analyzes your codebase, plans what to include, and emits a single AI-ready file — with diagnostics that explain every decision. Think tsc for LLM context: analyze → plan → emit, all local.
Quick start
npx fln          # or: npm i -g fln · bunx fln · brew install nesvet/tap/fln
fln              # → my-app-1.2.0.md in the current directory
$ fln --no-ansi
✓ my-app-1.2.0.md (42 files, 12_840 tokens)
One markdown file — header, directory tree, backtick-safe fences. Paste into Claude, ChatGPT, Gemini, Grok, Cursor, or Copilot; pipe to a CLI LLM (fln --stdout | llm "..."); or serve over MCP.
# Codebase Snapshot: demo-app

Generated: 2026-07-06 17:30
Files: 6 | Directories: 3

---

## Directory Tree
```text
├── README.md
├── package.json
├── src
│   ├── index.ts
│   ├── helper.ts
│   └── utils.ts
└── tests
    └── index.test.ts
```

---

## Source Files

### src/index.ts
```ts
import { helper } from "./helper";
import { format } from "./utils";

export function main(): string {
  return format(helper());
}
```
Why · Compare · Workflows · Install · Usage · API · FAQ
Who it's for
- CI budget guards, reproducible snapshots, offline packing
- MCP context-server for agents that need planned, explainable context
- Import-graph retrieval (
--relevant) without embeddings
Who it's not for
- Remote-only one-shot digests (gitingest, repomix
--remote) - IDE live
@codebaseon huge repos (Cursor) - Tree-sitter-first compression as the main goal (repomix
--compress)
Why fln
If you use LLMs on real projects, you've hit these limits:
- Context windows — the whole project doesn't fit
- Upload friction — picking dozens of files every session
- Partial understanding — the model sees fragments, not the architecture
- No explainability — why was this file excluded? was that secret filtered?
fln treats codebase context the way tsc treats TypeScript: analyze, plan, emit — with diagnostics (why, doctor, plan, diff) and MCP.
JIT agent retrieval (tool calls, embeddings, live search) is great for interactive exploration. fln is the complementary AOT snapshot compiler: it builds a deterministic context spine before the agent starts — structure-based retrieval (imports, priority, token budgets), no embeddings, no server. Same input → same snapshot; CI-friendly; offline.
How fln compares
When to use what
- fln — CI budget guards, MCP context-server, reproducible snapshots,
why/doctor/plan/diff,--relevant,--stdin - repomix — remote repos, Tree-sitter
--compress, watch mode, web UI - code2prompt — Handlebars prompt templates and custom prompt pipelines
- gitingest — quick web digest /
hub→ingestURL trick - Cursor
@codebase— live IDE retrieval on large repos
Not mutually exclusive: fln and repomix both produce paste-ready files; fln adds the compiler/diagnostics layer.
Workflows
Plan before you flatten
fln plan assigns fidelity per file and projects tokens before you spend the budget. With --relevant, only the import-graph neighborhood of the seed is included:
$ fln plan --relevant src/cli/index.ts --budget 200000
# Context Plan: .

Budget: 200,000 tokens
Projected: 67,149 tokens
Files included: 100
Files omitted: 1

## Included files

  src/api/index.ts — ~239 tokens (entry point — high priority)
  src/cli/index.ts — ~89 tokens (seed file)
  src/cli/output/index.ts — ~28 tokens (entry point — high priority)
  ...
Full output: assets/demo-plan.md. Use --format json for CI/agents. Formal schema: schema/fln-plan.json ($id: https://fln.nesvet.dev/schema/plan).
fln plan --budget 200000
fln plan --relevant src/cli/index.ts --budget 200000
fln plan --format json
Explain, preflight, MCP
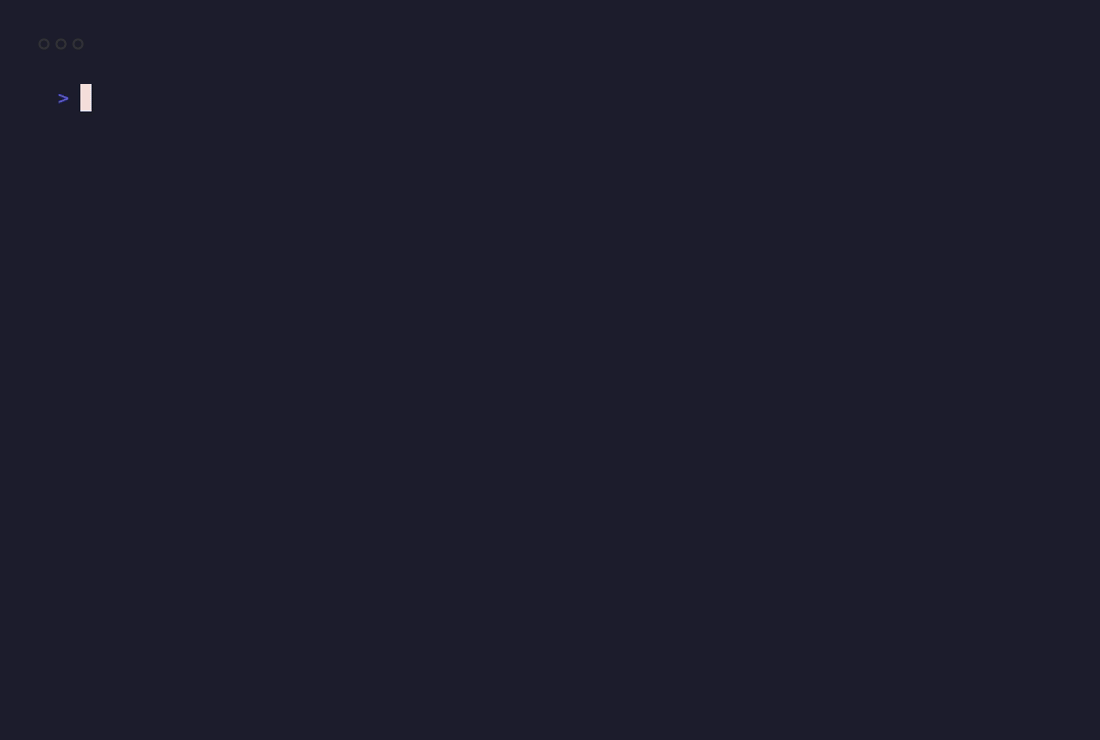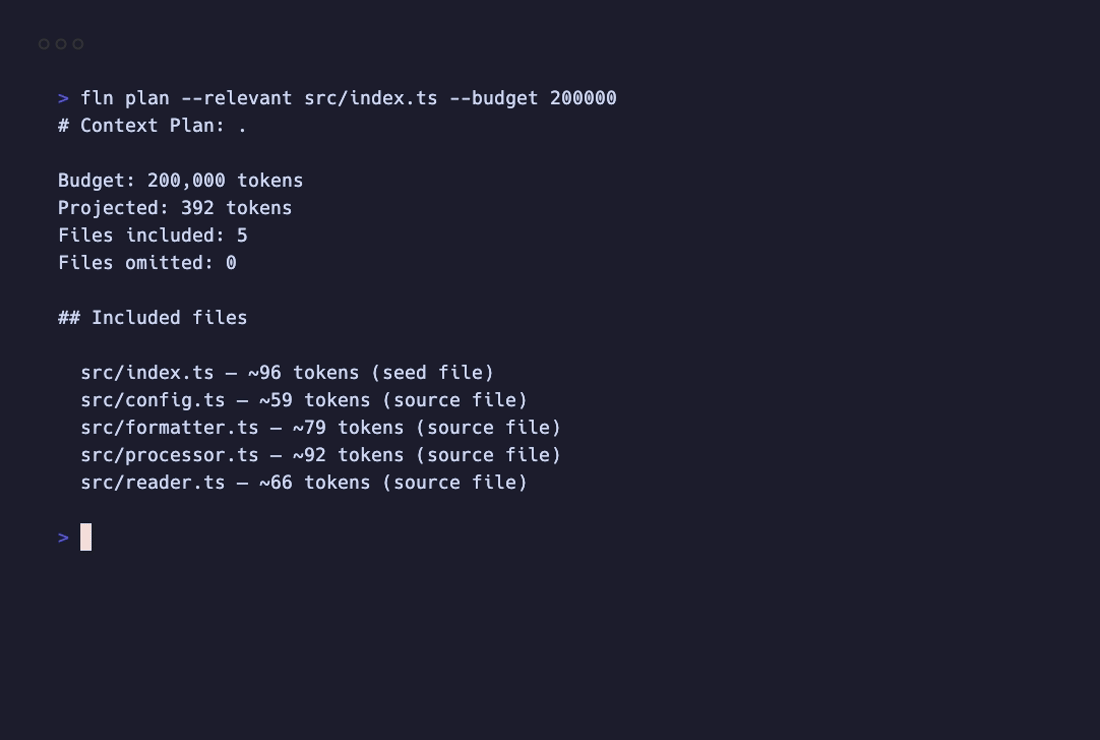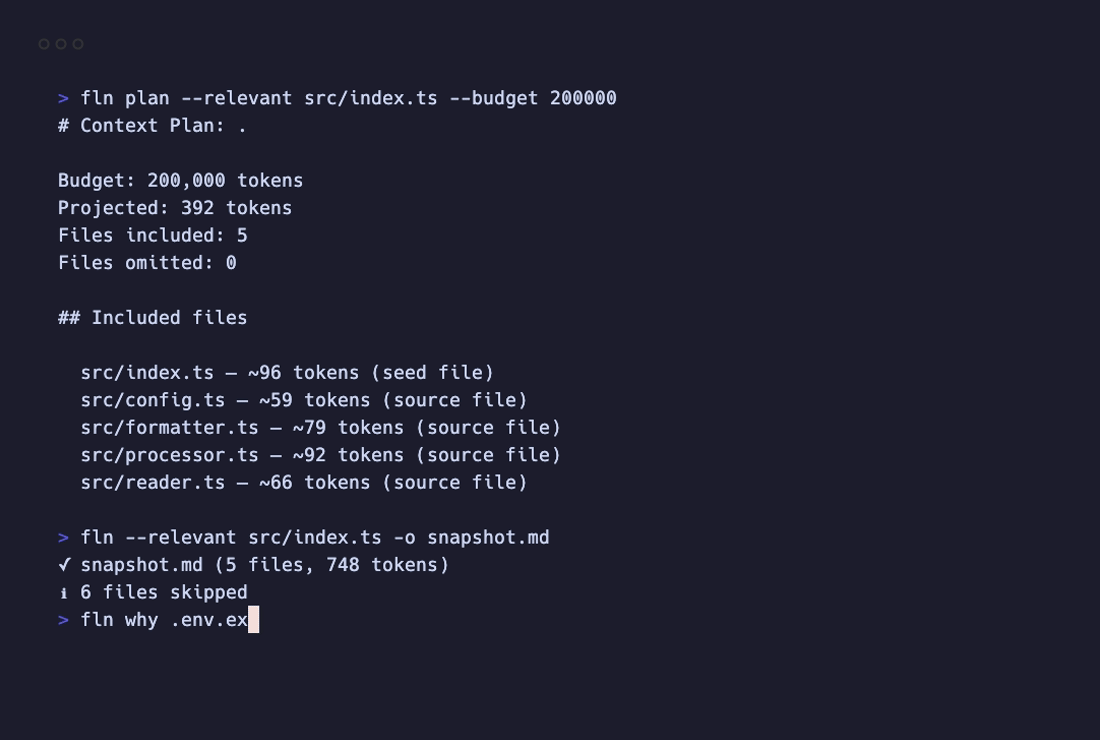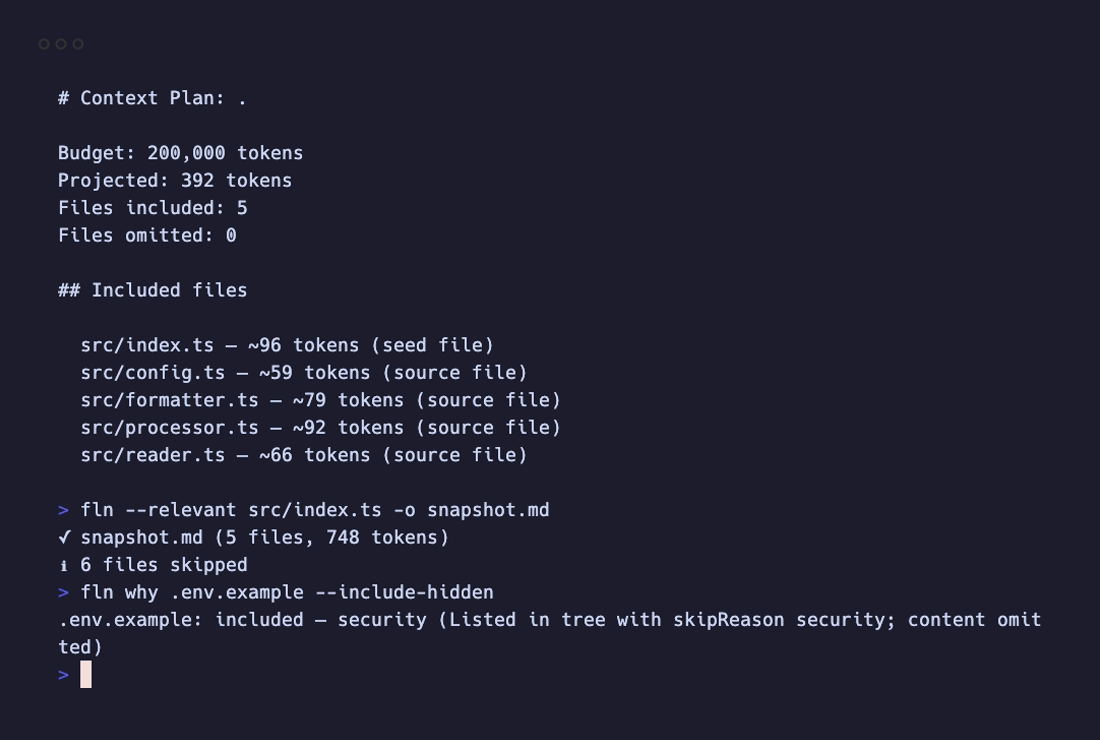
fln why .env                    # why is .env excluded?
fln why src/index.ts            # why is index.ts included?
fln why .env --format json      # machine-readable for CI/agents

fln doctor .                    # config, git, scan stats, token estimate
fln doctor --max-tokens 200000  # warn if over budget
fln doctor --format json --recommend-budget 200000

fln mcp                         # stdio MCP server
fln mcp --http --port 3000      # Streamable HTTP
fln why is a first-class path-decision CLI with stable reasons (gitignore, security, size, whitelist, …) and JSON for agents.
Resources: fln_file://{path}, fln_snapshot://{name}.
{
  "mcpServers": {
    "fln": { "command": "fln", "args": ["mcp"] }
  }
}
Compose with your tools
--stdin force-includes piped paths (like -i), then prunes the tree to exactly that set. Security still applies — detected secrets are never embedded:
git ls-files                | fln --stdin -o snapshot.md
git ls-files --others       | fln --stdin -o untracked.md
git diff --name-only HEAD~1 | fln --stdin --stdout
rg -l TODO                  | fln --stdin --stdout
git diff --name-only main   | fln plan --stdin --budget 50000
fln --copy                  # clipboard (32 MiB default; FLN_COPY_MAX_BYTES to override)
fln --stdout | llm "What are the biggest architecture issues here?"
fln --stdout | pbcopy       # fallback when --copy isn't available
fln --since main --ext ts,tsx
fln --since main --diff-hunks
fln --relevant src/index.ts --outline
fln --banner-file .prompt.md
fln --banner "Review this codebase for security vulnerabilities."
Highlights
Performance: linux-x64 CI baselines for the medium fixture (5000 files) — dry-run ~1.1s, full flatten ~2.4s (median; gate = baseline +10%). Details: benchmarks/README.md.
- Parallel scan; respects
.gitignore; skips binaries/lockfiles; configurable size limits - Directory-aware file order (README/entry/config first; tests/
vendor/deprioritized) - Token count every run;
--verboseextension breakdown; self-aware (skips prior fln output) - Backtick-safe fences (adapts to max run + safety margin for large samples)
- Project metadata naming from
package.json,Cargo.toml,pyproject.toml,pom.xml,go.mod, … - Output:
md/json;--compress/--outline(custom line-based signatures, not Tree-sitter) --max-total-sizegraceful omit;--strict-limitsfor CI;doctor --recommend-budget- TOCTOU warn/throw (
--strict-toctou);--annotate-tree;--collect-todo(same content pass) --dry-run; namespace API:fln(),.inspect(),.explain(),.doctor(),.plan(),.diff(),.mcp()omittedFilesin JSON (flat, capped, all reasons)
Privacy
- No network during normal runs (
flatten,why,doctor,plan,diff,mcp).fln upgradeis the explicit exception. - Local
~/.config/fln/usage.jsonmay storerunCount/lastRunonly (sponsor message on runs 5 and 25). Hide:FLN_NO_SPONSOR=1or--no-sponsor-message. Skip write:--no-local-state.
Install
npx fln                    # run once
bunx fln
npm install -g fln
bun add -g fln

# Native binary — no Node required
curl -fsSL https://fln.nesvet.dev/install | sh
powershell -c "irm fln.nesvet.dev/install.ps1 | iex"

brew install nesvet/tap/fln
# Homebrew 6.0+: trust the formula on first use
brew trust --formula nesvet/tap/fln

fln upgrade                # binary self-update (sha256 + optional cosign)
Pin version / custom dir (macOS/Linux):
curl -fsSL https://fln.nesvet.dev/install | FLN_VERSION="<version>" INSTALL_DIR="$HOME/.local/bin" sh
Windows:
$env:FLN_VERSION = "<version>"
$env:INSTALL_DIR = "$env:LOCALAPPDATA\fln\bin"
powershell -c "irm fln.nesvet.dev/install.ps1 | iex"
Manual GitHub Release:
curl -L "https://github.com/nesvet/fln/releases/latest/download/fln-macos-x64.tar.gz" | tar -xz -C /usr/local/bin
chmod +x /usr/local/bin/fln
Completions (bash / zsh / fish / PowerShell) — from a clone: source completions/_fln (zsh), source completions/fln.bash, etc. After npm i -g fln: source "$(npm root -g)/fln/completions/_fln". Regenerate: bun run generate:completions.
Usage
fln [directory] [...flags]
fln init [--overwrite]
fln why <path> [directory] [...flags]
fln doctor [directory] [...flags]
fln plan [directory] [--budget <n>] [--relevant <seed>] [...flags]
fln diff <before> <after> [...flags]
fln diff --since <ref>
fln mcp [directory]
fln upgrade
fln                              # → my-app-1.2.0.md
fln . -o context.md
fln src -o .                     # scan src/, write to project root
fln -e "*.test.ts" -e "fixtures/"
fln -e "*.md" -e '!README.md'
fln --ext ts,tsx --since HEAD~1
fln -i "src/generated/schema.ts" # force-include gitignored file
fln --only "**/*.ts"
fln why .env --include-hidden
fln --dry-run --verbose
fln --format json -o snapshot.json
fln mcp
Filtering model (2.x)
Files over --max-file-size are skipped unless force-included (-i / --stdin); content streams at render. See SECURITY.md.
Canonical list: fln --help. Config: fln.json / schema/fln.json. API: below.
Multi-word flags accept camelCase aliases (e.g. --maxFileSize, --noTree) — docs use kebab-case.
Subcommands
Output
Filtering
Content
Doctor: --recommend-budget <n>. MCP: --http, --port <n> (default 3000).
Logging: -q / -V / --debug / --no-ansi / --no-sponsor-message / --no-local-state / -v / -h.
Quote globs:
"*.test.ts". Un-exclude:-e "*.md" -e '!README.md'.
Config file
fln init
Writes fln.json with JSON Schema IntelliSense ($schema: https://fln.nesvet.dev/schema).
{
  "$schema": "https://fln.nesvet.dev/schema",
  "output": "output.md",
  "exclude": [],
  "include": [],
  "only": [],
  "includeHidden": false,
  "maxFileSize": "10mb",
  "maxTotalSize": "0",
  "maxTokens": 0,
  "maxContentTokens": 0,
  "tokenModel": "estimate",
  "strictLimits": false,
  "encoding": "auto",
  "format": "md",
  "followSymlinks": false,
  "overwrite": false
}
Additional keys (gitignore, banner, securityPatterns, …): schema/fln.json and API. Patterns are gitignore-style relative to input; CLI merges with the file (--ignore-config skips it).
CI/CD and automation
Fresh codebase.md on every push — download anytime to chat about the exact state of main or a PR:
# .github/workflows/codebase-snapshot.yaml
name: Snapshot Codebase

on:
  push:
    branches: ["main"]
  pull_request:

jobs:
  snapshot:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v7
      - name: Generate snapshot
        run: npx fln . -o codebase.md -w --no-ansi
      - uses: actions/upload-artifact@v7
        with:
          name: codebase-snapshot
          path: codebase.md
          retention-days: 7
Pre-commit budget guard:
# .husky/pre-commit
npx fln . --dry-run --max-total-size 5mb
API
npm install fln
import { fln } from "fln";

const result = await fln({
  input: "./src",
  output: "snapshot.md",
  exclude: ["*.test.ts", "fixtures/"],
  onProgress: (current, total) => {
    process.stdout.write(`\r${current}/${total} files`);
  },
});

console.log(`${result.filesIncluded} files → ${result.outputPath}`);
console.log(`~${result.outputTokenCount.toLocaleString()} tokens`);

const { root, stats } = await fln.inspect({ input: "./src", dryRun: true });
const decision = await fln.explain({ path: ".env", input: "./src" });
const report = await fln.doctor({ input: "./src" });
const planResult = await fln.plan({
  input: "./src",
  budget: 200_000,
  relevant: ["src/index.ts"],
});
const diffResult = await fln.diff({ before: "snapshot-v1.md", after: "snapshot-v2.md" });
await fln.mcp({ defaultInput: "./src" });
Formal schemas for JSON: plan ($id: https://fln.nesvet.dev/schema/plan), diff ($id: https://fln.nesvet.dev/schema/diff).
Matches FlnOptions / FlnResult / FlnInspectResult / FlnMcpOptions in the package types.
Options (FlnOptions)
MCP options (FlnMcpOptions)
Config file logLevel default in schema/fln.json is "normal" when using fln.json alone.
Diagnostics: fln why <path> from the CLI (--format json for agents/CI; not in fln.json). SDK: fln.explain().
Doctor (preflight)
fln doctor [directory] runs a dry-run scan (metadata only, no flatten file). Same filtering flags as flatten (-e, -i, --only, --since, --ext, --stdin, …).
Human output includes config path, git branch/dirty, file counts, estimated size/tokens (±20% vs real flatten), top extensions, and warnings (oversized files, security paths in tree, --max-tokens budget). With --since and no matching changes, prints the same early message as fln and exits 0.
fln doctor .
fln doctor --format json --max-tokens 500000
fln doctor --format json --recommend-budget 200000
JSON shape: schemaVersion: 1, config (loaded, path, optional ignored when --ignore-config), git, scan, estimate, extensions, warnings, optional recommend (exclude, projectedTokens, omittedCount). Formal schema: schema/fln-doctor.json ($id: https://fln.nesvet.dev/schema/doctor).
import { fln, toFlnWhyJson } from "fln";

const report = await fln.doctor({
	input: projectDir,
	recommendBudget: 200_000,
});
const decision = await fln.explain({ path: ".env", input: projectDir });
// why CLI JSON: { schemaVersion: 1, input: "<abs dir>", decision: { relativePath, included, reason, detail? } }
fln.doctor() does not accept --no-local-state or --no-sponsor-message — those are CLI-only. Programmatic sponsor status reflects usage.json and FLN_NO_SPONSOR only.
JSON flatten output
--format json emits a structured document. Top-level root is the FileNode tree; options.tree / options.contents are the boolean flags used for that run. The files array is omitted when --no-contents is set.
Formal schema: schema/fln-output.json ($id: https://fln.nesvet.dev/schema/output).
fln --format json --max-tokens 200000 -o snap.json
jq '.omittedFiles[] | select(.reason=="tokenLimit") | .path' snap.json
With fln why --format json, errors use toFlnFailureJson on stderr ({ ok: false, error: { code, message, hint? } }).
Inspect (fln.inspect) — same options as fln(), scan only. Returns FlnInspectResult: projectName, root (FileNode with skipReason), stats.
Programmatic API surface: operations on the namespace only — fln(), fln.inspect(), fln.explain(), fln.doctor(), fln.plan(), fln.diff(), fln.mcp(). Standalone: VERSION, toFlnWhyJson, toFlnDoctorJson, toFlnPlanJson, toFlnDiffJson, toFlnFailureJson, formatPlanText, formatDoctorText, formatDiffText, FlnError, and types.
Result (FlnResult): projectName, filesIncluded, filesScanned, directories, binary, skipped, errors, totalSizeBytes, outputSizeBytes, outputTokenCount, outputPath ("-" for stdout, "" when dryRun or copy).
Error codes (FlnError)
import { fln, FlnError } from "fln";

try {
	await fln({ input: dir });
} catch (error) {
	if (error instanceof FlnError)
		console.error(error.code, error.hint ?? error.message);
	throw error;
}
FAQ
How is fln different from repomix?
Both produce a paste-ready file. repomix is a feature-rich packer (remote repos, Tree-sitter compression, watch mode). fln is a compiler with diagnostics — why, doctor, plan, diff, --relevant, and an MCP server. Pick repomix for one-shot web-chat paste or remote repos; pick fln when you need reproducibility, CI guards, or explainability. See Compare.
Do I need embeddings or a server?
No. fln is fully local — zero network during a normal run. --relevant walks the import graph with a zero-dependency line-based parser (TS/JS/Py/Go/Rust/Java/C) — structure-based retrieval, not similarity search.
Does it work with MCP agents?
Yes. fln mcp starts an MCP server (stdio by default; --http --port for Streamable HTTP) exposing fln_snapshot, fln_plan, fln_diff, fln_why, and fln_doctor to any MCP-aware agent (Claude Code, Cursor, Codex CLI, VS Code). See Workflows.
Is it safe to pipe secrets?
Detected secrets are never embedded, even with force-include. fln skips sensitive paths (.env, keys, credentials) by pattern, and runs entropy + known-secret detection (AWS, Google, GitHub, Stripe, Slack, Azure, GitLab, JWT, PEM) on file headers. A force-included secret file stays in the tree with skipReason: "security" — content is omitted. Detection is not a guarantee — review output before sharing. See SECURITY.md.
Does --stdin bypass .gitignore?
Yes — intentionally. --stdin force-includes the piped paths (bypassing .gitignore, exclude, and hidden filters, like -i), then prunes the tree to exactly that set. That is what makes git ls-files --others | fln --stdin work for untracked files. Security patterns still apply; paths resolving outside the input directory are dropped.
Why AOT instead of JIT retrieval?
They solve different problems. JIT (Cursor @codebase, agentic search) is great for interactive exploration on large repos. AOT (fln) is great for reproducible snapshots, CI context guards, budget planning, and offline workflows — and for explainability. You decide what to include before the agent starts. They're complementary; many stacks use both.
How do I update fln?
- npm / Bun:
npm install -g flnorbun add -g fln - Homebrew:
brew upgrade nesvet/tap/fln - Binary install (
curl …/install):fln upgrade— downloads the latest GitHub Release, verifies sha256 (required), optionally verifies cosign whencosignis on PATH.
Token models
--token-model controls how fln estimates token counts for budgets, doctor, and diff deltas.
Use gpt-4o or gpt-5 when targeting OpenAI models. Use estimate for quick checks. Markdown snapshots record the model in the header; fln diff uses it for token deltas.
Preview
Real outputs from examples/:
Node.js — requires >=22.0.0, ESM-only ("type": "module"). Install via npm i -g fln or run with npx.
Bun — requires >=1.4.0. Install via bun add -g fln or run with bunx.
Standalone binary — no runtime required. Install via the curl / PowerShell one-liner above.
Migrating from 1.x
Unknown legacy keys in fln.json are rejected with Unknown config key. See CHANGELOG.md for the full 2.0 breaking list.
Support this project
fln is free, open-source, and maintained by one developer.
If it saves you time or improves your AI workflow:
- ⭐️ Star the repo — helps discoverability
- 💙 Support on Patreon — keeps development going
Contributing
PRs and issues are welcome. Local gate: bun run verify (mirrors CI). See CONTRIBUTING.md for setup and AGENTS.md for architecture and invariants.
License
MIT © Eugene Nesvetaev